
mizorewww/laya-coreml
mizorewww/laya-coreml has 1,630 GitHub stars and 140 forks. GitHot measured -1 stars in 24 hours. Last checked 2026-11-08 03:23 UTC. Last push 2026-10-29.
Local Laya typed decisions on Apple Core ML and Neural Engine. Validated ports, ~5 ms short decisions on M3 Max, reproducible speed and energy benchmarks.
Measured star growth
- in 24h
- -1
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalLaya-CoreML
Open-weight typed decisions on Apple Silicon: Core ML, Neural Engine, zero generated tokens.
中文 · Usage reference · Benchmarks · PyPI · Hugging Face weights · Changelog
Laya answers constrained questions (pick an option, score against a rubric, judge true or false) with calibrated probabilities from one bidirectional forward pass. It generates no tokens and returns no JSON to parse. This package runs the original Laya weights as Core ML programs on the CPU, GPU or Neural Engine. Inference needs no PyTorch, Transformers or MLX.
4.98 ms median for one short multilingual decision on the M3 Max Neural Engine, using 2.78× less system energy than compiled MLX.
Quick start
Requires Apple Silicon, macOS 15+ and Python 3.11–3.13.
pip install laya-coreml
import laya_coreml as laya

agent = laya.load("aac6fef/laya-multilingual-coreml-adaptive-fp16")
result = agent.predict(
    "I was billed twice. Please refund the duplicate.",
    {
        "department": {
            "type": "choice",
            "instructions": "Which department should handle this request?",
            "criteria": {
                "billing": "Payments, invoices, refunds, and duplicate charges.",
                "technical": "Broken features, errors, and product troubleshooting.",
                "sales": "Pricing, upgrades, and new purchases.",
            },
        },
        "refund": {
            "type": "noul",
            "instructions": "Does the customer ask for money back?",
        },
    },
)
print(result["answers"]["department"]["choice"])  # billing
Describing each option, as above, works much better than bare labels. The bundle downloads
before first use; predictions after that are local. Pass
local_files_only=True to forbid network access.
Question types
| Type | You provide | You get |
|---|---|---|
choice |
Named options, as a list or a label → description dict | Probability per option |
score |
Ordered rubric levels | Probability per level and the expected level |
noul |
A yes/no proposition | P(true) |
States can be text, JSON-like dicts or conversation lists. Each answer carries calibrated probabilities and confidence fields; confidence does not guarantee accuracy on a new task.
Model bundles
All bundles are under aac6fef/ on Hugging Face.
| Bundle | Engine | Capacity | Use |
|---|---|---|---|
laya-multilingual-coreml-adaptive-fp16 (also -fp32) |
CPU + GPU | 1,024 tokens, native batch 1/2/4/16 | Recommended general multilingual model |
laya-coreml-adaptive-fp16 / -fp32 |
CPU + GPU | 512 tokens, native batch 1/2/4/16 | English, 421M |
laya-typed-decisions-coreml-adaptive-fp16 / -fp32 |
CPU + GPU | 1,024 tokens, native batch 1/2/4/16 | Upstream typed-decisions workflows |
laya-coreml, laya-multilingual-coreml, laya-typed-decisions-coreml |
CPU + GPU | 512 / 1,024 tokens, batch 1 | Original single-graph bundles; Router() defaults |
laya-multilingual-coreml-ane |
CPU + Neural Engine | 96 tokens total, batch 1 | Fastest short decisions, FP16 |
laya-multilingual-coreml-ane-w8 |
CPU + Neural Engine | 96 tokens total, batch 1 | Approximate 8-bit palette weights |
laya-multilingual-coreml-snake |
CPU + GPU | 64 tokens, batch 3 | The Snake demo's three questions |
The ANE bundles' 96-token limit covers question, options and state together. Longer state is truncated, while oversized questions or option sets raise. Every bundle includes its tokenizer, model card, provenance, checksums and validation results. Choosing a bundle, pinned revisions and offline use.
What else it does
All of these are covered in the usage reference:
- Language routing:
Router()detects the language, picks a bundle and keeps up to two resident. You can register your own bundles. - Batches and long documents:
predict_batchandpredict_long, with answer attribution across windows. - Confidence gate:
min_confidence=marks low-confidence answers for review without changing them. - Large choice sets:
predict_tournament(no embedder) orpredict_shortlistwith your own embedding function. - Compute units:
compute_units="cpu_gpu" | "cpu_ne" | "cpu" | "all"overrides a bundle's default engine. - Tools and services: CLI (
laya-coreml predict), HTTP (laya-coreml-serve), MCP (laya-coreml-mcp-server), evaluation and calibration, and LangChain/LlamaIndex/CrewAI/Agno integrations, installed as extras. - Conversion:
pip install 'laya-coreml[convert]'thenlaya-coreml convertexports your own bundle.
Performance
M3 Max (40-core GPU, 128 GiB). One 91-token question padded to 96, end to end, from 65,598 stable calls in alternating 20-second blocks:
| Compiled MLX FP16 | Core ML ANE FP16 | Core ML ANE W8 | |
|---|---|---|---|
| P50 / P95 | 6.94 / 7.39 ms | 4.98 / 5.31 ms | 4.88 / 5.23 ms |
| System energy per decision | 0.4288 J | 0.1540 J | 0.1344 J |
| Speed / energy vs MLX | 1× / 1× | 1.39× / 2.78× | 1.42× / 3.19× |
Timings include prompt preparation, tokenization, inference, calibration and formatting; loading and warm-up are excluded. Energy comes from SMC power-sensor readings and is an estimate. The ANE advantage is for short inputs: a 1,024-token ANE graph takes about 91.7 ms, and a full Snake game is not consistently faster than compiled MLX. Speed, energy and hardware evidence · CPU/GPU benchmarks.
Port fidelity: the general bundles match upstream's selected answer on all 63 validation questions per checkpoint in FP32 and FP16, with 100 stable repeated calls each. The ANE FP16 bundle matches all 59 questions that fit in 96 tokens. These are conversion-fidelity checks, not task accuracy.
Snake demo
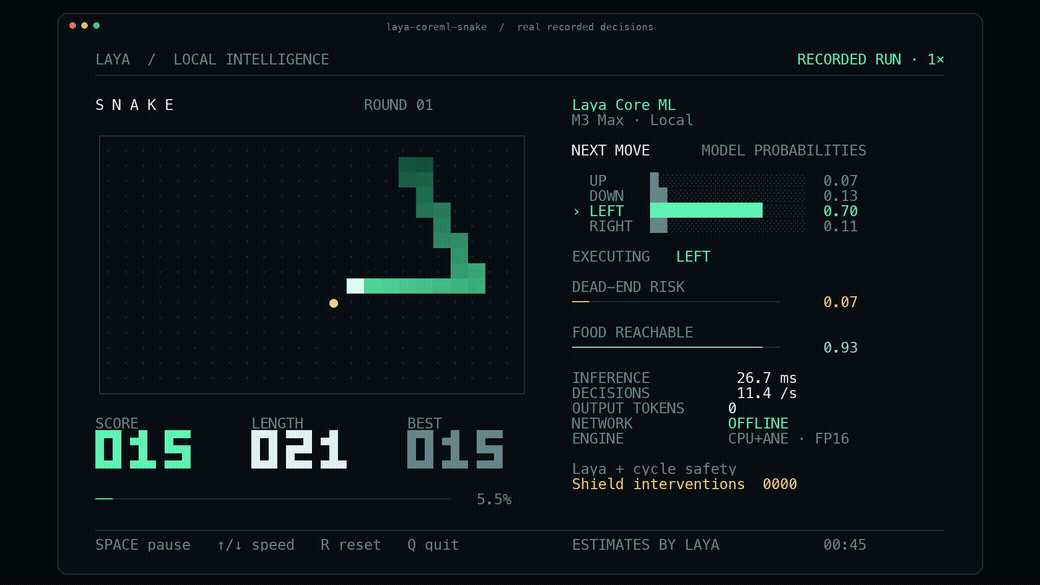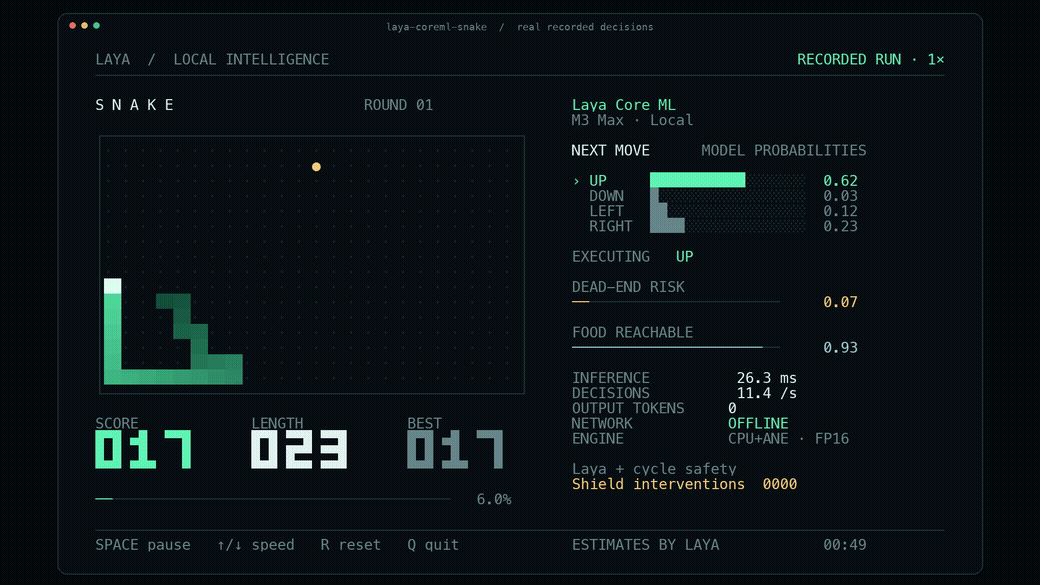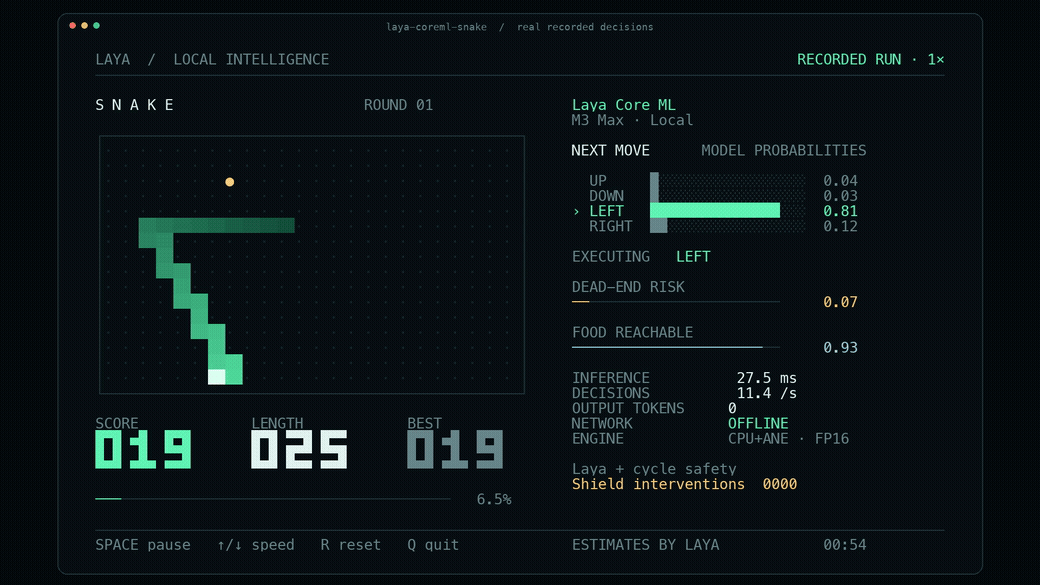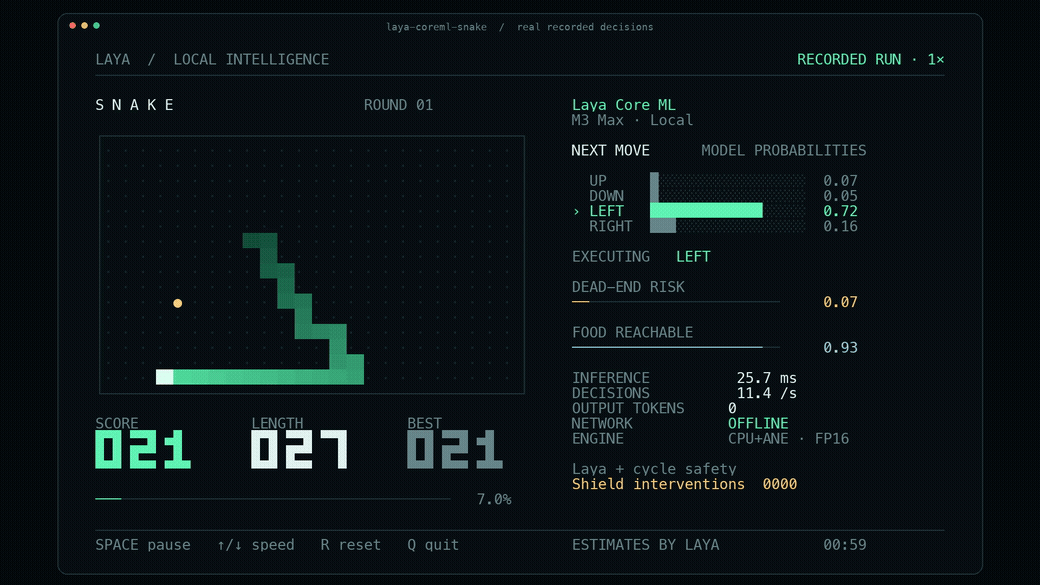
The GIF above replays a recorded Core ML run at 1× speed, with live probabilities, latency and a visible safety layer.
pip install 'laya-coreml[demo]'
hf download aac6fef/laya-multilingual-coreml-ane --local-dir models/snake
laya-coreml-snake --model ./models/snake
The terminal must be at least 104 × 35. Space pauses, ↑/↓ changes speed, R resets, Q quits. First Core ML initialization can take tens of seconds. The full loop sustained 49.1–50.0 decisions/s over three uncapped 600-step episodes with zero deaths. Demo guide · measured rates.
Relationship to upstream
This is an independent port, not an official Convai Innovations or Apple release. Prompt formatting, calibration, routing, output schema and host APIs follow NandhaKishorM/laya v0.4.17. Only the tensor, artifact, device and resource layers are Core ML-specific. Core ML bundles do not expose encoder embeddings, and training stays upstream. A sibling port for MLX is laya-mlx. Native boundaries · v0.4.17 migration record · all documentation.
Contributing
Bug reports and pull requests are welcome. Host behavior must stay traceable to upstream. See CONTRIBUTING.md for the development setup, tests, conversion and release process.
License
Apache-2.0; see LICENSE and NOTICE. Laya and its pretrained weights are by Convai Innovations and upstream contributors.
Explore related projects
codecrafters-io/build-your-own-x
Master programming by recreating your favorite technologies from scratch.
561,082 starspublic-apis/public-apis
A collective list of free APIs
497,325 starsmorluto/rea
Reverse engineer anything with agents, from app behavior down to native binaries.
443,716 starsopenclaw/openclaw
The AI that really does things. Any OS. Any Platform. The lobster way. 🦞
394,218 stars