
mhahsler/dbscan
mhahsler/dbscan has 354 GitHub stars and 65 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-17 03:39 UTC. Last push 2026-11-16.
Measured star growth
- in 24h
- 0
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Density Based Clustering of Applications with Noise (DBSCAN) and Related Algorithms - R package
Developer ToolsREADME.md
Original R package dbscan - Density-Based Spatial Clustering of Applications with Noise (DBSCAN) and Related Algorithms


Maintainer: Michael Hahsler
Introduction
This R package (Hahsler et al. 2019) provides a fast C++ (re)implementation of several density-based algorithms with a focus on the DBSCAN family for clustering spatial data. The package includes:
Clustering
- DBSCAN: Density-based spatial clustering of applications with noise (Ester et al. 1996).
- FOSC: Framework for optimal selection of clusters for unsupervised and semisupervised clustering of hierarchical cluster trees (Campello et al. 2013).
- HDBSCAN: Hierarchical DBSCAN with simplified hierarchy extraction (Campello et al. 2015).
- Jarvis-Patrick Clustering: Clustering using a similarity measure based on shared near neighbors (Jarvis and Patrick 1973).
- OPTICS/OPTICSXi: Ordering points to identify the clustering structure and cluster extraction methods (Ankerst et al. 1999).
- SNN Clustering: Shared nearest neighbor clustering (Ertöz et al. 2003).
Outlier Detection
- LOF: Local outlier factor algorithm (Breunig et al. 2000).
- GLOSH: Global-Local Outlier Score from Hierarchies algorithm (Campello et al. 2015).
Cluster Evaluation
- DBCV: Density-based clustering validation (Moulavi et al. 2014).
Fast Nearest-Neighbor Search (using k-d trees)
- kNN search
- Fixed-radius NN search
The implementations use the k-d tree data structure (from library ANN)
for faster k-nearest neighbor search, and are for Euclidean distance
typically faster than the native R implementations (e.g., dbscan in
package fpc), or the implementations in
WEKA,
ELKI and Python’s
scikit-learn.
The following R packages use dbscan:
AnimalSequences,
autoFlagR,
bioregion,
clayringsmiletus,
CLONETv2,
clusterWebApp,
cordillera,
CPC,
crosshap,
crownsegmentr,
CspStandSegmentation,
cyclicwave,
daltoolbox,
DataSimilarity,
diceR,
discoCVI,
dobin,
doc2vec,
dPCP,
DrData,
EHRtemporalVariability,
emcAdr,
eventstream,
evprof,
fastml,
FCPS,
fdacluster,
flowcluster,
flownet,
FORTLS,
FuelDeep3D,
funtimes,
HaploVar,
immunaut,
karyotapR,
ksharp,
LLMing,
LOMAR,
maotai,
MapperAlgo,
mditools,
metaCluster,
metasnf,
mlr3cluster,
neuroim2,
oclust,
openSkies,
opticskxi,
OTclust,
outlierensembles,
outlierMBC,
pagoda2,
parameters,
ParBayesianOptimization,
performance,
pguIMP,
phynotype,
PiC,
PsyML,
quickOutlier,
R4VN,
rarefun,
rcrisp,
relm,
Rhobots,
riemannianStats,
riskutility,
rMultiNet,
rtemis,
SampleCore,
seriation,
sfdep,
sfhotspot,
sfnetworks,
sharp,
smotefamily,
snap,
spCF,
spdep,
specmine,
spNetwork,
squat,
ssel,
ssMRCD,
STATassist,
stdbscan,
stream,
SuperCell,
synr,
tbnb,
TextAnalysisR,
tidyclust,
tidylearn,
tidySEM,
tlsR,
treehunt,
VBphenoR,
VIProDesign,
weird
Installation
Stable CRAN version: Install from within R with
install.packages("dbscan")
Current development version: Install from r-universe.
install.packages("dbscan",
    repos = c("https://mhahsler.r-universe.dev",
              "https://cloud.r-project.org/"))
Usage
Load the package and use the numeric variables in the iris dataset
library("dbscan")

data("iris")
x <- as.matrix(iris[, 1:4])
DBSCAN
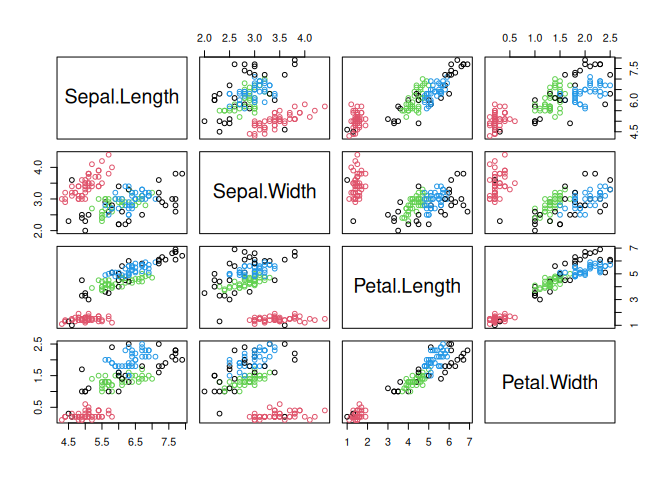
db <- dbscan(x, eps = 0.42, minPts = 5)
db
## DBSCAN clustering for 150 objects.
## Parameters: eps = 0.42, minPts = 5
## Using euclidean distances and borderpoints = TRUE
## The clustering contains 3 cluster(s) and 29 noise points.
##
##  0  1  2  3
## 29 48 37 36
##
## Available fields: cluster, eps, minPts, metric, borderPoints
Visualize the resulting clustering (noise points are shown in black).
pairs(x, col = db$cluster + 1L)
OPTICS
opt <- optics(x, minPts = 4)
opt
## OPTICS ordering/clustering for 150 objects.
## Parameters: minPts = 4, eps = Inf, eps_cl = NA, xi = NA
## Available fields: order, reachdist, coredist, predecessor, minPts, eps,
##                   eps_cl, xi
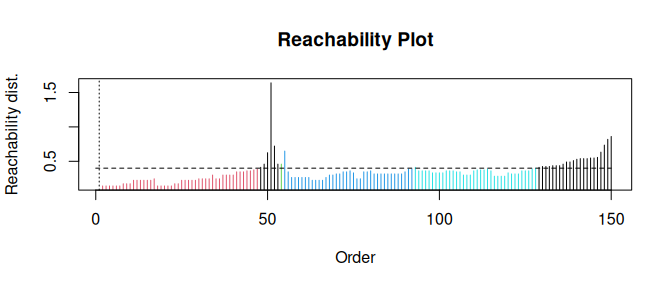
Extract DBSCAN-like clustering from OPTICS and create a reachability plot (extracted DBSCAN clusters at eps_cl=.4 are colored)
opt <- extractDBSCAN(opt, eps_cl = 0.4)
plot(opt, type = "h")
HDBSCAN
hdb <- hdbscan(x, minPts = 4)
hdb
## HDBSCAN clustering for 150 objects.
## Parameters: minPts = 4
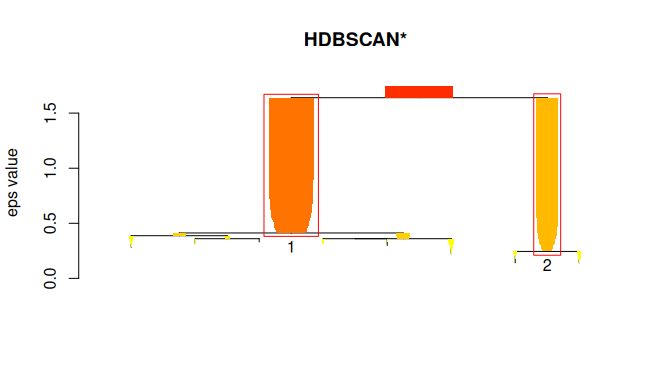
## The clustering contains 2 cluster(s) and 0 noise points.
##
##   1   2
## 100  50
##
## Available fields: cluster, minPts, coredist, cluster_scores,
##                   membership_prob, outlier_scores, hc
Visualize the hierarchical clustering as a simplified tree. HDBSCAN finds 2 stable clusters.
plot(hdb, show_flat = TRUE)
Additional guides
License
The dbscan package is licensed under the GNU General Public License (GPL) Version 3 or later.
The OPTICSXi R implementation in R/optics_extractXi.R was directly
ported from the ELKI framework’s (version 0.8.0) Java implementation
with permission by the original author, Erich Schubert. This function is
redistributed under the stricter GNU
AGPLv3. Remove the file
and function to use the package under the GNU GPL v3 license.
Citation request
To cite package ‘dbscan’ in publications use:
Hahsler M, Piekenbrock M, Doran D (2019). “dbscan: Fast Density-Based Clustering with R.” Journal of Statistical Software, 91(1), 1-30. doi:10.18637/jss.v091.i01 https://doi.org/10.18637/jss.v091.i01.
@Article{,
  title = {dbscan: Fast Density-Based Clustering with {R}},
  author = {Michael Hahsler and Matthew Piekenbrock and Derek Doran},
  journal = {Journal of Statistical Software},
  year = {2019},
  volume = {91},
  number = {1},
  pages = {1--30},
  doi = {10.18637/jss.v091.i01},
}
References
Ankerst, Mihael, Markus M Breunig, Hans-Peter Kriegel, and Jörg Sander. 1999. “OPTICS: Ordering Points to Identify the Clustering Structure.” ACM Sigmod Record 28: 49–60. https://doi.org/10.1145/304181.304187.
Breunig, Markus M, Hans-Peter Kriegel, Raymond T Ng, and Jörg Sander. 2000. “LOF: Identifying Density-Based Local Outliers.” ACM Int. Conf. On Management of Data 29: 93–104. https://doi.org/10.1145/335191.335388.
Campello, Ricardo JGB, Davoud Moulavi, and Jörg Sander. 2013. “Density-Based Clustering Based on Hierarchical Density Estimates.” Pacific-Asia Conference on Knowledge Discovery and Data Mining, 160–72. https://doi.org/10.1007/978-3-642-37456-2_14.
Campello, Ricardo JGB, Davoud Moulavi, Arthur Zimek, and Joerg Sander. 2015. “Hierarchical Density Estimates for Data Clustering, Visualization, and Outlier Detection.” ACM Transactions on Knowledge Discovery from Data (TKDD) 10 (1): 5. https://doi.org/10.1145/2733381.
Ertöz, Levent, Michael Steinbach, and Vipin Kumar. 2003. “Finding Clusters of Different Sizes, Shapes, and Densities in Noisy, High Dimensional Data.” In Proceedings of the 2003 SIAM International Conference on Data Mining (SDM). https://doi.org/10.1137/1.9781611972733.5.
Ester, Martin, Hans-Peter Kriegel, Jörg Sander, Xiaowei Xu, et al. 1996. “A Density-Based Algorithm for Discovering Clusters in Large Spatial Databases with Noise.” Proceedings of 2nd International Conference on Knowledge Discovery and Data Mining (KDD-96), 226–31. https://dl.acm.org/doi/10.5555/3001460.3001507.
Hahsler, Michael, Matthew Piekenbrock, and Derek Doran. 2019. “dbscan: Fast Density-Based Clustering with R.” Journal of Statistical Software 91 (1): 1–30. https://doi.org/10.18637/jss.v091.i01.
Jarvis, R. A., and E. A. Patrick. 1973. “Clustering Using a Similarity Measure Based on Shared Near Neighbors.” IEEE Transactions on Computers C-22 (11): 1025–34. https://doi.org/10.1109/T-C.1973.223640.
Moulavi, Davoud, Pablo A. Jaskowiak, Ricardo J. G. B. Campello, Arthur Zimek, and Jörg Sander. 2014. “Density-Based Clustering Validation.” In Proceedings of the 2014 SIAM International Conference on Data Mining (SDM). https://doi.org/10.1137/1.9781611973440.96.