
lupantech/AgentFlow
lupantech/AgentFlow has 2,087 GitHub stars and 242 forks. GitHot measured +1 stars in 24 hours. Last checked 2026-11-06 23:53 UTC. Last push 2026-02-08.
AgentFlow: In-the-Flow Agentic System Optimization
What you can do
- 🧩 Modular Agentic System – Four specialized agent modules (Planner, Executor, Verifier, Generator) that coordinate via evolving memory and integrated tools across multiple turns.
- 🔗 Multi-Tool Integration – Seamlessly connect with diverse tool ecosystems, including base_generator, python_coder, google_search, wikipedia_search, web_search, and more.
- 🎯 Flow-GRPO Algorithm – Enables in-the-flow agent optimization for long-horizon reasoning tasks with sparse rewards.
- 📈 Proven Results – AgentFlow (7B Backbone) beats top baselines on 10 benchmarks, with +14.9% search, +14.0% agentic, +14.5% math, +4.1% science, even outperforming ~200B-parameter GPT-4o.
Measured star growth
- in 24h
- +1
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original
AgentFlow: In-the-Flow Agentic System Optimization





📣 News
- [2026.01.26] 🚀 Our paper has been accepted by ICLR 2026! See you in Rio de Janeiro!
- [2025.10.26] 📚 Our project introduction has been featured on DeepWiki!
- [2025.10.16] 🏆 Our paper has been accepted by NeurIPS 2025 Efficient Reasoning Workshop!
- [2025.10.13] 📸 Excited to have a tutorial video for AgentFlow covered by Discover AI on YouTube!
- [2025.10.10] 🚀 Our X post received 1K+ likes! Feel free to check out the post and join the discussion! 💬
- [2025.10.08] 🔥 We are honored to be featured as 🤗 HuggingFace Daily Paper #2.
🌟 Why AgentFlow?
AgentFlow is a trainable, tool-integrated agentic framework designed to overcome the scalability and generalization limits of today’s tool-augmented reasoning approaches.
Unlike prevailing approaches such as Search-R1 which train a single LLM to interleave reasoning steps with tool calls, AgentFlow introduces a modular agentic system with four specialized modules: 🧭 Planner, 🛠 Executor, ✅ Verifier, and ✍️ Generator.
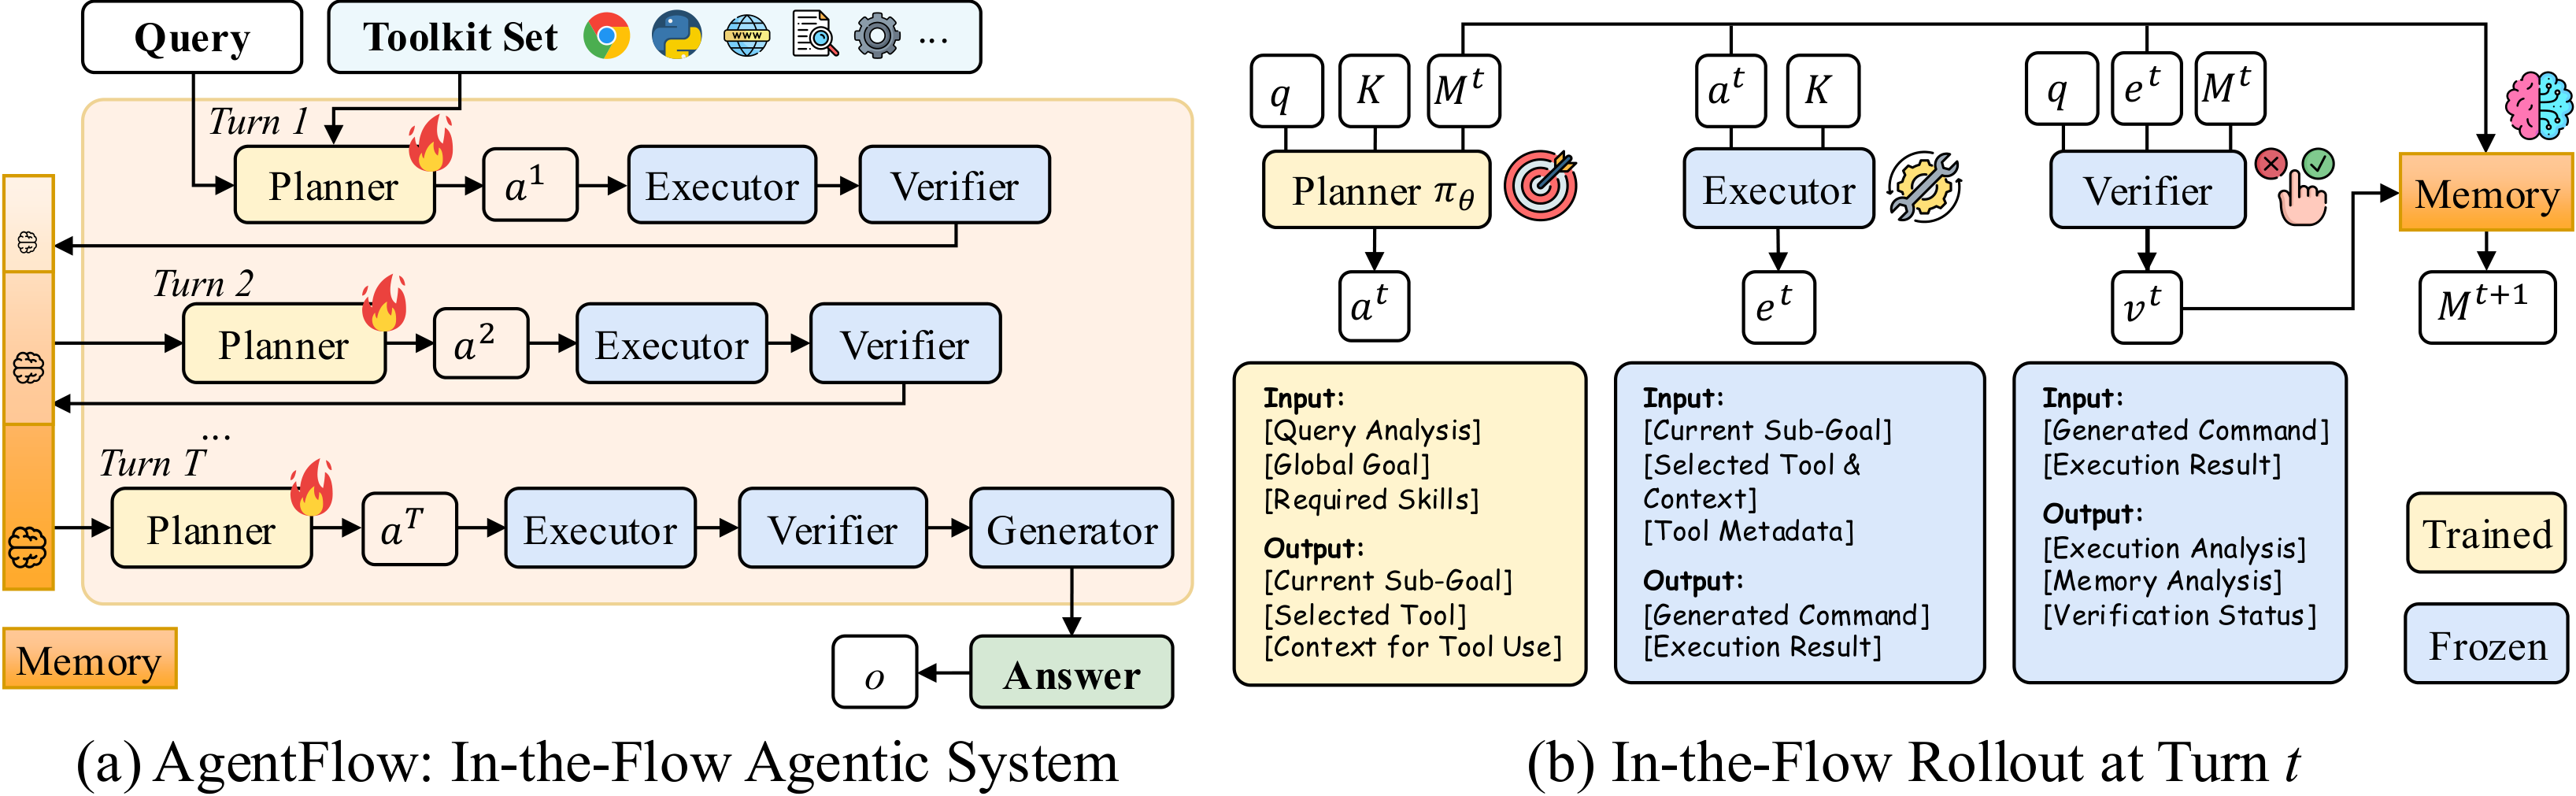
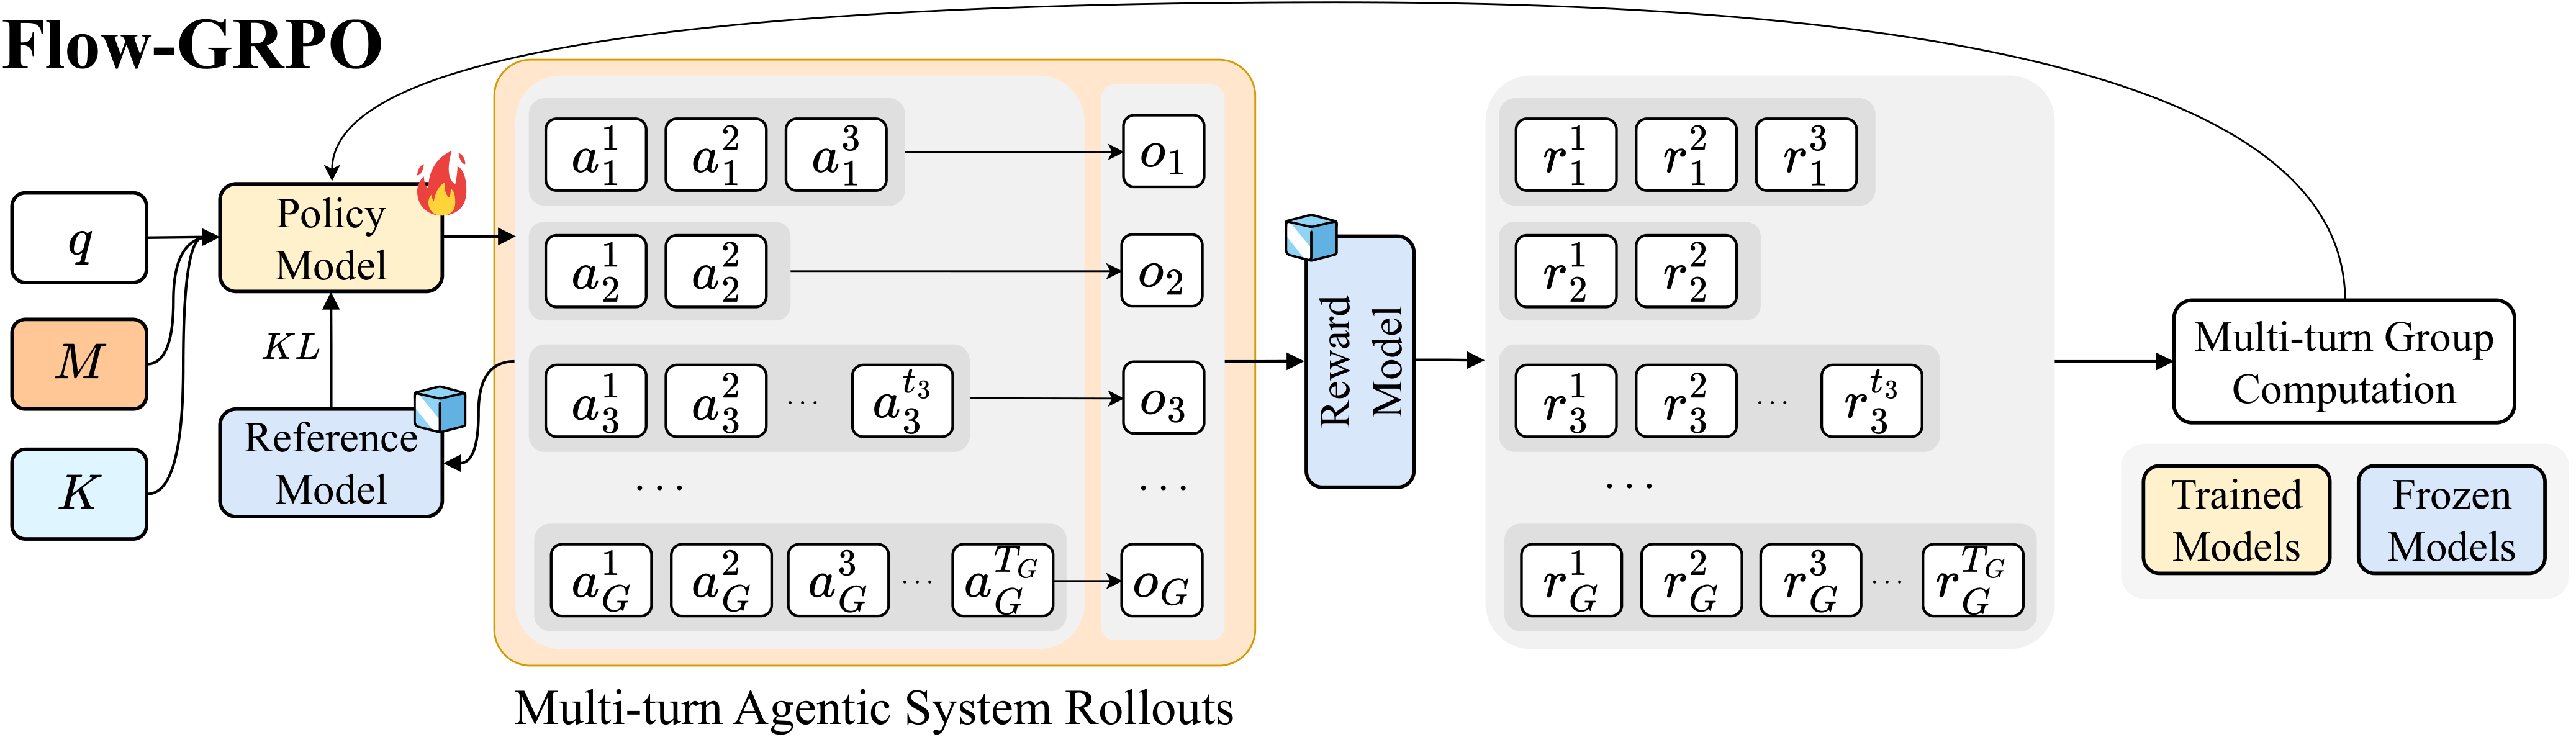
For effective planning and tool use, the framework directly optimizes planner agent within the system in an online fashion using Flow-based Group Refined Policy Optimization (Flow-GRPO), achieving superior performance across diverse domains with improved tool-calling reliability and long-horizon reasoning capabilities.
📺 YouTube Tutorial
Excited to have a tutorial video for AgentFlow covered by Discover AI on YouTube!
🚀 Key Features
- 🧩 Modular Agentic System – Four specialized agent modules (Planner, Executor, Verifier, Generator) that coordinate via evolving memory and integrated tools across multiple turns.
- 🔗 Multi-Tool Integration – Seamlessly connect with diverse tool ecosystems, including
base_generator,python_coder,google_search,wikipedia_search,web_search, and more. - 🎯 Flow-GRPO Algorithm – Enables in-the-flow agent optimization for long-horizon reasoning tasks with sparse rewards.
- 📈 Proven Results – AgentFlow (7B Backbone) beats top baselines on 10 benchmarks, with +14.9% search, +14.0% agentic, +14.5% math, +4.1% science, even outperforming ~200B-parameter GPT-4o.
📑 Table of Contents
- ⚙️ Setup
- ⚡ Quick Start on AgentFlow Inference
- 💥 Quick Start on AgentFlow Flow-GRPO Training
- 🎯 AgentFlow Benchmark
- 🧩 Use Your Own Model in AgentFlow
- 🤝 Core Contributors
- 🎓 Advisors
- 🙏 Acknowledgements
- 🚀 Contributing
⚙️ Setup
Prerequisites
- Python 3.11 (recommended)
Installation
bash setup.sh
source .venv/bin/activate
# (Optional) Install `parallel` for running benchmark experiments in parallel:
sudo apt-get update
sudo apt-get install parallel
Setup Environment Variables
Copy the .env.template file from agentflow/.env.template and rename it to .env, then place it in the agentflow/ folder. Update the following variables with your own API keys:
OPENAI_API_KEY(for judging reasponse)GOOGLE_API_KEY(for Google Search tool)DASHSCOPE_API_KEY([optional] for calling Qwen-2.5-7B-Instruct as engine for agents and tools)TOGETHER_API_KEY([optional] alternative for calling Qwen-2.5-7B-Instruct as engine for agents and tools - recommended for international users)- More ways: serve Qwen2.5-7B-instruct model with vLLM (details refer to
serve_vllm_local.md).
Please check API Key Setup Guide for detailed instructions on how to obtain these keys.
cp agentflow/.env.template agentflow/.env
# Then edit agentflow/.env with your API keys
🔍 Check Before You Run (Recommended)
Before running inference or training, we recommend verifying that your API keys and environment are properly configured.
🛠️ Test Tools
Run the following command to test all integrated tools:
cd agentflow/agentflow
bash ./tools/test_all_tools.sh
Example output:
Testing all tools...
✅ base_generator passed
✅ google_search passed
✅ python_coder passed
✅ wikipedia_search passed
...
✅ All tests passed
🧠 Test LLM Engines
Verify that your LLM engines (OpenAI, DashScope, Gemini, etc.) are correctly initialized and responding:
python agentflow/scripts/test_llm_engine.py
Example output:
🚀 Starting fault-tolerant test for 11 engines...
✅ Passed: 4
   • gpt-4o → ChatOpenAI
   • dashscope-qwen2.5-3b-instruct → ChatDashScope
   • gemini-1.5-flash → ChatGemini
   • deepseek-chat → ChatDeepseek
...
🎉 All engines initialized successfully!
⚡ Quick Start on AgentFlow Inference
AgentFlow provides a modular agentic system with four specialized modules (planner, executor, verifier, generator) that coordinate through evolving memory and a toolkit over multiple turns to solve complex reasoning tasks.
To quickly experience the system in action, run the command below (don’t forget to set up your API key):
python quick_start.py
Example output of python quick_start.py:
==> Initializing agentflow...
==> Setting up tools...
==> 🎯 Reasoning Steps from AgentFlow (Deep Thinking...)
==> 🔍 Step 0: Query Analysis
==> 🎯 Step 1: Action Prediction (Google_Search_Tool)
==> 🛠️ Step 1: Command Execution (Google_Search_Tool)
...
**Answer:** The capital of France is Paris.
==> ✅ Query Solved!

**Process Summary:**
1. **Query Analysis:** Identified as a factual question about the capital of France.
2. **Tool Selection:** Used Google Search for accurate information.
3. **Execution:** Confirmed Paris as the capital.
4. **Verification:** Cross-referenced sources for reliability.

**Answer:** The capital of France is Paris.
💥 Quick Start on AgentFlow Flow-GRPO Training
For effective planning and tool use, the framework directly optimizes the planner agent within the system in an online fashion using Flow-GRPO. Below is a quick start for training.
(Optional) Test Your Environment
Before diving in, we recommend verifying that AgentFlow's tools, LLM engines, and network configuration are properly set up. See test_env.md for detailed testing instructions.
Dataset Preparation
We mix two datasets for training: NQ (Natural Questions) for agentic search and DeepMath-103K for mathematical reasoning.
# train data
python data/get_train_data.py
# validation data
python data/aime24_data.py
After that, data dir should be:
data/
├── train/
│   └── combined_train.parquet (182,190 samples)
├── val/
│   └── aime24.parquet (30 samples)
├── aime24_data.py
└── get_train_data.py
Flow-GRPO Training
Start agentflow training using Flow-GRPO with tmux:
# Create tmux session and start agentflow service (Window 0)
tmux new-session -s agentflow
bash train/serve_with_logs.sh

# Create new window (Ctrl+B then C) and start training (Window 1)
bash train/train_with_logs.sh
Configuration:
All training hyperparameters are in train/config.yaml (model settings, tools, RL parameters, resources, etc.)
Logging: We provide a comprehensive logging to monitor training. See logs.md for more details.
🎯 AgentFlow Benchmark
Serve the trained planner model with VLLM (here we deploy our 7B Flow-GRPO planner model):
bash scripts/serve_vllm.sh
Run inference on specific benchmark tasks:
cd test
# Run Bamboogle benchmark
bash bamboogle/run.sh
After running, each task folder (e.g., test/bamboogle/) will contain:
data/: Contains the evaluation dataset (e.g.,data.json).logs/: Contains detailed execution logs for each problem index (organized by model label).results/: Contains the model's generated answers (output_i.json) and final evaluation scores (finalscore_*.log).
You can find more benchmarking details in benchmark.md.
🧩 Use Your Own Model in AgentFlow
AgentFlow supports different LLM engines for each agent module. See llm_engine.md for supported models and factory.py for the corresponding model_string configuration:
Planner Agent:
- Modify the
llm_engine_nameparameter in the correspondingrun.shscript (e.g.,test/bamboogle/run.sh)
Other Agents (Executor, Verifier, Generator):
- By default, these agents use a fixed LLM engine (Qwen-2.5-7B-Instruct via DashScope)
- To use your own model, modify
self.llm_engine_fixedinagentflow/agentflow/models/planner.py:19:
self.llm_engine_fixed = create_llm_engine(model_string="your-engine", is_multimodal=False, temperature=temperature)
and
- Modify the
llm_engine_nameparameter in the Executor instantiation fromagentflow/agentflow/solver.py:232:
# Instantiate Executor
executor = Executor(
    # llm_engine_name=llm_engine_name,
    llm_engine_name="dashscope",
    root_cache_dir=root_cache_dir,
    verbose=verbose,
    # base_url=base_url,
    temperature=temperature
)
- For detailed information on supported engines and
model_stringformats, seellm_engine.md
🏆 Experiments
📊 Main Results
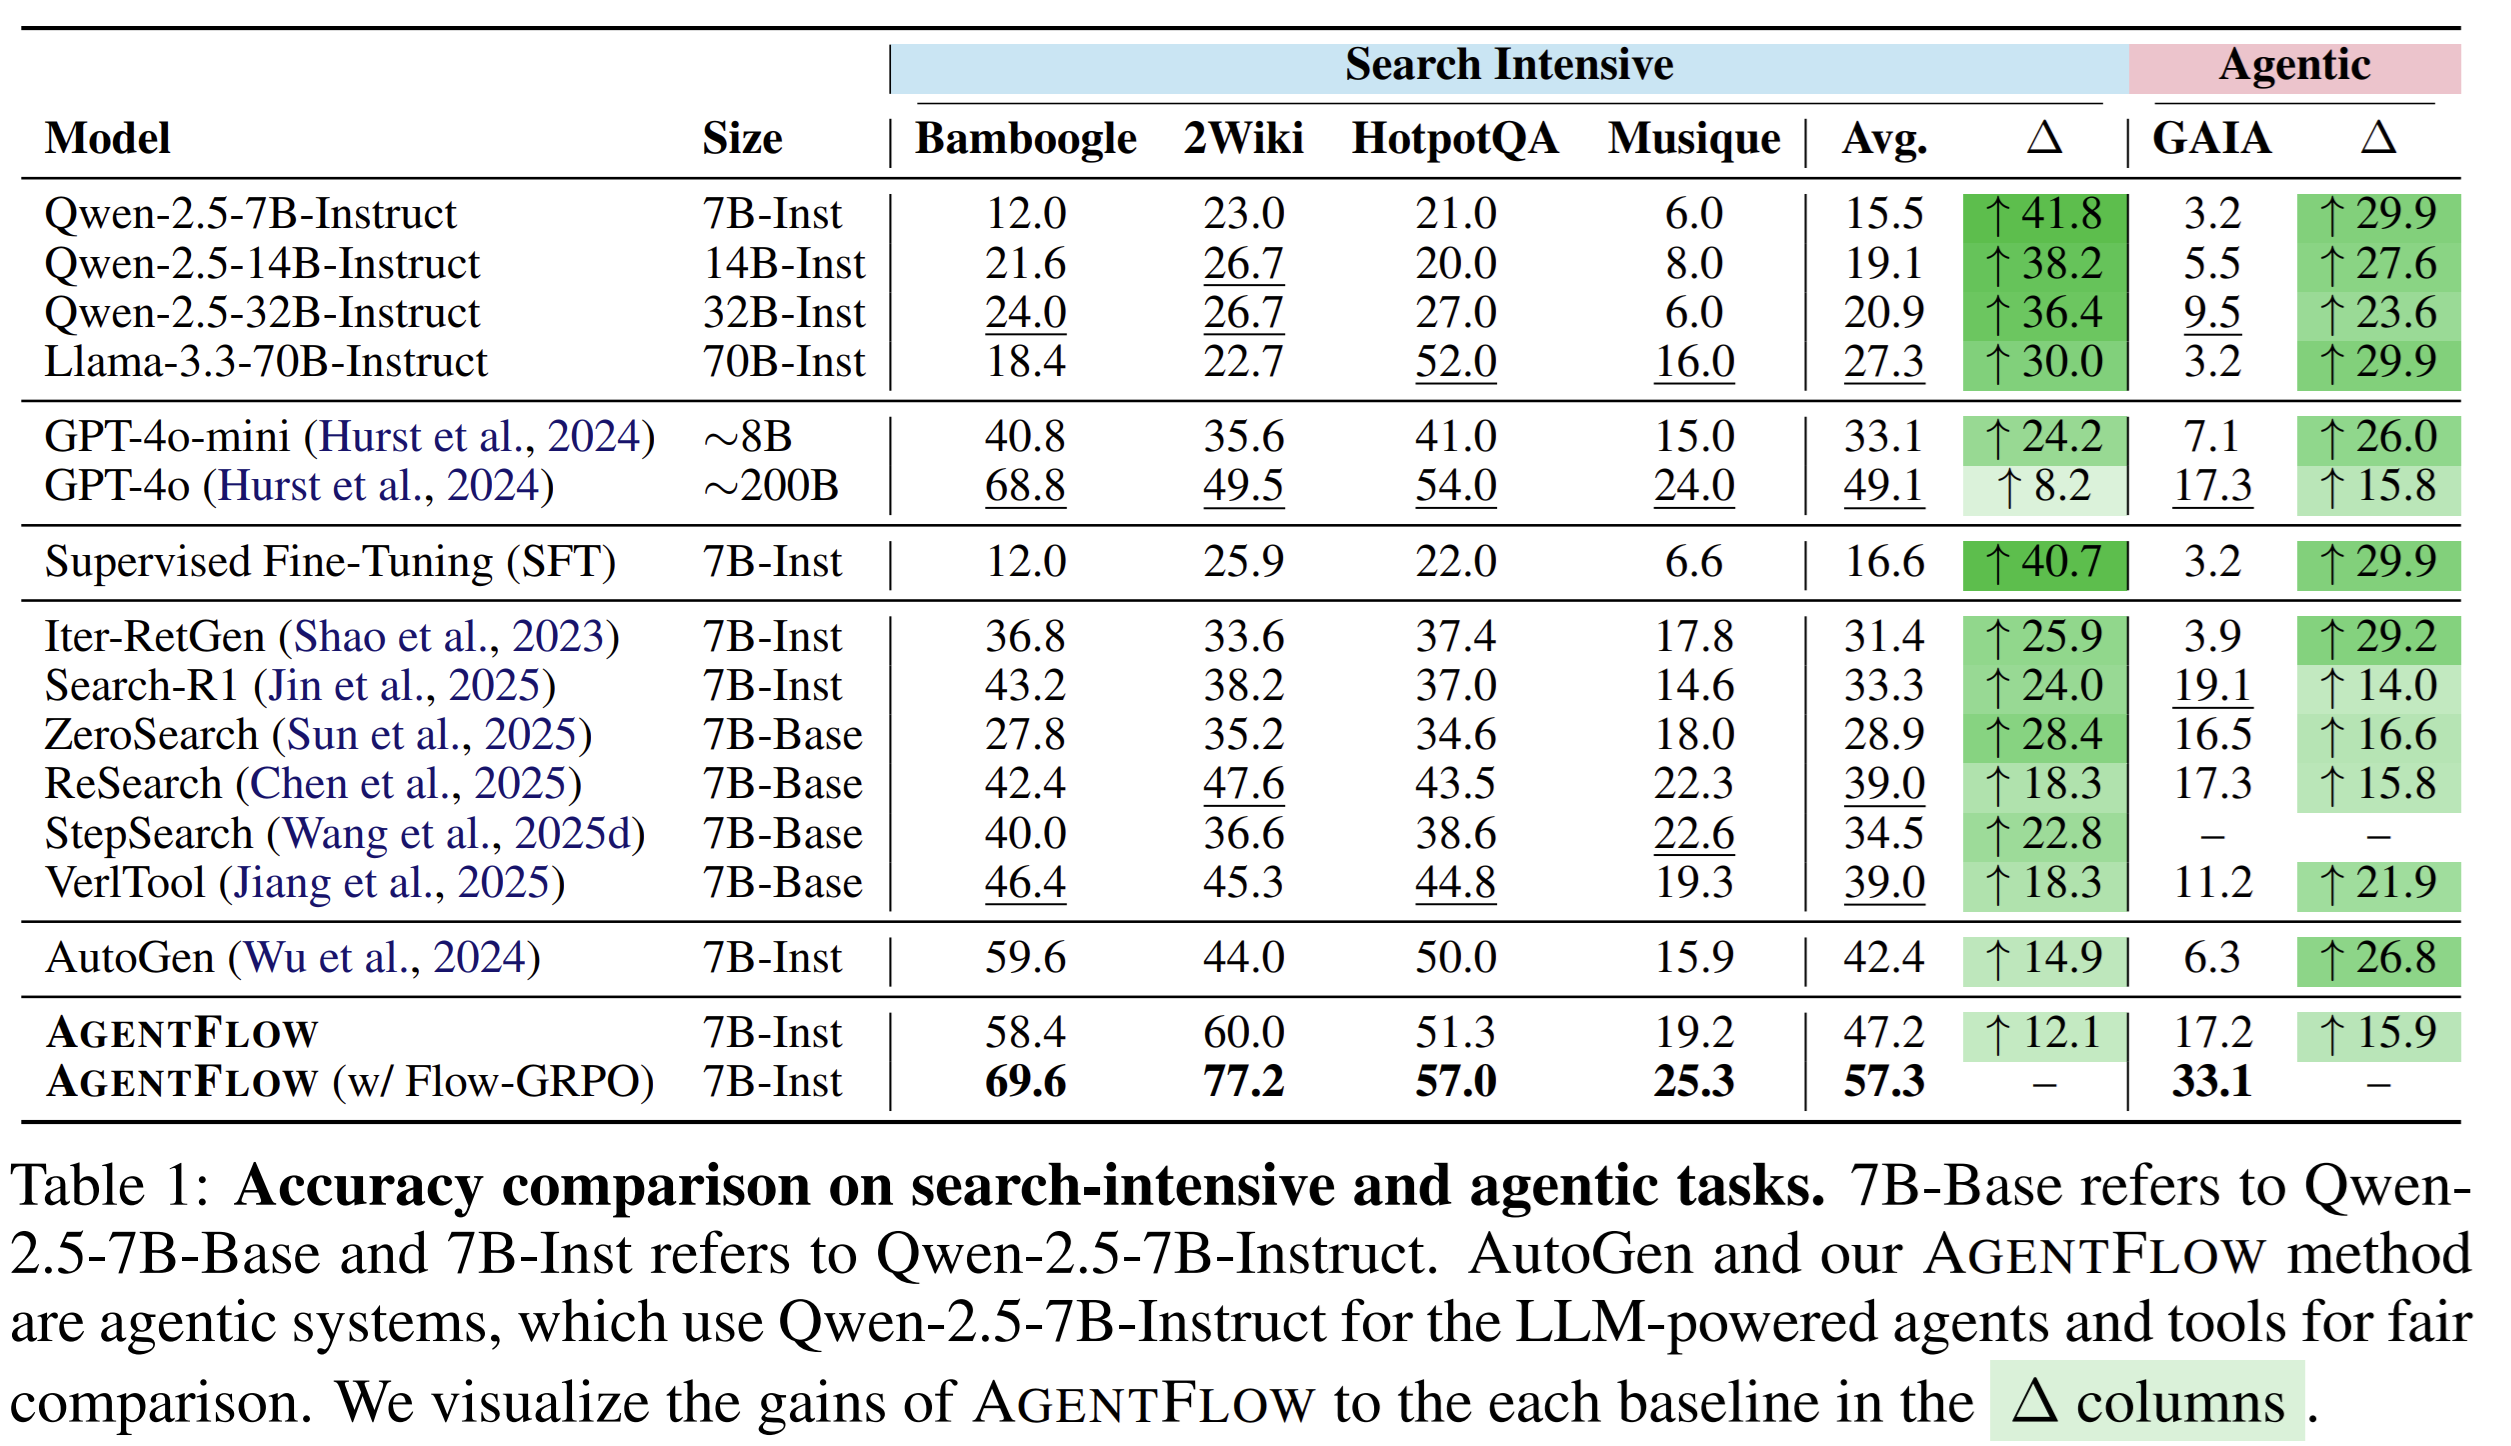
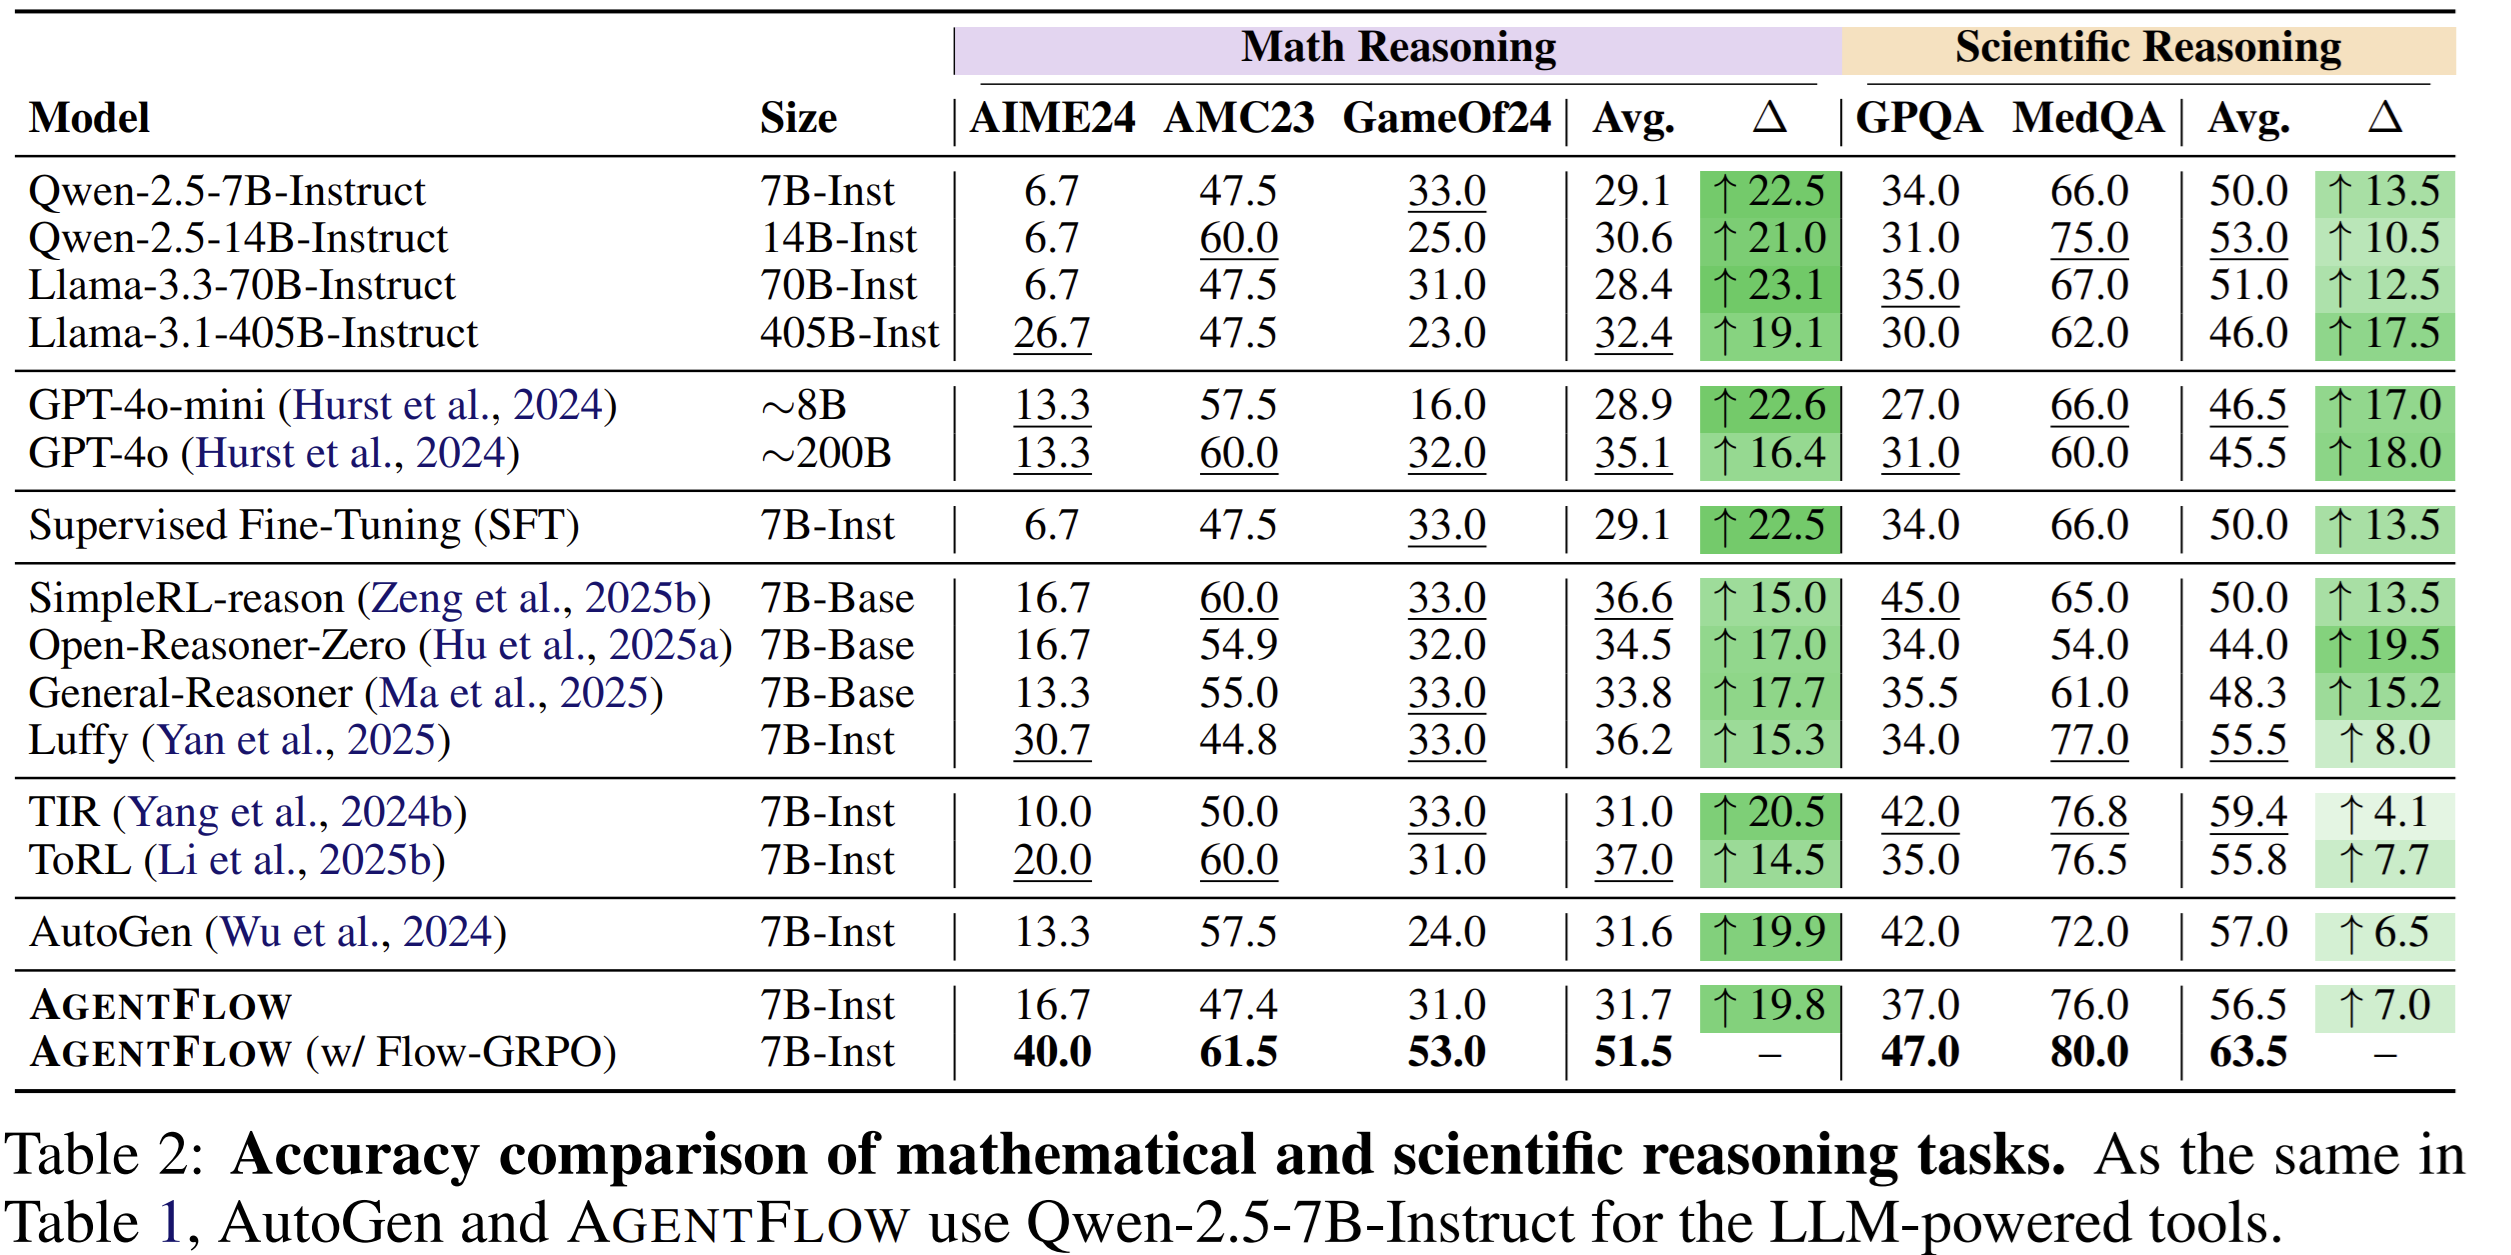
AgentFlow (Qwen-2.5-7B-Instruct Backbone) outperforms top baselines on 10 benchmarks:
- +14.9% on search
- +14.0% on agentic reasoning
- +14.5% on math
- +4.1% on science
💡 Even surpasses larger proprietary models like GPT-4o (~200B).
🔍 In-Depth Analysis
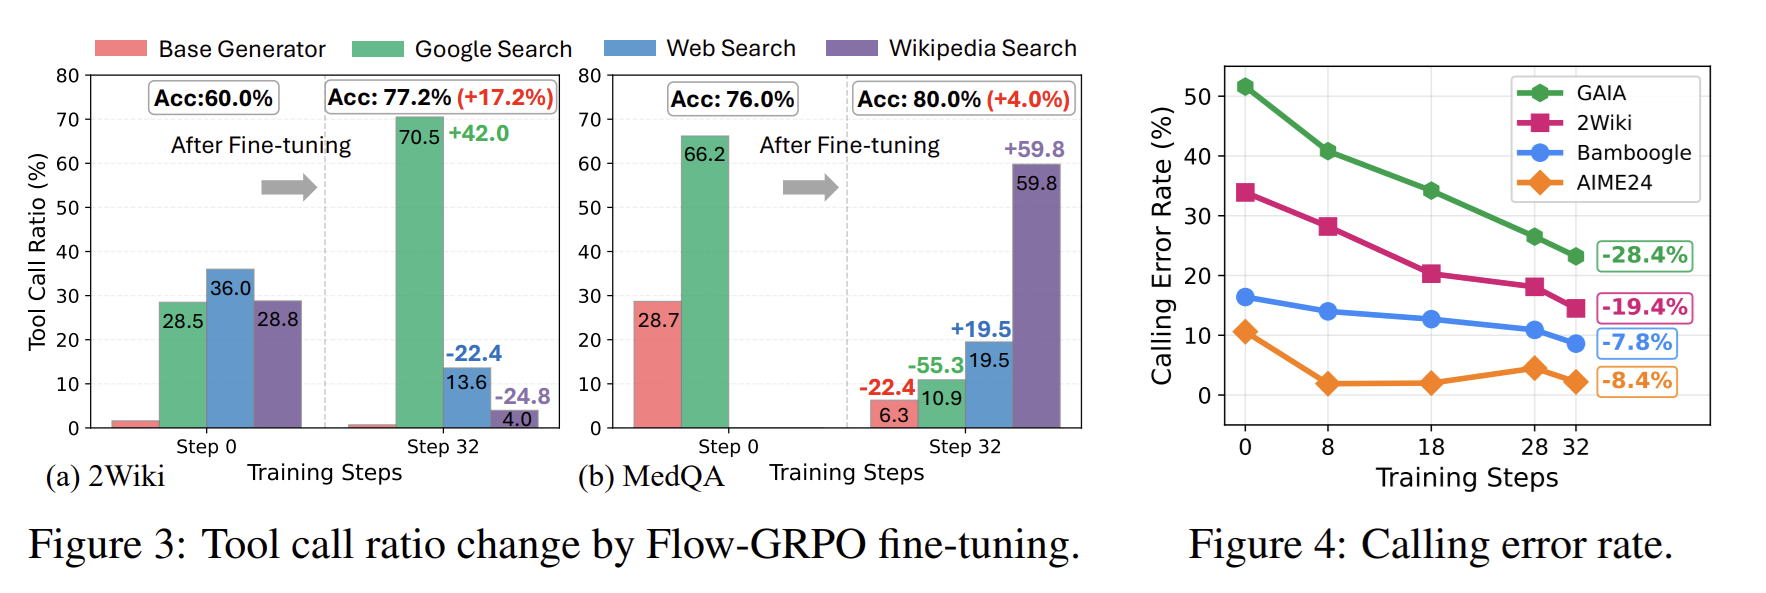
- Improved planning and decision-making
- Enhanced tool-calling reliability
- Positive scaling trends with model size & reasoning turns
Explore more in our paper or project page.
🤝 Core Contributors

Zhuofeng Li |

Haoxiang Zhang |

Pan Lu |
🎓 Advisors

James Zou |
Yejin Choi |
Yu Zhang |
🙏 Acknowledgements
We thank the following open-source projects:
- verl for the excellent RL framework design.
- vLLM for fast LLM inference support.
- Verl-Tool and agent-lightning for their early-stage exploration in agentic RL Training.
We thank Lambda for GPU support!
🚀 Contributing
We are truly looking forward to open-source contributions to AgentFlow! If you’re interested in contributing, collaborating, or reporting issues, please feel free to open an issue or submit a pull request (PR). You can also reach us at [email protected], [email protected], [email protected] or join our Slack community: AgentFlow.
We are also looking forward to your feedback and suggestions!
📚 Citation
@inproceedings{li2026flow,
    title = {In-the-Flow Agentic System Optimization for Effective Planning and Tool Use},
    author = {Li, Zhuofeng and Zhang, Haoxiang and Han, Seungju and Liu, Sheng and Xie, Jianwen and Zhang, Yu and Choi, Yejin and Zou, James and Lu, Pan},
    booktitle = {International Conference on Learning Representations (ICLR)},
    year = {2026}
}
⭐ Star History
Explore related projects
codecrafters-io/build-your-own-x
Master programming by recreating your favorite technologies from scratch.
560,778 starspublic-apis/public-apis
A collective list of free APIs
496,996 starsmorluto/rea
Reverse engineer anything with agents, from app behavior down to native binaries.
440,790 starsopenclaw/openclaw
The AI that really does things. Any OS. Any Platform. The lobster way. 🦞
394,142 stars