
lucidrains/titans-pytorch
lucidrains/titans-pytorch has 2,006 GitHub stars and 213 forks. GitHot measured 0 stars in 24 hours and +3 in 7 days. Last checked 2026-11-12 18:10 UTC. Last push 2026-07-13.
Unofficial implementation of Titans, SOTA memory for transformers, in Pytorch
Measured star growth
- in 24h
- 0
- in 7 days
- +3
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original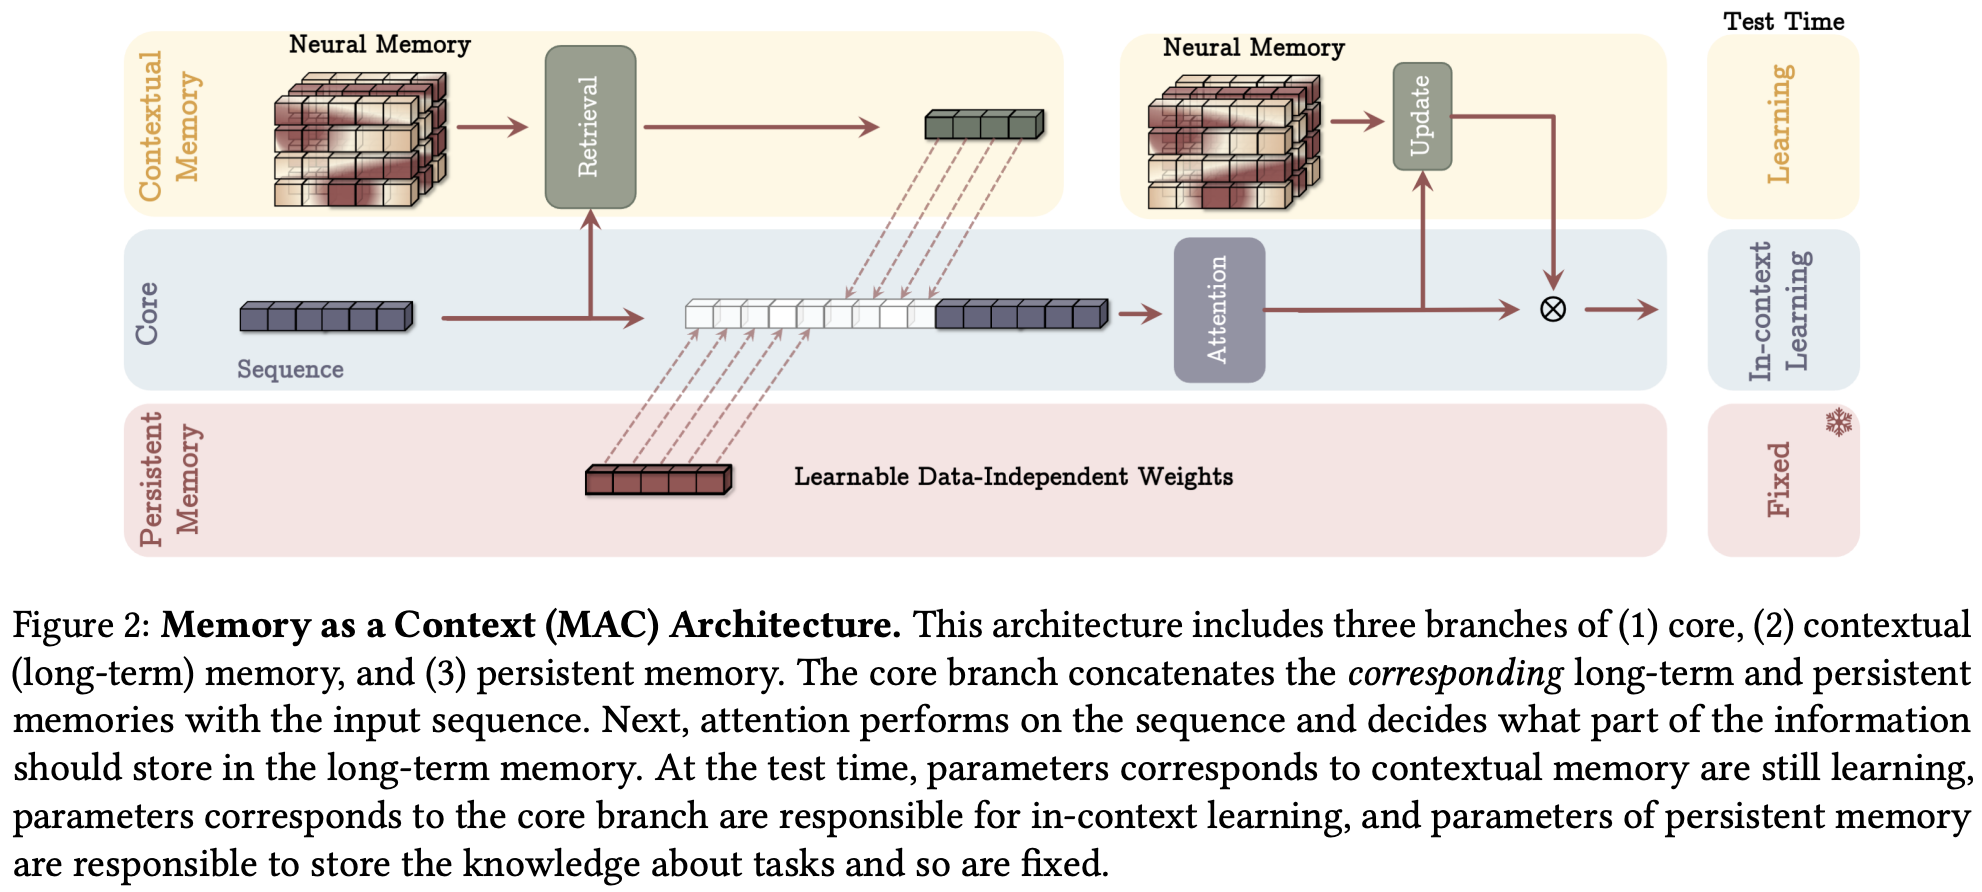
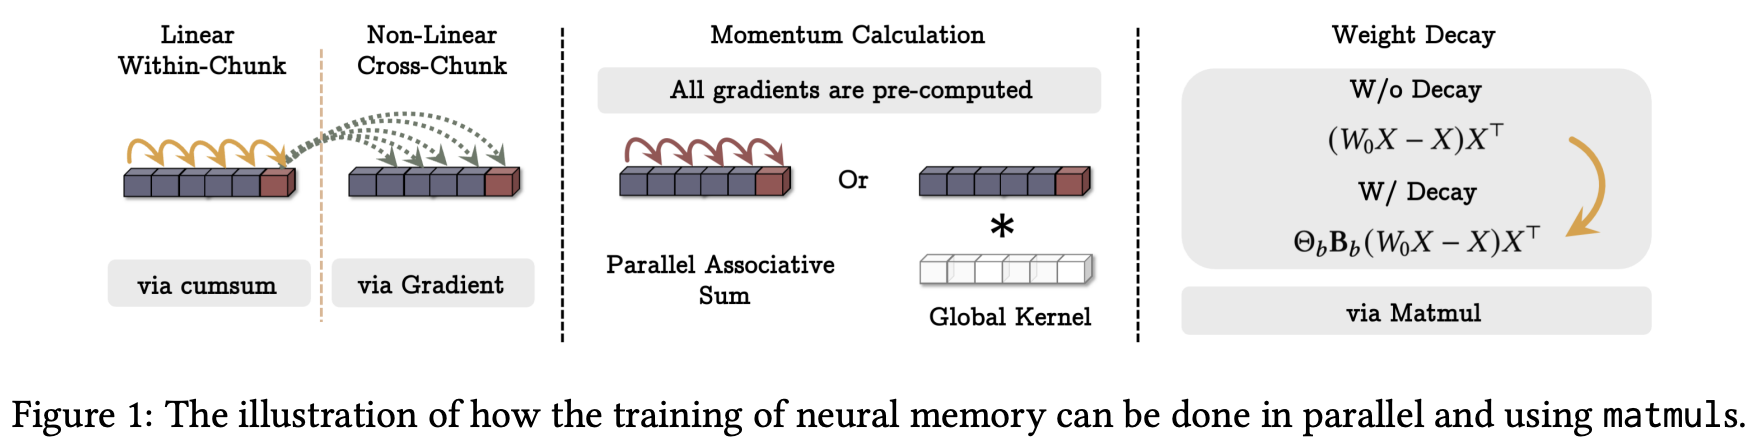
Titans - Pytorch
Unofficial implementation of Titans in Pytorch. Will also contain some explorations into architectures beyond their simple 1-4 layer MLP for the neural memory module, if it works well to any degree.
Appreciation
- Eryk for sharing his early experimental results with me, positive for 2 layer MLP
Install
$ pip install titans-pytorch
Usage
import torch
from titans_pytorch import NeuralMemory

mem = NeuralMemory(
    dim = 384,
    chunk_size = 64 # set to smaller chunk size for better perf on smaller sequence lengths (but more memory usage)
).cuda()

seq = torch.randn(2, 1024, 384).cuda()
retrieved, mem_state = mem(seq)

assert seq.shape == retrieved.shape
A transformer with the MAC configuration can be used as
import torch
from titans_pytorch import MemoryAsContextTransformer

transformer = MemoryAsContextTransformer(
    num_tokens = 256,
    dim = 256,
    depth = 2,
    segment_len = 128,              # local attention window size
    num_persist_mem_tokens = 4,
    num_longterm_mem_tokens = 16,
)

token_ids = torch.randint(0, 256, (1, 1023))

loss = transformer(token_ids, return_loss = True) # (1, 1023, 256)
loss.backward()

# after much training

sampled = transformer.sample(token_ids[:, :4], 512)
Experiments
$ pip install uv
Then modify train_mac.py and run it to query nature
$ uv run train_mac.py
Citations
@inproceedings{Behrouz2024TitansLT,
    title   = {Titans: Learning to Memorize at Test Time},
    author  = {Ali Behrouz and Peilin Zhong and Vahab S. Mirrokni},
    year    = {2024},
    url     = {https://api.semanticscholar.org/CorpusID:275212078}
}
@article{Sun2024LearningT,
    title   = {Learning to (Learn at Test Time): RNNs with Expressive Hidden States},
    author  = {Yu Sun and Xinhao Li and Karan Dalal and Jiarui Xu and Arjun Vikram and Genghan Zhang and Yann Dubois and Xinlei Chen and Xiaolong Wang and Oluwasanmi Koyejo and Tatsunori Hashimoto and Carlos Guestrin},
    journal = {ArXiv},
    year    = {2024},
    volume  = {abs/2407.04620},
    url     = {https://api.semanticscholar.org/CorpusID:271039606}
}
@inproceedings{Yang2024GatedDN,
    title   = {Gated Delta Networks: Improving Mamba2 with Delta Rule},
    author  = {Songlin Yang and Jan Kautz and Ali Hatamizadeh},
    year    = {2024},
    url     = {https://api.semanticscholar.org/CorpusID:274598177}
}
@inproceedings{Nguyen2024TurningUT,
    title   = {Turning Up the Heat: Min-p Sampling for Creative and Coherent LLM Outputs},
    author  = {Minh Nguyen and Andrew Baker and Clement Neo and Allen Roush and Andreas Kirsch and Ravid Shwartz-Ziv},
    year    = {2024},
    url     = {https://api.semanticscholar.org/CorpusID:270870613}
}
@article{Zhu2024HyperConnections,
    title   = {Hyper-Connections},
    author  = {Defa Zhu and Hongzhi Huang and Zihao Huang and Yutao Zeng and Yunyao Mao and Banggu Wu and Qiyang Min and Xun Zhou},
    journal = {ArXiv},
    year    = {2024},
    volume  = {abs/2409.19606},
    url     = {https://api.semanticscholar.org/CorpusID:272987528}
}
@article{Zhou2024ValueRL,
    title   = {Value Residual Learning For Alleviating Attention Concentration In Transformers},
    author  = {Zhanchao Zhou and Tianyi Wu and Zhiyun Jiang and Zhenzhong Lan},
    journal = {ArXiv},
    year    = {2024},
    volume  = {abs/2410.17897},
    url     = {https://api.semanticscholar.org/CorpusID:273532030}
}
@software{Kyrylov_Accelerated_Scan_2024,
    author  = {Kyrylov, Volodymyr},
    doi     = {10.5281/zenodo.10600962},
    title   = {Accelerated Scan},
    version = {0.1.2},
    year    = {2024}
}
@misc{wang2025testtimeregressionunifyingframework,
    title   = {Test-time regression: a unifying framework for designing sequence models with associative memory},
    author  = {Ke Alexander Wang and Jiaxin Shi and Emily B. Fox},
    year    = {2025},
    eprint  = {2501.12352},
    archivePrefix = {arXiv},
    primaryClass = {cs.LG},
    url     = {https://arxiv.org/abs/2501.12352},
}
@misc{jordan2024muon,
    author  = {Keller Jordan and Yuchen Jin and Vlado Boza and Jiacheng You and
                    Franz Cesista and Laker Newhouse and Jeremy Bernstein},
    title   = {Muon: An optimizer for hidden layers in neural networks},
    year    = {2024},
    url     = {https://kellerjordan.github.io/posts/muon/}
}
@inproceedings{Zhang2025TestTimeTD,
    title   = {Test-Time Training Done Right},
    author  = {Tianyuan Zhang and Sai Bi and Yicong Hong and Kai Zhang and Fujun Luan and Songlin Yang and Kalyan Sunkavalli and William T. Freeman and Hao Tan},
    year    = {2025},
    url     = {https://api.semanticscholar.org/CorpusID:279071244}
}
@inproceedings{Behrouz2025ATLASLT,
    title  = {ATLAS: Learning to Optimally Memorize the Context at Test Time},
    author = {Ali Behrouz and Ze-Minghui Li and Praneeth Kacham and Majid Daliri and Yuan Deng and Peilin Zhong and Meisam Razaviyayn and Vahab S. Mirrokni},
    year   = {2025},
    url    = {https://api.semanticscholar.org/CorpusID:278996373}
}
@misc{zhao2026fastweightproductkeymemory,
    title   = {Fast-weight Product Key Memory},
    author  = {Tianyu Zhao and Llion Jones},
    year    = {2026},
    eprint  = {2601.00671},
    archivePrefix = {arXiv},
    primaryClass = {cs.CL},
    url     = {https://arxiv.org/abs/2601.00671},
}
Explore related projects
tensorflow/tensorflow
An Open Source Machine Learning Framework for Everyone
201,584 starshuggingface/transformers
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
168,917 starsAUTOMATIC1111/stable-diffusion-webui
Stable Diffusion web UI
165,300 starsComfy-Org/ComfyUI
The most powerful and modular diffusion model GUI, api and backend with a graph/nodes interface. The fastest local inference engine in the world.
146,472 stars