
lnx-search/lnx has 1,459 GitHub stars and 52 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-07 06:07 UTC. Last push 2025-10-14.
A flexible, performant and reliable search database without the AI bullshit.
What you can do
- 🤓 Complex Query Parser.
- ❤️ Typo tolerant fuzzy queries.
- ⚡️ Typo tolerant fast-fuzzy queries. (pre-computed spell correction)
- 🔥 More-Like-This queries.
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalWARNING! This is the active dev branch, checkout the latest stable release: https://github.com/lnx-search/lnx/tree/refs/tags/0.9.0


✨ Feature Rich | ⚡ Insanely Fast
An ultra-fast, adaptable deployment of the tantivy search engine via REST.
🌟 Standing On The Shoulders of Giants
lnx is built to not re-invent the wheel, it stands on top of the tokio-rs work-stealing runtime, hyper web framework combined with the raw compute power of the tantivy search engine.
Together this allows lnx to offer millisecond indexing on tens of thousands of document inserts at once (No more waiting around for things to get indexed!), Per index transactions and the ability to process searches like it's just another lookup on the hashtable 😲
✨ Features
lnx although very new offers a wide range of features thanks to the ecosystem it stands on.
- 🤓 Complex Query Parser.
- ❤️ Typo tolerant fuzzy queries.
- ⚡️ Typo tolerant fast-fuzzy queries. (pre-computed spell correction)
- 🔥 More-Like-This queries.
- Order by fields.
- Fast indexing.
- Fast Searching.
- Several Options for fine grain performance tuning.
- Multiple storage backends available for testing and developing.
- Permissions based authorization access tokens.
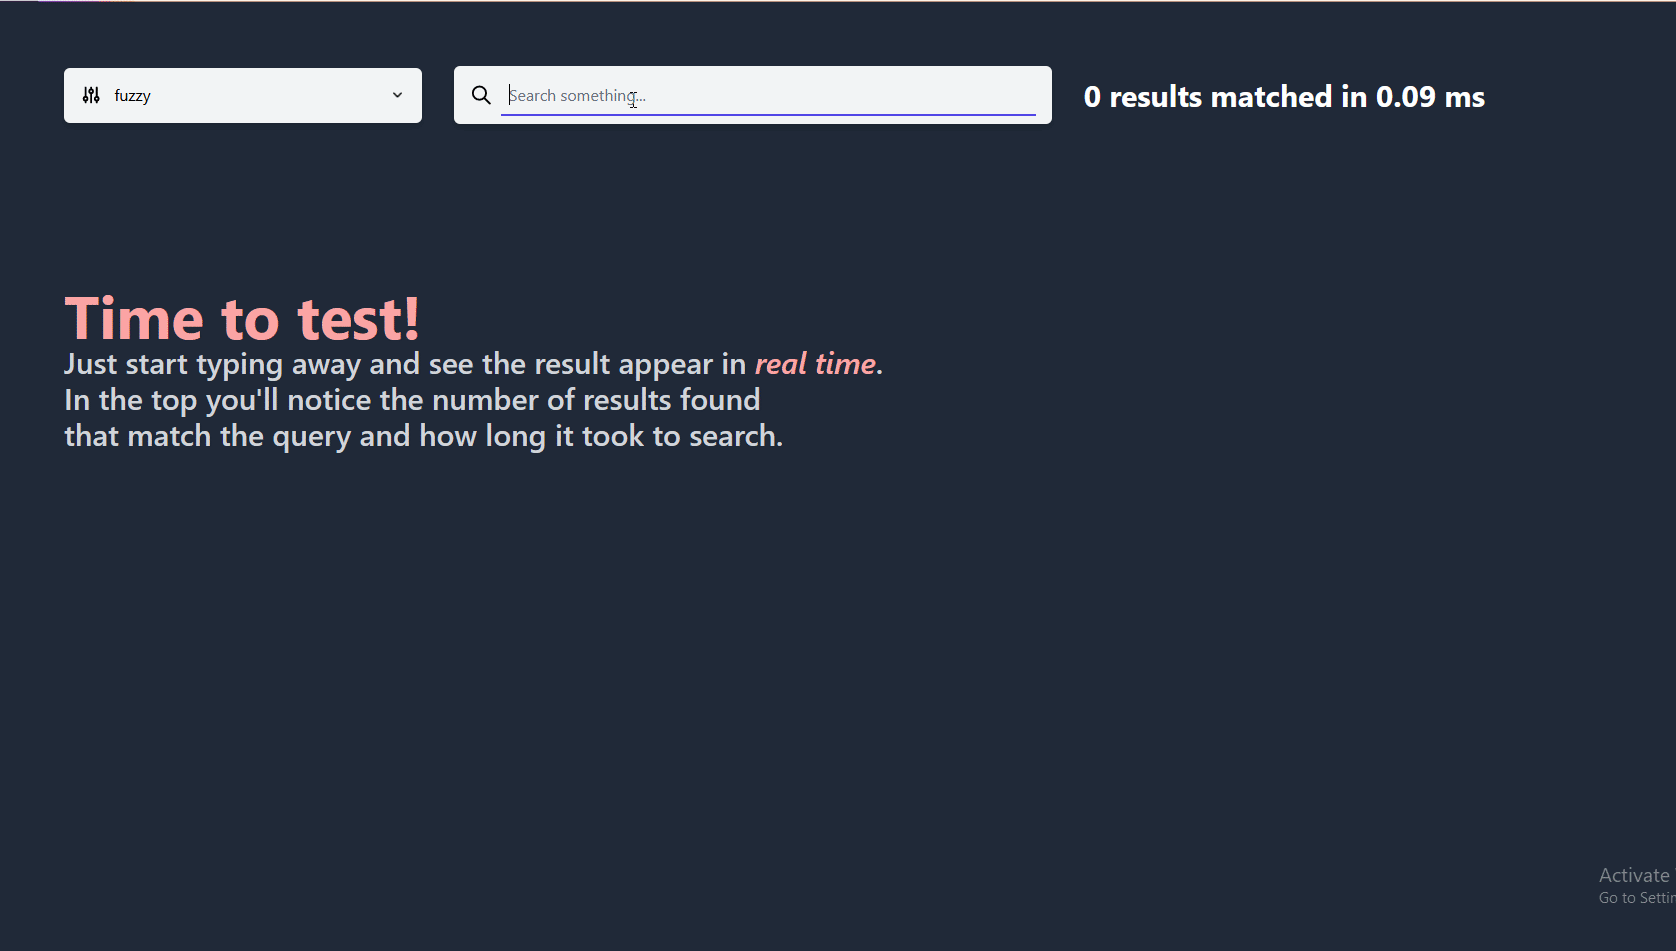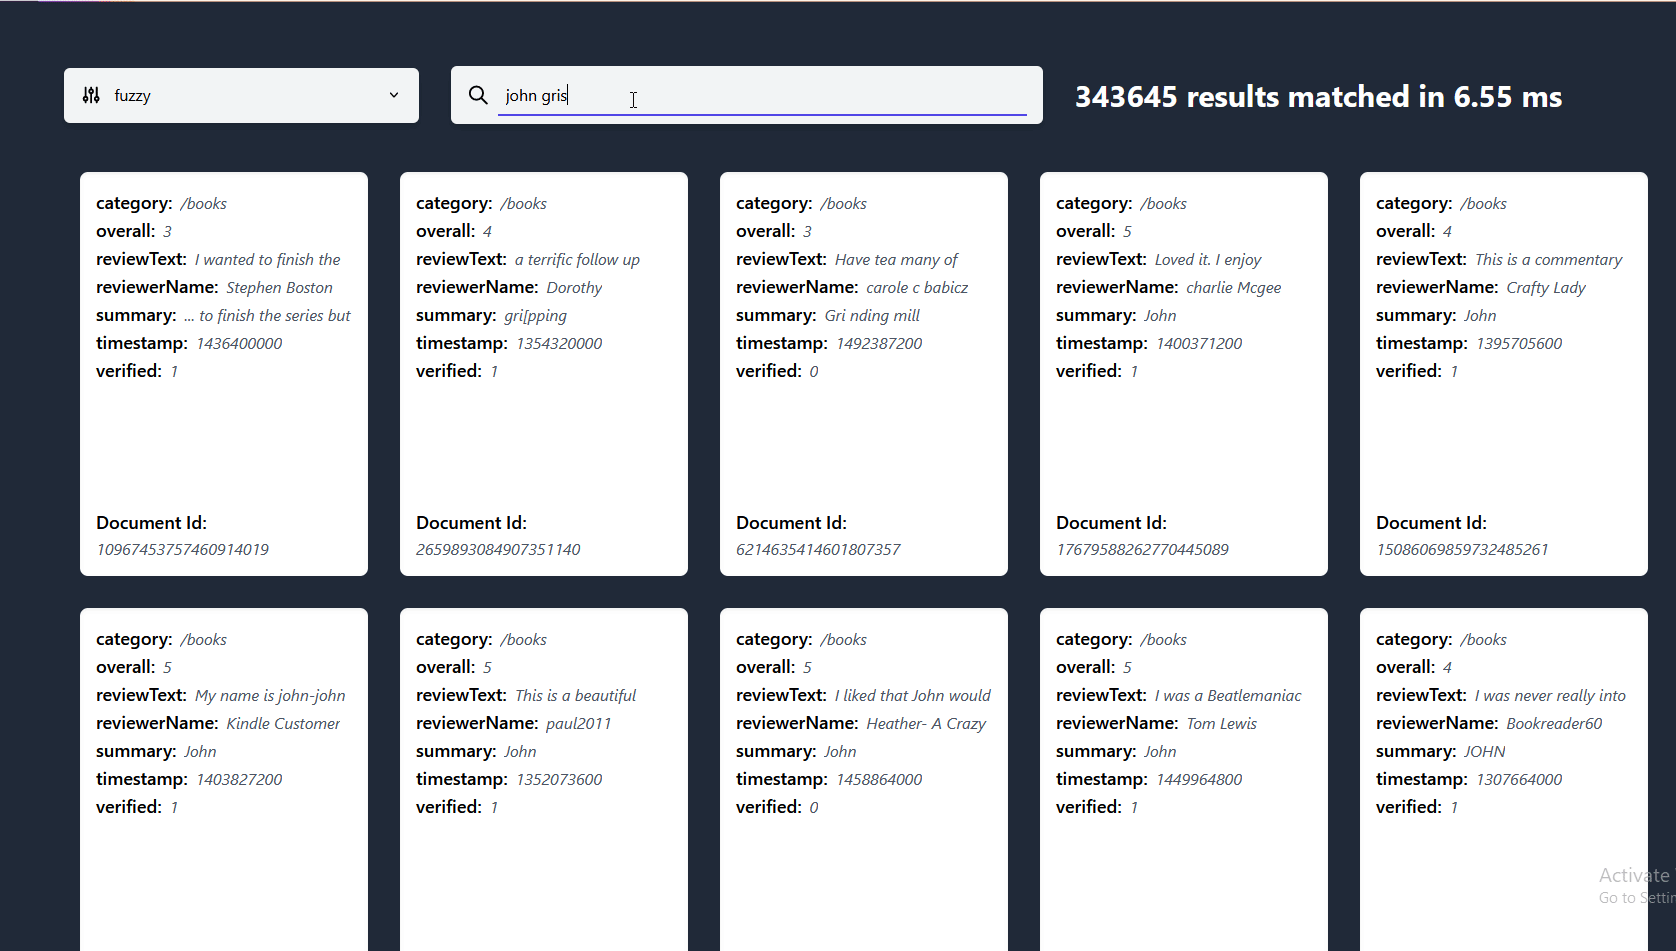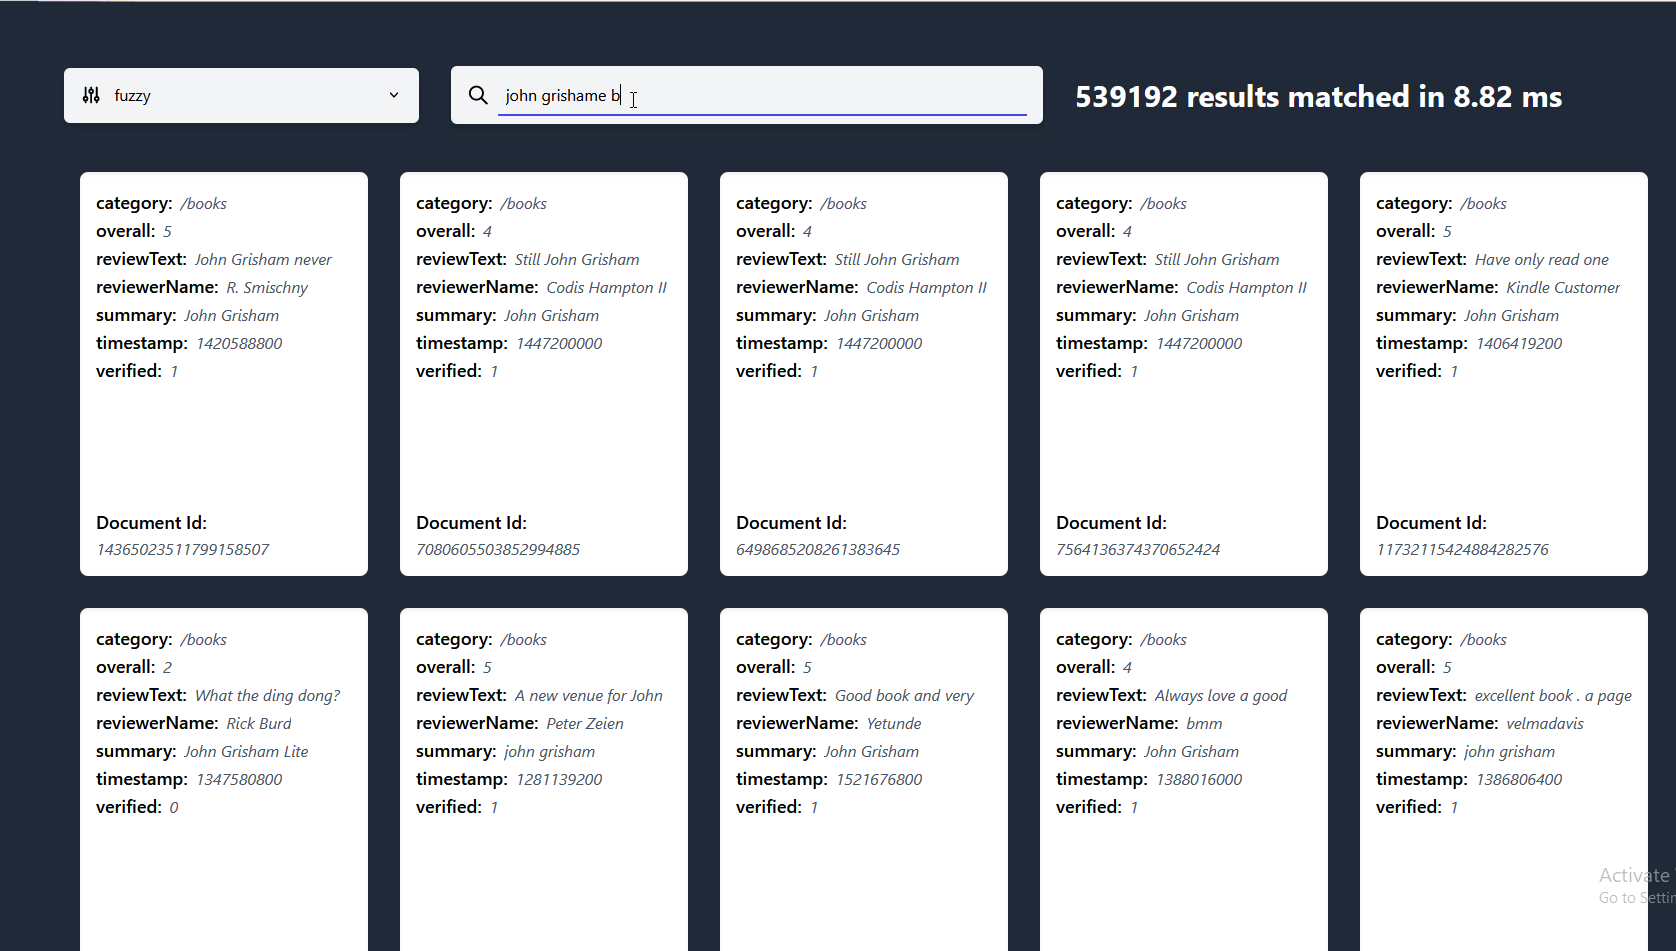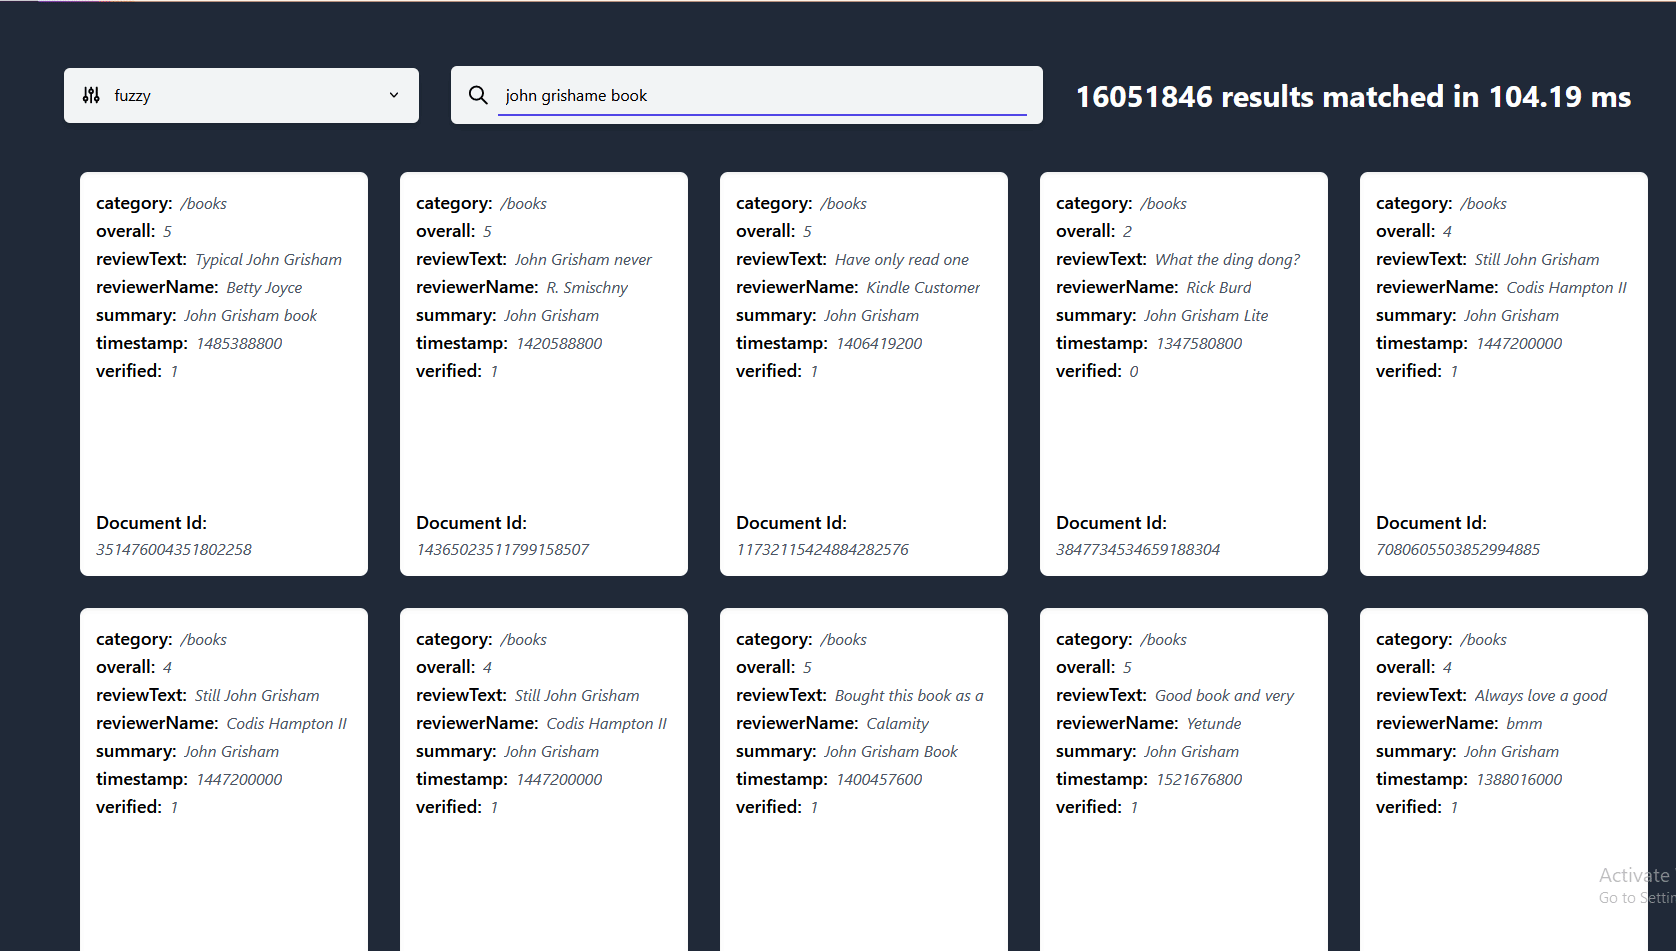
Here you can see lnx doing search as you type on a 27 million document dataset coming in at reasonable 18GB once indexed, ran on my i7-8700k using ~3GB of RAM with our fast-fuzzy system Got a bigger dataset for us to try? Open an issue!
Performance
lnx can provide the ability to fine tune the system to your particular use case. You can customise the async runtime threads. The concurrency thread pool, threads per reader and writer threads, all per index.
This gives you the ability to control in detail where your computing resources are going. Got a large dataset but lower amount of concurrent reads? Bump the reader threads in exchange for lower max concurrency.
The bellow figures were taken by our lnx-cli on the small movies.json dataset, we didn't try any higher as Meilisearch takes an incredibly long time to index millions of docs although the new Meilisearch engine has improved this somewhat.


💔 Limitations
As much as lnx provides a wide range of features, it can not do it all being such a young system. Naturally, it has some limitations:
- lnx is not distributed (yet) so this really does just scale vertically.
- Simple but not too simple, lnx can't offer the same level of ease of use compared to MeiliSearch due to its schema-full nature and wide range of tuning options. With more tuning comes more settings, unfortunately.
- Metrics (yet)
Building from scratch
Requirements
- rustc v1.81+
- sccache
- linux os
Explore related projects
Asabeneh/30-Days-Of-Python
The 30 Days of Python programming challenge is a step-by-step guide to learn the Python programming language in 30 days. This challenge may take more than 100 days. Follow your own pace. These videos may help too: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,303 starsgrafana/grafana
The open and composable observability and data visualization platform. Visualize metrics, logs, and traces from multiple sources like Prometheus, Loki, Elasticsearch, InfluxDB, Postgres and many more.
77,725 starsredis/redis
For developers, who are building real-time data-driven applications, Redis is the preferred, fastest, and most feature-rich cache, data structure server, and document and vector query engine.
77,268 starsapache/superset
Apache Superset is a Data Visualization and Data Exploration Platform
75,439 stars