
liampetti/fulloch
liampetti/fulloch has 166 GitHub stars and 11 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-09 21:59 UTC. Last push 2026-11-02.
Fulloch - The Fully Local Home Voice Assistant
What you can do
- Private, local by default - speech, language processing, notes, facts, and conversation history stay on your machine; web search, Spotify, and remote language models are explicit opt-ins
- Natural voice conversations - use the browser dashboard or connected satellites; Fulloch keeps conversational context, supports follow-up turns, and lets you barge in with the wakeword
- Your voice, your way - GPU and CPU stacks support voice cloning; ask it to whisper or speak quietly for per-turn reduced-volume delivery
- Obsidian notes and memory - read, write, append, and semantically search your vault by voice; remembered facts persist across restarts
Measured star growth
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalFulloch

The Fully Local Home Voice Assistant, a private voice layer for your notes, your home, and the web.
Fulloch is your privacy-focused local voice assistant running on your own PC or Mac. Ask questions, capture thoughts, and search your Obsidian vault by voice. Control your home via Home Assistant. Pull live answers from the web with SearXNG. The local stack keeps speech, language processing, notes, facts, and conversation history on your machine; optional web search, Spotify, and remote language models contact their configured services.
Click here to see the satellite companion project for running multiple ESP32-S3 satellites around your home.
Features
- Private, local by default - speech, language processing, notes, facts, and conversation history stay on your machine; web search, Spotify, and remote language models are explicit opt-ins
- Natural voice conversations - use the browser dashboard or connected satellites; Fulloch keeps conversational context, supports follow-up turns, and lets you barge in with the wakeword
- Your voice, your way - GPU and CPU stacks support voice cloning; ask it to whisper or speak quietly for per-turn reduced-volume delivery
- Obsidian notes and memory - read, write, append, and semantically search your vault by voice; remembered facts persist across restarts
- Smart-home control - control Home Assistant lights, locks, covers, climate, media, calendars, todos, weather, and more in natural language
- Music and reminders - find music with Spotify and play it through Home Assistant; create calendar reminders that Fulloch announces at the right time
- Live answers - get concise, source-aware summaries from self-hosted SearXNG web search, with the option to save results to your vault
- Deliberate research and planning - queue deeper background investigations for comparisons, academic literature, travel, and finance; research prefers Semantic Scholar and falls back to arXiv and OpenAlex, while optional SerpApi-backed travel and finance tools provide bounded, read-only results
- Home Assistant automation - use the HACS integration for status, mic control, proactive speech, chat, and scheduled deliberate-thinking tasks
Higgs TTS 3: The optional Higgs GPU backend is available only under Boson AI's Research and Non-Commercial License, not Fulloch's MIT license. It requires explicit consent for every voice reference. See Model Sources and Licenses.
Pocket TTS PyTorch: Premium uses Kyutai's GPU streaming runtime with a pinned, ungated mirror of its English voice-cloning weights. No Hugging Face account or token is required. Only clone voices with explicit, lawful consent. See Model Sources and Licenses.
openWakeWord feature extractors: The optional wakeword gate includes unmodified pre-trained feature extractor models from openWakeWord v0.5.1 under CC BY-NC-SA 4.0, not Fulloch's MIT license. See Model Sources and Licenses.
Quick installation
The default stack runs on CPU (mac/linux/windows). Audio runs through the browser dashboard. Choose regex-only commands, Laya semantic commands, or an off-box OpenAI-compatible language model in the wizard (e.g. Ollama / LM Studio / another machine on your LAN). The dashboard avatar swaps to Parloch, the Partially-local home voice assistant, when the LLM is running off-device.
Install Docker Desktop (or Docker Engine) first. The first run downloads the selected speech models, so it needs an internet connection, several GB of free disk, and enough Docker memory for the wizard's displayed estimate. For the GPU image, install a current NVIDIA driver and NVIDIA Container Toolkit, then confirm docker run --rm --gpus all nvidia/cuda:12.8.0-base-ubuntu22.04 nvidia-smi works before launching Fulloch.
CPU (mac/linux/windows)
docker run -d \
  --name fulloch-ai \
  --restart unless-stopped \
  --log-opt max-size=10m \
  --log-opt max-file=5 \
  -p 8765:8765 \
  -p 8766:8766 \
  -e DASHBOARD_HOST=0.0.0.0 \
  -v fulloch-data:/app/data:rw \
  ghcr.io/liampetti/fulloch:cpu
The named volume is repaired automatically on first boot and receives the bundled starter voice references. If you prefer a bind mount, use an existing writable directory such as -v "$PWD/data:/app/data:rw"; see data-directory permissions if startup reports a permission error. Open the HTTPS URL shown in docker logs fulloch-ai in a browser to continue the setup wizard. A self-signed certificate warning is expected on first visit; accept it to enable browser microphone access. Complete setup on a trusted network, then set a password in Settings → Dashboard before exposing the dashboard beyond it.
Add -v /path/to/your/ObsidianVault:/vault:rw before the image name to expose an Obsidian vault.
GPU (Linux/Windows + NVIDIA)
Swap :cpu for :latest (the CUDA image with Qwen3-TTS voice cloning and the on-GPU 9B SLM) and add --gpus all:
docker run -d \
  --name fulloch-ai \
  --restart unless-stopped \
  --log-opt max-size=10m \
  --log-opt max-file=5 \
  --memory=10g \
  --memory-swap=10g \
  --gpus all \
  -p 8765:8765 \
  -p 8766:8766 \
  -e DASHBOARD_HOST=0.0.0.0 \
  -v fulloch-data:/app/data:rw \
  ghcr.io/liampetti/fulloch:latest
The example limits container system RAM to 10 GiB and disables container
swap (--memory-swap equals --memory); --gpus all does not cap GPU VRAM.
Choose a limit appropriate to your models and leave sufficient RAM for the host
and other services. Too low a limit can kill model processes. Fulloch detects
Linux cgroup memory limits and monitors system memory headroom; on sustained
pressure it stops local inference and research, waits 300 seconds, and attempts
to restore the backend without replaying research. Without a container limit,
checks remain best effort and cannot isolate the VM from an OOM. A hard limit
and the monitor cannot guarantee recovery from all allocation spikes or driver
and hardware hangs. If the entire container is killed, Docker's restart policy
can restart it immediately; the in-process cooldown cannot survive that event.
If pressure persists after the cooldown, or a second emergency occurs, Fulloch
leaves the backend stopped rather than repeatedly reloading it.
Configure Docker itself, not config.yml, to change the limit.
OpenAI Endpoint
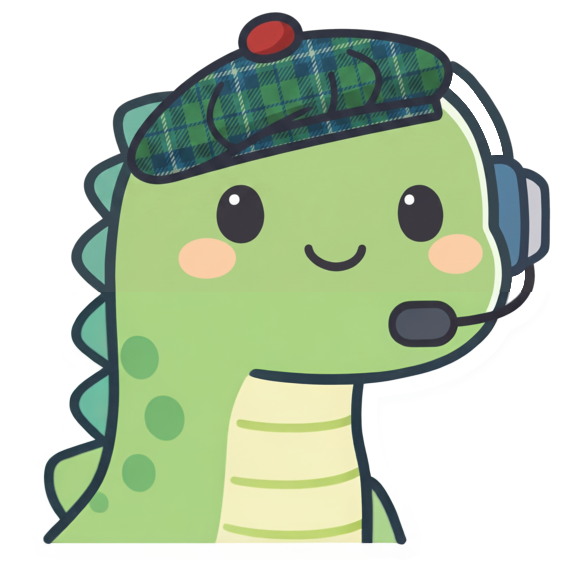
The moment you point the language model at an OpenAI-compatible endpoint, the avatar and favicon swap to a travelling version of the character (Let's call him Parloch: The Partially local home voice assistant), and the tagline reads "language model is off-device." Pick a local model again (None or the GPU 9B) and Fulloch comes home. It triggers as soon as a remote endpoint is configured, even if it is on your home network.
Recovering Or Reconfiguring
Use Settings for presets, voices, models, wakewords, notes, Home Assistant, web search, and dashboard access. Model changes need a restart; missing weights are downloaded for an already-completed installation, or setup reopens if needed. Hidden config-file options are preserved when unrelated controls are saved. Custom AI accepts a GGUF path on the GPU image or an OpenAI-compatible API address on either image.
Advanced options not shown in Settings are documented in data/config.example.yml: Spotify OAuth, native satellite tokens, and external-LLM timeouts. Keep those files under the persistent data volume.
Model options
The wizard has three steps: Preset and wakeword → Home Assistant → Web Search. Press Continue through all three for system-appropriate defaults; integrations are optional. Go back preserves your choices. Individual model selection is in Settings; GPU-only models are not offered on the CPU image. Download sources and licence details are in MODELS.md.
| Preset | GPU capacity class | AI | Speech-to-text | Text-to-speech |
|---|---|---|---|---|
| Max (experimental) | 32 GB | Qwen 27B | Qwen 1.7B GPU | Qwen 1.7B GPU |
| Pro | 16 GB | Ornith 9B | Qwen 1.7B GPU | Qwen 1.7B GPU |
| Premium | 12 GB | Ornith 9B | Orukeet GPU | Pocket PyTorch GPU |
| Economy | 8 GB | Ornith 9B | Moonshine Base CPU | Kokoro CPU |
| Lite | No GPU required | Laya + regex | Moonshine Base CPU | Kokoro CPU |
These are hardware classes, not precise model-memory estimates. The wizard recommends the highest available tier that fits; it falls back to Lite when no GPU tier fits or GPU information is unavailable. A 24 GB card can use Pro, or a custom 27B + Orukeet + Pocket stack through Settings; the full Max stack targets 32 GB.
| Component | CPU options | GPU options |
|---|---|---|
| Speech recognition (ASR) | Qwen3-ASR ONNX 1.7B or 0.6B; Parakeet TDT v3 ONNX 0.6B; Moonshine Base or Tiny | Qwen3-ASR PyTorch 1.7B or 0.6B; Qwen3-ASR GGUF 1.7B or 0.6B; NVIDIA Parakeet TDT 0.6B; Orukeet 0.6B |
| Text to speech (TTS) | Kokoro 82M; Pocket TTS ONNX voice cloning | Qwen3-TTS PyTorch 1.7B or 0.6B; Qwen3-TTS GGUF 1.7B or 0.6B; Pocket TTS PyTorch or GGUF; Audio8; Higgs TTS 3; Breeze TTS 2 |
| Language and command routing | Regex-only commands; Laya semantic commands; an external OpenAI-compatible endpoint | Local Qwen3.5 9B MTP, Gemma 4 12B, Ornith 1.5 9B, Qwen3.8 27B IQ4_XS (32 GB full stack), or a custom GGUF; an external OpenAI-compatible endpoint |
Choose Hey Atticus, Alexa, or Hey Jarvis in the wizard's preset step or Settings. All use local acoustic openWakeWord classifiers. Alexa/Jarvis weights have a CC BY-NC-SA 4.0 non-commercial license; they do not connect to Amazon or another voice service. Moonshine Base/Tiny and Parakeet ONNX trust the acoustic detector without ASR verification by default, avoiding rejection of names such as Atticus; the UI warns about possible false activations. Other ASR backends verify candidates by default. Custom wakeword models, names, regex and verification overrides are config-file only.
Obsidian Integration
Connect your Obsidian vault so Fulloch reads, writes, appends, and searches your notes by voice.
Just add your vault's directory as a volume when launching Docker container -v /Users/you/Documents/MyVault:/vault:rw
Set Settings → General → Notes directory to /vault (or your mount path).
The plugin is optional: the folder link alone supports reading, writing, appending, and searching notes. Advanced plugin setup is outside the web UI; see scripts/OBSIDIAN.md and scripts/setup_obsidian.py. Existing bridge configuration remains supported.
Home Assistant Integration
When Fulloch runs in Docker, enter Home Assistant's LAN address, for example http://192.168.1.50:8123. localhost refers to the Fulloch container, not Home Assistant.
For the HACS integration, create a Fulloch integration token in the wizard's Home Assistant step or Settings → Home Assistant → Connect from Home Assistant, then copy it into Home Assistant. This token lets Home Assistant connect to Fulloch; it is separate from the Home Assistant long-lived access token Fulloch uses to control devices. Use Fulloch's LAN address and integration API port (normally 8766). The integration API uses plain HTTP, so use it only on a trusted network. If Fulloch listens only on localhost, set its Dashboard Host to 0.0.0.0, set a dashboard password, and restart; ensure the integration port is exposed when using Docker. Token creation does not revoke existing integrations.
A HACS-installable integration for status sensors, mic control, proactive speech, and automation triggers.

| Entity | Description |
|---|---|
sensor.fulloch_status |
idle / thinking / speaking |
sensor.fulloch_last_utterance |
Last thing the user said |
sensor.fulloch_last_response |
Last thing Fulloch said (full_text attribute has the full string) |
sensor.fulloch_thinking_task |
Active deliberate-thinking task and status |
switch.fulloch_mic |
Mute / unmute the microphone |
text.fulloch_speak |
Submit text → Fulloch speaks it |
text.fulloch_chat |
Submit a query → full agent loop |
| Action | Field | Description |
|---|---|---|
fulloch.speak |
text |
Speak a message |
fulloch.chat |
text |
Run a full agent query and speak the result |
fulloch.mic |
enabled |
Turn the mic on or off |
fulloch.run_thinking_task |
task |
Queue a deeper background investigation |
fulloch.cancel_thinking_task |
job_id |
Cancel a queued or active investigation |
fulloch.get_thinking_task_status |
job_id |
Retrieve an investigation's current status |
| Event | When |
|---|---|
fulloch_wakeword_detected |
Voice turn starts |
fulloch_turn_ended |
Fulloch finishes speaking |
Instant Commands
Common commands take a regex fast-path that skips the language model entirely, for an instant response. Compound requests ("… and …"), vague references ("turn it off"), or conversation, falls through to the full agent.
| Say | Does |
|---|---|
| "turn on/off the fan" | on / off |
| "toggle the porch light" | toggle |
| "set the kitchen lights to 60 percent" | brightness |
| "dim / brighten the lights" | dim (30%) / brighten (100%) |
| "make the lamp blue" | colour |
| "turn the volume up / down" | volume |
| "lock / unlock the front door" | lock / unlock |
| "open / close the blinds" | covers |
| "play the Beatles" | music search & play |
| "stop" · "skip" · "resume" | media control |
| "set a timer for 5 minutes" · "list my timers" | timers |
| "what time is it" | time |
| "think about …" · "summarise your thinking" | thinking mode |
Laya semantic commands
Laya is a local CPU-only option between the regex fast-path and a full language model. Regex commands still run first; after a miss, Laya can recognise common command phrasing and select only from Fulloch's supported action schemas, using locally validated values and Home Assistant aliases.
It does not provide free-form conversation or generate arbitrary tool arguments. Choose Lite in the setup wizard when you want more flexible command phrasing without running a full LLM.
Reporting a Problem
Submit a Bug Report or a Feature Request.
Contributing
See CONTRIBUTING.md for how to add tools and submit changes.
Credits
Model download sources and licensing notes are listed in MODELS.md.
Voices in data/voices/:
atticus/tulloch- generated with Qwen3-TTS-12Hz-1.7B-VoiceDesign (Apache-2.0) from text descriptions; synthetic, not clones of real peoplecori- sample from Piperen_GB/cori/highby Bryce Beattie, trained on LibriVox recordings (MIT / public domain)All Kokoro voices- generated with Kokoro-82M (Apache-2.0)
Pocket TTS uses a selected data/voices/<name>.wav reference for one-shot cloning; use only voices you have permission to reproduce. The experimental official PyTorch backend streams PCM as it generates; the GGUF and ONNX options use independent conversions.
Development Disclosure
This project was developed with assistance from AI coding tools. Generated contributions are reviewed, tested, and maintained by the project author.
License
MIT - see LICENSE.
Explore related projects
affaan-m/ECC
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
300,811 starsNousResearch/hermes-agent
The agent that grows with you
262,449 starsmultica-ai/andrej-karpathy-skills
A single CLAUDE.md file to improve Claude Code behavior, derived from Andrej Karpathy's observations on LLM coding pitfalls.
231,864 starsfirecrawl/firecrawl
Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥
200,444 stars