
kiki-le-singe/epub-optimizer
kiki-le-singe/epub-optimizer has 40 GitHub stars and 3 forks. GitHot measured +1 stars in 24 hours. Last checked 2026-11-15 10:27 UTC. Last push 2026-11-13.
What you can do
- ✅ Can dramatically reduce file size - The original author workflow often produces files 70-90% smaller
- ✅ Validates before publishing - EPUBCheck must succeed before the requested output is replaced
- ✅ Offers explicit quality trade-offs - Choose balanced, lossless, or the complete author workflow
- ✅ Uses the EPUB package as source of truth - Discovers modern and legacy content through container.xml and the OPF manifest
Measured star growth
- in 24h
- +1
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Advanced EPUB optimizer: minifies HTML/CSS/JS, compresses and downscales images, subsets fonts, optimizes SVGs, and repackages EPUBs for smaller, faster, and standards-compliant e-books.
Creative & MediaREADME.md
OriginalEPUB Optimizer


A Node.js utility to optimize EPUB files by compressing HTML, CSS, images and recompressing the archive. This tool can significantly reduce EPUB file sizes while maintaining compatibility with e-readers and ensuring EPUB specification compliance.
Why Use EPUB Optimizer?
- ✅ Can dramatically reduce file size - The original author workflow often produces files 70-90% smaller
- ✅ Validates before publishing - EPUBCheck must succeed before the requested output is replaced
- ✅ Offers explicit quality trade-offs - Choose balanced, lossless, or the complete author workflow
- ✅ Uses the EPUB package as source of truth - Discovers modern and legacy content through
container.xmland the OPF manifest - ✅ Handles tricky EPUBs gracefully - Refuses DRM-encrypted books, leaves obfuscated/embedded fonts intact, and skips downscaling for fixed-layout titles instead of corrupting them
- ✅ Zero setup with Docker - No need to install Node.js, Java, or other dependencies
- ✅ Battle-tested - Used for real book publishing workflows
- ✅ Structured results - Optional JSON reports, strict mode, and per-step profiling
- ✅ Explicit controls - Generic, lossless, repair, and complete author workflows
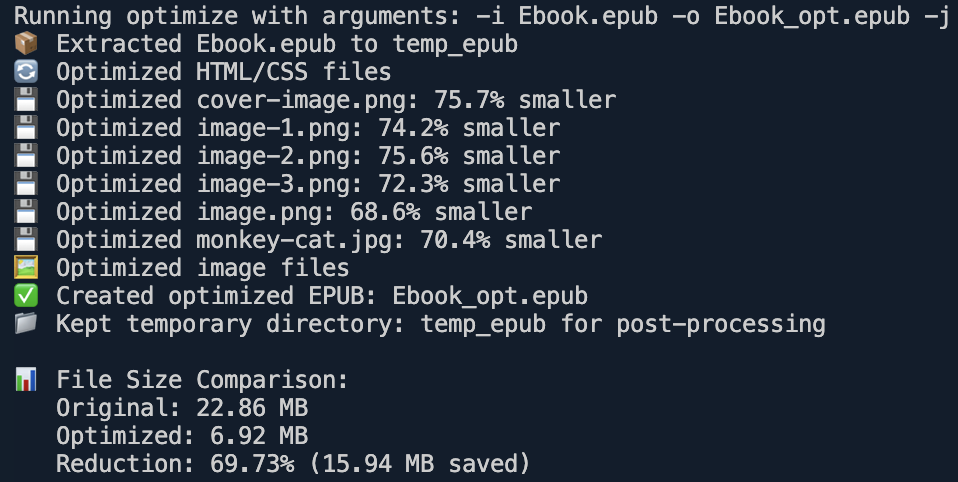
Results
Measured on an image-heavy EPUB with 12 full-page PNGs, with EPUBCheck-clean output. The input is 57 MB as printed by the CLI, which uses 1024-based units (60.0 MB on disk):
| Preset | Output | Reduction | EPUBCheck |
|---|---|---|---|
balanced (default) |
8.3 MB | −85.5% | 0 errors / 0 warnings |
author |
8.3 MB | −85.5% | 0 errors / 0 warnings |
repair |
8.3 MB | −85.5% | 0 errors / 0 warnings |
lossless |
~unchanged | by design (no lossy image changes) | 0 errors / 0 warnings |
The balanced row was remeasured with v3.8.0. The author and repair rows are earlier measurements and were not rerun for v3.8.0; the lossless row describes the preset's behavior.
Nearly all of the savings come from raster image optimization, so results scale with how image-heavy your book is. In this book, 11 of the 12 PNGs contain transparency: they stay PNG and shrink through palette quantization (--png-quality) and downscaling to the default 1600 px maximum dimension. Only the opaque cover is converted to JPEG, because PNG-to-JPEG conversion applies by default only to large PNGs without an alpha channel.
Memory was observed, not bounded by design. In local v3.8.0 runs of the balanced preset on this book (macOS arm64, Node.js 25, Java 25, default image concurrency), the Node.js process peaked at about 548 MiB (0.53 GiB) of resident memory. EPUBCheck then runs in a separate Java process, about 0.3 GiB here, which that figure excludes. These are single-machine observations, not limits: memory depends mainly on image dimensions and --image-concurrency.
Table of Contents
- Quick Start
- Migrating to v3
- Features
- About This Project
- Requirements
- Installation
- Local Package and Typed Node API
- EPUBCheck Setup
- Docker Alternative
- Usage
- Project Structure
- Development Information
- Linting and Formatting
- Minification
- Modular Fix Scripts
- Common Issues
- Troubleshooting
- Dependencies
- License
About This Project
I use this project to optimize EPUB files that I create using Pages on Mac. My workflow is:
- Write (text and images) in Pages.
- Create a manual summary page with bookmark links to chapters and sections. The author workflow preset can synchronize these subsections from the manual summary page to the system navigation files - both EPUB3 toc.xhtml and EPUB2 NCX - so they appear in e-reader navigation menus.
- Export my work as an EPUB file.
- Fill in the required information.
- For "Cover": check the option "Use the first page as the book cover image".
- For "Layout": check the reflowable option and "Use table of contents". For "Embed fonts", see the Important Note for Apple Pages Users section below to decide based on whether preserving your typography/design is important to you.
After exporting, my original EPUB file is about 24.4MB. I use the author workflow preset to optimize it (resulting in about 7.3MB). Then I test the result in Apple Books, Kindle Previewer, etc.
This project started with this workflow (I don't use any other tools), but anyone who wants to optimize their EPUB file is welcome to try it! The default pnpm optimize path is generic. My complete Pages/manual-summary workflow is available through pnpm optimize:author, --preset author, or --author-workflow. If you have any questions or issues, let me know. Enjoy! :)
⚠️ Important Note for Apple Pages Users
Apple Pages applies DRM encryption to embedded fonts for copyright protection. This means:
- ✅ Optional font optimization can work on eligible unencrypted TTF, OTF, WOFF and WOFF2 fonts when
--fontsis enabled - ❌ Font optimization WILL NOT work on Pages EPUBs if you check "Embed fonts"
- 🔒 Why? Apple encrypts fonts to protect font vendors from piracy (this is intentional and legal)
Your Decision: To Embed Fonts or Not?
This depends on whether preserving your book's design and typography is important to you.
Option 1: Keep "Embed fonts" checked (Preserve design - recommended if typography matters)
- ✅ Your embedded typography and intended design are preserved more consistently
- ✅ Consistent appearance across all e-readers
- ✅ Full control over typography
- ❌ Fonts remain at their original size (typically 1-3 MB total, can't be optimized due to DRM encryption)
- 📊 My image-heavy workflow still achieves about 85-90% total reduction from image/HTML/CSS optimization
Option 2: Uncheck "Embed fonts" (Maximum optimization - recommended if design is not critical)
- ✅ Maximum file size reduction potential - optimize images/HTML/CSS and optionally subset compatible fonts with
--fonts - ✅ Better performance - smaller files load faster
- ✅ More compatible - readers' preferred fonts are used (better accessibility)
- ✅ Cleaner output - no encrypted font files that can't be processed
- ❌ You lose control over typography - readers will see their default fonts
- ❌ Your book's appearance becomes unpredictable across devices
- ❌ Design integrity may be compromised
Choose based on your priority:
- Professional publications where typography matters → Embed fonts (accept 1-3 MB overhead)
- Maximum file size and performance → Don't embed fonts (lose design control)
Quick Start
Note: Traditional usage accepts absolute or relative file paths. Docker Compose automatically shares the repository directory with the container, so Docker commands also use simple relative paths.
Fastest: run the published image (no clone, no build):
docker run --rm -v "$PWD:/epub-files" ghcr.io/kiki-le-singe/epub-optimizer \
  -i YourBook.epub -o YourBook-optimized.epub
The image ships Node.js, Java, and EPUBCheck pre-installed and supports amd64 and arm64 (Apple Silicon).
Traditional installation:
pnpm install --frozen-lockfile
pnpm build
pnpm optimize -i YourBook.epub -o YourBook-optimized.epub
The default balanced preset performs generic optimization without running the modifying XHTML repair or author workflow passes.
Or use Docker Compose (recommended if you cloned the repository):
git clone https://github.com/kiki-le-singe/epub-optimizer.git
cd epub-optimizer
# Place YourBook.epub in this directory, then run:
docker compose run --build --rm optimizer \
  -i YourBook.epub -o YourBook-optimized.epub
The first run builds the image and optimizes the EPUB. Later runs can omit --build.
For the complete Pages/manual-summary author workflow:
docker compose run --rm optimizer \
  -i YourBook.epub -o YourBook-optimized.epub --preset author
Migrating to v3
Version 3 makes the default command safer and less specific to this project's original author workflow:
pnpm optimizenow uses the genericbalancedpreset. It does not apply XHTML repairs, lazy loading, or author structure changes unless explicitly requested.pnpm optimize:author,--preset author, and--author-workflowrun the complete Pages/manual-summary workflow, including repairs, lazy loading, cover navigation, summary synchronization, and chapter sections.- For behavior close to the old generic v2 pipeline without the author structure changes, use
pnpm optimize ... --repair --lazy-loading. - Input, output, and JSON report paths must be different. The output is created as a candidate and replaces the requested output only after EPUBCheck succeeds.
- Use
--strictto reject warnings,--profileto inspect step durations, and--report-jsonfor a machine-readable result.
Features
- Discovers the package/content root through
META-INF/container.xmland resolves navigation/resources through the OPF manifest - HTML/XHTML minification (removes comments and minifies embedded code while preserving text and significant whitespace)
- CSS optimization (minifies and combines rules)
- Image compression (JPEG, PNG, WebP, GIF, AVIF, and SVG according to the selected preset and quality settings)
- JPEG recompression applies EXIF orientation to the pixels before encoding, preserving the displayed rotation and mirroring.
- PNG to JPEG conversion for non-transparent images (significantly reduces file size)
- JavaScript minification (reduces script size)
- Optional font subsetting via
--fonts, using the included HarfBuzz WebAssembly engine with conservative content and font checks - SVG optimization (minifies SVG files using SVGO)
- Image downscaling (optionally resizes large images to a max dimension for e-reader compatibility)
- Lazy loading for images (adds
loading="lazy"to all<img>tags in XHTML for EPUB3 readers) - Cross-platform archive processing (pure JavaScript implementation with no external ZIP binaries)
- Archive recompression (EPUB-compliant ZIP packaging with proper compression settings)
- EPUB validation against the EPUB specification, with optional structured success and failure reports
- Transactional output publication after successful EPUBCheck validation
- Optional XHTML repair mode via
--repair - Optional author workflow preset (syncs subsections from a manual summary page, updates cover navigation, and applies the project author's structure fixes)
- Balanced, lossless, and author presets
- Strict failure mode, per-step profiling, and JSON run reports
- Non-destructive doctor/inspect mode for OPF, navigation, internal reference, image weight, and optimization-risk summaries
- Archive extraction limits, zip-slip and symlink rejection, and safe OPF/manifest/navigation path resolution
- Graceful handling of special EPUBs: detects
META-INF/encryption.xmland refuses DRM-encrypted books instead of silently corrupting them, while still optimizing books whose only encrypted resources are fonts (the fonts are left byte-for-byte intact) - Fixed-layout aware: automatically disables image downscaling for pre-paginated (
rendition:layout) EPUBs so page images stay aligned with the declared viewport - Animation-safe image processing: keeps animated PNG (APNG) files byte-for-byte unchanged, including when resizing is requested; preserves animated GIF/WebP/AVIF frames and timing during processing. Recompression that would grow an image is discarded unless its dimensions actually shrink. Image concurrency bounds parallel processing on image-heavy books.
- Modular fix scripts for EPUB and OPF structure
- Command-line interface with customizable options
- File size comparison reporting
- Automated unit, EPUBCheck E2E, and Docker E2E test suites
Note:
- Font subsetting limitation: fonts listed in encryption metadata remain byte-for-byte intact.
--fontsis opt-in and uses the included HarfBuzz engine; no separate font package installation is needed. Dynamic CSS/JavaScript text and unsupported font features are conservatively skipped. See Font subsetting for limits.- Lazy loading is enabled by the author preset or explicitly with
--lazy-loading.
Requirements
Only required for traditional installation (skip if using Docker):
- Node.js 22.12 or higher (CI validates Node.js 22 and 24; use Node.js 24 for development)
- Java Runtime Environment (JRE) 17 or higher for EPUBCheck (CI and Docker use OpenJDK 17)
- pnpm 10.30.3 for repository development and packing, pinned by
packageManager; the installed CLI/API runs directly on Node.js
Installation
# Clone the repository
git clone https://github.com/kiki-le-singe/epub-optimizer.git
cd epub-optimizer

# Install dependencies
pnpm install --frozen-lockfile

# Build the project (required before running optimize commands)
pnpm build
Local package and typed Node API
Build and inspect a local package without publishing it to a registry:
# From this repository; prepack rebuilds JavaScript and declarations first.
pnpm pack --out /tmp/epub-optimizer.tgz

# From a separate Node.js project:
pnpm add /tmp/epub-optimizer.tgz
bash node_modules/epub-optimizer/scripts/install-epubcheck.sh ./epubcheck
EPUBCHECK_PATH="$PWD/epubcheck/epubcheck.jar" pnpm exec epub-optimizer \
  -i book.epub -o book-optimized.epub --strict
The tarball contains compiled JavaScript, TypeScript declarations, README, license and the pinned EPUBCheck installer. It excludes TypeScript implementation sources, tests, development tools, local reports and books. Java and the EPUBCheck JAR are not bundled or downloaded during package installation; configure the JAR explicitly with EPUBCHECK_PATH as above. Docker remains the distribution that includes Java and EPUBCheck. Creating a tarball does not publish an npm release.
ESM consumers import the API and its types from the package root:
import { optimizeEPUB, type Args, type OptimizeOptions } from "epub-optimizer";

export async function optimizeBook(args: Args, hooks: OptimizeOptions = {}) {
  return optimizeEPUB(args, hooks);
}
Args still describes fully resolved processing options; this does not introduce a partial-options API or change defaults. Exported types also include Preset, ContentProcessingOptions, BatchReport, BatchItem, PipelineReport, StepReport, StepStatus and EpubCheckReport. Existing root and deep ESM imports remain available. The same Java/EPUBCheck validation and output protection apply to installed API calls.
pnpm test:package packs the project and installs the tarball with production dependencies into a new temporary consumer outside the repository, without dependency lifecycle scripts. It audits that consumer's production dependencies and verifies strict TypeScript usage (including rejected invalid types), CLI/API execution from another working directory, readable JavaScript stack locations, external EPUBCheck configuration and preservation of an existing output when the validator is missing. It requires Java, the pinned validator and registry access for consumer dependencies; it only uses generated EPUB fixtures. CI runs it on Node 22 and 24.
EPUBCheck Setup
This tool requires EPUBCheck to validate EPUB files. Follow these steps:
- Download EPUBCheck from the official website
- Extract the downloaded zip file
- Copy the extracted
epubcheck-x.x.xfolder (where x.x.x is the version) to the root of this project - Make sure the folder is named
epubcheckto match the path inepubcheckPathin src/utils/config.ts
Or simply run bash scripts/install-epubcheck.sh from the project root — it downloads and installs the pinned EPUBCheck version into epubcheck/ for you.
The default JAR is resolved from the installed package's epubcheck/ directory,
so the CLI can run from another working directory. Set EPUBCHECK_PATH to use a
different installation, for example:
EPUBCHECK_PATH=/opt/epubcheck/epubcheck.jar epub-optimizer -i book.epub -o book-opt.epub
An explicit relative EPUBCHECK_PATH is resolved from the current working
directory. EPUBCheck messages use English regardless of the JVM's language.
--strict enables EPUBCheck's native rejection of warnings and also rejects a
missing or unreadable validation totals. Totals come from JSON, with the native
text summary retained as a compatibility fallback when detailed JSON diagnostics
are unavailable. A nonzero validator exit or timeout always fails validation.
CI and Docker pin EPUBCheck 5.4.0 and its sha256 checksum centrally in scripts/install-epubcheck.sh (single source of truth); the download is verified against the checksum before installation.
Docker Alternative
You must have Docker installed with Docker Compose v2. Docker Desktop includes both.
Pre-built Image (GHCR)
Every release publishes a multi-arch image (amd64 and arm64, including Apple Silicon) to GitHub Container Registry. It is the fastest way to use the optimizer — no clone, no build, no Node.js or Java to install:
docker run --rm -v "$PWD:/epub-files" ghcr.io/kiki-le-singe/epub-optimizer \
  -i your-book.epub -o your-book-optimized.epub
Pin a specific release with a version tag, e.g. ghcr.io/kiki-le-singe/epub-optimizer:3.5.0 (images are published starting with v3.5.0). Building locally with Compose (below) remains fully supported and is the right choice when modifying the source.
Docker Compose provides a containerized environment with all dependencies pre-installed. It automatically mounts the repository directory, so the same relative EPUB paths work on Windows, macOS, and Linux. When working from a clone, Compose builds the image locally.
Docker Requirements
- Docker Desktop, or Docker Engine with Docker Compose v2
Docker Installation
# Clone the repository
git clone https://github.com/kiki-le-singe/epub-optimizer.git
cd epub-optimizer

# Build the local image (includes all dependencies)
docker compose build
Docker Quick Start
# Build when needed, then optimize an EPUB from the repository directory
docker compose run --build --rm optimizer \
  -i your-book.epub -o your-book-optimized.epub
Benefits of Docker approach:
- ✅ No need to install Node.js, Java, or pnpm
- ✅ Works consistently across all platforms (Windows, Mac, Linux)
- ✅ Includes EPUBCheck automatically
- ✅ Uses the dependency versions tested by the project
- ✅ Automatically mounts the working directory and accepts relative EPUB paths
- ✅ Runs non-root with no network, no Linux capabilities, and a read-only container filesystem
Usage
Available Scripts
| Script | Description |
|---|---|
build |
Build TypeScript for production (with minification) |
build:dev |
Build TypeScript for development (no minification) |
build:prod |
Build TypeScript with minification for production |
minify:safe |
Optional legacy minification of compiled JavaScript; not part of the production/package build |
optimize |
Run optimizer, keeping temp files |
optimize:author |
Run the complete project-author workflow, including repairs and structure updates |
optimize:repair |
Run generic optimization plus modifying XHTML repair passes |
optimize:lossless |
Avoid lossy image conversion, recompression, and resizing |
optimize:clean |
Run optimizer, removing temp files afterward |
cleanup |
Remove temporary files |
test |
Run tests in watch mode |
test:run |
Run tests once and exit |
test:coverage |
Run tests with coverage report |
test:package |
Install and verify a local tarball, its CLI/API and TypeScript declarations |
test:e2e |
Validate every public pnpm optimization workflow with fixtures and EPUBCheck |
test:docker |
Validate raw Docker and the complete Docker Compose workflow matrix with EPUBCheck |
release:check |
Validate a requested release version against package.json and optional tag/ref guards |
release:prepare |
Prepare a version PR, wait for Required CI, then merge into main (--dry-run to preview) |
lint |
Lint TypeScript files in src and scripts directories |
lint:fix |
Lint and auto-fix TypeScript files in src and scripts |
format |
Auto-format all .ts, .json, and .md files with Prettier |
format:check |
Check formatting of all .ts, .json, and .md files with Prettier |
Modern Workflow
# Build for development (faster, not minified)
pnpm build:dev

# Build for production (with minification)
pnpm build
# or
pnpm build:prod

# Then run the optimizer
pnpm optimize -i YourBook.epub -o YourBook-optimized.epub

# Or use the project author's Pages/manual-summary workflow
pnpm optimize:author -i YourBook.epub -o YourBook-optimized.epub

# Avoid lossy image changes
pnpm optimize:lossless -i YourBook.epub -o YourBook-optimized.epub

# Apply the explicit XHTML repair passes
pnpm optimize:repair -i YourBook.epub -o YourBook-optimized.epub

# Reject warnings, print timings, and write a machine-readable report
pnpm optimize -i YourBook.epub -o YourBook-optimized.epub \
  --strict --profile --report-json reports/optimization-report.json

# Inspect an EPUB without writing an optimized output
pnpm optimize --doctor -i YourBook.epub \
  --report-json reports/doctor-report.json

# Run tests
pnpm test
# or run tests once and exit
pnpm test:run
# run the EPUBCheck end-to-end fixture after pnpm build
pnpm test:e2e

# after docker compose build, run the raw Docker and Compose fixtures
pnpm test:docker
Command Line Options
Usage: epub-optimizer [options]

Options:
  -i, --input       Input EPUB file path                    [string] [default: "mybook.epub"]
  -o, --output      Output EPUB file path                   [string] [default: "mybook_opt.epub"]
  --batch           Directory of EPUB files to optimize (non-recursive)
  --output-dir      Destination directory required with --batch
  -t, --temp        Temporary directory for processing      [string] [default: unique temp_epub-<id>]
  --jpg-quality     JPEG compression quality (0-100)        [number] [default: 70]
  --png-quality     PNG compression quality (0-1 scale)     [number] [default: 0.6]
  --lang            UI language for labels (e.g. fr, en)    [string] [default: "fr"]
  --fonts           Enable experimental font subsetting      [boolean] [default: false]
  --preset          Optimization preset: balanced, lossless, author
  --repair          Apply potentially modifying XHTML repairs
  --author-workflow Enable the complete author workflow, including repairs
  --author-config   JSON overrides for the author workflow's summary, cover, and CSS class mapping
  --convert-png     Convert large opaque PNG files to JPEG when safe
  --png-background  Opt in to flattening eligible transparent PNGs onto #RRGGBB before JPEG conversion
  --no-convert-png  Disable PNG-to-JPEG conversion
  --lazy-loading    Add loading="lazy" to XHTML images
  --no-lazy-loading Disable lazy loading
  --max-image-dim   Maximum image width/height; 0 disables resizing
  --strict          Fail when a step emits warnings or errors
  --validation-timeout
                    Maximum EPUBCheck runtime in milliseconds [number] [default: 120000]
  --image-concurrency
                    Concurrent image operations, from 1 to 64 [number] [default: CPU parallelism, capped at 8]
  --profile         Print execution time for each pipeline step
  --report-json     Write a structured pipeline or batch summary report to JSON
  --report-html     Write a standalone HTML optimization or batch summary report
  --doctor, --inspect
                    Inspect an EPUB without optimizing or writing an output EPUB
  --clean           Clean temporary files after processing  [boolean] [default: false]
  -h, --help        Show help message                       [boolean]
  -v, --version     Show version number                     [boolean]

Examples:
  pnpm optimize -i book.epub -o book-optimized.epub            Basic optimization
  pnpm optimize:clean -i book.epub -o book-opt.epub            Optimize and clean temp files
  pnpm optimize -i book.epub -o book-opt.epub --jpg-quality 85 Higher JPEG quality (less compression)
  pnpm optimize -i book.epub -o book-opt.epub --png-quality 0.9 Higher PNG quality (less compression)
  pnpm optimize -i book.epub -o book-opt.epub --fonts          Enable font subsetting
  pnpm optimize:lossless -i book.epub -o book-opt.epub         Avoid lossy image changes
  pnpm optimize:repair -i book.epub -o book-opt.epub           Apply XHTML repair passes
  pnpm optimize:author -i book.epub -o book-opt.epub           Use the author's Pages/manual-summary workflow
  pnpm optimize -i input.epub -o output.epub --jpg-quality 85 --png-quality 0.8 Custom image settings
  pnpm optimize --doctor -i input.epub                         Inspect without modifying the EPUB
Script Differences:
pnpm optimize- Optimizes the EPUB file and keeps temporary files for inspectionpnpm optimize:lossless- Skips lossy image conversion, recompression, and resizingpnpm optimize:repair- Same as optimize, plus explicit XHTML repair passespnpm optimize:author- Complete author workflow: generic optimization, repairs, lazy loading, cover navigation, summary page, and chapter sectionspnpm optimize:clean- Same as optimize but removes temporary files afterwardpnpm cleanup <directory>- Removes a marked temporary directory from a previous run
Modes and Presets
| Behavior | balanced |
lossless |
author |
|---|---|---|---|
| HTML/CSS/JavaScript minification | Yes | Yes | Yes |
| SVG optimization | Yes | Yes | Yes |
| PNG-to-JPEG conversion | Yes | No | Yes |
| Raster image resize/re-encode | Yes | No | Yes |
| Default maximum image dimension | 1600 px | Disabled | 1600 px |
| Lazy loading | No | No | Yes |
| XHTML repairs | No | No | Yes |
| Author structure workflow | No | No | Yes |
balancedis the default generic preset. It optimizes content and images without applying XHTML repairs or author structure changes.losslessmeans no lossy raster processing. Text, CSS, JavaScript, and SVG files are still optimized, so the output is not byte-for-byte identical to the input.authorruns this project's complete Pages/manual-summary workflow and is equivalent topnpm optimize:author.--repairexplicitly enables the potentially modifying XHTML repair passes.- XHTML repair preserves valid scripts and text directly inside
<body>; it does not remove scripting from an EPUB. XHTML normalization also preserves quoted attributes and markup-like strings inside scripts. - All three repair passes discover nested
.xhtmlfiles case-insensitively and XHTML documents declared in the OPF manifest, including.htmland other extensions. Manifest paths are resolved relative to the OPF, so chapters may live outside its folder within the EPUB. Repair skips symbolic links and keeps valid microdata metadata, CDATA, and UTF-8 text. --author-workflowremains supported and always enables the complete author workflow, including repairs.--author-configoptionally adapts the author workflow to another summary/cover/class mapping. Without it, the original project-author workflow is unchanged.- Font subsetting is opt-in through
--fontsand is not enabled by any preset.
Applicable CLI options override preset defaults. For example, --preset balanced --no-convert-png disables PNG-to-JPEG conversion. The lossless preset always skips lossy raster processing, and the author workflow always includes repairs and author structure updates.
Optional background for transparent PNGs
By default, PNGs with an alpha channel are kept as PNG. To allow eligible transparent PNGs to be converted to JPEG, explicitly choose an opaque background:
pnpm optimize -i book.epub -o book-white.epub --png-background '#ffffff'
--png-background accepts only a six-digit hex color (#RRGGBB), including the #; quote it in the shell. There is no default background. This option also applies to each book in batch mode and is available to Node API callers as args.pngBackground.
Flattening permanently replaces transparency, including around captions, with the chosen color. White backgrounds can create visible white rectangles in dark reading modes. JPEG encoding is lossy; inspect text inside images, diagrams and edges in the target readers. EPUBCheck and content/text checks do not certify visual quality.
The existing conversion safeguards still apply: PNGs smaller than 200 KiB and animated PNGs are skipped; the JPEG must be smaller than the original PNG, have a manifest entry and have supported, safely rewritable references. Conversion and resizing share one encoding pass; an unsuccessful conversion retains the PNG. This is not a command to recolor every PNG. Opaque PNGs retain their existing conversion behavior. --png-background is rejected with --preset lossless, --no-convert-png, or doctor mode, rather than silently ignored. Existing commands and presets are unchanged when the option is omitted.
Safe temporary directories and validation deadlines
Each CLI run uses a unique temp_epub-<id> directory by default. An explicit
--temp <path> must not already exist: even an empty or previously used directory
is refused, so concurrent runs cannot overwrite one another. Existing directories
are never cleared during extraction. The console and JSON report (tempDir) show
the actual extraction path. --clean removes only the current run's marked
directory after successful publication. For a retained run, use
pnpm cleanup <directory>; unmarked directories and symbolic links are refused.
The hidden ownership marker is excluded from the output EPUB.
EPUBCheck has a 120-second deadline. Use --validation-timeout 300000 for larger
books that need up to five minutes. A timeout fails the run, discards the candidate,
and preserves any previous output and the extracted files.
HTML/XHTML text whitespace and SVG identifiers are preserved because external
stylesheets and references can depend on them. Named character references such as
or é (valid in EPUB 2) are rewritten as the equivalent numeric
references, and CDATA text outside scripts and styles is rewritten as escaped text:
the displayed characters are unchanged. XHTML minification keeps existing UTF-8
text in UTF-8.
XHTML documents are identified by their OPF media type as well as their extension
and XML markers. Before accepting minification, the optimizer compares element
nesting and order, identifiers, namespaces, and the position of character data. If these
change, it keeps the original document byte for byte and logs the skipped
optimization. Intentional inline CSS and JavaScript minification is excluded from
this comparison; final EPUBCheck validation still applies.
CDATA-wrapped or entity-escaped inline scripts and styles are kept as written.
CSS @import rules are kept instead of being inlined. External stylesheets,
<style> blocks and style attributes retain their CSS when the minifier reports
an error or warning, or offers no smaller result. XHTML styles also retain their
original CSS if minification would introduce XML delimiters. Raster recompressions
are committed only when smaller, unless they actually change the dimensions
requested by the user.
Font subsetting
--fonts enables HarfBuzz/WASM subsetting of eligible TTF, OTF, WOFF and WOFF2
fonts, preserving their container format, hinting, layout features, embedding
permissions and copyright/license text. It is disabled by default for every
preset. Original bytes are retained when there is no size benefit or processing
fails. The feature does not remove fonts or change the book's text or CSS.
The character pool includes nested XHTML, navigation, SVG, attributes and literal stylesheets across the archive, including Unicode NFC/NFD and case equivalents. For safety, the entire font step is skipped when it encounters scripts, MathML, embedded documents, imported/remote stylesheets, CSS variables, generated content, unsupported list markers or text transformations. This deliberately sacrifices some possible savings when displayed characters cannot be determined reliably. All fonts are preserved when encryption metadata exists. Variable, color, MathML/ Graphite and embedding/subsetting-restricted fonts are also preserved.
Fonts within each book are processed sequentially, with at most 16 fonts per book, 8 MiB per input font,
16 MiB per expanded font, 16 MiB of text resources, 4,096 resources and 65,536
collected code points. Each font runs in a disposable child process with a
10-second timeout and a 128 MiB V8 heap cap. Parent-side RSS sampling every 100 ms
terminates a worker observed above 256 MiB; this is a sampled budget, not an OS
hard memory limit, and short allocation spikes can exceed it. Monitoring is
supported on Linux (/proc) and macOS (/bin/ps); if it is unavailable, fonts
remain unchanged. Other platforms conservatively skip this optional feature.
These budgets apply per book/worker; concurrent API calls can run separate workers.
Failures and uncertain content produce report warnings; --strict can reject
these warnings while preserving an existing final EPUB. Known unsupported fonts
and absent size benefits are informational skips. EPUBCheck validates the final
candidate but does not certify font rendering on every reading system. A candidate
cleanup or ownership failure aborts optimization even without --strict, rather
than packaging a stray temporary font.
Image Concurrency
Use --image-concurrency 2 on memory-constrained machines, or adjust from 1 to 64.
The default is the available CPU parallelism capped at 8. The setting applies to
both PNG-to-JPEG conversion and image recompression. Lower values trade runtime for
lower peak memory; compare with --profile on representative books before tuning.
A local Node 24 measurement on the 60 MB example, for the image stage alone, gave:
| Concurrent images | Time | Peak Node RSS |
|---|---|---|
| 1 | 13.31 s | 210 MiB |
| 2 | 6.99 s | 307 MiB |
| 4 | 4.53 s | 417 MiB |
| 8 | 4.39 s | 429 MiB |
These are single measurements on one Mac, not cross-platform guarantees. All four runs produced identical raster bytes (SHA-256 comparison). Java memory is excluded.
Doctor / Inspect Mode
Use --doctor or --inspect to analyze an EPUB without publishing a candidate output and without modifying the input archive:
pnpm optimize --doctor -i book.epub
pnpm optimize --inspect -i book.epub --report-json reports/book-doctor.json
Doctor mode extracts the EPUB to a system temporary directory, reads container.xml and the OPF manifest, prints a console summary, writes JSON when --report-json is provided, and removes its temporary extraction directory. It does not run the optimizing processors and it does not replace EPUBCheck.
For supported books, the report includes OPF path/version, manifest and spine counts, EPUB3/NCX navigation presence, internal reference counts and missing targets, image byte totals and largest images, duplicate image basenames, large raster images, opaque PNG conversion candidates, and other optimization-risk hints.
Doctor checks internal DTD subsets and content DRM before interpreting package or content XML. When either blocks optimization, it prints the reason and writes analysisComplete: false, optimization.blocked: true, and structured blockers in optimization.blockers and risks. Detailed opf, navigation, references, images, and content fields are omitted rather than reporting misleading metrics. Font obfuscation alone remains inspectable. Exit code 0 means the diagnosis completed, including a diagnosis that finds a blocker; optimizing a blocked book still fails.
For a complete diagnosis, analysisComplete is true and optimization.blocked is false. These fields do not certify EPUB validity or replace EPUBCheck. Consumers of doctor JSON must check analysisComplete before reading detailed metrics.
Image reporting distinguishes images.totalBytes (uncompressed manifest image file bytes) from images.compressedBytes (the compressed ZIP payload of unique image resources). images.archivePercent uses compressed image bytes divided by the EPUB archive size, including ZIP overhead. Multiple manifest references to the same resource count once in the compressed share. When inspecting only an extracted directory without ZIP metadata, compressedBytes and archivePercent are null; uncompressed bytes are never presented as a percentage of compressed archive size.
Optional Author Workflow Configuration
pnpm optimize:author continues to use the original Pages/manual-summary conventions by default: chapter-2.xhtml, cover.xhtml, cover spine id cover, chapter classes p6/p8, section class p7, and navigation classes s3/s4.
For a different authoring workflow, create a JSON file containing only the values that differ:
{
  "summaryHref": "contents.xhtml",
  "coverSpineId": "front-cover",
  "chapterClasses": ["chapter-link"],
  "sectionClasses": ["section-link"],
  "summaryEntryClass": "chapter-link",
  "coverNavClass": "toc-cover",
  "sectionNavClass": "toc-section"
}
Then pass it to the same author command:
pnpm optimize:author -i book.epub -o book-optimized.epub \
  --author-config author-workflow.json
The configuration is validated before structure updates. Unknown keys, unsafe paths, and invalid class/id values fail the run while preserving the temporary directory for debugging.
Structured Reports and Profiling
--strictalso fails the run on processing or EPUBCheck warnings; processing and EPUBCheck errors always fail.--report-html reports/book.htmlwrites a standalone, offline HTML report with archive size changes, validation/publication status, step diagnostics and a byte/content comparison of extracted resources. It is available for optimization runs; doctor mode continues to use JSON.--profileprints each pipeline step's status and duration.--report-json reports/report.jsonwrites a structured report on success and on pipeline failures that occur after preflight path validation.- The report directory is created automatically. Local reports under
reports/are ignored by Git.
Processing diagnostics are emitted explicitly and collected within each asynchronous step; the optimizer does not replace global console methods or infer severity from message text. Step messages and strict warning/error handling retain their existing format. Custom API processing hooks should use the exported reportWarning(...args) and reportError(...args) helpers to participate in reports and strict checks. Ordinary console output remains display-only; thrown exceptions still fail the operation. Nested step diagnostics also reach the enclosing operation, while concurrent operations have separate collectors and completed steps stop collecting late callbacks. Batch processing remains sequential.
Once EPUBCheck runs, optimization reports include an optional validation object with its native exitCode, diagnostic source (json, text, or unavailable), version when available, totals (fatals, errors, warnings, infos), and detailed messages. Each message contains a code, uppercase severity, message, locations (path and available line/column/context), additionalLocations, and an optional suggestion. The same details appear in HTML reports and per-book batch reports, including failed runs. These fields are additive; existing step statuses and messages are retained, and doctor mode is unchanged.
EPUBCheck groups repeated messages and defaults to at most 25 occurrences per code/message combination; totals may exceed the detailed entries returned. Unknown line/column values are omitted. Publication metadata and unrelated raw validator fields are not copied into the optimization report. JSON diagnostics are read from a unique private temporary file with a 16 MiB limit and removed after the invocation. If they are missing, malformed, unsupported or too large, diagnosticsError explains that details are unavailable and the native text totals are used when readable. Strict mode still rejects warnings and unavailable totals; non-strict mode retains its native-exit fallback with an explicit warning when totals cannot be read. Fatal/error diagnostics also block publication even if a validator incorrectly exits with code 0.
HTML reports can be used alongside --report-json; all report paths must be distinct from the EPUBs and from each other, including symbolic/hard-link aliases. Reports are written on success and on processing/validation failures after preflight. A report write failure makes the command fail, while preserving any already-published validated EPUB. Resource hashing adds disk reads only when HTML reporting is requested. The report contains no external assets or scripts and escapes book-derived filenames and diagnostics. It contains local paths; review it before sharing. Added and removed resources can describe format conversion, and byte comparisons do not certify visual rendering.
pnpm optimize -i book.epub -o book-optimized.epub --clean \
  --report-html reports/book.html --report-json reports/book.json
Reports contain the configured input/output paths, preset, strict mode, timestamps, total duration, size reduction when available, per-step statuses/durations/messages, before/after content metrics, integrity checks, and the final error when a run fails:
{
  "input": "/books/input.epub",
  "output": "/books/output.epub",
  "preset": "balanced",
  "strict": true,
  "success": true,
  "durationMs": 1234,
  "content": {
    "before": {
      "manifestItems": 42,
      "spineItems": 18,
      "contentDocuments": 20,
      "images": 12,
      "navigationEntries": 36,
      "missingReferences": 0
    },
    "after": {
      "manifestItems": 42,
      "spineItems": 18,
      "contentDocuments": 20,
      "images": 12,
      "navigationEntries": 36,
      "missingReferences": 0
    },
    "integrity": {
      "valid": true,
      "newMissingReferences": [],
      "issues": []
    }
  },
  "steps": [
    {
      "name": "Extract EPUB",
      "status": "success",
      "durationMs": 42,
      "messages": []
    }
  ]
}
The report path must differ from the input and output EPUB paths and must be absent or a regular file. A report write failure fails the command.
Batch optimization
Optimize the regular .epub files directly inside a directory (case-insensitive extension, non-recursive):
pnpm optimize --batch books --output-dir optimized --preset balanced --clean \
  --report-json reports/batch.json --report-html reports/batch.html
Books are processed one at a time in filename order, using the same candidate validation and transactional output publication as single-book runs. Image concurrency still applies within each book. A failure is recorded and the remaining books continue. Exit code 0 means every book succeeded; exit code 1 means one or more books failed, or planning/report writing failed.
Outputs are named <original-stem>-optimized.epub. Per-book JSON reports are always written under <output-dir>/reports; requesting an HTML summary also creates per-book HTML reports there. Without --report-json, the JSON summary defaults to <output-dir>/batch-report.json. The summary lists each book's result, whether this invocation published a validated output, and any error. A later cleanup/report failure can mark a run failed even though its validated output was already published.
The entire path plan is checked before processing: input/output/report aliases, hard links, duplicate target names and file/parent collisions are rejected. EPUB input symlinks and symbolic-link directory roots are refused. Use a distinct output directory. Do not combine --batch with explicit --input, --output, --temp, or doctor mode. Empty directories fail without creating outputs. Each book receives a unique system temporary directory; --clean removes successful extraction directories while failed runs keep their diagnostics.
The exported runBatch(args) API returns the structured summary without setting a process exit code. Pass resolved options, including batch and outputDir; use optimizeEPUB(args) for single-book calls.
Safety Model
The exported optimizeEPUB(args) Node.js entry point uses the same pipeline as the CLI: content/text preservation checks, optional repair and author passes, candidate EPUBCheck validation, and transactional publication. Java and EPUBCheck must be available for API calls too; validationTimeout, strict, reportJson, and clean apply as they do in the CLI. Validation failure or timeout preserves an existing output. The supplied options object is copied before feature detection adjusts processing settings.
Advanced optimizeEPUB(args, { skipPackaging: true }) calls only prepare extracted content. They never create, replace or validate an output EPUB, and leave the extraction directory available even when clean is true. Processing hooks apply to the content-processing stage and do not replace final validation.
The final EPUB is transactional: the optimizer creates a hidden candidate next to the requested output, validates that candidate with EPUBCheck, and publishes it only after validation succeeds. If optimization, packaging, validation, or publication fails before the commit, the candidate is discarded, the previous output remains untouched, and any temporary processing directory already created is preserved for debugging.
Before parsing package metadata or optimizing content, every preset checks for internal DTD subsets in XML resources, regardless of their filename. These are refused with a message identifying the file, even without --strict: custom entity declarations can otherwise change displayed text while still passing EPUBCheck. This conservative check also refuses empty or comment-only internal subsets. Ordinary <!DOCTYPE html> and standard EPUB 2 external doctypes remain supported. The check does not resolve entities or fetch external DTDs. For affected books, expand the internal declarations to literal text or numeric character references with a tool that supports them before optimizing. A refusal preserves the input, any existing output, and the extracted files for inspection.
Before packaging, the optimizer also compares the extracted EPUB before and after processing. Publication is blocked if manifest, spine, document, image, or navigation counts decrease, or if processing introduces a new missing internal reference. Existing input issues remain visible in the report without turning a previously processable EPUB into a false failure.
The text of every content document is also compared before and after the optimizing and repair passes (the Validate text preservation step). Scripts, styles, comments and markup are ignored and character references are resolved, so re-encoding is accepted, but publication is blocked if any displayed character is lost or altered. The check runs before the author workflow, whose navigation and summary edits are intentional.
SVG resources are included: text, titles, accessibility descriptions and foreign object content are checked. Editor metadata and formatting whitespace between graphical elements are ignored. HTML/XHTML documents throughout the archive are checked, including secondary renditions.
Cleanup and JSON report writing happen after the validated EPUB is published. If either of these later operations fails, the command exits non-zero but keeps the newly published, EPUBCheck-validated output.
Input, output, and report collisions are rejected, including aliases through symbolic links or hard links and case-only aliases on macOS/Windows. Existing output and report targets must be regular files.
Temporary-directory cleanup is guarded: the optimizer refuses filesystem roots, the current working directory, the home directory, and any temp directory containing the input or output EPUB. Manual cleanup requires the optimizer's ownership marker and rejects symbolic links. The build cleanup script also refuses paths outside the project or system temp directories.
Archive extraction rejects unsafe absolute/traversal paths and symbolic links. It also limits archives to 20,000 entries, 512 MB per file, 2 GB total extracted size, and a maximum compression ratio of 1000:1.
META-INF/container.xml and the OPF package document are the source of truth for content discovery. OPF and navigation references are resolved safely and cannot escape the extracted EPUB root.
Docker Usage
Docker Compose is the recommended cross-platform Docker interface. It automatically builds or reuses the local image, mounts the repository at /epub-files, and lets the CLI use normal relative paths.
First run or rebuild after updating the repository:
docker compose run --build --rm optimizer \
  -i book.epub -o book-optimized.epub
Later runs:
docker compose run --rm optimizer \
  -i book.epub -o book-optimized.epub
Custom image quality:
docker compose run --rm optimizer \
  -i book.epub -o book-optimized.epub \
  --jpg-quality 50 --png-quality 0.4
Complete author workflow:
docker compose run --rm optimizer \
  -i book.epub -o book-optimized.epub \
  --preset author --clean
Author workflow with an optional configuration file:
docker compose run --rm optimizer \
  -i book.epub -o book-optimized.epub \
  --preset author --author-config author-workflow.json
Compose command breakdown:
docker compose run- Run theoptimizerservice defined incompose.yaml--build- Build or refresh the image before running; needed on the first run and after code updates--rm- Remove the stopped one-off container after processing- Arguments after
optimizerare passed directly to the EPUB optimizer
By default, Compose shares the repository directory with the container. Place EPUB files in that directory and use their normal relative names. Temporary files also appear there unless --clean is used.
Advanced: raw Docker
Raw docker run remains supported, but its bind-mount syntax varies by shell. The image now works from /epub-files, so the EPUB arguments themselves remain relative:
docker build -t epub-optimizer .
docker run --rm -v "$PWD:/epub-files" epub-optimizer \
  -i book.epub -o book-optimized.epub
Debugging with Temporary Files
Traditional usage:
# Keep temp files for inspection (default behavior)
pnpm optimize -i book.epub -o book-opt.epub
# Inspect the temp_epub-<id>/ directory reported by the command

# Custom temp location
pnpm optimize -i book.epub -o book-opt.epub -t my-debug-folder

# Clean up when done
pnpm cleanup my-debug-folder
Docker usage:
# Temp files automatically appear in your current directory
docker compose run --rm optimizer \
  -i book.epub -o book-optimized.epub
# Inspect the reported temp_epub-<id>/ directory on your host

# Custom temp location (still visible on host)
docker compose run --rm optimizer \
  -i book.epub -o book-optimized.epub \
  -t my-debug-folder

# Clean temp files after processing
docker compose run --rm optimizer \
  -i book.epub -o book-optimized.epub \
  --clean
What's in the temp directory?
- Extracted EPUB structure
- Processed HTML/CSS/JavaScript files
- Optimized images
- Modified fonts only when
--fontsis enabled - All intermediate processing artifacts
This is invaluable for debugging optimization issues or understanding what the tool does to your EPUB.
Failures before successful cleanup preserve temporary files even when --clean was requested. This keeps the failed processing state available for debugging. A later report-writing failure can occur after cleanup and publication have already succeeded.
Project Structure
epub-optimizer/
├── .github/workflows/
│   ├── ci.yml                 # Audit, shared quality/Docker checks, and Required CI gate
│   ├── docker-check.yml       # Shared native AMD64/ARM64 Docker E2E and image scans
│   ├── epubcheck-watch.yml    # Weekly check for new EPUBCheck releases (opens an issue)
│   ├── prepare-release.yml    # Prepare and merge a checked release PR to main
│   ├── quality.yml            # Shared Node 22/24, coverage, lint, types, and EPUBCheck checks
│   ├── release-published.yml  # Promote tested image digests and sync main into develop by PR
│   ├── release.yml            # Validate candidates, tag the source, and create a release draft
│   └── security-audit.yml     # Required production audit, also available weekly/manually
├── compose.yaml            # Recommended cross-platform Docker interface
├── Dockerfile              # Multi-stage production container image
├── docker-entrypoint.sh    # Docker defaults and CLI entrypoint
├── docs/RELEASING.md        # Release preparation, publication, diagnostics, and recovery
├── dist/                   # Compiled JavaScript (production code)
├── package.json            # Package configuration
├── README.md               # Documentation
├── tsconfig.json           # TypeScript configuration
├── vitest.config.ts        # Test configuration
├── epubcheck/              # EPUBCheck for EPUB validation (not included in repo)
├── scripts/                # Build and maintenance scripts
│   ├── clean-path.ts          # Guarded cleanup helper used instead of rm -rf
│   ├── docker-e2e.ts          # Docker fixture test runner
│   ├── e2e-epubcheck.ts       # Local fixture test runner with EPUBCheck
│   ├── install-epubcheck.sh   # Single source of the EPUBCheck version (CI + Docker)
│   ├── minify-dist.ts         # Optional legacy minification, outside the default build
│   ├── package-e2e.ts         # Installed tarball, CLI/API and TypeScript checks
│   ├── prepare-release.ts     # Prepare and validate a release PR (pnpm release:prepare)
│   └── validate-release.ts    # Release version/tag/ref guards (pnpm release:check)
└── src/                    # Source code directory
    ├── index.ts            # Validated Node.js API entry point
    ├── batch.ts            # Sequential batch planning, reports and execution
    ├── optimization.ts     # Shared API/CLI validation and publication pipeline
    ├── pipeline.ts         # CLI entry point for the shared optimization pipeline
    ├── cli.ts              # yargs-based argument parser
    ├── types.ts            # TypeScript type definitions
    ├── types.d.ts          # Additional TypeScript declarations
    ├── processors/         # Content-processing modules
    │   ├── epub-processor.ts       # Extraction and content processing without publication
    │   ├── archive-processor.ts    # EPUB extraction/compression (zip-slip safe)
    │   ├── html-processor.ts       # HTML/CSS processing
    │   ├── js-processor.ts         # JavaScript minification
    │   ├── svg-optimizer.ts        # SVG optimization
    │   ├── lazy-img.ts             # Add loading="lazy" to <img>
    │   ├── font-processor.ts       # Optional font subsetting
    │   ├── image-converter.ts      # PNG → JPEG conversion (parallel)
    │   └── image-processor.ts      # Resize + re-encode (single-pass, parallel)
    ├── scripts/            # Post-processing steps (exported run(opts) fns)
    │   ├── create-epub.ts  # Package the final EPUB archive
    │   ├── validate-epub.ts # Run EPUBCheck via java
    │   ├── utils.ts        # Shared helpers (RunOpts, isEntryPoint, …)
    │   ├── fix/            # General XHTML fix scripts (modular)
    │   │   ├── fix-span-tags.ts
    │   │   ├── fix-xml.ts
    │   │   ├── remove-empty-styles.ts
    │   │   ├── xhtml-files.ts # Shared recursive and manifest-based repair discovery
    │   │   └── index.ts    # runFixes(): call every fix in sequence
    │   └── ops/            # EPUB structure modifications
    │       ├── add-cover-image-property.ts
    │       ├── update-cover-linear.ts
    │       ├── update-toc-with-cover.ts
    │       ├── update-summary-page.ts
    │       ├── add-chapter-sections-to-toc.ts
    │       └── update-structure.ts # runStructureUpdates(): call every op
    └── utils/              # Utility modules
        ├── config.ts       # Application configuration
        ├── epub-utils.ts   # OPF / TOC file discovery
        ├── output-transaction.ts # Candidate output commit/rollback
        ├── author-workflow-config.ts # Optional validated author workflow mapping
        ├── epub-doctor.ts    # Non-destructive EPUB inspection and optimization-risk summary
        ├── epub-integrity.ts # Before/after content metrics and regression checks
        ├── epub-text.ts      # Before/after text preservation check
        ├── path-safety.ts  # Safe path resolution inside the extracted EPUB
        ├── pipeline-options.ts # Preset resolution
        ├── run-report.ts   # Structured results and profiling
        └── i18n.ts         # Localized label lookup
Note: Test files are colocated with their respective source files but omitted from this structure for clarity.
Development Information
This project is built with TypeScript and uses modern ESM modules. Here's how the development workflow works:
Source and Build Separation
- TypeScript source files are in the
src/andscripts/directories - The compiled JavaScript output goes to the
dist/directory - The production build contains:
- Test files (
*.test.ts) are completely excluded - TypeScript declaration files (
*.d.ts) for the API and its referenced types - No source maps are included
- Readable JavaScript with comments and function names, so stack locations point to inspectable code
- Test files (
- You must run
pnpm buildbefore running anyoptimizecommands
Import Structure
- The project uses TypeScript's
NodeNextmodule resolution, which mirrors Node.js ESM semantics exactly - Relative imports must include the explicit
.jsextension in source files (e.g.,import { foo } from './foo.js'), matching what Node.js resolves at runtime - Type-only imports use
import type(enforced byverbatimModuleSyntax) so they are fully erased at build time
Testing
- Test files are colocated with the source files they test (e.g.,
src/index.tsandsrc/index.test.ts) - This "side-by-side" approach has several advantages:
- Easy to locate tests for any module
- Promotes keeping tests updated when changing implementation
- Makes it clear which parts of the codebase are covered by tests
- Simplifies relative imports between tests and implementation
- Tests are written using Vitest, a modern test framework compatible with Jest syntax
- Run tests with
pnpm test(watch mode) orpnpm test:run(single run) - Run tests with coverage using
pnpm test:coverage pnpm test:e2eruns the publicoptimize,optimize:clean,optimize:lossless,optimize:repair, andoptimize:authorcommands, including a configured author workflow- Every pnpm E2E output is checked for content integrity and validated with EPUBCheck; clean/keep-temp behavior and workflow-specific transformations are also verified
- The author E2E fixture also checks before/after content integrity, sequential NCX navigation, and a maximum output-size ratio to catch compression regressions
pnpm test:dockervalidates raw Docker balanced/author/fonts plus Docker Compose balanced, lossless, repair, author, and configured-author workflows- Docker E2E verifies reports, content integrity, EPUBCheck output, workflow-specific transformations, and clean/keep-temp behavior
- CI validates the project on Node.js 22 and 24, and runs the Docker E2E workflow on Node.js 24
- Unit tests run in a Node.js environment and mock external dependencies where appropriate
Production Validation
Use Node 24 LTS for development and release checks (.node-version); the minimum
supported runtime is Node 22.12. Install with pnpm install --frozen-lockfile.
CI validates Node 22 and 24, coverage, formatting, EPUBCheck and Docker workflows.
The production dependency audit is required by every CI and release run, including
release retries; it also runs weekly and can be started manually.
Publishing a prerelease promotes its tested image to the version tag without changing latest.
Release Validation
Run Prepare release from main in GitHub Actions with the next version after develop's CI passes. It prepares a PR, waits for Required CI, merges through branch rules and dispatches the shared validation and native AMD64/ARM64 image tests. Release creates a draft with the tested image digests; publishing that draft promotes the same images to their version tag and, for stable releases, latest, then synchronizes develop. Release retries preserve existing notes and reuse recorded images.
The local pnpm release:prepare X.Y.Z command uses the same PR flow with authenticated Git/GitHub CLI access; follow it by dispatching Release from main with the printed expected-sha. Configure the dedicated repository-scoped release App before using the automated workflows. See Releases and CI for setup, diagnostics, scan policy, prereleases and recovery.
Before creating a release manually, run the CI quality gates plus coverage, audit, and local Docker checks:
pnpm release:check --version "$(node -p 'require("./package.json").version')"
pnpm lint
pnpm format:check
pnpm build
pnpm test:run
pnpm test:coverage
pnpm audit --prod
pnpm test:e2e
docker compose config --quiet
docker compose build
pnpm test:docker
Also validate a representative real EPUB through both execution paths:
pnpm optimize:author -i YourBook.epub -o YourBook-pnpm.epub \
  --strict --report-json reports/YourBook-pnpm-report.json

docker compose run --rm optimizer \
  -i YourBook.epub -o YourBook-docker.epub \
  --preset author --strict --report-json reports/YourBook-docker-report.json
A successful release candidate exits with code 0, passes EPUBCheck without errors or warnings in strict mode, and produces reports with "success": true and "content.integrity.valid": true.
Development and Production
- For development: Make changes to TypeScript files and run
pnpm build:dev - For production: Run
pnpm buildto create readable JavaScript and API declarations indist/ - The
optimizecommands run against the compiled code indist/
Linting and Formatting
- Linting:
pnpm run lintlints all TypeScript files in thesrcandscriptsdirectories.pnpm run lint:fixdoes the same, but also auto-fixes issues where possible.
- Formatting:
pnpm run formatauto-formats all.ts,.json, and.mdfiles in the project using Prettier.pnpm run format:checkchecks formatting without making changes (useful for CI).
Minification
JavaScript embedded inside EPUBs is still minified with Terser. The optimizer's own Node.js code is compiled without application minification so stack traces retain useful file/line/column locations. Source maps are not needed to read those JavaScript locations and are not shipped by the production build.
The legacy pnpm minify:safe command remains available as an explicit development-tool opt-in; it reduces readability and is not called by pnpm build. pnpm pack runs a clean build through prepack, regenerating readable JavaScript and declarations before creating the tarball.
Modular Fix Scripts
Every processing step is a plain async function. pipeline.ts runs them all in-process (no sub-process spawns), forwarding a shared { tempDir, lang, output } down the chain.
- Explicit repair passes (span tags, XML/XHTML sanity, empty styles) live in
src/scripts/fix/. They run only with--repairor the author workflow because they intentionally modify document structure. - Author workflow structure modifications (cover linear, TOC, summary page, chapter sections) live in
src/scripts/ops/.src/scripts/ops/update-structure.tsexportsrunStructureUpdates(opts), and the pipeline runs it only when--author-workflowis enabled. - To enable/disable a step, comment or uncomment the corresponding
await …(opts)call in the matching orchestrator file. - To add a new step, create a script that exports
async run(opts: RunOpts)and add anawait run(opts)line in the orchestrator. - Each leaf script also auto-runs when executed directly (
node dist/src/scripts/fix/fix-xml.js); theisEntryPoint()guard keeps that from firing on import.
Customizing the Optimization Process
Use the default generic optimizer for EPUBs that do not need the project author's Pages/manual-summary workflow:
pnpm optimize -i book.epub -o book-opt.epub
If you do want the complete Pages/manual-summary workflow, enable the author preset:
pnpm optimize:author -i YourBook.epub -o YourBook-optimized.epub
# equivalent:
pnpm optimize -i YourBook.epub -o YourBook-optimized.epub --preset author
The existing project-author conventions remain the defaults. To adapt summary/cover paths or CSS classes without editing source code, use --author-config author-workflow.json as documented under Optional Author Workflow Configuration.
For deeper source-level customization, there are two levels of granularity:
Wholesale (in src/pipeline.ts) — comment out an entire step to disable a whole group at once:
- Omit
--repairand the author preset to skip all modifying XHTML repair passes. - Omit
--author-workflow/--preset authorto skip all author workflow structure updates. - EPUBCheck validation is required for transactional publication. When a run fails, inspect the preserved temporary directory instead of disabling validation.
Granular (in the orchestrator files) — keep some steps, skip others:
- Example: Skip adding cover to TOC — comment out
await updateTocWithCover(opts)insrc/scripts/ops/update-structure.ts - Example: Skip adding cover to summary page — comment out
await updateSummaryPage(opts)in the same file - Example: Skip setting cover as first page — comment out
await updateCoverLinear(opts)in the same file - Example: Skip chapter sections synchronization — comment out
await addChapterSectionsToToc(opts)in the same file (useful if you don't have subsections in your manual summary page) - Example: Disable specific XML/HTML fixes — comment out the relevant
await …(opts)call insrc/scripts/fix/index.ts
After making any customizations, rebuild the project with pnpm build to apply your changes.
Common Issues
Docker Issues
"docker: command not found"
- Install Docker first: Download Docker
- Make sure Docker Desktop is running
"docker compose is not a docker command"
- Install Docker Compose v2 or update Docker Desktop
- Verify with
docker compose version
"Permission denied" or file access errors
- Ensure your EPUB file is in the project root or mounted directory
- Check file permissions (especially on Linux/Mac)
Traditional Installation Issues
"Java not found" or EPUBCheck errors
- Install Java JRE 17+ (see Requirements)
- Download EPUBCheck manually (see EPUBCheck Setup)
"pnpm command not found"
- Install pnpm:
npm install -g pnpm
Build errors
- Run
pnpm buildbefore usingpnpm optimize - Try
pnpm installif dependencies are missing
File Issues
"Input file not found"
- Check your file path and name (case-sensitive)
- Make sure the EPUB file is in the correct directory
- Use relative paths from the project root
"Output file permission errors"
- Check write permissions in the output directory
- Try a different output filename
Troubleshooting
If you encounter any issues, please check the GitHub issues page for existing issues or open a new one.
Dependencies
This project uses the following dependencies:
System Requirements
- Node.js 22.12 or higher (Node.js 24 for development)
- Java Runtime Environment (JRE) 17 or higher (for EPUBCheck validation)
- pnpm 10.30.3
Key npm Packages
- cheerio - For robust HTML/XHTML DOM manipulation
- entities - For resolving HTML named character references in XHTML
- clean-css - For CSS minification
- fs-extra - Enhanced file system operations
- html-minifier-terser - For HTML minification
- sharp - For image optimization (JPEG, PNG, WebP, GIF, AVIF, SVG)
- unzipper - For extracting EPUB files
- yazl - For cross-platform EPUB archive creation (pure JavaScript ZIP implementation)
- yargs - For command-line argument parsing
Development Dependencies
- typescript - For static typing and compilation
- terser - For JavaScript minification
- vitest - For testing
- typescript-eslint - For linting TypeScript code
- prettier - For code formatting
License
This project is licensed under the MIT License. See the LICENSE file for more details.