
jirikuncar/sqlty
jirikuncar/sqlty has 76 GitHub stars and 2 forks. GitHot measured +1 stars in 24 hours. Last checked 2026-11-16 20:59 UTC. Last push 2026-11-13.
Measured star growth
- in 24h
- +1
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Type-safe raw SQL for Python: infer row and parameter types from SQL strings and your schema, checked by mypy, Pyright or ty, no database needed
DataREADME.md
Original


Your SQL already knows its types. SQLTy tells Python.
Type-safe raw SQL without an ORM or a database connection. sqlty reads row and parameter types from your SQL and schema, and checks them on every commit, so a migration that changes a column is caught in review, not in production.
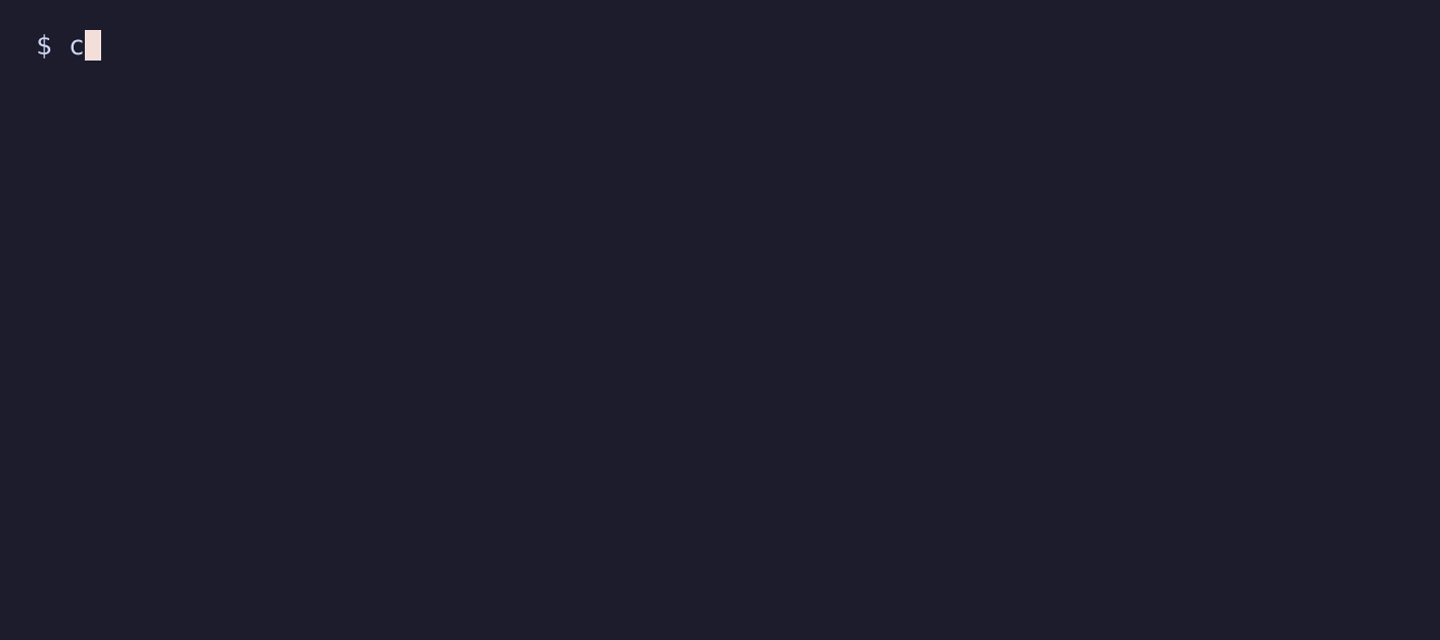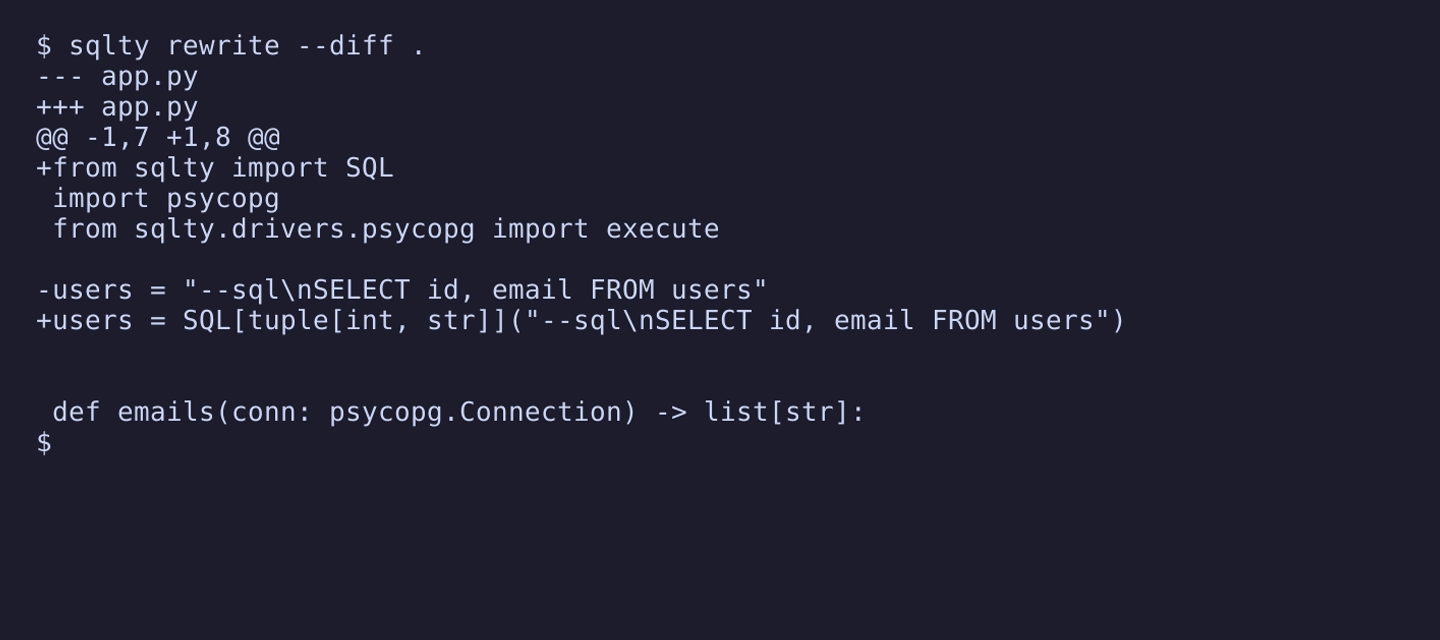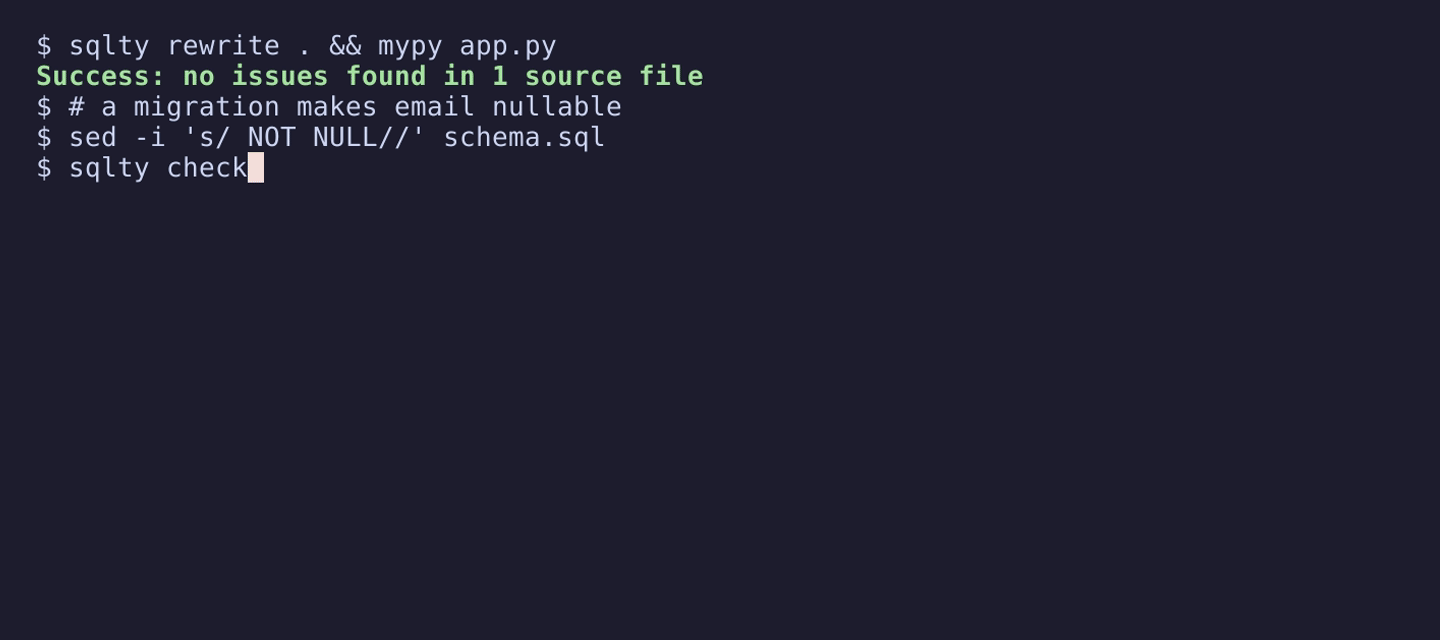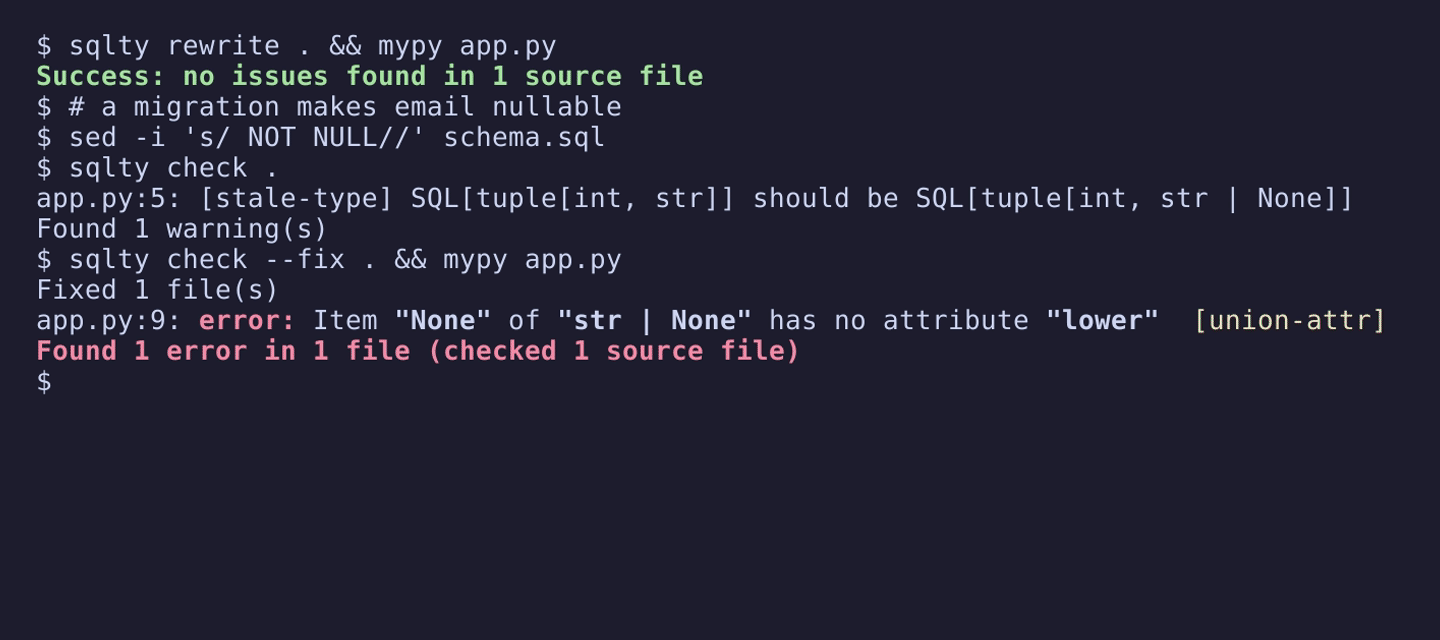
A migration makes email nullable. sqlty and mypy find the code that would crash.
(view source)
Documentation: sqlty.kuncar.dev · Try it in your browser: Playground
Fits if you write SQL as string literals on Python 3.14+, against PostgreSQL, SQLite or MySQL, with a schema dump or SQL migrations in the repository. Rows are typed end to end with psycopg 3; with other drivers sqlty checks the query and its parameters, and you annotate what the cursor returns (Drivers).
Beta. APIs and configuration may change before 1.0. Feedback welcome in GitHub Issues.
How it works
Drivers return rows of Any, so nothing ties a query's columns to the code
that reads them. Start a query with --sql and a newline, and
sqlty rewrite . adds the row type inferred from your CREATE TABLE
statements:
# pyproject.toml
[tool.sqlty]
schema = "schema.sql"
schema.sql:
CREATE TABLE users (id INTEGER PRIMARY KEY, name TEXT NOT NULL, email VARCHAR(255) NOT NULL);
query = "--sql\nSELECT id, name, email FROM users"
# rewritten: query = SQL[tuple[int, str, str]]("--sql\nSELECT id, name, email FROM users")
SQL[T] is a str subclass, so the query still runs anywhere a string does,
and mypy, pyright and ty see T. Without a schema, casts such as id::INTEGER
type the columns; a query with neither stays as it is. With a space instead of
the newline, "--sql SELECT ..." is a SQL comment, and sqlty check warns.
What it catches
A migration changes a column
[tool.sqlty]
schema = "schema.sql"
A migration dropped NOT NULL from email.
schema.sql:
CREATE TABLE users (id INTEGER PRIMARY KEY, email TEXT);
from sqlty import SQL

# error: [narrow-type] "SQL[tuple[int, str]] should be SQL[tuple[int, str | None]]"
query = SQL[tuple[int, str]]("--sql\nSELECT id, email FROM users")
sqlty check --fix . updates the type, and your type checker finds every
caller that now needs a None check. narrow-type is an error, so CI fails on
it; an annotation that is only wider than the rows, such as str | None for a
column made NOT NULL, is a stale-type warning
(CI). For rolling deploys,
sqlty breaking --against origin/main exits 1 when old code breaks on the new
schema or new code on the old one
(Breaking schema changes).
A row type that doesn't match its query
from typing import TypedDict
from sqlty import SQL

class User(TypedDict):
    id: str
    name: str

# error: [column-type-mismatch] "User.id is str but query column 'id' infers int"
query = SQL[User]("--sql\nSELECT id::INTEGER, name::TEXT FROM users")
TypedDict, NamedTuple, dataclasses and Pydantic models are all checked
(Row types).
Wrong parameters, misspelled columns
[tool.sqlty]
dialect = "sqlite"
schema = "schema.sql"

[tool.sqlty.rules]
unknown-column = "warn"
schema.sql:
CREATE TABLE users (id INTEGER PRIMARY KEY, email TEXT);
import sqlite3
from sqlty import SQL

conn = sqlite3.connect("app.db")

# error: [param-count-mismatch] "query has 1 parameter, the call passes 2"
conn.execute(SQL[tuple[str | None]]("--sql\nSELECT email FROM users WHERE id = ?"), (1, 2))

# error: [unknown-column] "column `emial` does not exist in `users`"
conn.execute("--sql\nSELECT emial FROM users")
?, $1, %s and :name placeholders are checked on sqlite3, aiosqlite,
psycopg and asyncpg calls (Parameters).
These are the mistakes coding agents make: every problem is one
file:line: [rule] message line and a non-zero exit code they can act on, and
the sqlty skills teach
them the conventions. In Claude Code, /plugin install sqlty --marketplace jirikuncar/sqlty
installs them.
Get started
pip install "sqlty[psycopg]"   # or: uv add sqlty; the extra adds the psycopg helpers
printf '%s\n' 'q = "--sql\nSELECT id::INTEGER, name::TEXT FROM users"' > queries.py
sqlty rewrite -v .             # q = SQL[tuple[int, str]]("--sql\n...")
sqlty check .                  # report drift and mismatches
sqlty strip .                  # undo: back to plain strings
rewrite and strip only touch the wrapper, never the SQL, so you can adopt
sqlty one module at a time and back out. New project:
Quickstart. Existing codebase:
Migration, starting
with pg_dump --schema-only app > schema.sql. In the editor:
VS Code.
Not a fit for ORMs, SQL built at runtime, or runtime validation; Why SQLTy? compares it with sqlc, sqlx, PgTyped and others.
About
The engine is Rust (sqlparser-rs via PyO3), with wheels for Linux, macOS and Windows. SQLTy is developed with AI coding agents, mainly Claude Code; every change is reviewed by a maintainer (see the AI-assisted contributions policy). Contributing · Credits · MIT License.