
jingjingqian75/GeoPredict
jingjingqian75/GeoPredict has 35 GitHub stars and 5 forks. GitHot measured +1 stars in 24 hours and +3 in 7 days. Last checked 2026-11-09 09:11 UTC. Last push 2026-10-14.
[CVPR2026] GeoPredict: Leveraging Predictive Kinematics and 3D Gaussian Geometry for Precise VLA Manipulation
Measured star growth
- in 24h
- +1
- in 7 days
- +3
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original
GeoPredict: Leveraging Predictive Kinematics
and 3D Gaussian Geometry
for Precise VLA Manipulation
🔥 CVPR 2026  🔥
Jingjing Qian1
Boyao Han2
Chen Shi1
Lei Xiao1
Long Yang1
Shaoshuai Shi3
Li Jiang1
1Chinese University of Hong Kong, Shenzhen
2Hunan University
3Voyager Research, Didi Chuxing


🔥 News
- [2026-07] We released the training code and dataset for GeoPredict.
- [2026-05] We released the inference code and checkpoints for GeoPredict.
- [2026-02] Our paper was accepted by CVPR2026 as a Highlight ! 🥳
- [2025-12] We released the paper and the project page for GeoPredict.
🎄 Overview
GeoPredict is a geometry-aware vision-language-action (VLA) framework for robotic manipulation. Existing methods are often limited by:
- 2D-Centric Formulation: operate in 2D image space, lacking explicit 3D spatial modeling.
- Reactive Control: map observations reactively, failing to anticipate future physical dynamics.
- Geometric Inconsistency: view-independent predictions struggle to enforce 3D consistency.
GeoPredict addresses these limitations with:
- Geometry-Aware VLA: augments VLA with predictive kinematic and 3D geometric priors.
- Predictive 3D Modeling: forecasts workspace geometry using track-guided 3DGS refinement.
- Lightweight Inference: uses predictive modules solely for training, reducing test-time overhead.
📝 TODO
- Release paper and project page.
- Release inference code and checkpoints.
- Release training code and dataset.
📚 Getting Started
The training dataset is available on ModelScope.
📖 Framework
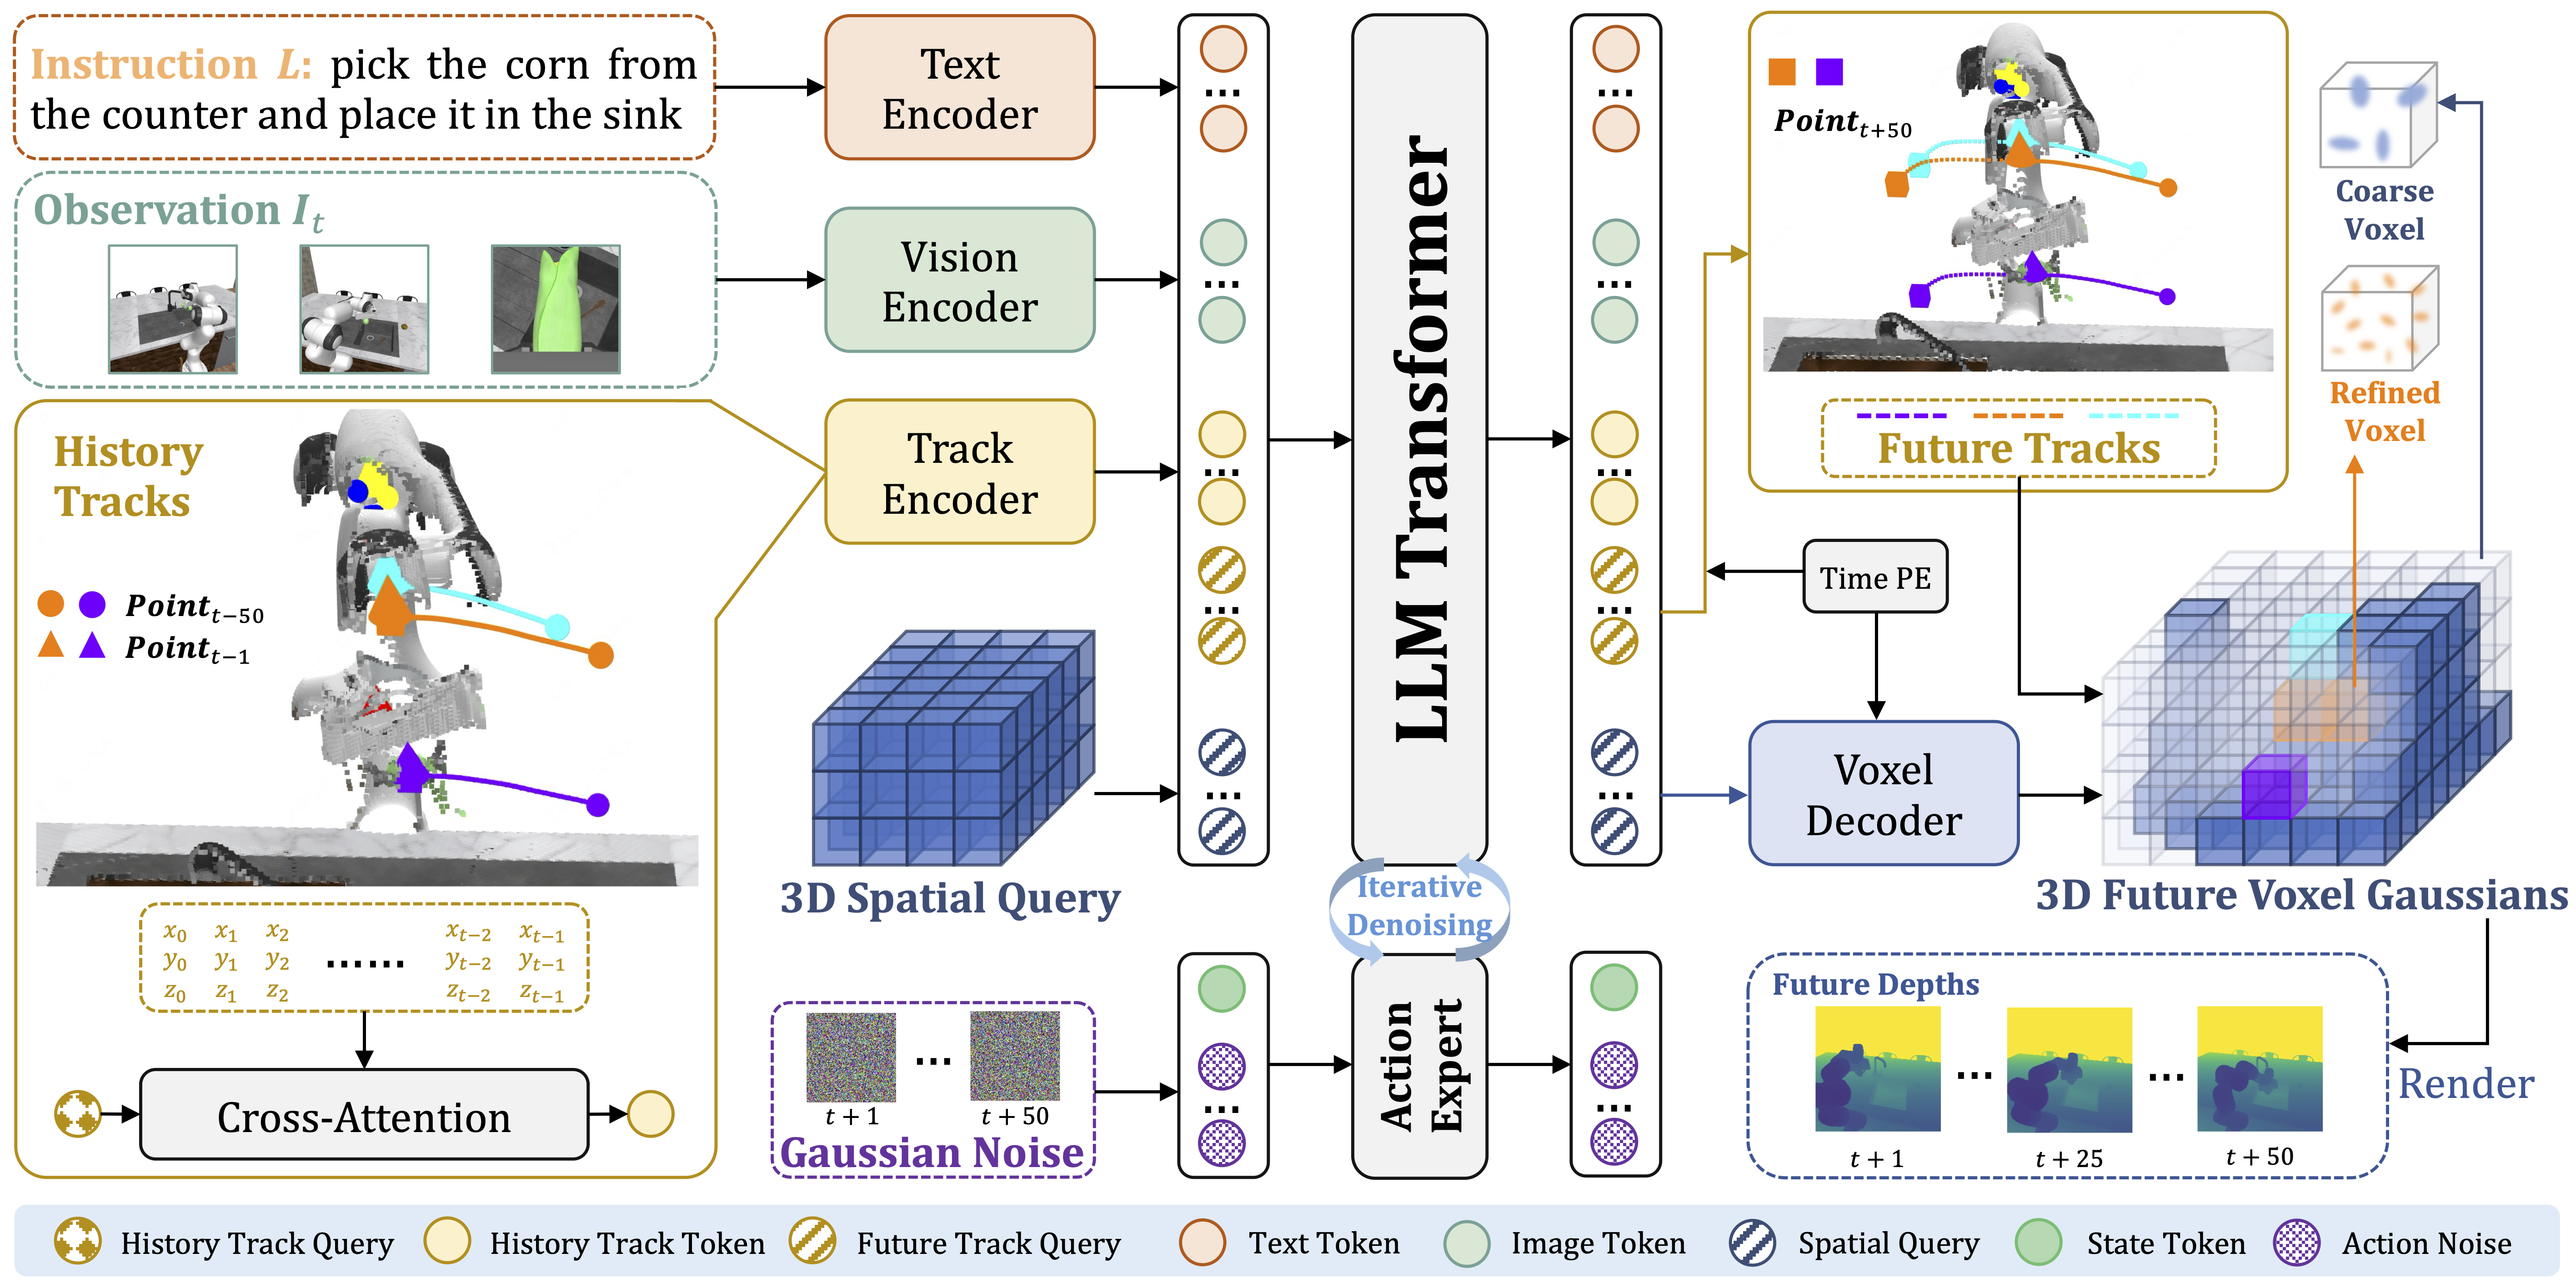
GeoPredict consists of three key components:
- (a) Trajectory-Level Kinematic Prediction: encodes motion history of robot keypoints into compact tokens via a Track Encoder, and predicts multi-step 3D keypoint trajectories using learnable future track queries.
- (b) Predictive 3D Gaussian Geometry: decodes a coarse 3D spatial query into initial Gaussian primitives to represent workspace geometry, and forecasts how the explicit 3D scene representation evolves across multiple future timesteps.
- (c) Track-Guided Refinement & Rendering: adaptively increases Gaussian density along predicted trajectories to capture task-relevant interaction regions, and supervises the predictive 3DGS exclusively through future depth-map rendering without color modeling.
📊 Results
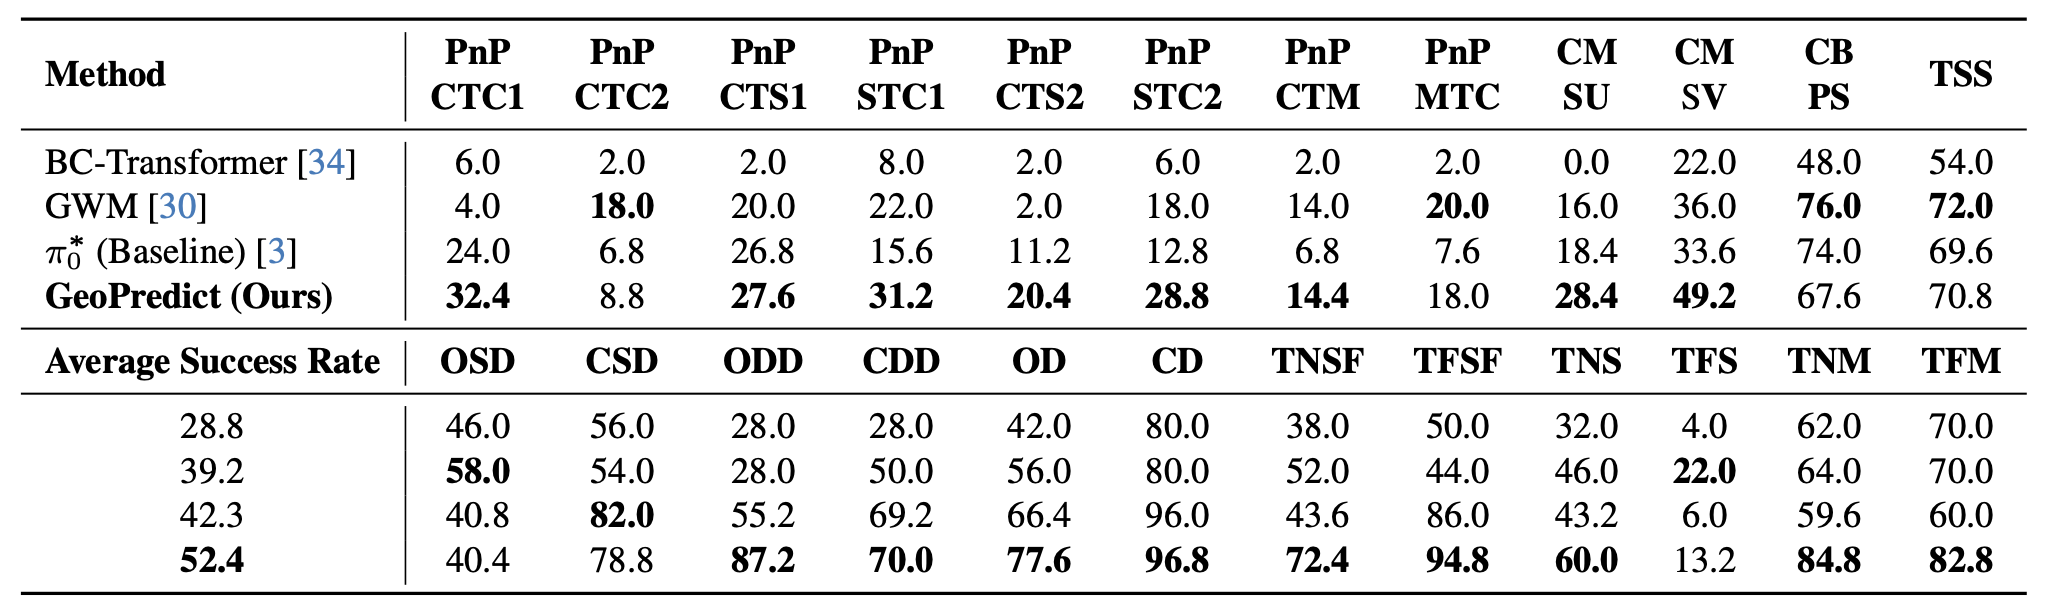
RoboCasa Simulation Benchmark Results
LIBERO Simulation Benchmark Results
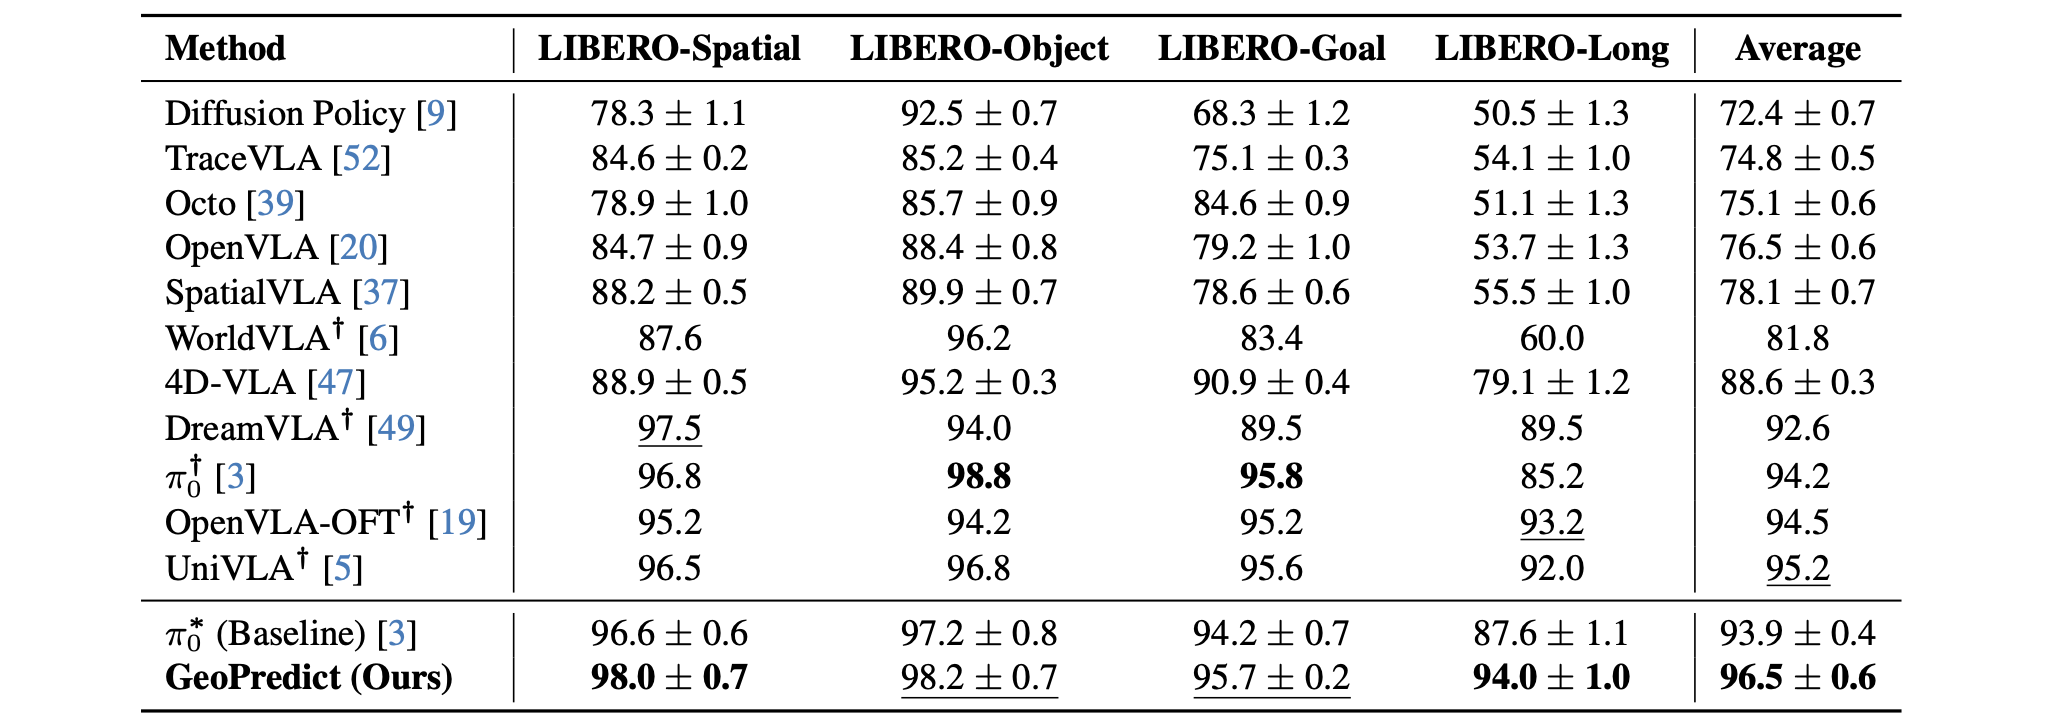
We report strong performance on both RoboCasa Human-50 and LIBERO benchmarks, demonstrating the effectiveness of GeoPredict in geometry-intensive and spatially demanding manipulation tasks. Please see the paper for full tables, metrics, and more detailed analysis.
📬 Contact
If you have questions about the paper, feel free to open an issue or contact:
- Jingjing Qian:
[email protected]
🔗 Citation
If you find our work helpful, please cite:
@misc{qian2025geopredict,
  title={GeoPredict: Leveraging Predictive Kinematics and 3D Gaussian Geometry for Precise VLA Manipulation},
  author={Jingjing Qian and Boyao Han and Chen Shi and Lei Xiao and Long Yang and Shaoshuai Shi and Li Jiang},
  year={2025},
  eprint={2512.16811},
  archivePrefix={arXiv},
  primaryClass={cs.CV},
  url={https://arxiv.org/abs/2512.16811},
}
Explore related projects
tensorflow/tensorflow
An Open Source Machine Learning Framework for Everyone
201,427 starshuggingface/transformers
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
168,711 starsAUTOMATIC1111/stable-diffusion-webui
Stable Diffusion web UI
165,274 starsComfy-Org/ComfyUI
The most powerful and modular diffusion model GUI, api and backend with a graph/nodes interface. The fastest local inference engine in the world.
146,024 stars