
jefferyZhan/Griffon
jefferyZhan/Griffon has 254 GitHub stars and 13 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-18 00:55 UTC. Last push 2026-04-17.
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Official repo of Griffon series including v1(ECCV 2024), v2(ICCV 2025), G, and R, and also the RL tool Vision-R1(CVPR 2026).
Developer ToolsREADME.md
Original
Welcome to Griffon
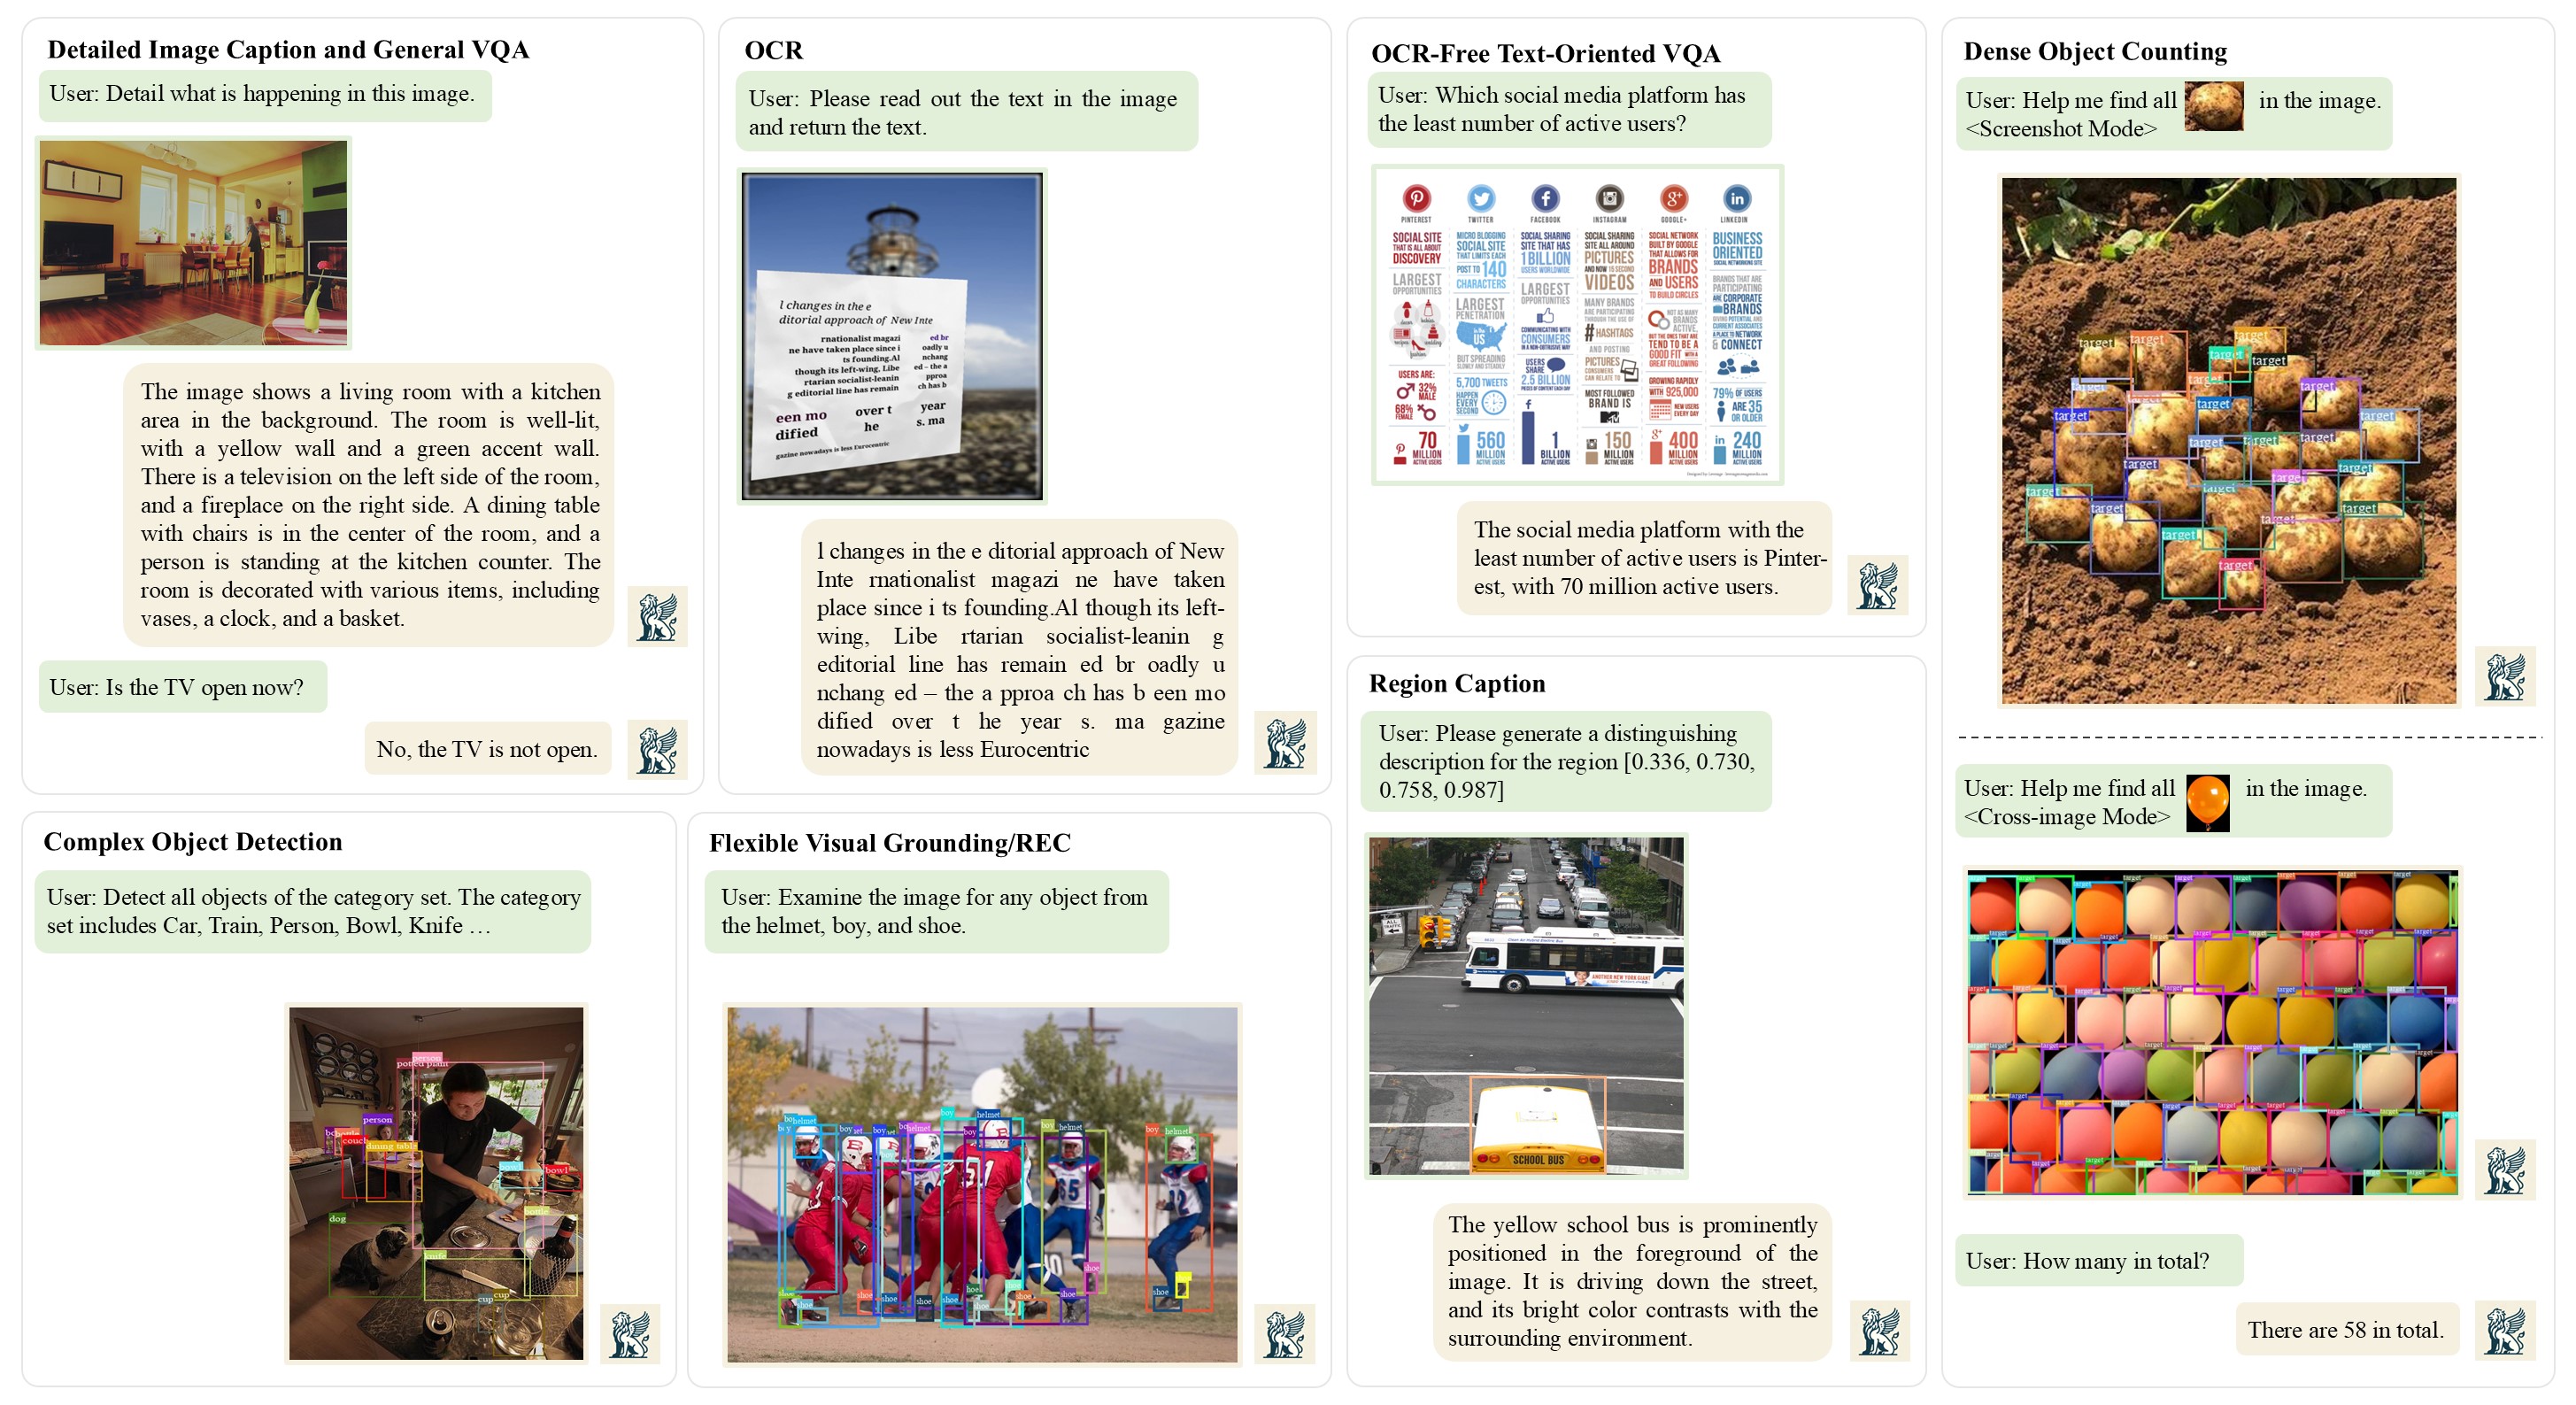
Welcome to the official repository of the Griffon Series — including Griffon v1, v2, G, R, and the Vision-R1 reinforcement learning framework. Griffon begins with fine-grained perception and localization, achieving state-of-the-art performance in visual grounding and referring expression comprehension (REC) — rivaling expert-level object detection models. Beyond its visual strengths, Griffon also demonstrates impressive general-purpose question answering and the ability to identify relevant regions based on a given question to perform reasoning. Griffon is continuously evolving to tackle increasingly complex vision-language tasks. We are actively maintaining and open-sourcing our progress. Feel free to follow the project and open an issue if you have questions or feedback!
Understand, Think, and Answer: Advancing Visual Reasoning with Large Multimodal Models
Vision-R1: Evolving Human-Free Alignment in Large Vision-Language Models via Vision-Guided Reinforcement Learning (CVPR 2026)
Griffon-G: Bridging Vision-Language and Vision-Centric Tasks via Large Multimodal Models
Griffon v2: Advancing Multimodal Perception with High-Resolution Scaling and Visual-Language Co-Referring (ICCV 2025)
Griffon: Spelling out All Object Locations at Any Granuality with Large Language Model (ECCV 2024)
Release
-
2026.04.17🔥🔥We are glad to annouce that Vision-R1 has been accepted to CVPR 2026. Also, we'd like to update to support Qwen3-VL training with EasyR1. -
2025.08.12🔥🔥We have released the data of Griffon v2 and Griffon-G in the 🤗HuggingFace and also updated the training codes. For any potential bugs or improvements, feel free to submit a pull request. -
2025.08.11We are glad to annouce that Griffon v2 has been accepted to ICCV 2025. -
2025.05.27We have released Griffon-R in the arxiv. -
2025.03.25We release the Vision-R1 paper, evaluation codes, models, and data. Check out in the repo. -
2025.01.15Release the evaluation scripts supporting distributed inference. -
2024.11.26We are glad to release inference code and the model of Griffon-G in🤗Griffon-G. Training codes will be released later. -
2024.07.01Griffon has been accepted to ECCV 2024. Data is released in🤗HuggingFace -
2024.03.11We are excited to announce the arrival of Griffon v2. Griffion v2 brings fine-grained perception performance to new heights with high-resolution expert-level detection and counting and supports visual-language co-referring. Take a look at our demo first. Paper is preprinted in📕Arxiv. -
2023.12.06Release the Griffon v1 inference code and model in🤗HuggingFace. -
2023.11.29Griffon v1 Paper has been released in📕Arxiv.
What can Griffon do now?
Griffon-G demonstrates advanced performance across multimodal benchmarks, general VQAs, and text-rich VQAs, achieving new state-of-the-art results in REC and object detection.
More quantitative evaluation results can be found in our paper.
Get Started with Griffon
💡 Looking for Vision-R1? If you are here for the RL training on Qwen3-VL/Qwen2.5-VL, please navigate to the Vision-R1 Directory after cloning this repository.
1.Clone & Install
git clone [email protected]:jefferyZhan/Griffon.git
cd Griffon
pip install -e .
Tips: If you encounter any errors while installing the packages, you can always download the corresponding source files (*.whl), which have been verified by us.
2.Download the Griffon and CLIP models to the checkpoints folder.
| Model | Links |
|---|---|
| Griffon-G-9B | 🤗HuggingFace |
| Griffon-G-27B | 🤗HuggingFace |
| clip-vit-large-path14 | 🤗HuggingFace |
| clip-vit-large-path14-336_to_1022 | 🤗HuggingFace |
3. Training
Please refer to the Training README.
4.Inference
# 4.1 Modify the instruction in the run_inference.sh.

# 4.2.1 DO NOT USE Visual Prompt
bash run_inference.sh [CUDA_ID] [CHECKPOINTS_PATH] [IMAGE_PATH]

# 4.2.2 USE Visual Prompt for COUNTING: Input both query image and prompt image splited with comma and specify <region> placeholder in the instruction
bash run_inference.sh [CUDA_ID] [CHECKPOINTS_PATH] [IMAGE_PATH,PROMPT_PATH]
Notice: Please pay attention to the singular and plural expressions of objects.
5.Evaluation
5.1 Multimodal Benchmark Evaluation
Please Refer to LLaVA Evaluation or Use VLMEvalKit.
5.2 COCO Detection Evaluation
# Single Node
torchrun --nproc_per_node 8 --nnodes 1 --node_rank 0 --master_addr 127.0.0.1 --master_port 12457 -m griffon.eval.eval_detection --model-path PATH/TO/MODEL --image-folder PATH/TO/coco2017/val2017 --dataset PATH/TO/instances_val2017.json

# Multiple Node
## NODE 0
torchrun --nproc_per_node 8 --nnodes N --node_rank 0 --master_addr MASTER_ADDR --master_port MASTER_PORT -m griffon.eval.eval_detection --model-path PATH/TO/MODEL --image-folder PATH/TO/coco2017/val2017 --dataset PATH/TO/instances_val2017.json --init tcp://MASTER_ADDR:MASTER_PORT
## NODE K(1 to N-1)
torchrun --nproc_per_node 8 --nnodes N --node_rank K --master_addr MASTER_ADDR --master_port MASTER_PORT -m griffon.eval.eval_detection --model-path PATH/TO/MODEL --image-folder PATH/TO/coco2017/val2017 --dataset PATH/TO/instances_val2017.json --init tcp://MASTER_ADDR:MASTER_PORT
5.3 REC Evaluation
Processed RefCOCO annotation set can be downloaded from this link.
# Single Node
torchrun --nproc_per_node 8 --nnodes 1 --node_rank 0 --master_addr 127.0.0.1 --master_port 12457 -m griffon.eval.eval_rec --model-path PATH/TO/MODEL --image-folder PATH/TO/COCO/train2014 --dataset PATH/TO/REF_COCO_ANN

# Multiple Node
## NODE 0
torchrun --nproc_per_node 8 --nnodes N --node_rank 0 --master_addr MASTER_ADDR --master_port MASTER_PORT -m griffon.eval.eval_detection --model-path PATH/TO/MODEL --image-folder PATH/TO/COCO/train2014 --dataset PATH/TO/REF_COCO_ANN --init tcp://MASTER_ADDR:MASTER_PORT
## NODE K(1 to N-1)
torchrun --nproc_per_node 8 --nnodes N --node_rank K --master_addr MASTER_ADDR --master_port MASTER_PORT -m griffon.eval.eval_detection --model-path PATH/TO/MODEL --image-folder PATH/TO/COCO/train2014 --dataset PATH/TO/REF_COCO_ANN --init tcp://MASTER_ADDR:MASTER_PORT
Acknowledgement
- LLaVA provides the base codes and pre-trained models.
- Shikra provides insight of how to organize datasets and some base processed annotations.
- Llama provides the large language model.
- Gemma2 provides the large language model.
- volgachen provides the basic environment setting config.
Citation
If you find Griffon useful for your research and applications, please cite using this BibTeX:
@inproceedings{zhan2025griffonv1,
  title={Griffon: Spelling out all object locations at any granularity with large language models},
  author={Zhan, Yufei and Zhu, Yousong and Chen, Zhiyang and Yang, Fan and Tang, Ming and Wang, Jinqiao},
  booktitle={European Conference on Computer Vision},
  pages={405--422},
  year={2025},
  organization={Springer}
}

@inproceedings{zhan2025griffon,
  title={Griffon v2: Advancing multimodal perception with high-resolution scaling and visual-language co-referring},
  author={Zhan, Yufei and Zheng, Shurong and Zhu, Yousong and Zhao, Hongyin and Yang, Fan and Tang, Ming and Wang, Jinqiao},
  booktitle={Proceedings of the IEEE/CVF International Conference on Computer Vision},
  pages={22947--22957},
  year={2025}
}

@article{zhan2024griffon-G,
  title={Griffon-G: Bridging Vision-Language and Vision-Centric Tasks via Large Multimodal Models},
  author={Zhan, Yufei and Zhao, Hongyin and Zhu, Yousong and Yang, Fan and Tang, Ming and Wang, Jinqiao},
  journal={arXiv preprint arXiv:2410.16163},
  year={2024}
}

@article{zhan2025understand,
  title={Understand, Think, and Answer: Advancing Visual Reasoning with Large Multimodal Models},
  author={Zhan, Yufei and Zhao, Hongyin and Zhu, Yousong and Zheng, Shurong and Yang, Fan and Tang, Ming and Wang, Jinqiao},
  journal={arXiv preprint arXiv:2505.20753},
  year={2025}
}

@misc{zhan2025visionr1evolvinghumanfreealignment,
      title={Vision-R1: Evolving Human-Free Alignment in Large Vision-Language Models via Vision-Guided Reinforcement Learning},
      author={Yufei Zhan and Yousong Zhu and Shurong Zheng and Hongyin Zhao and Fan Yang and Ming Tang and Jinqiao Wang},
      year={2025},
      eprint={2503.18013},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2503.18013},
}
License


The data and checkpoint is licensed for research use only. All of them are also restricted to uses that follow the license agreement of LLaVA, LLaMA, Gemma2, and GPT-4. The dataset is CC BY NC 4.0 (allowing only non-commercial use) and models trained using the dataset should not be used outside of research purposes.