
jaedync/crucible-strix-halo
jaedync/crucible-strix-halo has 32 GitHub stars and 6 forks. GitHot measured +5 stars in 24 hours. Last checked 2026-11-15 19:50 UTC. Last push 2026-11-12.
What you can do
- Its own ROCm/HIP kernels in C++20.
- Speculative decoding that is exact: the model checks every draft token, so only the speed changes.
- A conversation cache in memory and on the SSD. A later turn pays only for its new tokens, also after a restart.
- An OpenAI-compatible API with streaming, tool calls and image input, up to 8 sessions.
Measured star growth
- in 24h
- +5
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Run Qwen3.8-Flash-Next on one AMD Strix Halo (Ryzen AI Max+ 395, gfx1151). EXL3 4.05 and 3.05 bpw packs, own ROCm/HIP kernels, OpenAI-compatible server, 4 sessions of 262K context, setup guide included.
Developer ToolsREADME.md
OriginalCrucible
An inference engine for one model on one machine: Qwen3.8-Flash-Next (EXL3) on AMD Strix Halo, a Ryzen AI Max+ 395 with 128 GB. Its OpenAI-compatible server gives local coding agents 4 sessions of 262,144 tokens.
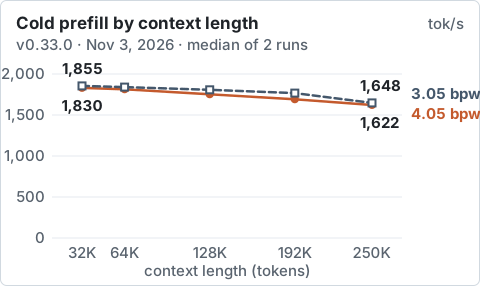
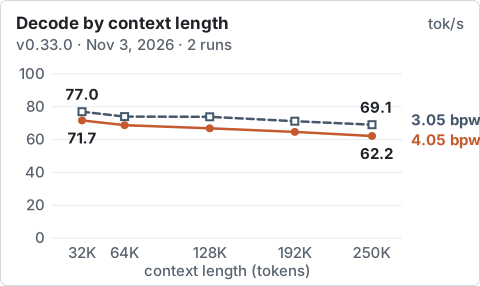
One request at a time, default configuration, balanced power profile, v0.33.0 (Nov 3, 2026). No new run for v0.37.0.
Install
One command. It downloads the release engine (about 25 MB) and checks its sha256.
curl -fsSL https://raw.githubusercontent.com/jaedync/crucible-strix-halo/main/install.sh | bash
Build from source. It takes about 16 minutes and needs the ROCm 7.2.4 compiler (why).
git clone --branch v0.37.0 https://github.com/jaedync/crucible-strix-halo.git
cd crucible-strix-halo
./crucible setup
Setup checks the machine, downloads the model (about 107 GB), starts the server and sends a test request. Then send your own:
curl -sS http://127.0.0.1:8790/v1/chat/completions -H 'Content-Type: application/json' \
  -d '{"model":"crucible","messages":[{"role":"user","content":"Say hello."}]}'
Read more: setup guide · service · Docker · clients · updates
What you need
- Machine: Ryzen AI Max+ 395 with Radeon 8060S (gfx1151) and 128 GB of memory. Other machines are not supported.
- System: Linux with Python 3.12 or newer. The tested system is Arch Linux.
- ROCm: the release engine runs on ROCm 10.1 (recommended) and on 7.2.4. A source build needs the 7.2.4 compiler.
- GPU memory: two kernel parameters let the GPU use the system memory. Setup prints the change and applies it
only after you type
yes. - Disk: an SSD with about 110 GB for the model, and up to 200 GiB for the conversation cache.
Read more: step 1 and step 2 of the setup guide
Configurations
Setup installs the pack 4.05bpw_h6_ng6.
With --pack 3.05 it installs 3.05bpw_h5_ng5,
the faster pack with the lower quality. ./crucible setup --layout NAME sets the sessions:
default: 4 sessions of 262,144 tokens.long: 1 session of 524,288 tokens and 2 of 262,144.two-long: 2 sessions of 524,288 tokens.
Each one needs about 28 GB of GPU memory for the sessions. A request that fits in 262,144 tokens gets the same tokens in
all three. A longer request uses YaRN. Measured in long:
long, 4.05 pack |
250,000 tokens | 490,000 tokens (YaRN) |
|---|---|---|
| Cold prompt: first token | 149.0 s | 340.4 s |
| Cold prompt: prefill | 1,677.6 tok/s | 1,436.2 tok/s |
| Decode, code | 67.7 tok/s | 59.8 tok/s |
v0.37.0, measured Nov 11, 2026: 1 run, balanced power profile.
Read more: long context
Speed by release
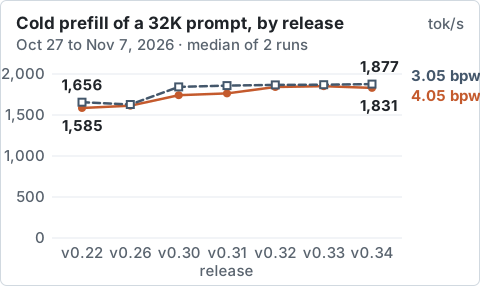
Each release ran with the settings of its own time, balanced power profile. No new run for v0.37.0.
| v0.34.0 | 4.05 pack | 3.05 pack |
|---|---|---|
| Cold 32K prompt: first token | 17.1 s | 16.6 s |
| Cold 130K prompt: first token | 72.4 s | 71.1 s |
| Same 32K prompt again: first token | 0.019 s | 0.015 s |
| Decode at 32K, 1 session, code | 71.2 tok/s | 76.8 tok/s |
| Decode at 32K, 1 session, prose | 58.4 tok/s | 60.7 tok/s |
| Decode, 4 sessions, total | 118.3 tok/s | 129.0 tok/s |
v0.34.0, measured Nov 7, 2026: median of 2 runs, balanced power profile, default configuration. No new run for v0.37.0.
Read more: results and method · history · Halogen and Gufo on the same machine · how it got fast
Features
- Its own ROCm/HIP kernels in C++20.
- Speculative decoding that is exact: the model checks every draft token, so only the speed changes.
- A conversation cache in memory and on the SSD. A later turn pays only for its new tokens, also after a restart.
- An OpenAI-compatible API with streaming, tool calls and image input, up to 8 sessions.
- One tool,
./crucible, for setup, checks, the service, updates with rollback, and removal. - Kiln, a dashboard and OpenAI-compatible gateway for Crucible.
Read more
- Architecture, server guide and all documents.
- Changelog: the changes and the known limits of each release.
- Security and remote access. The server listens on
127.0.0.1with no key and no TLS. A key is required for an address that is not loopback, except in the Docker image. - Updates: once in 24 hours the server asks GitHub if a newer release exists.
--no-update-checkturns this off.
This is research software for one GPU architecture. It is not a production service.
Licenses
The engine uses Apache-2.0 (LICENSE, NOTICE). The model weights use other terms: the Qwen Community License 1.0, with more conditions for commercial use. Read the model license note before you download a pack. This repository does not include the weights.