
haodehaode378/ai-paper-coach
haodehaode378/ai-paper-coach has 43 GitHub stars and 3 forks. GitHot measured 0 in 7 days. Last checked 2026-11-11 07:09 UTC. Last push 2026-07-29.
面向学生和研究者的 AI 论文教练:自动生成结构化解读、复现 指导、七问回答与可追踪历史记录。
What you can do
- End-to-end pipeline: ingest -> analyze -> review -> finalize -> report
- Structured 7-question reading framework
- RAG Q&A: retrieval-augmented generation over paper text, with cross-lingual query support
- AI chat quick prompts: built-in dropdown with common paper questions for one-click insertion
Measured star growth
- in 24h
- Update delayed
- in 7 days
- 0
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalAI Paper Coach
读论文更快,理解更深,复现更稳。



GitHub About(建议配置)
可直接复制到仓库 About
Description(中文)
面向学生和研究者的 AI 论文阅读与复现助手:结构化分析、复现指导、七问洞察、全流程可追踪。
Description (English)
An AI paper coach for students and researchers: structured paper analysis, reproducibility guidance, 7-question insights, and traceable history.
Suggested Topicsai paper-reading research-assistant llm fastapi vue3 pdf reproducibility arxiv education
Repo Pitch
- 一条流完成:
导入 -> 分析 -> 审阅 -> 整理 -> 报告 - 双模型协作 + 七问框架 + 可回放 trace/API 诊断
- 适合课堂汇报、组会复述与复现实验落地
简体中文
项目简介
AI Paper Coach 是一个面向学生和研究者的论文阅读与复现助手。
输入 arXiv/PDF 链接或直接上传 PDF,就能自动生成结构化报告,并支持后续问答与历史追踪。
30 秒价值说明
- 解决什么问题:把论文阅读中分散的「摘要理解、创新判断、复现落地」整合成一条可执行流程。
- 核心能力:结构化分析 + 七问框架 + 复现指导,并保留 trace 方便回溯诊断。
- 适用人群:课程汇报场景下的学生、做文献调研和实验复现的研究者。
为什么值得用
- 一条流完成:
导入 -> 分析 -> 审阅 -> 整理 -> 报告 - 七问结构化输出:更适合课堂汇报、组会复述、复现实验
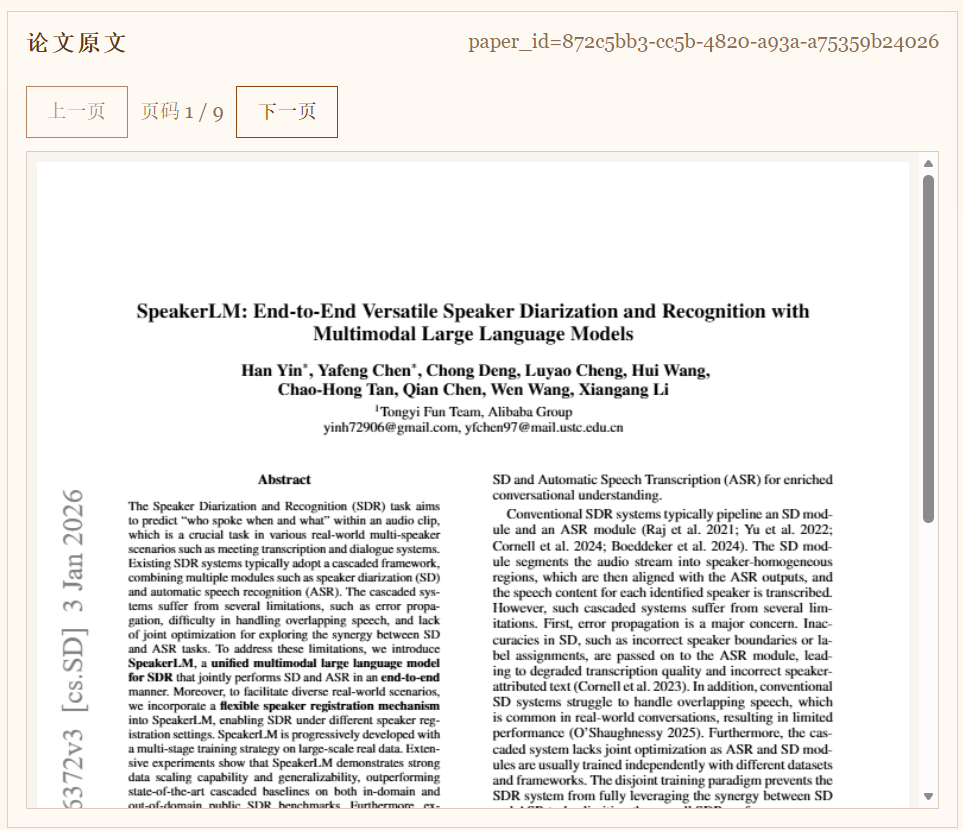
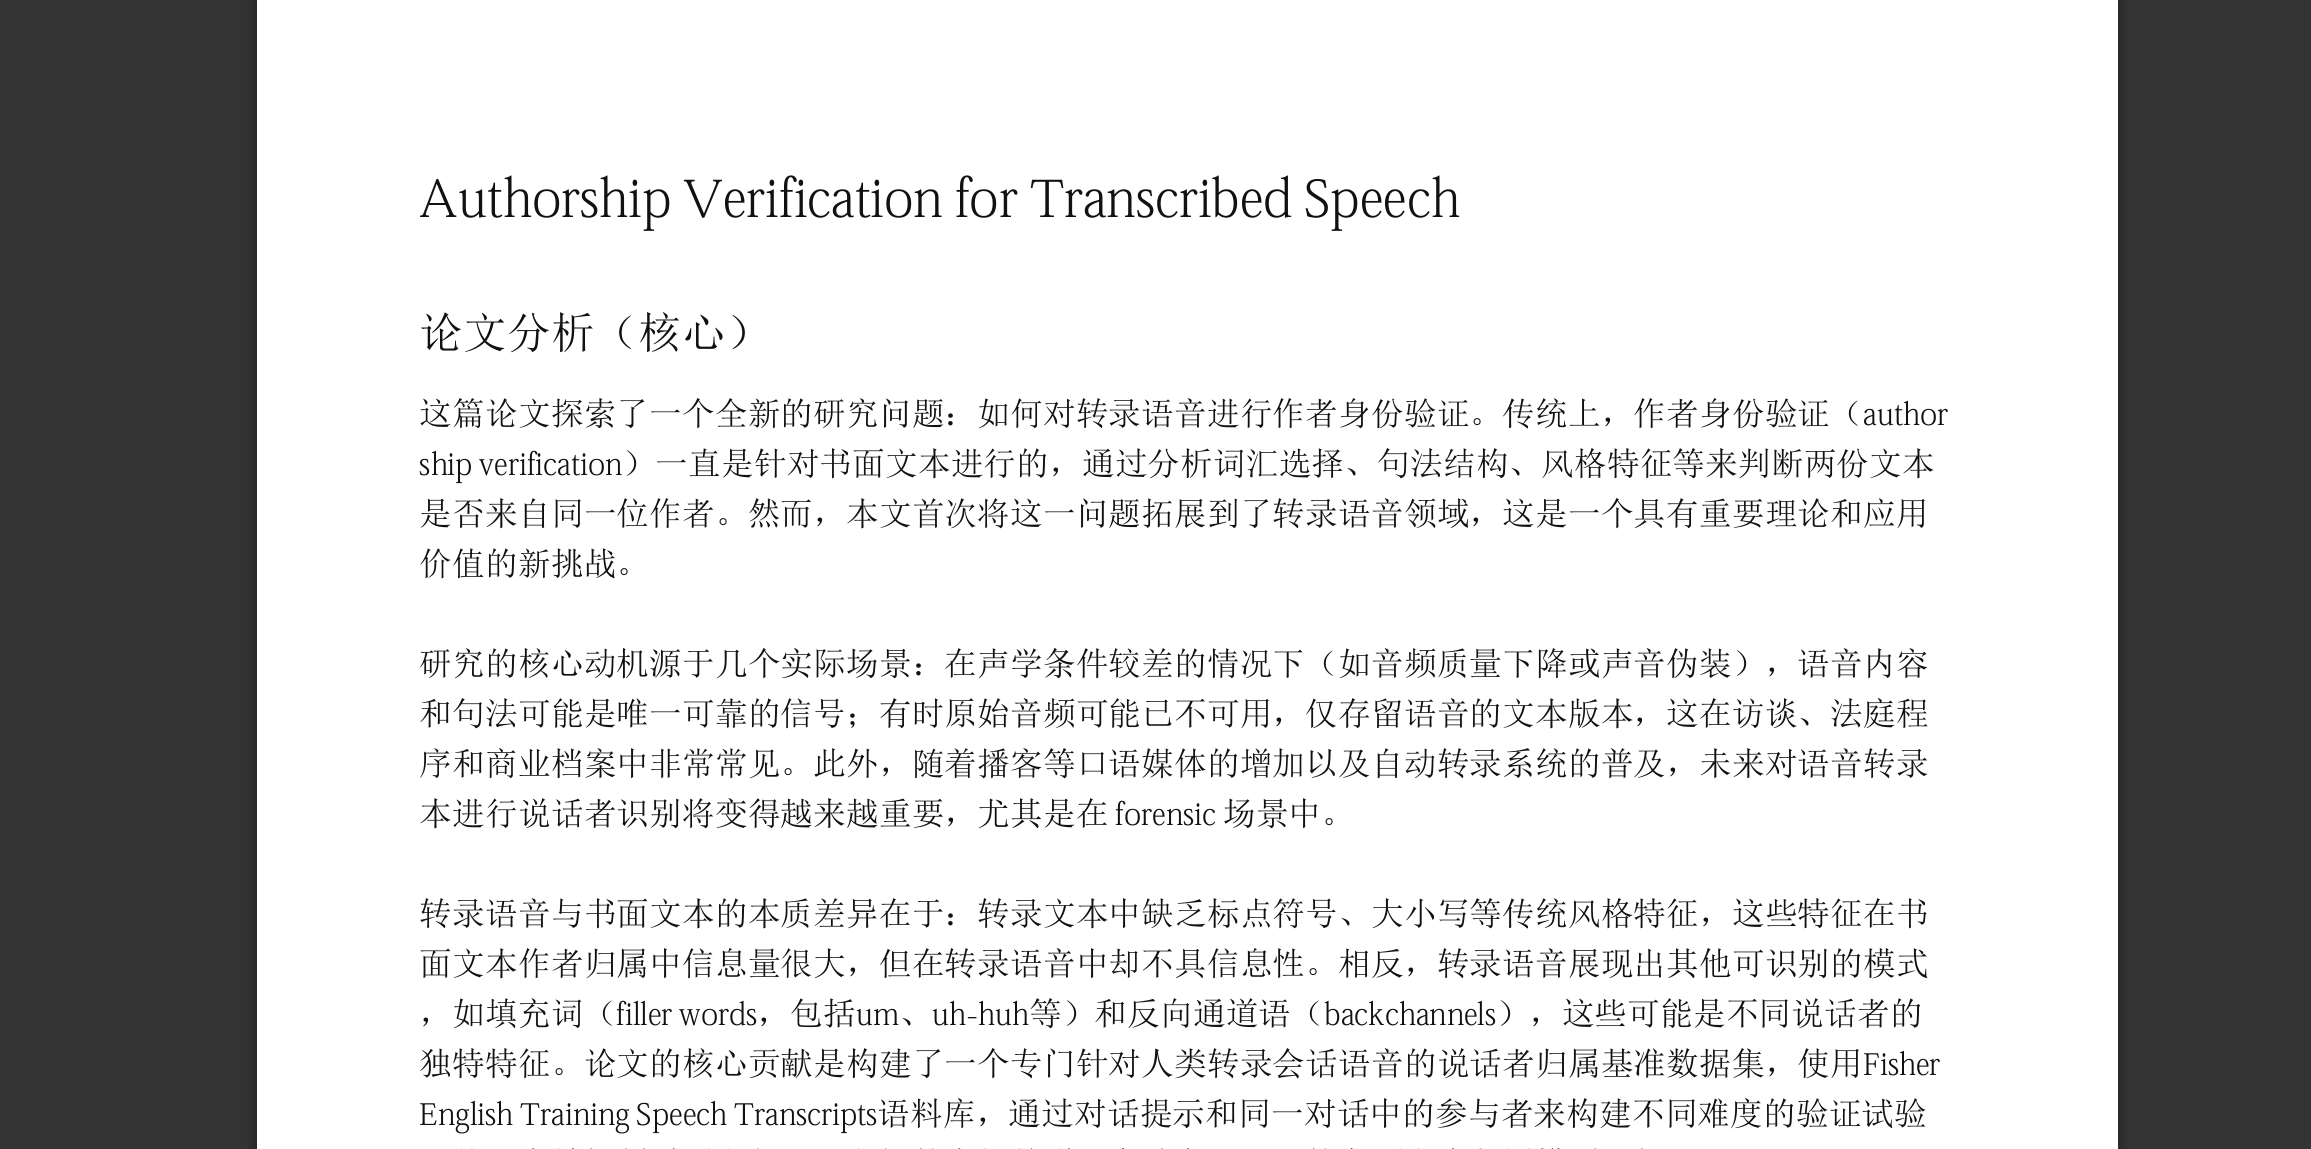
- 原文阅读联动:报告和 PDF 原文可对照查看
- RAG 问答:基于论文原文的检索增强问答,支持跨语言查询(中文问英文论文)
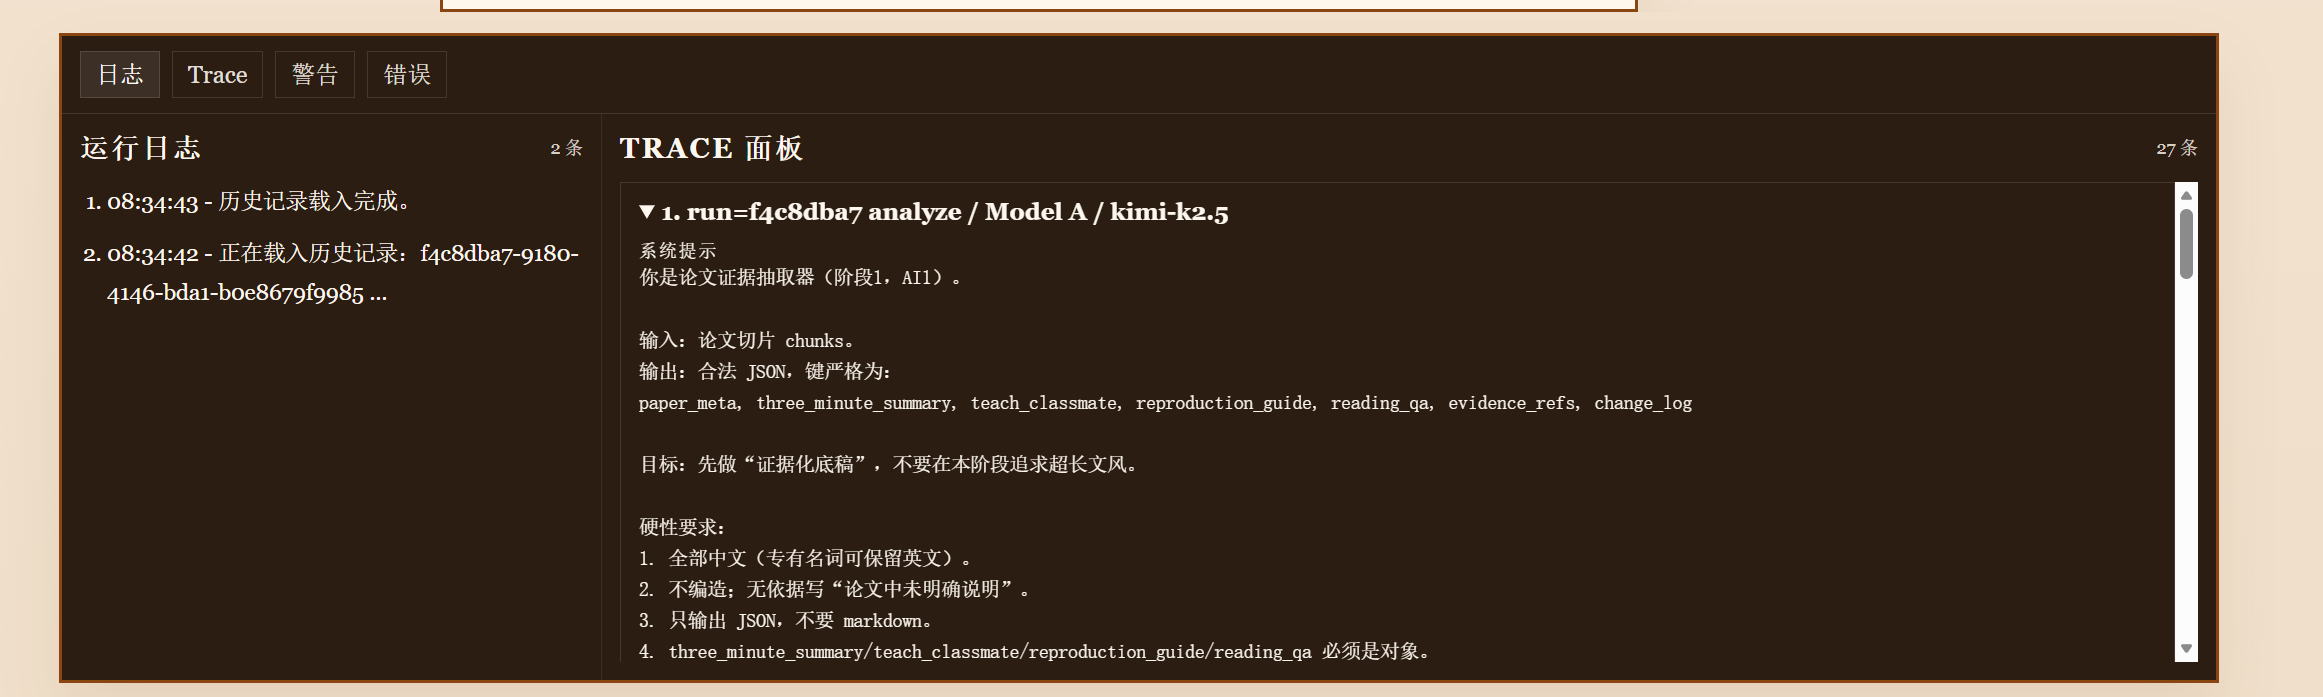
- 可追踪可回放:保留 trace、历史记录、已保存报告
- 支持删除管理:历史记录和已保存报告都可删除
- API 连通性验证:一键检查后端是否可达
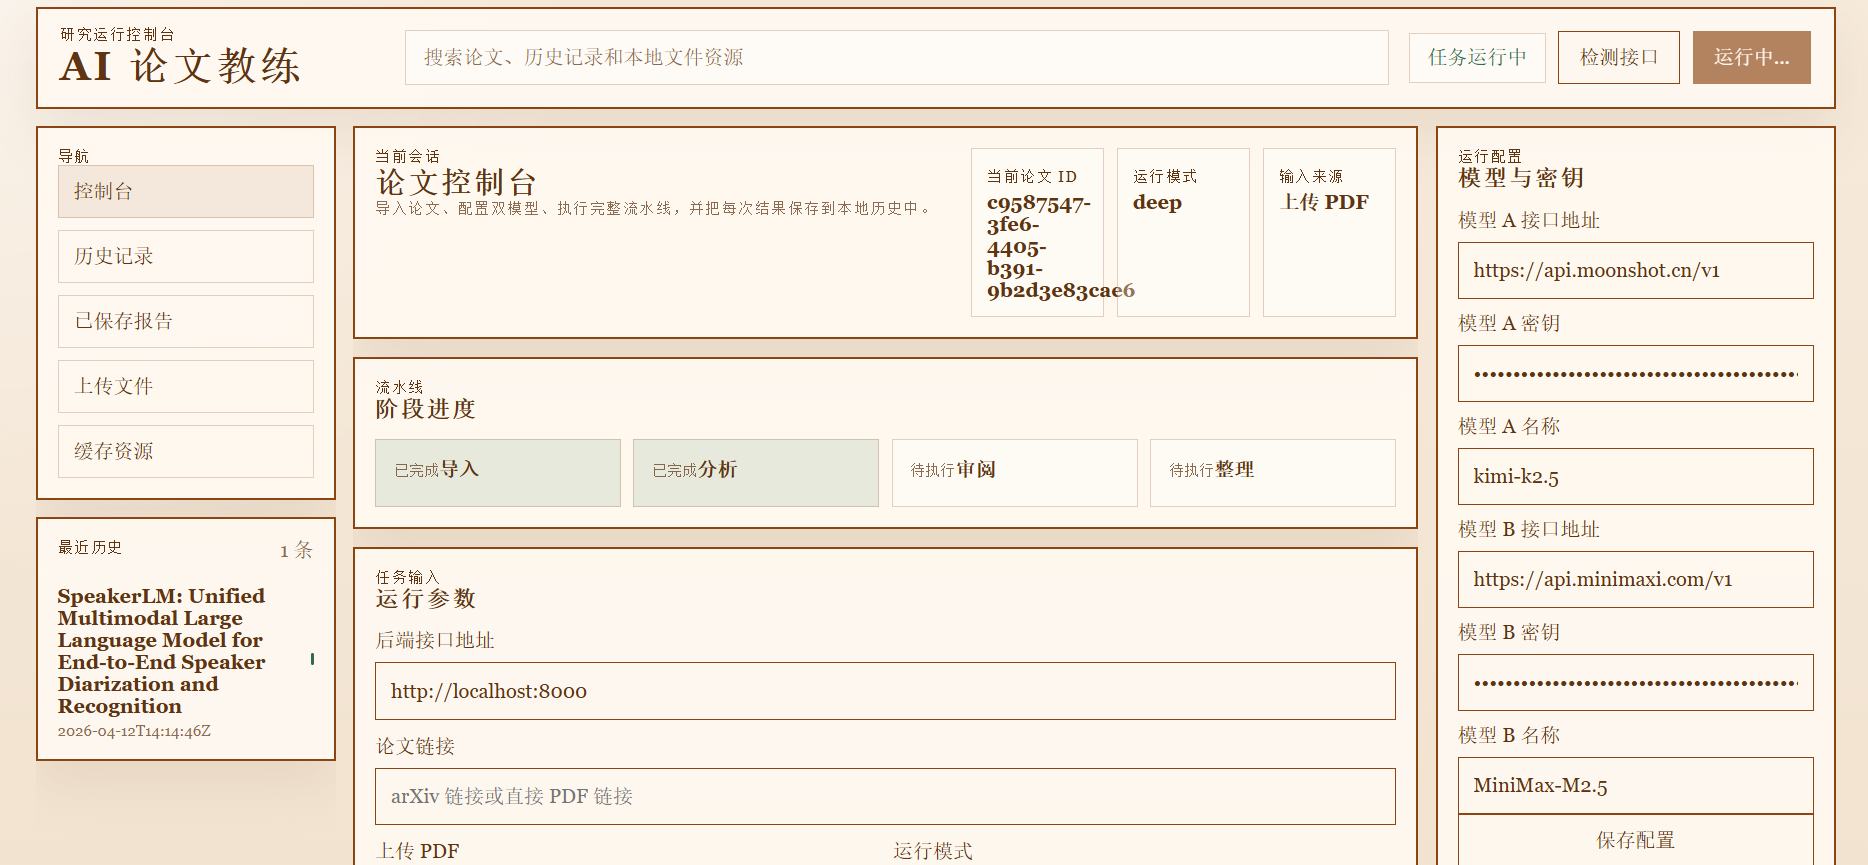
最新界面截图
整体界面
论文原文阅读区
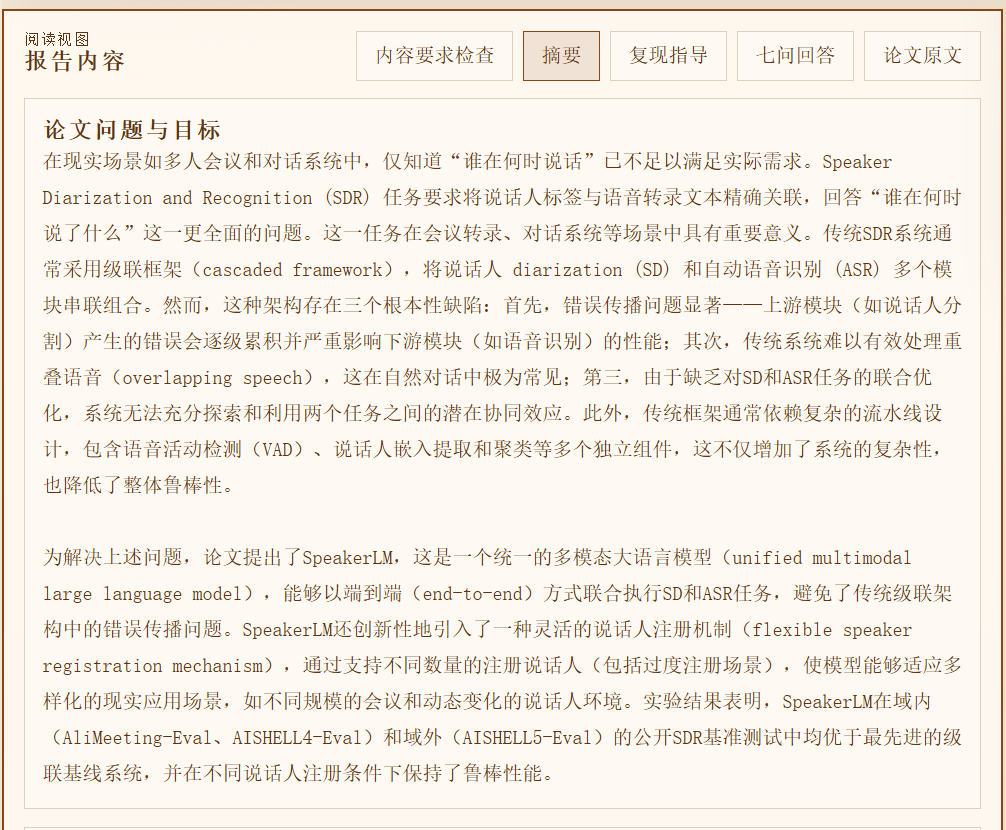
摘要面板
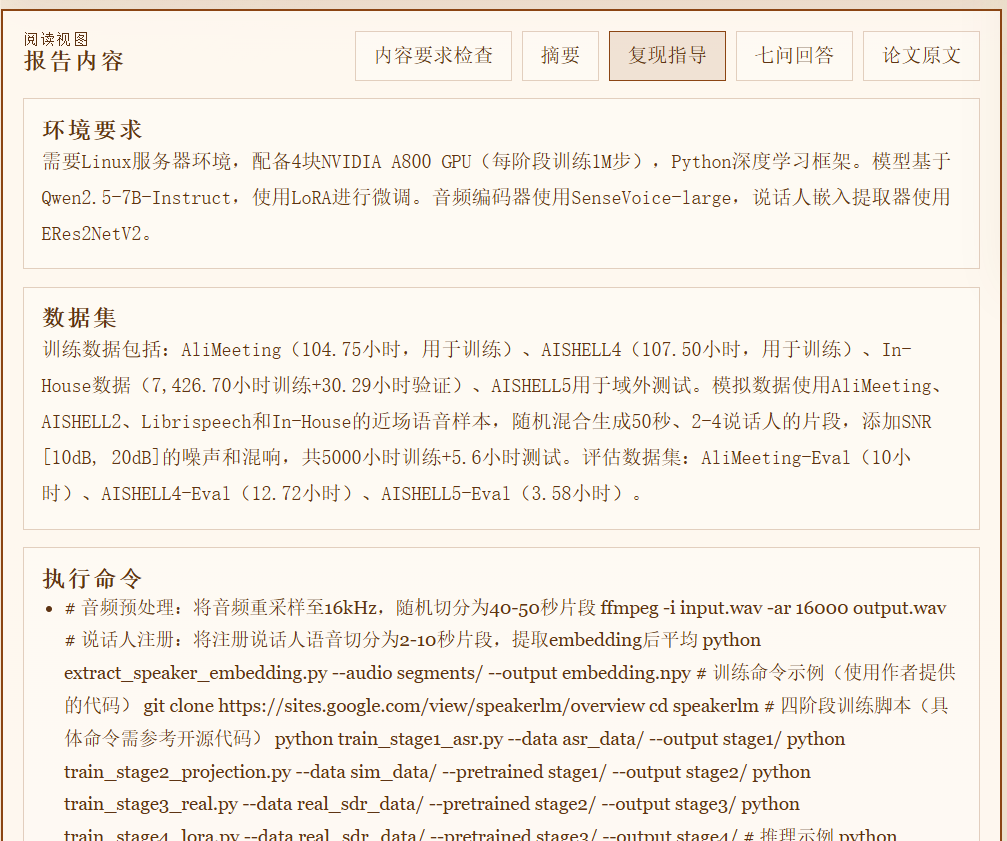
复现指导
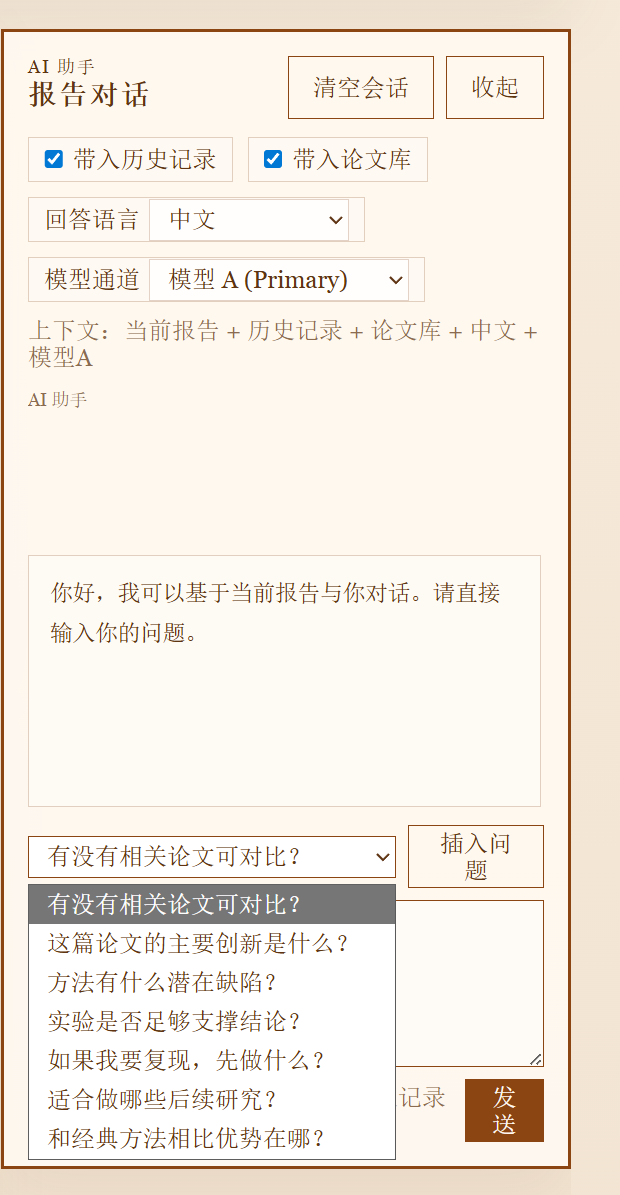
AI 对话(常用提问)
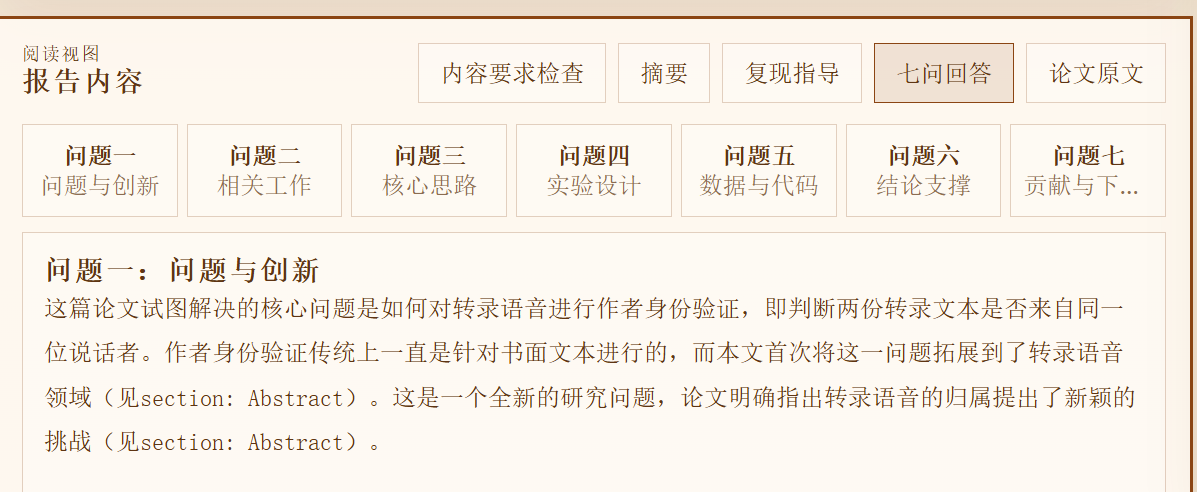
七问切换
Trace 面板
导出 PDF
七问框架(完整)
- 论文试图解决什么问题?这是否是一个新的问题?
- 有哪些相关研究?如何归类?谁是这一课题在领域内值得关注的研究者(公司)?
- 论文中提到的解决方案之关键是什么?
- 论文中的实验是如何设计的?
- 用于定量评估的数据集是什么?代码有没有开源?
- 文中的实验及结果有没有很好地支持需要验证的科学假设/提出方案?
- 这篇论文到底有什么贡献?下一步呢?有什么工作可以继续深入?
核心功能
- 论文导入:URL / 本地 PDF
- 双模型协作:支持模型校验与配置保存
- 七问阅读框架:横向切换,间距紧凑
- RAG 问答:基于论文原文的检索增强生成,支持跨语言查询、引用溯源
- 结果管理:历史记录、已保存报告、删除功能
- AI 对话工具:内置常用提问下拉,可一键插入论文高频问题模板
- 导出能力:Markdown / PDF 报告导出
- 诊断信息:运行日志 + trace 记录
内容要求阈值(当前)
- 摘要(论文问题与目标):
>= 800字 - 复现指导(整体):
>= 1000字 - 七问长答:每题
>= 700字
常见问题(FAQ)
Q1:模型 key 放哪里?
A:放在项目根目录 .env,并按 .env.example 填写。生产环境建议用系统环境变量注入,不直接写入仓库文件。
Q2:为什么 finalize 阶段有时比较慢?
A:finalize 会进行结构整理、长度校验、必要时触发 repair 和重试。现在已经在 trace 中增加模型调用耗时、repair 触发标记和重试次数,便于定位慢点。
Q3:为什么标题显示“论文中未明确说明”?
A:当 PDF/元数据解析失败或命中占位文本时会回退到该占位。当前版本已补 arXiv API 标题补全和占位识别逻辑,建议对同一论文重新执行完整流程。
Q4:复现指导为空怎么处理?
A:当前版本已增加兜底合并逻辑。若仍为空,按「ingest -> analyze -> review -> finalize」重新跑一次,trace 会显示是否触发 repair 与重试。
Q5:PDF 导出里出现乱码或方块怎么办?
A:当前版本已在 PDF 导出前做字符规范化(清理异常替代字符并过滤字体不支持的符号),并将列表符号改为兼容性更高的格式。若历史报告仍异常,请重新导出最新报告。
版本与路线图
v0.1(已完成)- 完整主流程:
ingest -> analyze -> review -> finalize -> report - 七问结构化输出与阈值校验
- 历史记录/保存报告管理(含删除)
- finalize 可观测性(耗时、repair、重试)与 trace 回放
- 标题提取增强(含 arXiv API 兜底)和复现指导空内容修复
- 完整主流程:
v0.2(进行中)- RAG 检索增强问答,支持跨语言查询
- Pipeline 服务化(async 架构,analyze.py 从 634 行瘦身到 170 行)
- ModelRouter 异步方法(httpx 非阻塞 HTTP)
- 全局异常处理加固,不再向客户端泄漏内部异常
- SQLite 连接池、PDF 按页提取、LangSmith 追踪集成
v0.3(计划中)- 失败可恢复执行(按阶段断点续跑)
- 更细粒度质量评分和告警
- 前端组件化拆分(ResultsView 解耦)
- RAG 语义检索(向量数据库集成)
Release Note:见 docs/releases/v0.1.2.md
安全声明
- API Key 不会提交到仓库:
.env、.env.*、*.env.local已在.gitignore中忽略。 - 支持
gitleaks历史扫描;当前仓库历史扫描结果为0命中(无疑似密钥泄露)。 - CORS 白名单:
APC_ALLOWED_ORIGINS必须显式配置,不允许通配符*。 - 全局异常处理:500 响应不包含原始异常信息,详细堆栈仅写入服务端日志。
- 可选开启后端鉴权:
APC_REQUIRE_API_KEY=1+APC_API_KEY,请求头使用x-api-key。
项目结构
ai-paper-coach/
|- apps/web/                  # Vue 3 + Vite 前端
|  |- src/views/              # 页面组件(ResultsView, TaskView 等)
|  |- src/composables/        # 组合式函数(useTraceHistory 等)
|  `- src/lib/                # 工具库(API 调用、本地存储)
|- services/api/              # FastAPI 后端
|  |- app/core/
|  |  |- model_router.py      # 模型调用路由(同步 + 异步双轨)
|  |  |- orchestrator.py      # 分析/审阅/整理编排
|  |  |- pipeline.py          # Pipeline 任务管理(async)
|  |  |- rag.py               # RAG 检索增强生成
|  |  |- tracing.py           # LangSmith 追踪集成
|  |  |- storage.py           # SQLite 存储(连接池)
|  |  `- parser.py            # PDF 解析(按页提取)
|  |- app/routers/            # HTTP 端点
|  `- tests/                  # pytest 测试
|- services/data/             # 运行时数据(DB、上传、缓存)
|- caogao/                    # README 截图素材
|- run.py                     # 一键启动前后端
`- README.md
快速开始
1) 安装后端依赖
cd services/api
pip install -r requirements.txt
2) 安装前端依赖
cd apps/web
npm install
3) 配置环境变量
cp .env.example .env
按需填写模型配置;不填也可在 MVP 模式下运行部分流程。
安全相关可选配置:
APC_ALLOWED_ORIGINS:CORS 白名单,逗号分隔(如http://localhost:5500,https://your-domain.com)APC_MAX_UPLOAD_MB:上传 PDF 大小限制(默认20)APC_REQUIRE_API_KEY:是否开启 API Key 鉴权(0/1)APC_API_KEY:鉴权 key(请求头使用x-api-key)
4) 一键启动
python run.py
5) 运行后端测试(新增)
cd services/api
pytest -q
手动启动(可选)
后端:
cd services/api
uvicorn app.main:app --reload --host 0.0.0.0 --port 8000
前端:
cd apps/web
npm run dev -- --host 127.0.0.1 --port 5500
主要 API
GET /health— API 连通性检查POST /validate-models— 模型接口校验POST /ingest— 论文导入(URL / PDF 上传)POST /analyze— 结构化分析POST /review— 审阅POST /finalize— 整理定稿POST /pipeline/start— 启动全自动流水线(异步,SSE 进度)GET /pipeline/jobs/{job_id}/events— 流水线 SSE 事件流POST /rag/query— RAG 检索问答GET /report/{paper_id}— 获取报告GET /export/{paper_id}.md— 导出 MarkdownGET /export/{paper_id}.pdf— 导出 PDFGET /trace/{paper_id}— 获取 trace 记录GET /history/DELETE /history/{record_id}— 历史管理GET /saved/DELETE /saved/{record_id}— 已保存报告管理
统一响应结构
除流式接口外,JSON 接口统一返回:
{
  "success": true,
  "data": {},
  "error": null
}
失败返回:
{
  "success": false,
  "data": null,
  "error": {
    "code": 400,
    "message": "...",
    "details": null
  }
}
适用场景
- 上课/组会前 10 分钟快速吃透论文
- 形成复现实验 TODO 清单
- 比较不同模型配置下的输出质量
- 长期积累论文阅读档案
English
Overview
AI Paper Coach helps students and researchers read papers faster and reproduce results with more confidence. You can ingest a paper from URL/PDF, generate structured reports, and continue with Q&A and traceable history.
30-Second Value
- Problem solved: unify scattered paper reading tasks (understanding, critique, reproducibility) into one workflow.
- Core capability: structured analysis + 7-question framework + reproducibility guidance with traceable diagnostics.
- Audience: students preparing talks and researchers doing literature review or reproduction work.
Highlights
- End-to-end pipeline:
ingest -> analyze -> review -> finalize -> report - Structured 7-question reading framework
- RAG Q&A: retrieval-augmented generation over paper text, with cross-lingual query support
- AI chat quick prompts: built-in dropdown with common paper questions for one-click insertion
- Side-by-side report + original PDF reading
- History and saved reports with deletion support
- Async pipeline architecture with SSE progress streaming
- LangSmith tracing integration for observability
Content Thresholds (Current)
- Summary (
three_minute_summary.problem):>= 800chars - Reproduction guide (combined fields):
>= 1000chars - 7 Q&A answers: each
>= 700chars
FAQ
Where should I put model keys?
Use the project root .env (based on .env.example). For production, prefer environment-variable injection.
Why can finalize be slow?finalize may trigger repair/retry loops after validation. Trace now records per-call latency, repair trigger, and retry count.
Why does title show a placeholder?
When parsing metadata/title fails, a placeholder is used. Current version adds arXiv API fallback and better placeholder detection.
What if reproduction guidance is empty?
Current version includes fallback merge logic. Re-run ingest -> analyze -> review -> finalize and inspect trace if needed.
Version & Roadmap
v0.1done: full pipeline, 7-question outputs, trace observability, title fallback, reproduction-guide fixes.v0.2in progress: RAG with cross-lingual support, async pipeline architecture, ModelRouter async methods, security hardening, SQLite connection pool, LangSmith tracing.v0.3planned: resumable stage runs, finer quality scoring, frontend component refactoring, vector-based RAG.
Security Statement
- API keys are not committed:
.env,.env.*, and*.env.localare ignored. gitleakshistory scan reports0findings.- CORS whitelist is enforced (no wildcard
*allowed). - Global exception handler: 500 responses never expose raw exception details.
- Optional backend key auth:
APC_REQUIRE_API_KEY=1andAPC_API_KEYviax-api-keyheader.
Quick Start
# backend
cd services/api
pip install -r requirements.txt

# frontend
cd apps/web
npm install

# run all
python run.py

# backend tests
cd services/api
pytest -q
Optional security env vars in .env:
APC_ALLOWED_ORIGINS: comma-separated CORS whitelistAPC_MAX_UPLOAD_MB: upload limit in MB (default20)APC_REQUIRE_API_KEY: enable API key auth (0/1)APC_API_KEY: expected value inx-api-keyheader
Key APIs
GET /health— connectivity checkPOST /validate-models— model provider validationPOST /ingest— paper import (URL / PDF upload)POST /analyze— structured analysisPOST /review— reviewPOST /finalize— finalizePOST /pipeline/start— async full pipeline with SSE progressPOST /rag/query— RAG retrieval Q&AGET /report/{paper_id}— get reportGET /export/{paper_id}.md/.pdf— exportGET /trace/{paper_id}— trace records
Unified Response Envelope
For non-streaming JSON APIs, the response format is:
{
  "success": true,
  "data": {},
  "error": null
}
Error format:
{
  "success": false,
  "data": null,
  "error": {
    "code": 400,
    "message": "...",
    "details": null
  }
}
Contributing
Issues and PRs are welcome. Please include:
- clear problem statement
- reproducible steps
- expected vs. actual behavior
Explore related projects
affaan-m/ECC
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
300,984 starsNousResearch/hermes-agent
The agent that grows with you
262,573 starsmultica-ai/andrej-karpathy-skills
A single CLAUDE.md file to improve Claude Code behavior, derived from Andrej Karpathy's observations on LLM coding pitfalls.
232,024 starsfirecrawl/firecrawl
Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥
200,444 stars