
haiyangliu0/character-policy
haiyangliu0/character-policy has 1,317 GitHub stars and 194 forks. GitHot measured 0 stars in 24 hours and +3 in 7 days. Last checked 2026-11-12 00:11 UTC. Last push 2026-11-02.
character-policy: Official Benchmark & Codebase for Multimodal 3D Character & Holistic Co-Speech Gesture Policy
Measured star growth
- in 24h
- 0
- in 7 days
- +3
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Originalcharacter-policy
multimodal interactive 3D character policy
character-policy is an open-source research project for multimodal interactive 3D character policies:
(1) generating face and body animation from speech · (2) generating body animation from text
It works as an API that takes speech, text, trajectory, or scene inputs and outputs standard 3D motion parameters
such as SMPL, transferable to iPhone ARKit Blendshape weights, Vicon Skeleton BVH files, or game engines.


News
- [2026.09] Released World2Motion for scene-aware 3D motion generation.
- [2026.09] Released Triangular Resampling for long-horizon streaming motion generation.
- [2026.09] Released FloodDiffusion 2 for path-controllable streaming motion generation.
- [2026.09] Released GestureFAR for streaming co-speech gesture generation.
- [2026.09] Intentional-Gesture accepted to NeurIPS 2026.
- [2026.05] Released PersonaGesture for single-reference speaker style personalization.
- [2026.02] FloodDiffusion accepted to CVPR 2026 (Highlight).
- [2025.07] GestureLSM accepted to ICCV 2025.
1. Demo
| FD2 (2.3 ms Real-Time Stream) | Triangular Resampling (120s+ Long-Horizon Rollout) |
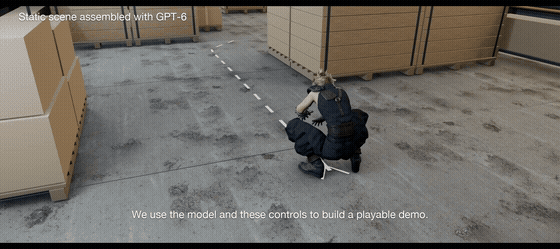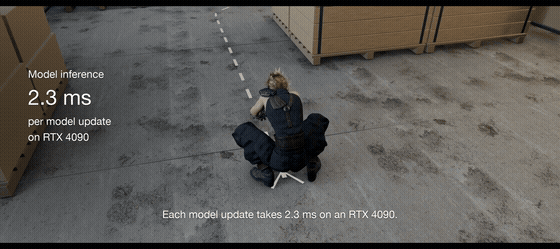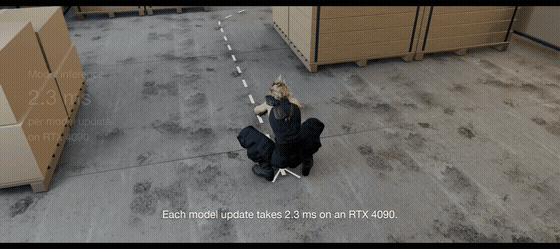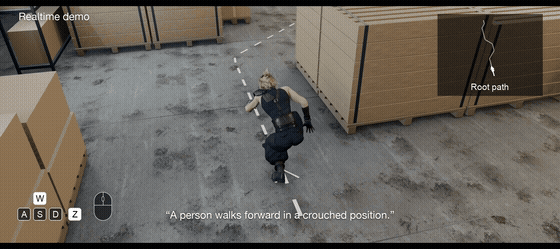 |
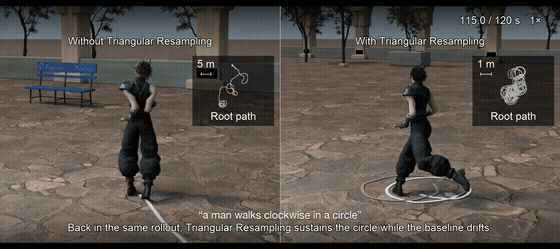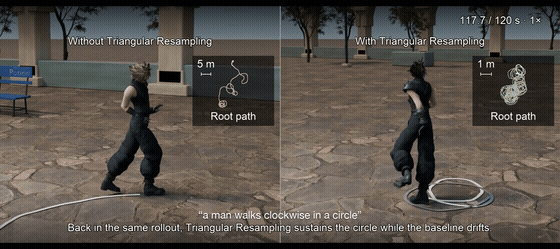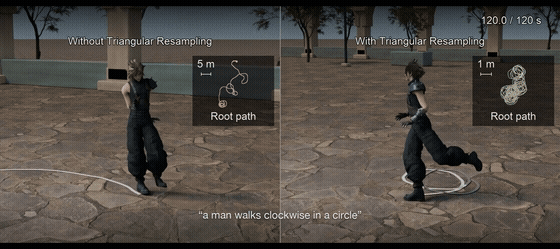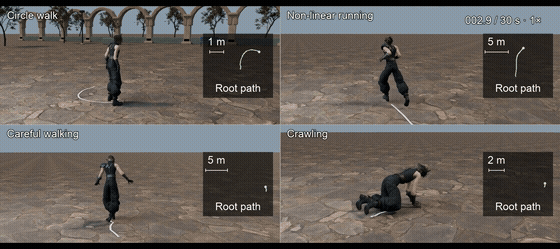 |
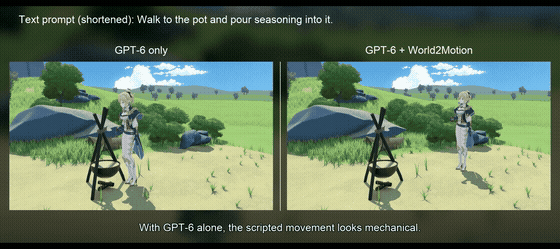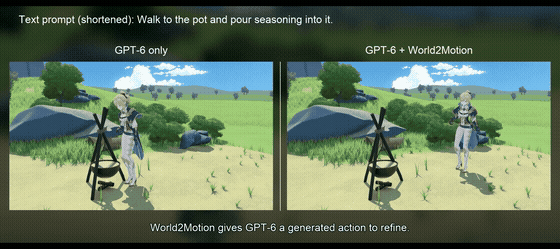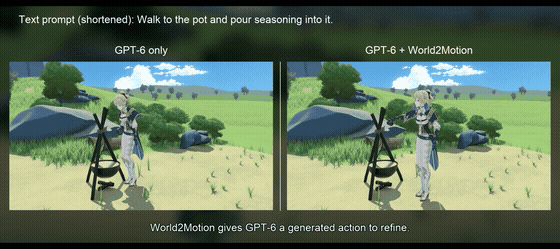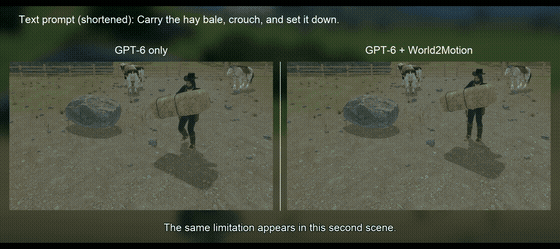
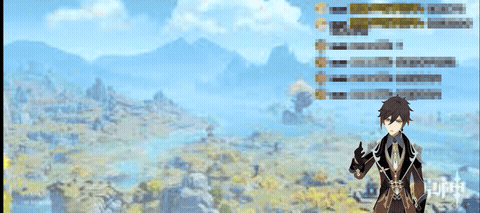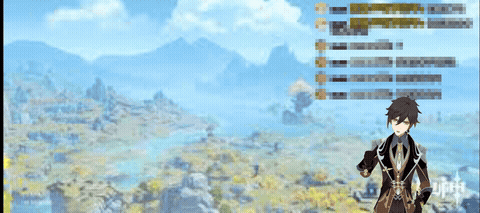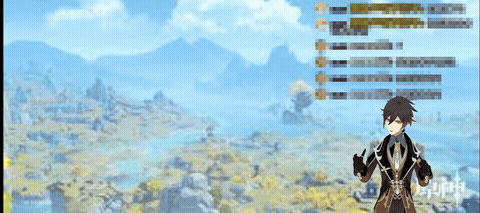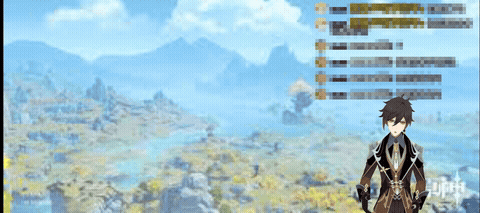
| World2Motion (GPT-6 + 3D World Grounding) | Co-Speech (Audio → Full-Body & 3D Avatar) |
 |
 |
2. Models, Weights & Benchmarks
2.1 Generating Face and Body Animation from Speech (BEAT2)
All outputs are in SMPL-X (body + hands) and FLAME (face) parameters evaluated on BEAT2 (Speaker 2 Scott).
Models from character-policy Team
| Model | Venue | Similarity (FGD ↓) |
Audio Alignment (BC ↑) |
Diversity (Div →) |
Inputs | Outputs | Links |
|---|---|---|---|---|---|---|---|
| Real Data | — | — | 0.703 | 11.97 | — | Full Body + Face | BEAT2 Dataset |
| DisCo (Haiyang Liu et al.) | ACM MM 2022 | 0.942 | 0.643 | 9.91 | Audio | Upper + Hands | Weights · Paper |
| CaMN (Haiyang Liu et al.) | ECCV 2022 | 0.664 | 0.676 | 10.86 | Audio | Upper + Hands | Weights · Paper |
| EMAGE (Haiyang Liu et al.) | CVPR 2024 | 0.551 | 0.772 | 13.06 | Audio + Text | Full Body + Face | Weights · Paper |
| GestureLSM (Pinxin Liu et al.) | ICCV 2025 | 0.409 | 0.714 | 13.24 | Audio + Text | Full Body + Face | Code · Paper |
| Intentional-Gesture (Pinxin Liu et al.) | NeurIPS 2026 | 0.379 | 0.690 | 11.00 | Audio + Text | Full Body + Face | Code · Paper |
| PersonaGesture (Xiangyue Zhang et al.) | ArXiv 2026 | 0.393 | 0.710 | 13.25 | Audio + Ref Clip | Full Body + Face | Paper |
| GestureFAR (Pinxin Liu et al.) | ArXiv 2026 | 0.308 | 0.741 | 13.24 | Streaming Audio | Full Body + Face | Code · Paper |
Models from Community*
*Agent-summarized models reported on BEAT2 (Speaker 2); may contain inaccuracies, issues or PRs for corrections and new entries are welcome.
| Model | Venue | Similarity (FGD ↓) |
Audio Alignment (BC ↑) |
Diversity (Div →) |
Links |
|---|---|---|---|---|---|
| LivelySpeaker (Yihao Zhi et al.) | ICCV 2023 | 1.180 | 0.666 | 11.28 | Code · Paper |
| DiffSHEG (Junming Chen et al.) | CVPR 2024 | 0.714 | 0.743 | 8.21 | Code · Paper |
| Audio2Photoreal (Evonne Ng et al.) | CVPR 2024 | 1.020 | 0.550 | 12.47 | Code · Paper |
| ProbTalk (Yifei Liu et al.) | CVPR 2024 | 0.504 | 0.771 | 13.27 | Code · Paper |
| SynTalker (Bohong Chen et al.) | ACM MM 2024 | 0.469 | 0.736 | 12.43 | Code · Paper |
| MambaTalk (Zunnan Xu et al.) | NeurIPS 2024 | 0.537 | 0.781 | 13.05 | Code · Paper |
| RAG-Gesture (Mahmoud H. Mughal et al.) | CVPR 2025 | 0.879 | 0.730 | 12.62 | Code · Paper |
| SemTalk (Xiangyue Zhang et al.) | ICCV 2025 | 0.428 | 0.777 | 12.91 | Code · Paper |
| GlobalDiff (Xiangyue Zhang et al.) | AAAI 2026 | 0.478 | 0.705 | 13.73 | Code · Paper |
| MIBURI (Mahmoud H. Mughal et al.) | CVPR 2026 | 0.806 | 0.790 | 17.50 | Code · Paper |
| LiveGesture (Muhammad H. Saleem et al.) | CVPR 2026 | 0.457 | 0.794 | 13.91 | Paper |
| StreamTalk (Xiangyue Zhang et al.) | ECCV 2026 | 0.383 | 0.704 | 13.18 | Code · Paper |
2.2 Generating Body Animation from Text (HumanML3D)
All outputs are 3D body motion parameters evaluated on HumanML3D.
Models from character-policy Team
| Model | Venue | Similarity (FID ↓) |
Text Alignment (R@3 ↑) |
Diversity (Div →) |
Inputs | Outputs | Links |
|---|---|---|---|---|---|---|---|
| Real Motion | — | — | 0.797 | 9.50 | — | Full Body | HumanML3D |
| FloodDiffusion (Yiyi Cai et al.) | CVPR 2026 | 0.057 | 0.810 | 9.58 | Streaming Text | Full Body | Code · Paper |
| FloodDiffusion 2 (Yiyi Cai et al.) | ArXiv 2026 | 0.050 | 0.816 | 9.31 | Streaming Text + Path | Full Body + Trajectory | Code · Paper |
| Triangular Resampling (Kunhang Li et al.) | ArXiv 2026 | — | — | — | Streaming Text | Full Body | Paper |
| World2Motion (Fangyuan Tu et al.) | ArXiv 2026 | — | — | — | Image + Text | Full Body + Video | Project · Paper |
Models from Community*
*Agent-summarized models reported on HumanML3D; may contain inaccuracies, issues or PRs for corrections and new entries are welcome.
| Model | Venue | Similarity (FID ↓) |
Text Alignment (R@3 ↑) |
Diversity (Div →) |
Links |
|---|---|---|---|---|---|
| MDM (Guy Tevet et al.) | ICLR 2023 | 0.544 | 0.611 | 9.56 | Code · Paper |
| MLD (Xin Chen et al.) | CVPR 2023 | 0.473 | 0.772 | 9.72 | Code · Paper |
| T2M-GPT (Jianrong Zhang et al.) | CVPR 2023 | 0.141 | 0.775 | 9.72 | Code · Paper |
| ReMoDiffuse (Mingyuan Zhang et al.) | ICCV 2023 | 0.103 | 0.795 | 9.02 | Code · Paper |
| FineMoGen (Mingyuan Zhang et al.) | NeurIPS 2023 | 0.151 | 0.784 | 9.26 | Code · Paper |
| OmniControl (Yiming Xie et al.) | ICLR 2024 | 0.100 | 0.804 | 9.69 | Code · Paper |
| MMM (Ekkasit Pinyoanuntapong et al.) | CVPR 2024 | 0.089 | 0.804 | 9.41 | Code · Paper |
| MoMask (Chuan Guo et al.) | CVPR 2024 | 0.045 | 0.807 | 9.68 | Code · Paper |
| Motion Mamba (Zeyu Zhang et al.) | ECCV 2024 | 0.281 | 0.792 | 9.87 | Code · Paper |
| ParCo (Qiran Zou et al.) | ECCV 2024 | 0.109 | 0.795 | 9.57 | Code · Paper |
| MotionLCM (Wenxun Dai et al.) | ECCV 2024 | 0.304 | 0.798 | 9.61 | Code · Paper |
| BAMM (Ekkasit Pinyoanuntapong et al.) | ECCV 2024 | 0.055 | 0.814 | 9.72 | Code · Paper |
| MoGenTS (Weihao Yuan et al.) | NeurIPS 2024 | 0.033 | 0.812 | 9.57 | Code · Paper |
| DART (Kaifeng Zhao et al.) | ICLR 2025 | 0.854 | 0.722 | 9.50 | Code · Paper |
| MARDM (Zichong Meng et al.) | CVPR 2025 | 0.114 | 0.795 | 9.66 | Code · Paper |
| SALAD (Seokhyeon Hong et al.) | CVPR 2025 | 0.076 | 0.857 | 9.70 | Code · Paper |
| PRIMAL (Yan Zhang et al.) | ICCV 2025 | 0.511 | 0.780 | 9.52 | Code · Paper |
| MotionStreamer (Lixing Xiao et al.) | ICCV 2025 | 0.092 | 0.802 | 9.72 | Code · Paper |
| MoMask++ (Chuan Guo et al.) | NeurIPS 2025 | 0.072 | 0.811 | 9.56 | Code · Paper |
| Event-T2M (Seong-Eun Hong et al.) | ICLR 2026 | 0.056 | 0.842 | 9.61 | Project · Paper |
| CMDM (Qing Yu et al.) | CVPR 2026 | 0.068 | 0.860 | 9.44 | Code · Paper |
| MotionHiFlow (Heng Li et al.) | CVPR 2026 | 0.032 | 0.843 | 9.50 | Paper |
| ScaleMoGen (Inwoo Hwang et al.) | ECCV 2026 | 0.030 | 0.856 | 9.54 | Project · Paper |
| BiMoGen (Wanjiang Weng et al.) | NeurIPS 2026 | 0.047 | 0.818 | 9.42 | Paper |
3. Data & Tools
Data & Tools from character-policy Team
| Resource | Description | Links |
|---|---|---|
| BEAT2 | 76h co‑speech 3D body, hand & face dataset (30 speakers, SMPL‑X + FLAME) | HuggingFace |
| BEAT | 76h co‑speech 3D body, hand & face dataset (30 speakers, BVH + ARKit) | HuggingFace |
| EMAGE Eval Tools | BEAT2 evaluation (FGD / BC / Div) & neutral SMPL‑X model | HuggingFace |
| ARKit2FLAME | Convert between FLAME (100‑D) and iPhone ARKit (52‑D) blendshapes | Download |
| Blender SMPL‑X Add‑on | Import and animate SMPL‑X + FLAME .npz files in Blender |
Download |
| BEAT Avatars & Renderer | Rigged 3D character avatars and batch video rendering scripts | Avatars · Scripts |
4. For Agents Using This Repo
- Input:
.wavmono speech audio (resampled automatically to16,000 Hz). - Output:
.npzdictionary at30 FPS(T = int(audio_seconds * 30)), saved viaemage_utils.motion_io.beat_format_save:
| Key | Shape & Dtype | Specification |
|---|---|---|
poses |
(T, 165) float32 |
SMPL-X 55-joint axis-angle (0:3 root, 3:66 21 body, 66:69 jaw, 69:75 eyes, 75:165 30 hands) |
expressions |
(T, 100) float32 |
FLAME 100-D facial expression parameters |
trans |
(T, 3) float32 |
Global root translation in meters |
betas |
(300,) float32 |
SMPL-X shape parameters |
mocap_frame_rate |
30 |
Frame rate (30 FPS) |
gender / model |
"neutral" / "smplx2020" |
Mesh topology identifiers |
git clone https://github.com/haiyangliu0/character-policy.git
cd character-policy

uv venv .venv --python 3.10
source .venv/bin/activate
uv pip install "setuptools<70" pip wheel "numpy<1.24"
uv pip install torch torchvision torchaudio librosa==0.9.2 soundfile scipy scikit-learn tqdm pyyaml wandb
uv pip install transformers==4.46.3 huggingface_hub accelerate einops timm
uv pip install smplx==0.1.28 trimesh pyrender pyopengl imageio moviepy==1.0.3 opencv-python wget
uv pip install --no-build-isolation chumpy

git clone https://huggingface.co/haiyangliu0/emage_evaltools

# Inference & rendering (.npz + .mp4 to ./examples/motion)
python test_emage_audio.py --audio_folder ./examples/audio --save_folder ./examples/motion --visualization
python test_camn_audio.py --audio_folder ./examples/audio --save_folder ./examples/motion --visualization --nopytorch3d
python test_disco_audio.py --audio_folder ./examples/audio --save_folder ./examples/motion --visualization --nopytorch3d

# Training on BEAT2
hf download haiyangliu0/BEAT2 --repo-type dataset --local-dir ./BEAT2
python ./datasets/foot_contact.py
torchrun --nproc_per_node=1 train_emage_audio.py --config ./configs/emage_audio.yaml --evaluation
Explore related projects
ytdl-org/youtube-dl
Command-line program to download videos from YouTube.com and other video sites
141,539 starsexcalidraw/excalidraw
Virtual whiteboard for sketching hand-drawn like diagrams
135,492 starsgodotengine/godot
Godot Engine – Multi-platform 2D and 3D game engine
120,003 starsmrdoob/three.js
JavaScript 3D Library.
118,122 stars