
feast-dev/feast
feast-dev/feast has 7,354 GitHub stars and 1,491 forks. GitHot measured +4 in 7 days. Last checked 2026-11-04 22:02 UTC. Last push 2026-11-04.
The Open Source Feature Store for AI/ML
Measured star growth
- in 24h
- Update delayed
- in 7 days
- +4
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original


Join us on Slack!
Overview
Feast (Feature Store) is an open source feature store for machine learning. Feast is the fastest path to manage existing infrastructure to productionize analytic data for model training and online inference.
Feast allows ML platform teams to:
- Make features consistently available for training and serving by managing an offline store (to process historical data for scale-out batch scoring or model training), a low-latency online store (to power real-time prediction), and a battle-tested feature server (to serve pre-computed features online).
- Avoid data leakage by generating point-in-time correct feature sets so data scientists can focus on feature engineering rather than debugging error-prone dataset joining logic. This ensure that future feature values do not leak to models during training.
- Decouple ML from data infrastructure by providing a single data access layer that abstracts feature storage from feature retrieval, ensuring models remain portable as you move from training models to serving models, from batch models to realtime models, and from one data infra system to another.
Please see our documentation for more information about the project.
📐 Architecture
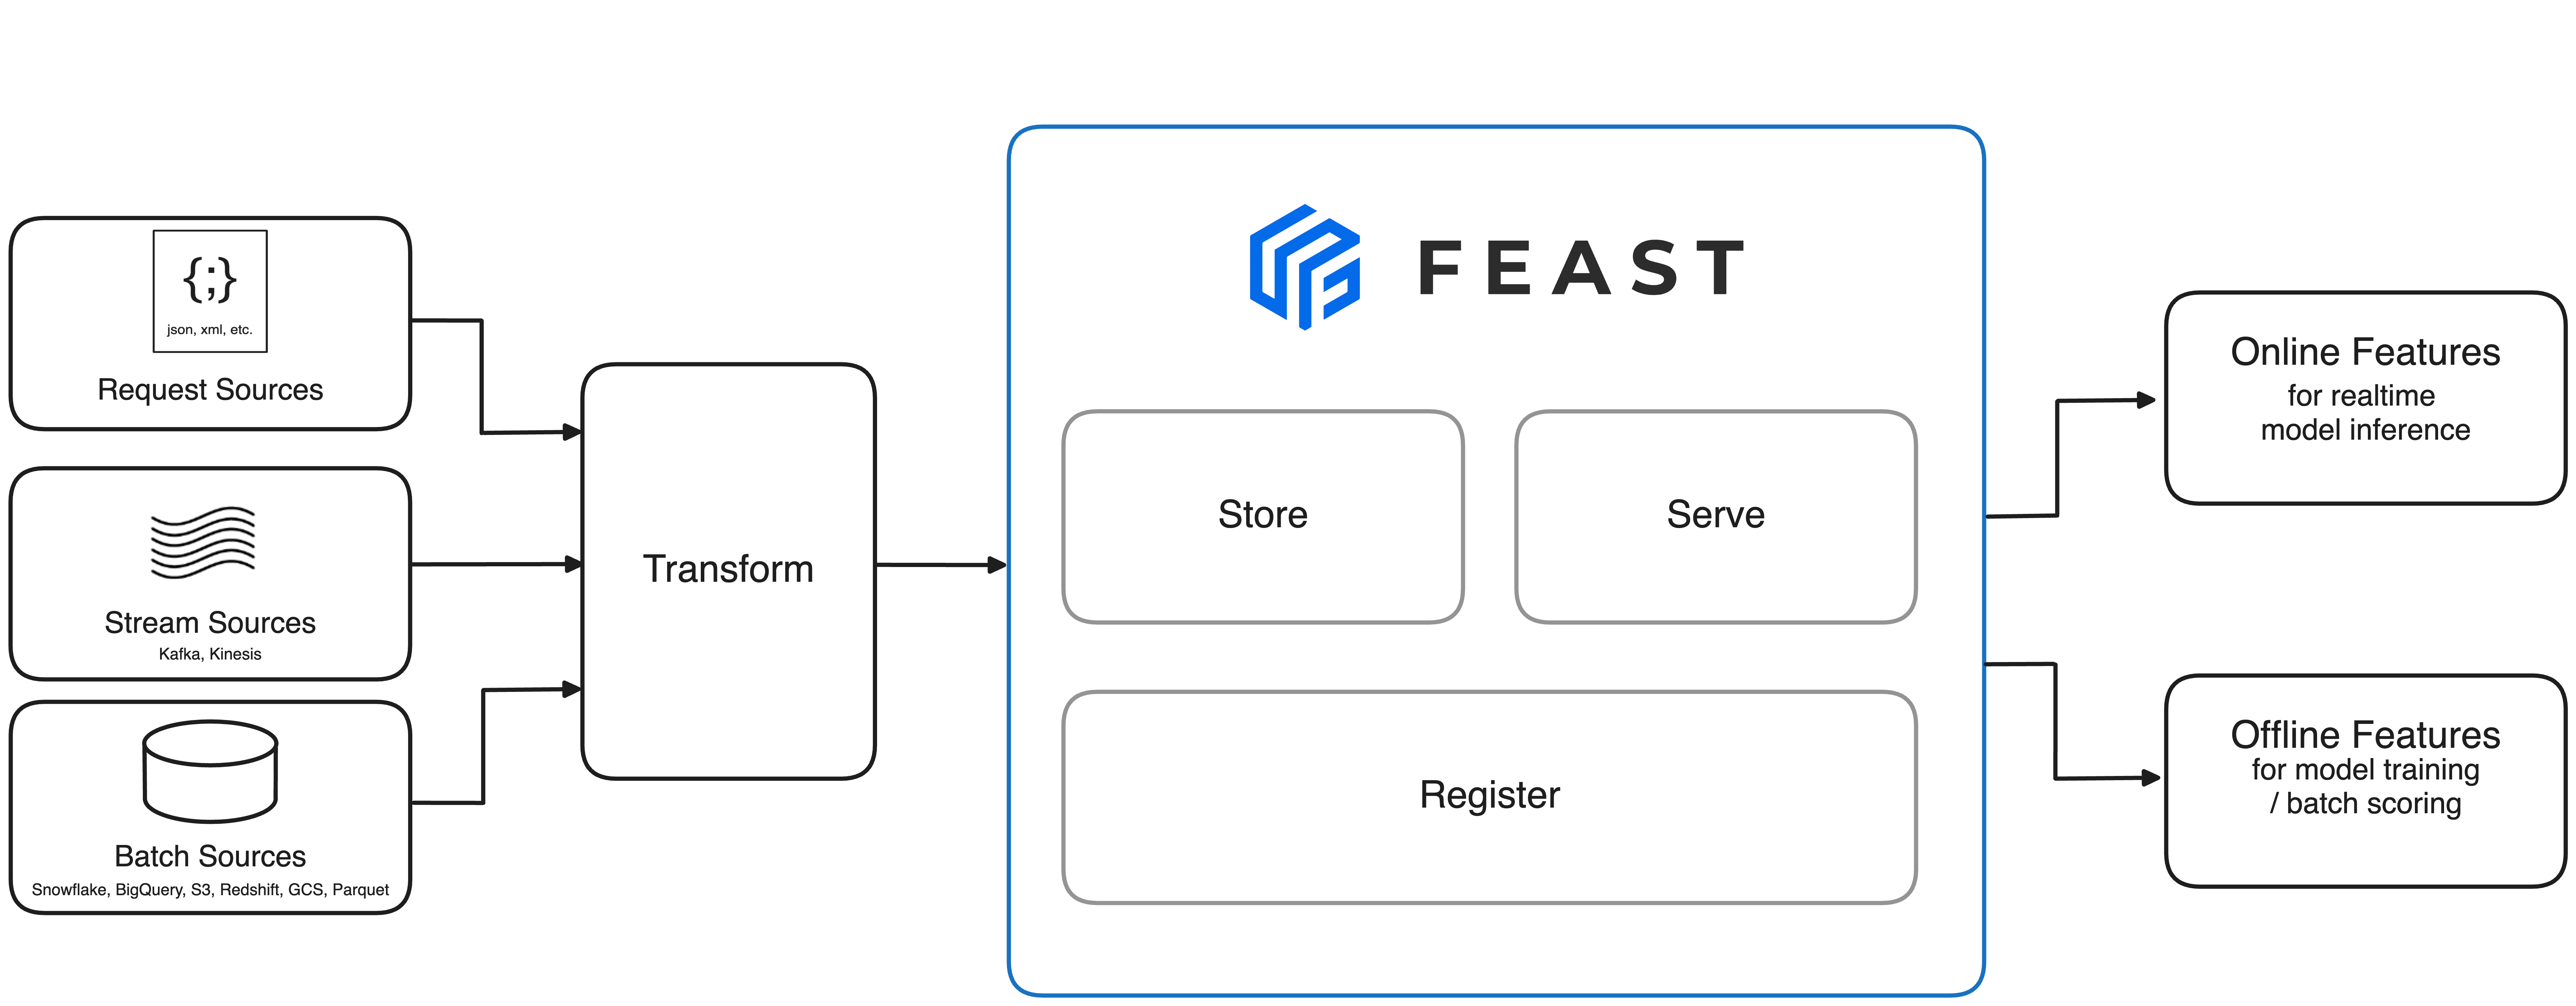
The above architecture is the minimal Feast deployment. Want to run the full Feast on Snowflake/GCP/AWS? Click here.
🐣 Getting Started
1. Install Feast
pip install feast
2. Create a feature repository
feast init my_feature_repo
cd my_feature_repo/feature_repo
3. Register your feature definitions and set up your feature store
feast apply
4. Explore your data in the web UI (experimental)
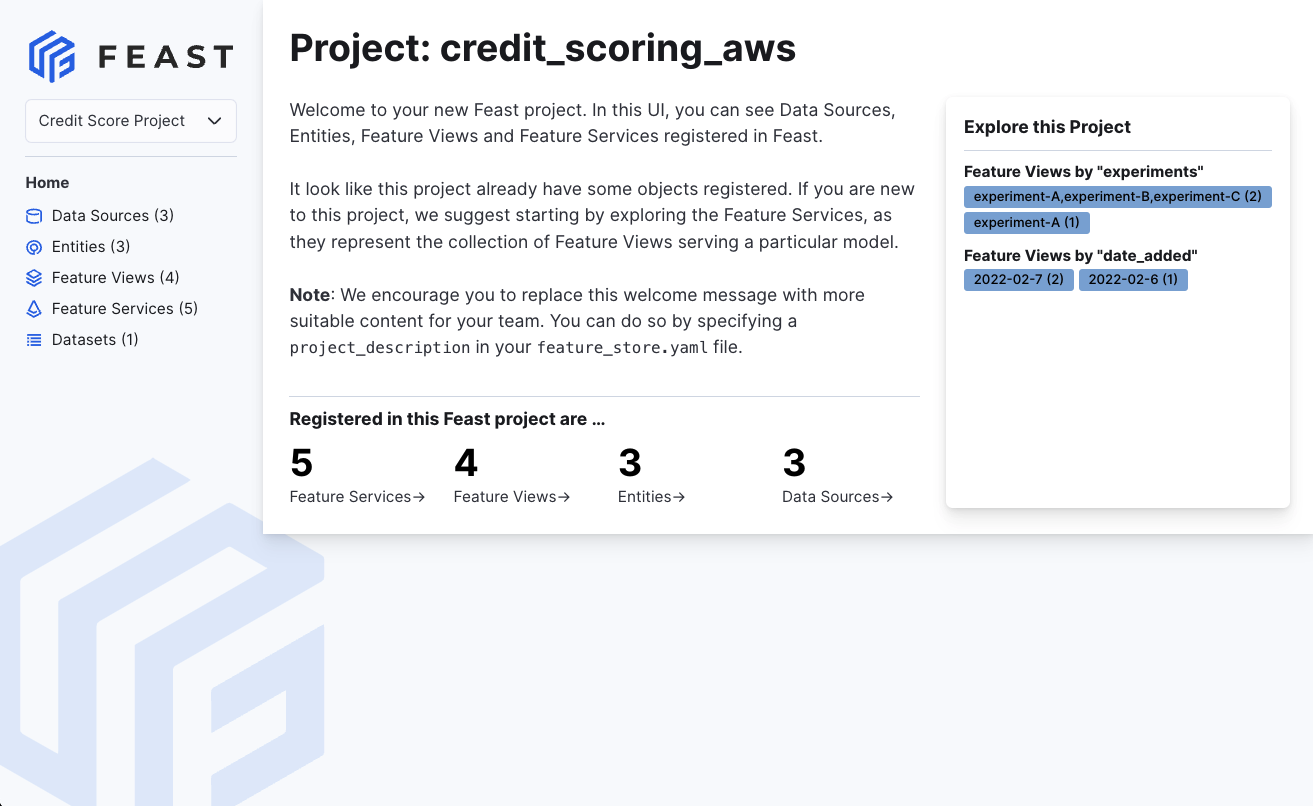
feast ui
5. Build a training dataset
from feast import FeatureStore
import pandas as pd
from datetime import datetime

entity_df = pd.DataFrame.from_dict({
    "driver_id": [1001, 1002, 1003, 1004],
    "event_timestamp": [
        datetime(2021, 4, 12, 10, 59, 42),
        datetime(2021, 4, 12, 8,  12, 10),
        datetime(2021, 4, 12, 16, 40, 26),
        datetime(2021, 4, 12, 15, 1 , 12)
    ]
})

store = FeatureStore(repo_path=".")

training_df = store.get_historical_features(
    entity_df=entity_df,
    features = [
        'driver_hourly_stats:conv_rate',
        'driver_hourly_stats:acc_rate',
        'driver_hourly_stats:avg_daily_trips'
    ],
).to_df()

print(training_df.head())

# Train model
# model = ml.fit(training_df)
            event_timestamp  driver_id  conv_rate  acc_rate  avg_daily_trips
0 2021-04-12 08:12:10+00:00       1002   0.713465  0.597095              531
1 2021-04-12 10:59:42+00:00       1001   0.072752  0.044344               11
2 2021-04-12 15:01:12+00:00       1004   0.658182  0.079150              220
3 2021-04-12 16:40:26+00:00       1003   0.162092  0.309035              959
6. Load feature values into your online store
Option 1: Incremental materialization (recommended)
CURRENT_TIME=$(date -u +"%Y-%m-%dT%H:%M:%S")
feast materialize-incremental $CURRENT_TIME
Option 2: Full materialization with timestamps
CURRENT_TIME=$(date -u +"%Y-%m-%dT%H:%M:%S")
feast materialize 2021-04-12T00:00:00 $CURRENT_TIME
Option 3: Simple materialization without timestamps
feast materialize --disable-event-timestamp
The --disable-event-timestamp flag allows you to materialize all available data (from 1970-01-01 up to the current UTC time) without specifying start and end timestamps. Rows keep the event timestamps from the source.
Materializing feature view driver_hourly_stats from 2021-04-14 to 2021-04-15 done!
7. Read online features at low latency
from pprint import pprint
from feast import FeatureStore

store = FeatureStore(repo_path=".")

feature_vector = store.get_online_features(
    features=[
        'driver_hourly_stats:conv_rate',
        'driver_hourly_stats:acc_rate',
        'driver_hourly_stats:avg_daily_trips'
    ],
    entity_rows=[{"driver_id": 1001}]
).to_dict()

pprint(feature_vector)

# Make prediction
# model.predict(feature_vector)
{
    "driver_id": [1001],
    "driver_hourly_stats__conv_rate": [0.49274],
    "driver_hourly_stats__acc_rate": [0.92743],
    "driver_hourly_stats__avg_daily_trips": [72]
}
📦 Functionality and Roadmap
The list below contains the functionality that contributors are planning to develop for Feast.
We welcome contribution to all items in the roadmap!
Natural Language Processing
- Vector Search (Alpha release. See RFC)
- Enhanced Feature Server and SDK for native support for NLP
Data Sources
- Chronon source (contrib)
- Snowflake source
- Redshift source
- BigQuery source
- Parquet file source
- Azure Synapse + Azure SQL source (contrib plugin)
- Hive (community plugin)
- Postgres (contrib plugin)
- Spark (contrib plugin)
- Couchbase (contrib plugin)
- Athena (contrib plugin)
- Clickhouse (contrib plugin)
- Oracle (contrib plugin)
- MongoDB (contrib plugin)
- Ray source (contrib plugin)
- Kafka / Kinesis sources (via push support into the online store)
Offline Stores
- Chronon (contrib)
- Snowflake
- Redshift
- BigQuery
- DuckDB
- Dask
- Remote
- Azure Synapse + Azure SQL (contrib plugin)
- Hive (community plugin)
- Postgres (contrib plugin)
- Trino (contrib plugin)
- Spark (contrib plugin)
- Couchbase (contrib plugin)
- Athena (contrib plugin)
- Clickhouse (contrib plugin)
- Ray (contrib plugin)
- Oracle (contrib plugin)
- MongoDB (contrib plugin)
- Hybrid
- Custom offline store support
Online Stores
- Chronon
- Snowflake
- DynamoDB
- Redis
- Dragonfly
- Datastore
- Bigtable
- SQLite
- Remote
- Postgres
- HBase
- Cassandra / AstraDB
- ScyllaDB
- MySQL
- Hazelcast
- Elasticsearch
- SingleStore
- Couchbase
- MongoDB
- Aerospike
- Qdrant (vector store)
- Milvus (vector store)
- Faiss (vector store)
- Hybrid
- Azure Cache for Redis (community plugin)
- Custom online store support
Feature Engineering
- On-demand Transformations (On Read) (Beta release. See RFC)
- Streaming Transformations (Alpha release. See RFC)
- Batch transformation (In progress. See RFC)
- On-demand Transformations (On Write) (Beta release. See GitHub Issue)
Streaming
Deployments
Feature Serving
Data Quality Management (See RFC)
- Feature Quality Monitoring — built-in metrics, drift detection, serving log monitoring, and UI dashboard
Feature Discovery and Governance
- Python SDK for browsing feature registry
- CLI for browsing feature registry
- Model-centric feature tracking (feature services)
- Amundsen integration (see Feast extractor)
- DataHub integration (see DataHub Feast docs)
- Feast Web UI (Beta release. See docs)
- Feast Lineage Explorer
🎓 Important Resources
Please refer to the official documentation at Documentation
👋 Contributing
Feast is a community project and is still under active development. Please have a look at our contributing and development guides if you want to contribute to the project:
- Contribution Process for Feast
- Development Guide for Feast
- Development Guide for the Main Feast Repository
🌟 GitHub Star History
✨ Contributors
Thanks goes to these incredible people:
Explore related projects
Asabeneh/30-Days-Of-Python
The 30 Days of Python programming challenge is a step-by-step guide to learn the Python programming language in 30 days. This challenge may take more than 100 days. Follow your own pace. These videos may help too: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,085 starsgrafana/grafana
The open and composable observability and data visualization platform. Visualize metrics, logs, and traces from multiple sources like Prometheus, Loki, Elasticsearch, InfluxDB, Postgres and many more.
77,699 starsredis/redis
For developers, who are building real-time data-driven applications, Redis is the preferred, fastest, and most feature-rich cache, data structure server, and document and vector query engine.
77,173 starsapache/superset
Apache Superset is a Data Visualization and Data Exploration Platform
75,413 stars