
facebookresearch/DepthLM_Official
facebookresearch/DepthLM_Official has 373 GitHub stars and 16 forks. GitHot measured 0 stars in 24 hours and +1 in 7 days. Last checked 2026-11-09 07:29 UTC. Last push 2026-06-01.
[ICLR 2026 Oral (top 1.2%)] Official implementation of DepthLM
Measured star growth
- in 24h
- 0
- in 7 days
- +1
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original[ICLR2026 Oral (top 1.2%)] DepthLM
Official implementation of "DepthLM: Metric Depth from Vision Language Models".
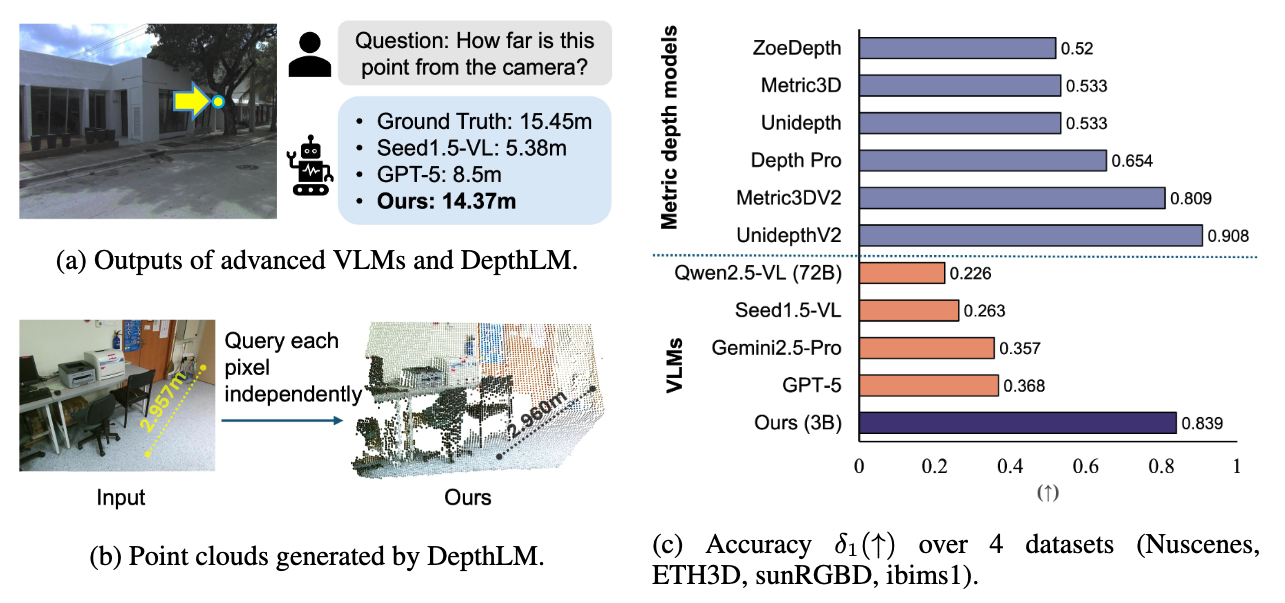
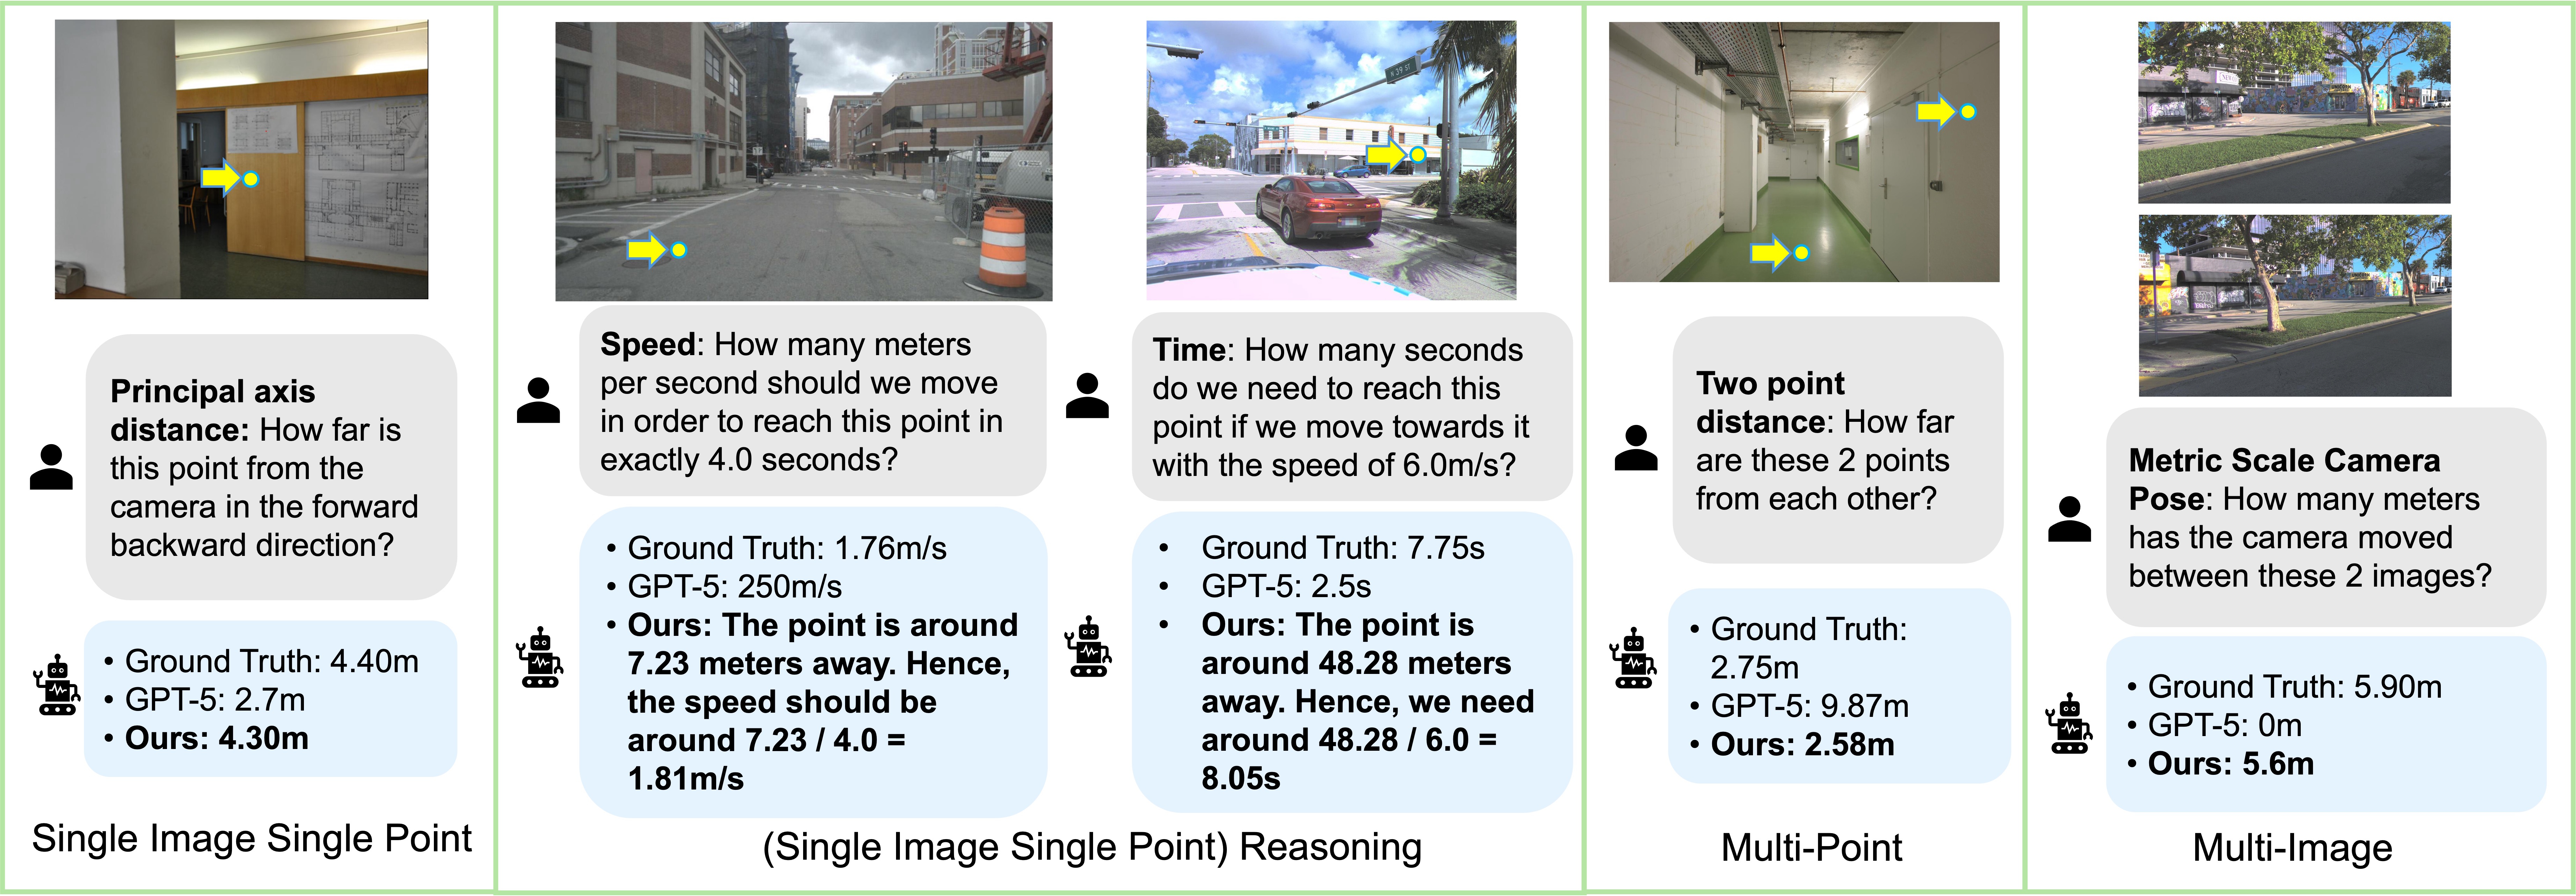
We show for the first time that VLMs can achieve comparable accuracy with pure vision models on metric depth estimation, with standard text-based SFT and no architecture chagne, i.e., no dense prediction head or regression/regularization loss is needed. Such simplicity allows DepthLM to train a unified VLM to handle various complex 3D understanding tasks such as speed or time estimation, and metric scale camera pose estimation, which require different architecture or hand-crafted pipelines in pure vision models.
Citation
If you find our code useful for your research, please consider citing:

@article{cai2025depthlm,
    title={DepthLM: Metric Depth from Vision Language Models},
    author={Cai, Zhipeng and Yeh, Ching-Feng and Hu, Xu and Liu, Zhuang and Meyer, Gregory and Lei, Xinjie and Zhao, Changsheng and Li, Shang-Wen and Chandra, Vikas and Shi, Yangyang},
    journal={arXiv preprint arXiv:2509.25413},
    year={2025},
}
Contact
Zhipeng Cai, Meta Inc, homepage: https://zhipengcai.github.io/, email: czptc2h at gmail dot com.
Prerequisites
- run
conda create -n DepthLM python=3.12 - run
pip install -r requirements.txt(the code is tested with transformers 4.51.1 version)
| Model | Link |
|---|---|
| DepthLM (Pixtral 12B) | Download 🤗 |
| DepthLM (3B) | (Coming soon!) |
| DepthLM (7B) | (Coming soon!) |
Data Preparation
- For each training/eval dataset, we curate them into
- A folder containing the images
- A jsonl file containing the corresponding camera intrinsics and 3D labels
- We provide example data from the iBims1 dataset at examples/ibims1 for quick code run without the need of data preparation. Other images/datasets can use the same code after finishing the data preparation steps.
- Due to legal reasons, we cannot directly release the curated data. However, we provide the data curation code to enable reproduction.
- Checkout each block in prepare_data.sh for the detailed data preparation steps on each dataset.
Eval
- run
bash eval.sh <path_to_your_model>
Training
- Download the base model you want to train from here. Our code currently supports Qwen2.5-VL and Pixtral, please see our paper for the corresponding hyper-parameters.
- run
bash train.sh <path_to_your_model> <output_path>
Results
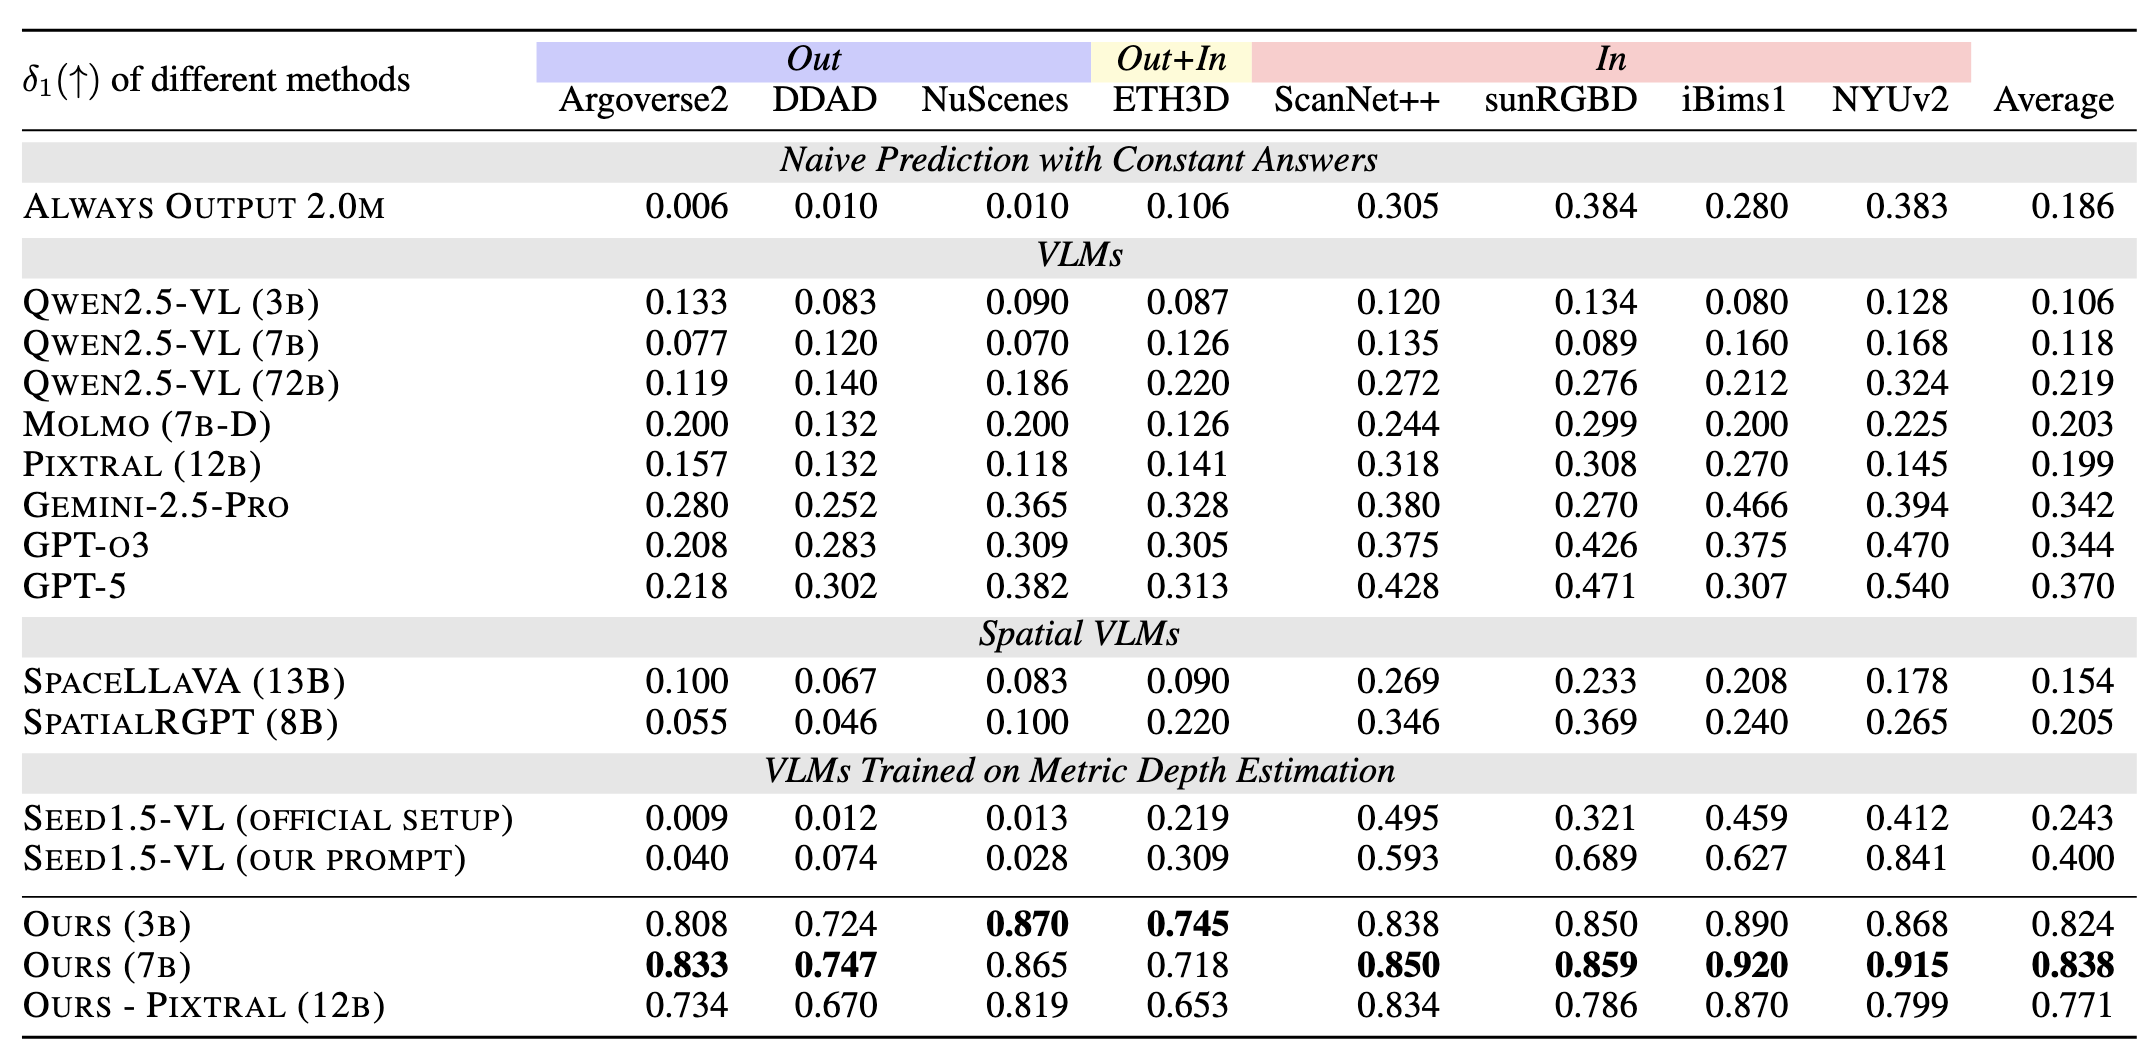
Comparison with VLMs
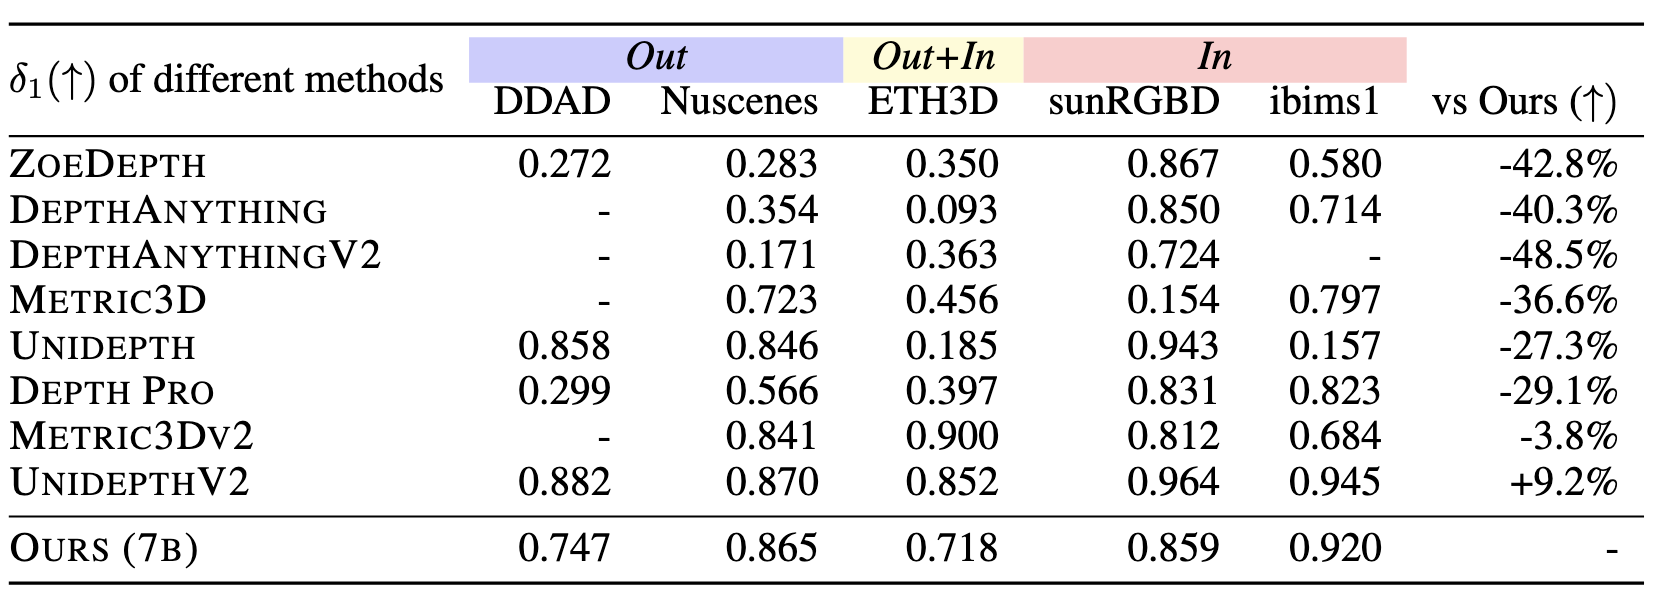
Comparison with pure vision models
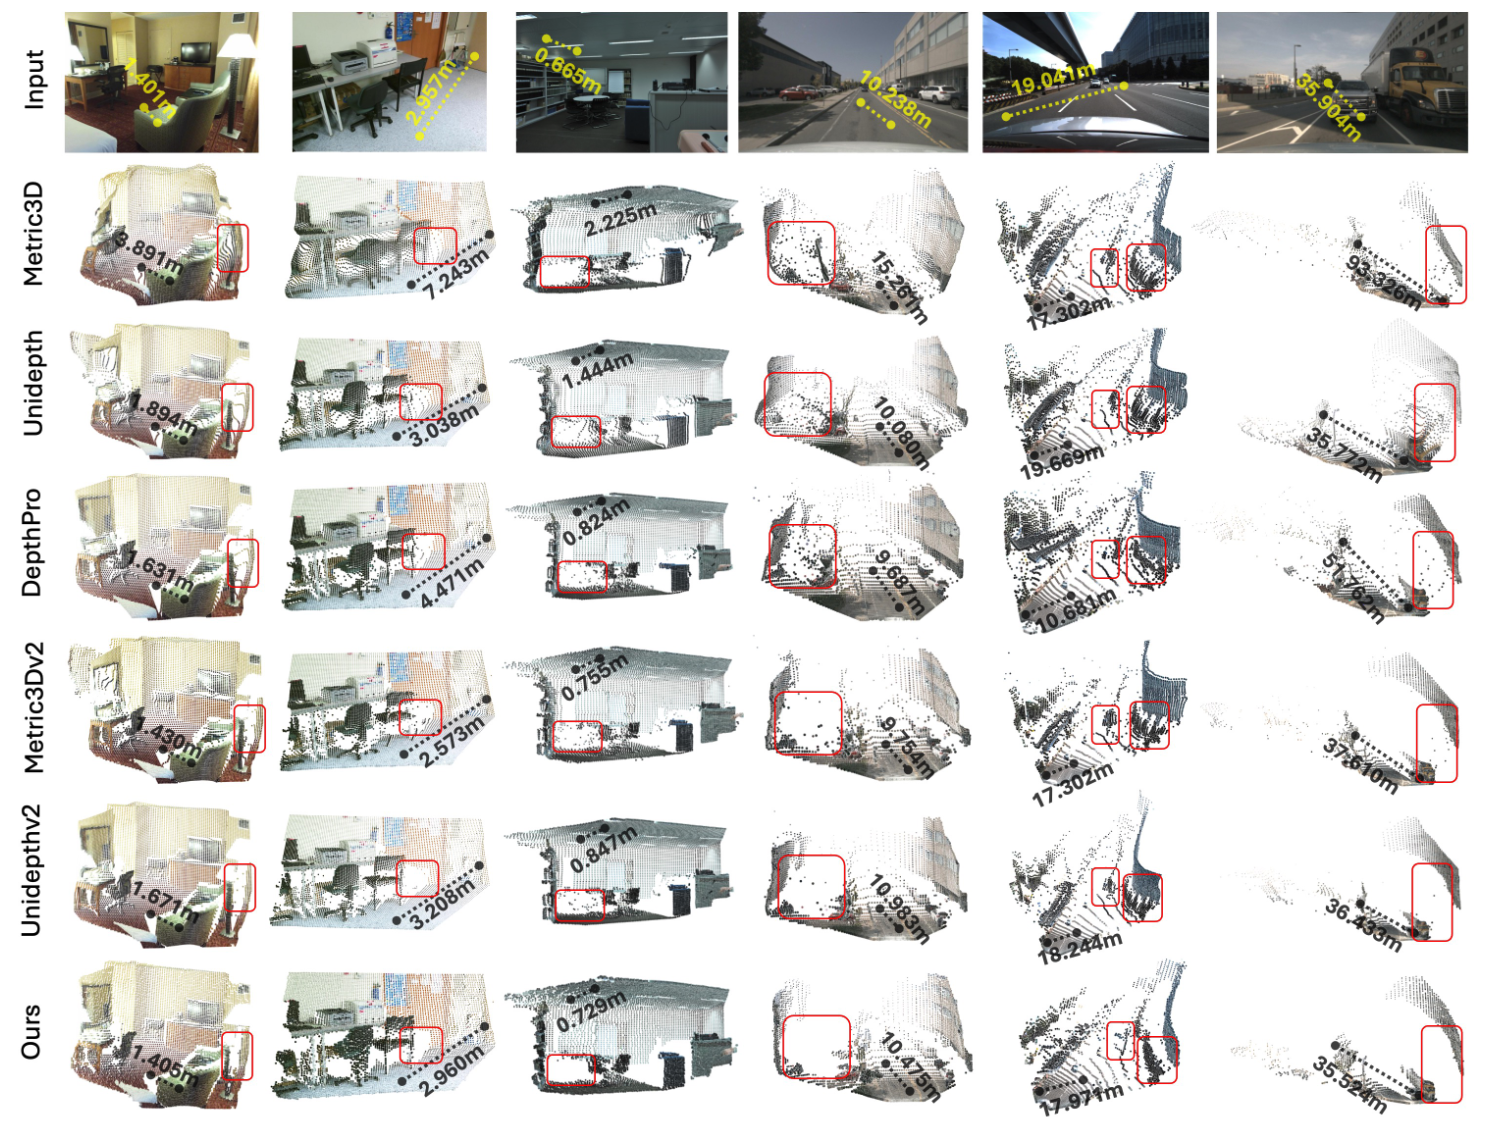
Point cloud visualization
Related project
Our follow up project VLM³ has been released! It extends the findings of DepthLM to diverse 3D vision tasks!
License
DepthLM is FAIR CC-BY-NC licensed, as found in the LICENSE file.
Explore related projects
ytdl-org/youtube-dl
Command-line program to download videos from YouTube.com and other video sites
141,500 starsexcalidraw/excalidraw
Virtual whiteboard for sketching hand-drawn like diagrams
135,396 starsgodotengine/godot
Godot Engine – Multi-platform 2D and 3D game engine
119,840 starsmrdoob/three.js
JavaScript 3D Library.
117,905 stars