
enhuiz/vall-e
enhuiz/vall-e has 2,967 GitHub stars and 398 forks. GitHot measured 0 stars in 24 hours and -1 in 7 days. Last checked 2026-11-06 00:14 UTC. Last push 2023-05-10.
An unofficial PyTorch implementation of the audio LM VALL-E
Measured star growth
- in 24h
- 0
- in 7 days
- -1
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original
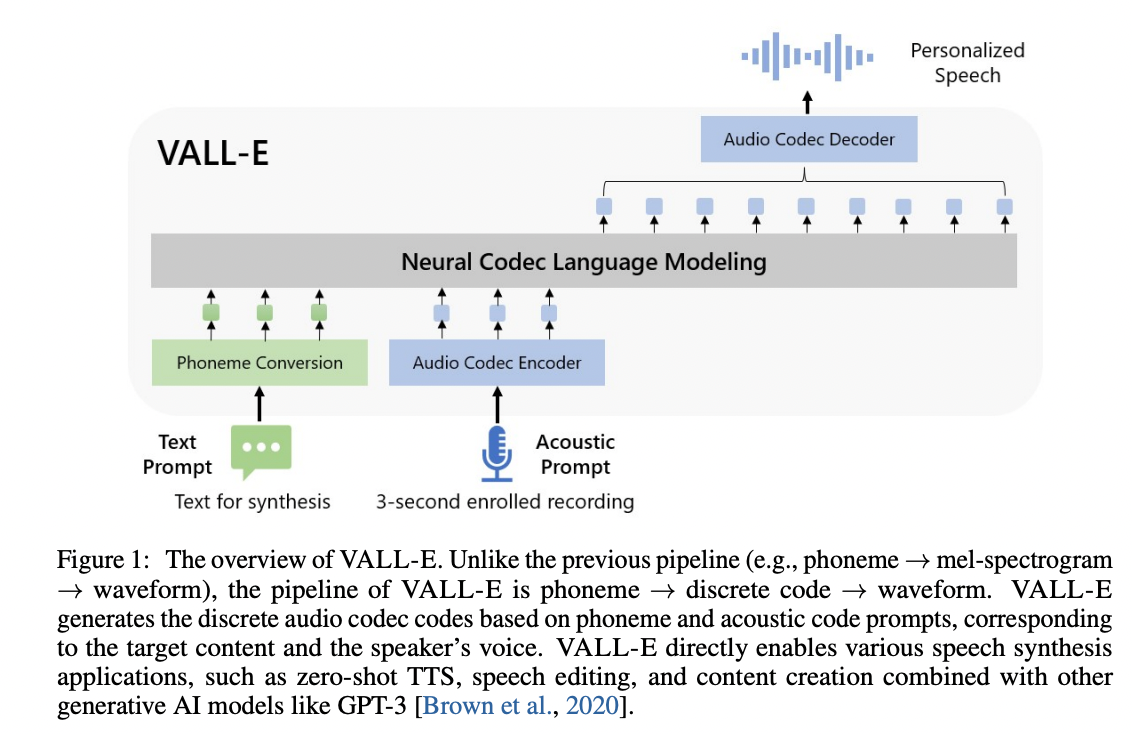
VALL-E
An unofficial PyTorch implementation of VALL-E, based on the EnCodec tokenizer.

Get Started
A toy Google Colab example:
. Please note that this example overfits a single utterance under the
data/testand is not usable. The pretrained model is yet to come.
Requirements
Since the trainer is based on DeepSpeed, you will need to have a GPU that DeepSpeed has developed and tested against, as well as a CUDA or ROCm compiler pre-installed to install this package.
Install
pip install git+https://github.com/enhuiz/vall-e
Or you may clone by:
git clone --recurse-submodules https://github.com/enhuiz/vall-e.git
Note that the code is only tested under Python 3.10.7.
Train
Put your data into a folder, e.g.
data/your_data. Audio files should be named with the suffix.wavand text files with.normalized.txt.Quantize the data:
python -m vall_e.emb.qnt data/your_data
- Generate phonemes based on the text:
python -m vall_e.emb.g2p data/your_data
Customize your configuration by creating
config/your_data/ar.ymlandconfig/your_data/nar.yml. Refer to the example configs inconfig/testandvall_e/config.pyfor details. You may choose different model presets, checkvall_e/vall_e/__init__.py.Train the AR or NAR model using the following scripts:
python -m vall_e.train yaml=config/your_data/ar_or_nar.yml
You may quit your training any time by just typing quit in your CLI. The latest checkpoint will be automatically saved.
Export
Both trained models need to be exported to a certain path. To export either of them, run:
python -m vall_e.export zoo/ar_or_nar.pt yaml=config/your_data/ar_or_nar.yml
This will export the latest checkpoint.
Synthesis
python -m vall_e <text> <ref_path> <out_path> --ar-ckpt zoo/ar.pt --nar-ckpt zoo/nar.pt
TODO
- AR model for the first quantizer
- Audio decoding from tokens
- NAR model for the rest quantizers
- Trainers for both models
- Implement AdaLN for NAR model.
- Sample-wise quantization level sampling for NAR training.
- Pre-trained checkpoint and demos on LibriTTS
- Synthesis CLI
Notice
- EnCodec is licensed under CC-BY-NC 4.0. If you use the code to generate audio quantization or perform decoding, it is important to adhere to the terms of their license.
Citations
@article{wang2023neural,
  title={Neural Codec Language Models are Zero-Shot Text to Speech Synthesizers},
  author={Wang, Chengyi and Chen, Sanyuan and Wu, Yu and Zhang, Ziqiang and Zhou, Long and Liu, Shujie and Chen, Zhuo and Liu, Yanqing and Wang, Huaming and Li, Jinyu and others},
  journal={arXiv preprint arXiv:2301.02111},
  year={2023}
}
@article{defossez2022highfi,
  title={High Fidelity Neural Audio Compression},
  author={Défossez, Alexandre and Copet, Jade and Synnaeve, Gabriel and Adi, Yossi},
  journal={arXiv preprint arXiv:2210.13438},
  year={2022}
}
Explore related projects
tensorflow/tensorflow
An Open Source Machine Learning Framework for Everyone
201,311 starshuggingface/transformers
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
168,576 starsAUTOMATIC1111/stable-diffusion-webui
Stable Diffusion web UI
165,264 starsComfy-Org/ComfyUI
The most powerful and modular diffusion model GUI, api and backend with a graph/nodes interface. The fastest local inference engine in the world.
145,310 stars