
dllm-reasoning/d1 has 461 GitHub stars and 54 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-17 18:45 UTC. Last push 2026-08-30.
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Official Implementation for the paper "d1: Scaling Reasoning in Diffusion Large Language Models via Reinforcement Learning"
LearningREADME.md
Originald1: Scaling Reasoning in Diffusion Large Language Models via Reinforcement Learning
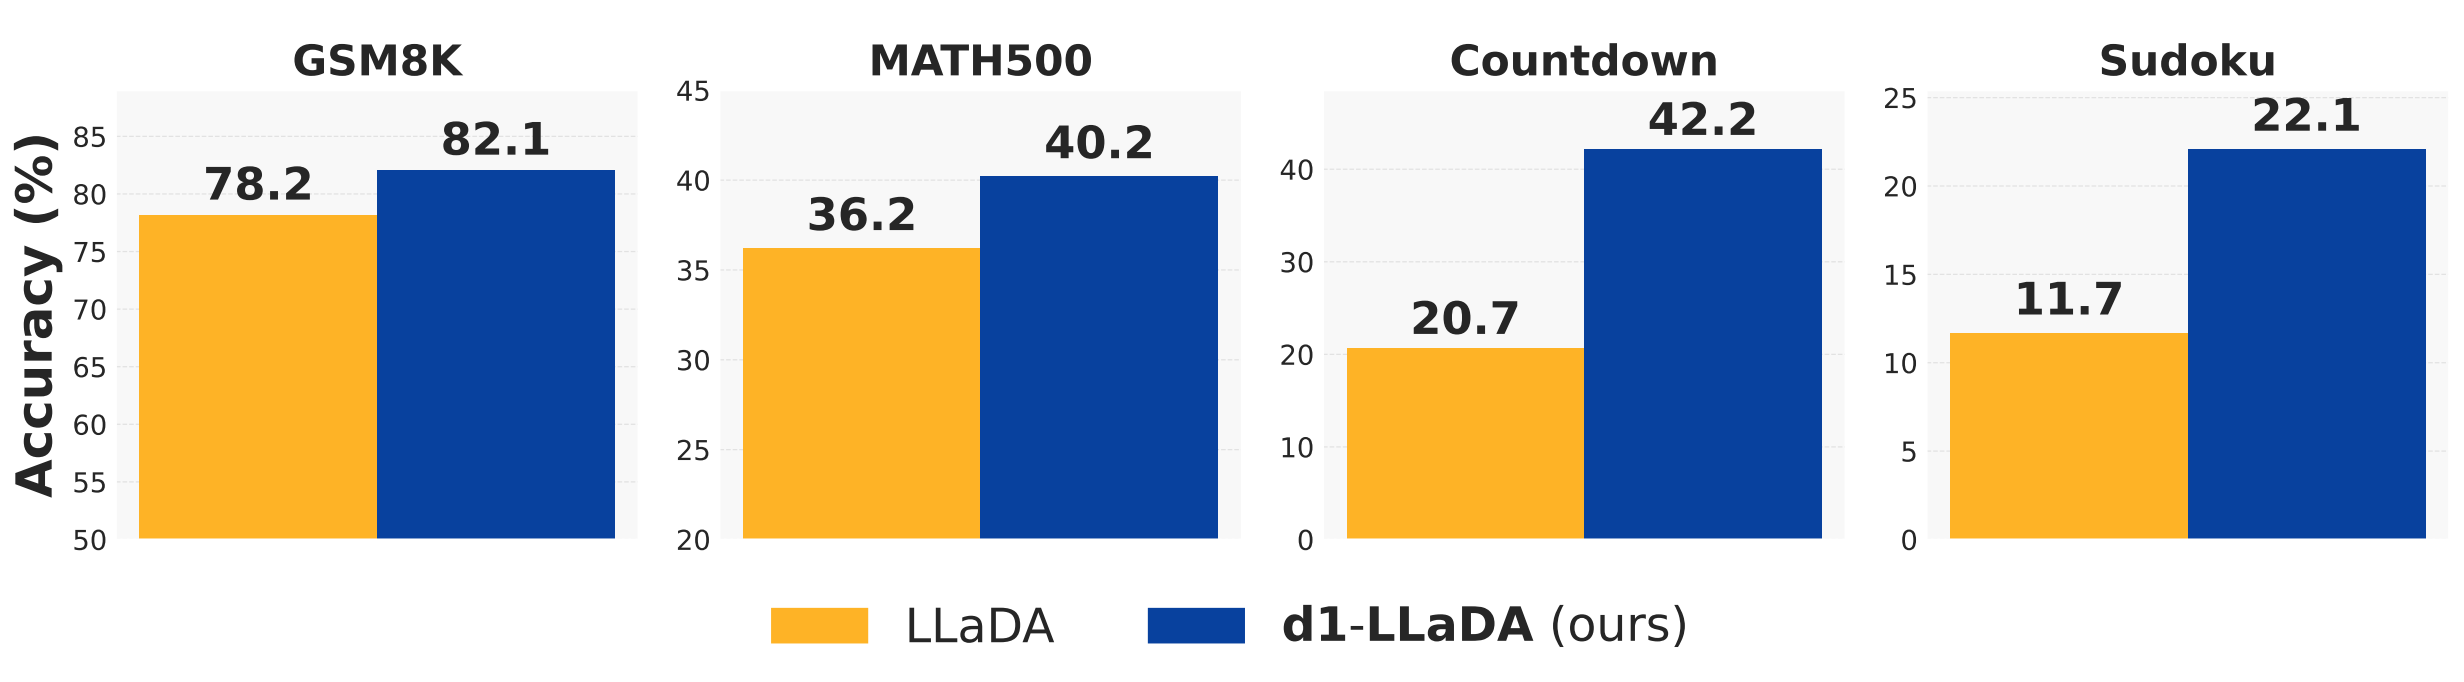
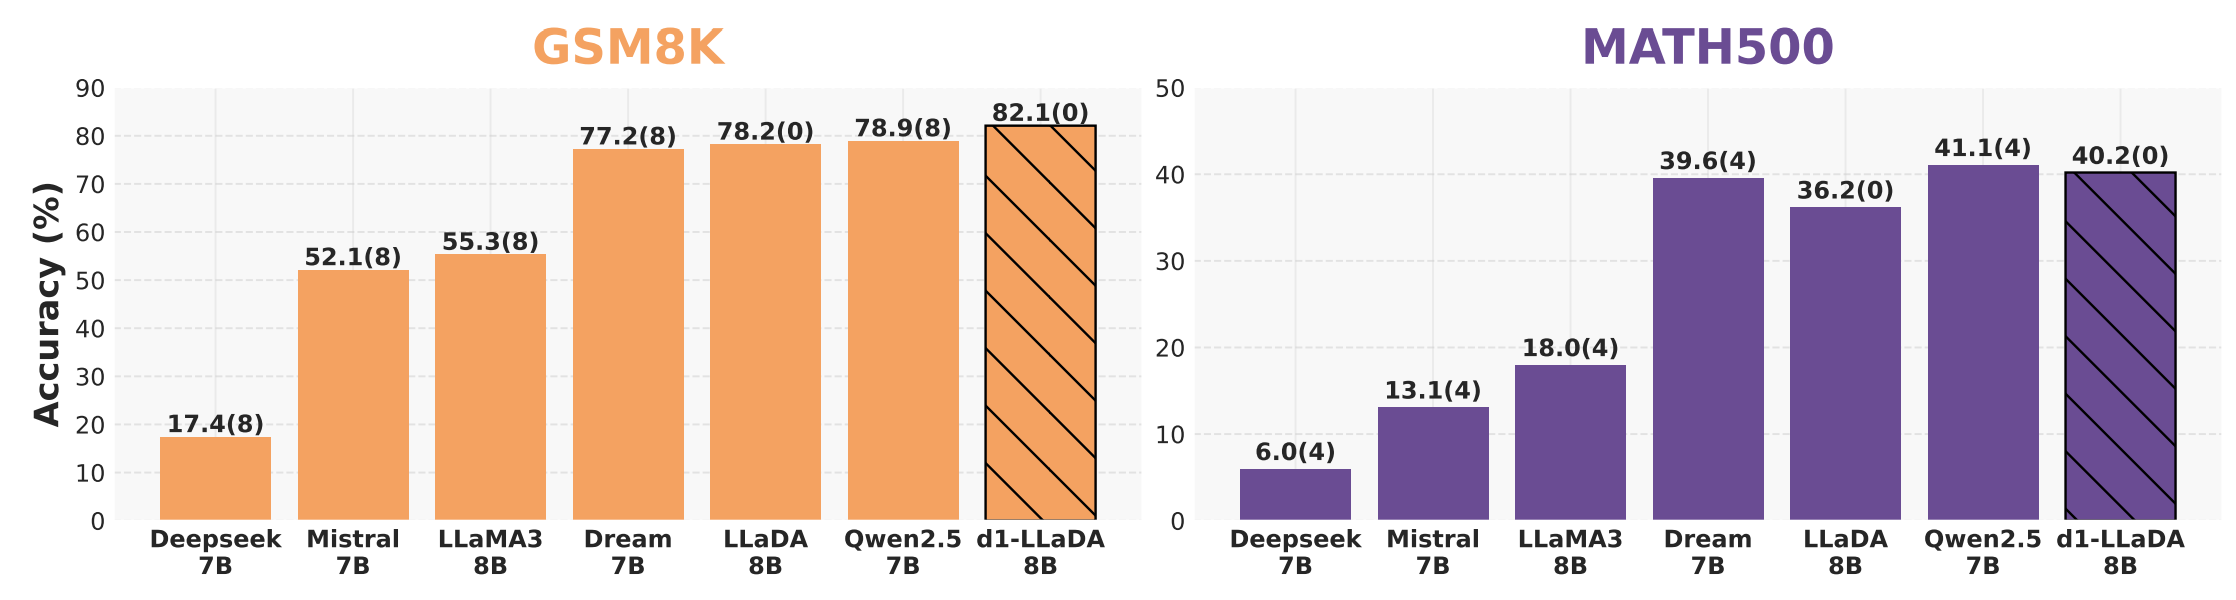
A two-stage approach combining masked SFT with diffu-GRPO—a novel policy gradient method based on GRPO that features efficient log probability estimation designed for masked dLLMs—to scale reasoning capabilities in pre-trained diffusion Large Language Models
🔄Updates:
- 05-04-2025: We released the diffu-GRPO and eval code.
- 04-11-2025: We released our paper and project page. Additionally, the SFT code was open-sourced.
Environment Setup
To setup the environment, run;
conda env create -f env.yml
conda activate d1
SFT
We open-source our code to perform completion-only masked SFT for dLLMs. We implement the algorithm proposed in LLaDA, and also provide it below for completeness.
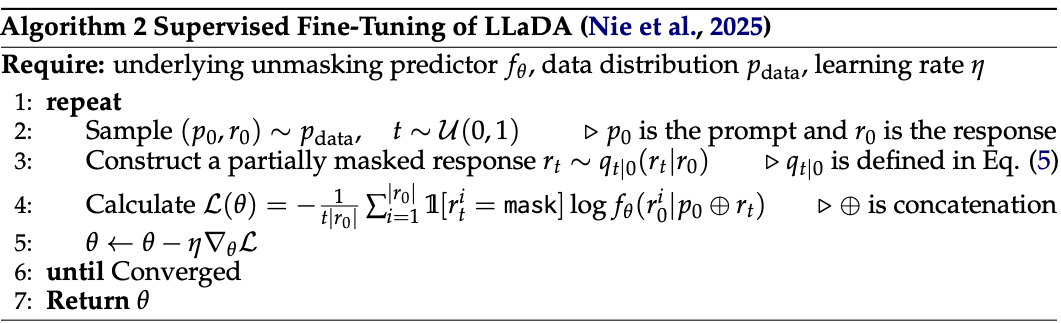
The framework follows a similar interface to 🤗 Transformers. dLLMTrainer subclasses Trainer and overrides the loss computation to implement the diffusion loss. dLLMDataCollator extends DefaultDataCollator by incorporating a forward noising process applied to each training batch. Additionally, we provide a custom torch dataset, dLLMSFTDataset, tailored for completion-only SFT of dLLMs.
To preprocess and tokenize your dataset, you will need to modify preprocess_dataset. Presently, it works with the s1K dataset.
SFT results can be reproduced with the command,
# First go to the SFT directory
cd SFT

CUDA_VISIBLE_DEVICES=0,1 accelerate launch --config_file ddp_config.yaml --main_process_port 29500 --num_processes 2 sft_train.py --grad_accum_steps 4 --batch_size 1 --num_epochs 20
# this results in effective batch size of 8 = 1 * 2 * 4, where 2 is the number of gpus.
diffu-GRPO
The code is inside the diffu-grpo directory.
diffu-grpo/slurm_scriptscontains the slurm scripts we used to run the RL experiments- Example bash script for running the RL experiment:
cd diffu-GRPO

CUDA_VISIBLE_DEVICES=0,1,2,3,4,5,6,7 bash run.sh
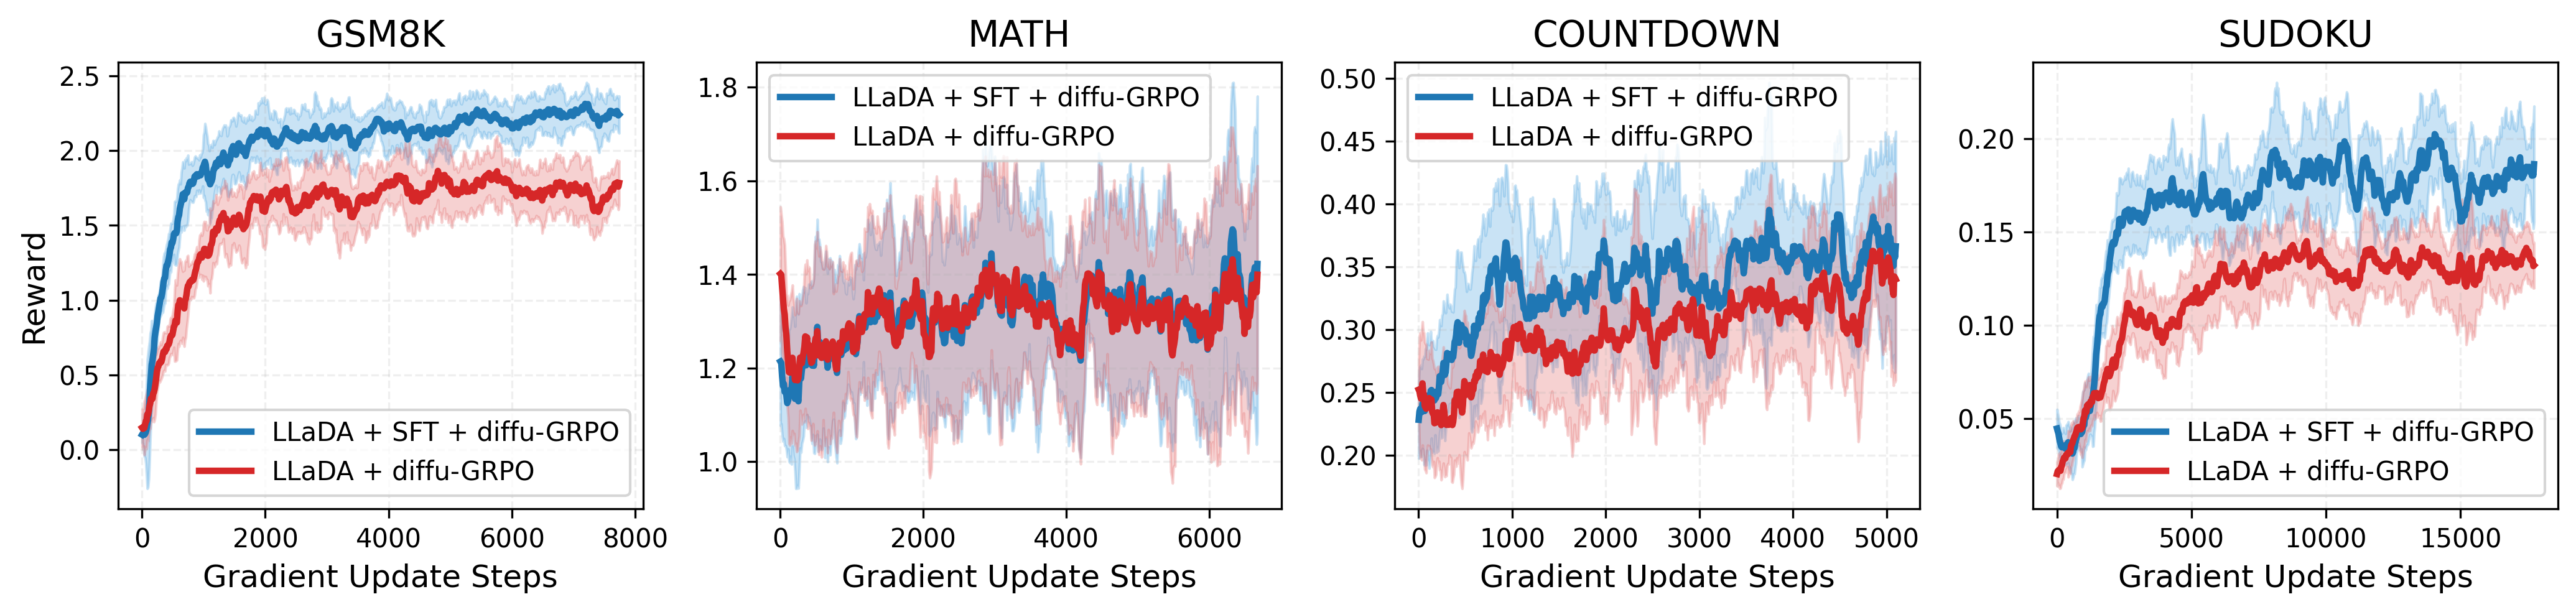
RL training curves across four reasoning tasks, with models initialized from Llada-Instruct (with and without SFT on s1K):
Evaluation
The evaluation code is inside the eval directory.
- Run with
bash run_eval.sh - The evaluation file will only save the generations; use the parser to calculate accuracy
- For example, baseline generations are in the
eval_baselinesdirectory. Usepython parse_and_get_acc.pyto print the accuracy.
Citation
If you find this work useful, please consider citing:
@article{zhao2025d1,
  title={d1: Scaling reasoning in diffusion large language models via reinforcement learning},
  author={Zhao, Siyan and Gupta, Devaansh and Zheng, Qinqing and Grover, Aditya},
  journal={arXiv preprint arXiv:2504.12216},
  year={2025}
}