
dexmal/realtime-vla
dexmal/realtime-vla has 640 GitHub stars and 45 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-16 04:22 UTC. Last push 2026-09-30.
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Running VLA at 30Hz frame rate and 480Hz trajectory frequency
Developer ToolsREADME.md
OriginalRunning VLA in Real Time (Pi0 + Pi05 + DM0)
This project provides accelerated inference kernels of Pi0 and Pi05 models from the OpenPI project.
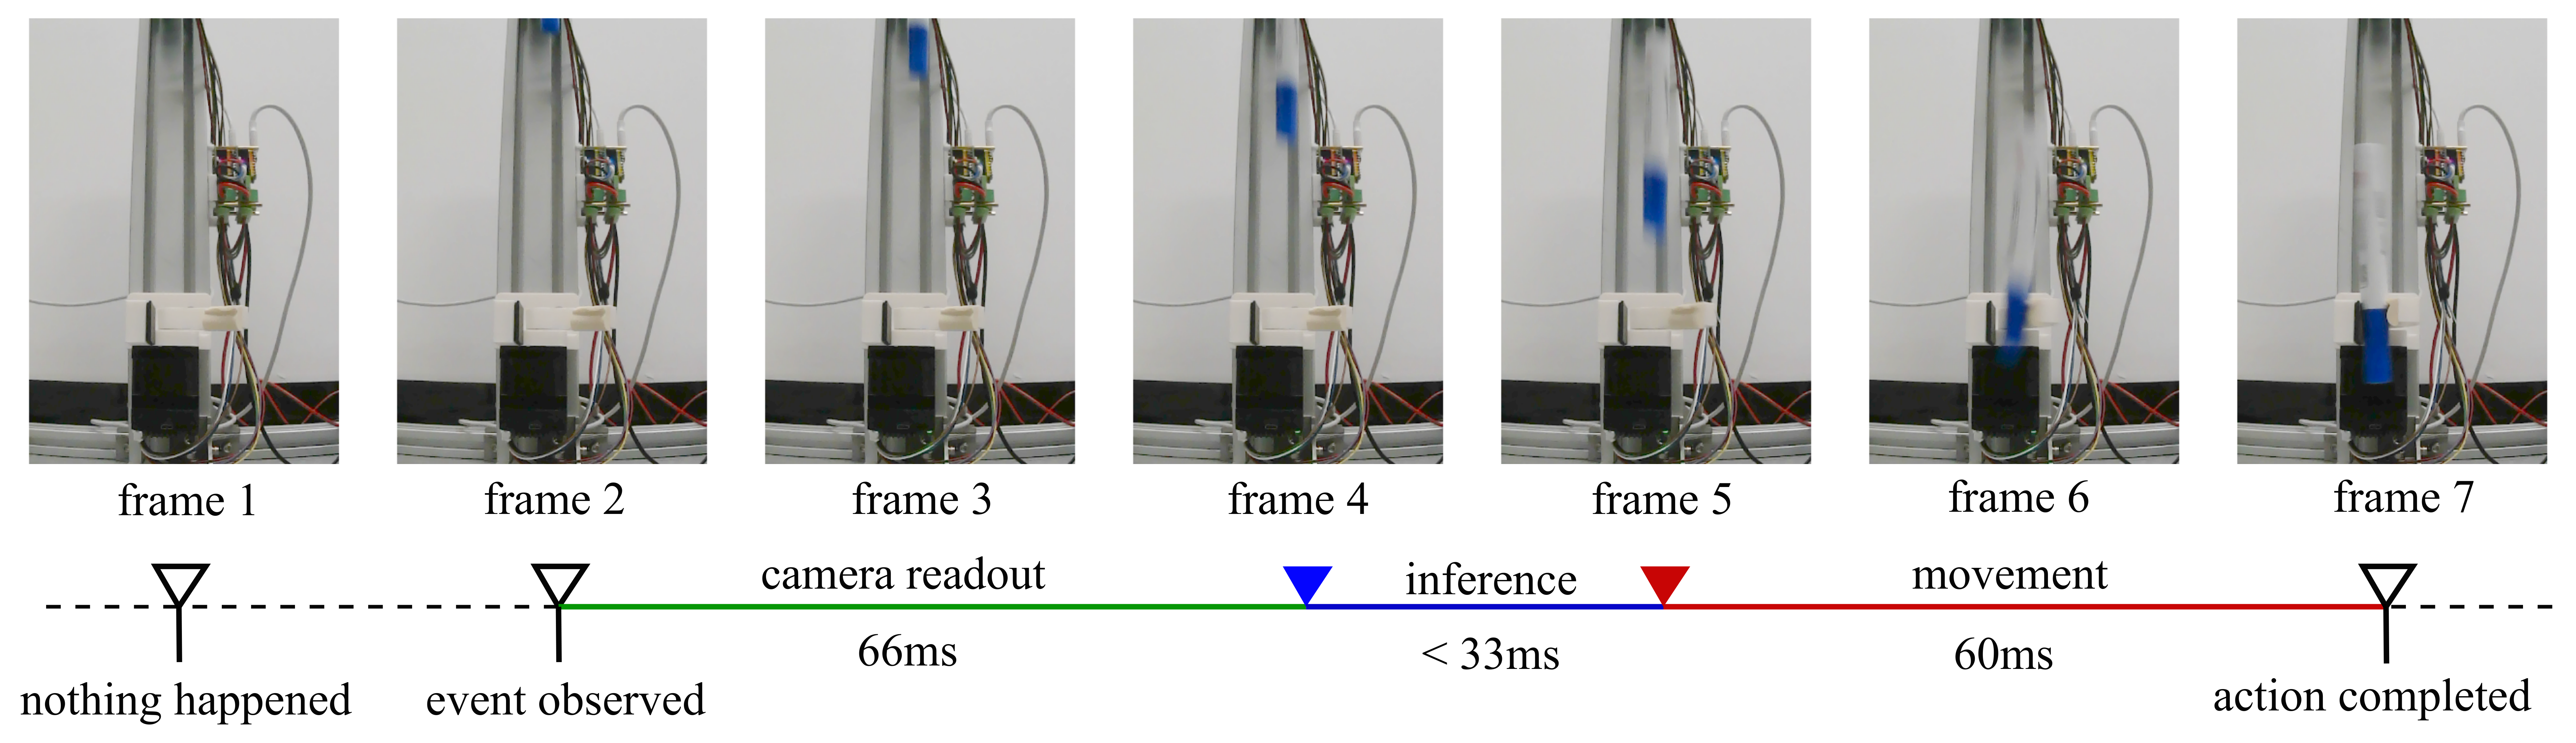 Real-world demonstration: catching a falling pen with sub-200ms end-to-end latency using 30 FPS inference. (From "Running VLAs at Real-time Speed")
Pi0 (Triton) latency on RTX 4090 (max boosted clock 2.79GHz) for one set of observations (10 flow steps, chunk size 63, empty prompt) is as follows:
| 1 view | 2 views | 3 views |
|---|---|---|
| 20.0ms | 27.3ms | 36.8ms |
For more realistic Pi0 settings (prompt length 20 tokens, chunk size 50), we have:
| 1 view | 2 views | 3 views |
|---|---|---|
| 23.6ms | 32.9ms | 39.2ms |
To match camera speeds, you should consider using 30fps for one or two views, and 25fps for three views.
What's NEW!
- [2026/09] 🔥 Further optimized Pi0/Pi05 kernels, weight layouts and execution scheduling, reducing inference latency by about 11–13% for Pi0 and 20% for Pi05, with an AI agent assisting kernel parameter search.
- [2026/02] 🔥 Added DM0 Triton inference:
dm0_infer.py(New high-speed vla model support). - [2026/01] 🔥 Added Pi05 Triton inference:
pi05_infer.py(major upgrade; Pi0 + Pi05 supported). - [2026/01] 🔥 Added
test.pyfor Triton vs JAX correctness/consistency checks, supporting both Pi0 and Pi05 (MAE + per-dimension MAE). - [2026/01] 🔥 Added a benchmark matrix: RTX 4090/5090 × 1/2/3 views × Pi0/Pi05 × Triton.
Benchmark Matrix
| Model / Backend | RTX 4090 (1 view) | RTX 4090 (2 views) | RTX 4090 (3 views) | RTX 5090 (1 view) | RTX 5090 (2 views) | RTX 5090 (3 views) | RTX 5090 optimized 2026/09 (2 views) | RTX 5090 optimized 2026/09 (3 views) |
|---|---|---|---|---|---|---|---|---|
| Pi0 Triton | 20.0ms | 27.3ms | 36.8ms | 17.6ms | 24.0ms | 31.9ms | 21.2ms | 27.7ms |
| Pi05 Triton | 22.1ms | 29.2ms | 38.9ms | 20.1ms | 26.6ms | 34.2ms | 21.3ms | 27.4ms |
| DM0 Triton | 55.8ms |
How to Use
The intended usage is to directly copy the inference file into your project:
pi0_infer.py: Pi0 Triton inferencepi05_infer.py: Pi05 Triton inferencedm0_infer.py: DM0 Triton inference (new)
Pi0 Triton inference
converted_checkpoint = pickle.load(open('converted_checkpoint.pkl', 'rb'))

from pi0_infer import Pi0Inference

infer = Pi0Inference(converted_checkpoint, number_of_images, length_of_trajectory)
output_actions = infer.forward(
   normalized_observation_image_bfloat16, # (number_of_images, 224, 224, 3)
   observation_state_bfloat16, # (32,)
   diffusion_input_noise_bfloat16, # (length_of_trajectory, 32)
)
Pi05 Triton inference
converted_checkpoint = pickle.load(open('converted_checkpoint.pkl', 'rb'))

from pi05_infer import Pi05Inference

infer = Pi05Inference(
  checkpoint=converted_checkpoint,
  num_views=number_of_images,
  chunk_size=length_of_trajectory,
  tokenizer_path="/path/to/paligemma-3b-pt-224",
  # discrete_state_input=True is recommended (and matches `test.py`)
  discrete_state_input=True,
)
output_actions = infer.forward(
   normalized_observation_image_bfloat16, # (number_of_images, 224, 224, 3)
   diffusion_input_noise_bfloat16, # (length_of_trajectory, 32)
   task_prompt, # str
   state_tokens, # np.ndarray (discrete tokens if discrete_state_input=True)
)
DM0 Triton inference (new)
converted_checkpoint = torch.load('converted_checkpoint.pt', map_location=device, weights_only=True)

from dm0_infer import DM0Inference

infer = DM0Inference(
  checkpoint=converted_checkpoint,
  num_images=number_of_images,
)
output_actions = infer.forward(
   images, # (number_of_images, 3, 728, 728)
   input_ids, # (length_of_language,)
   diffusion_input_noise_bfloat16, # (length_of_trajectory, 32)
)
Convert from JAX checkpoint
pytho3 convert_from_jax.py \
   --jax_path /path/to/checkpoint/folder\
   --output converted_checkpoint.pkl\
   --prompt "your task prompt"\
   --tokenizer_path /path/to/paligemma-3b-pt-224
python3 convert_from_jax_pi05.py \
   --jax_path /path/to/checkpoint/folder\
   --output converted_checkpoint.pkl\
   --prompt "your task prompt"\
   --tokenizer_path /path/to/paligemma-3b-pt-224
python3 convert_dm0_weight.py \
   --model_path /path/to/checkpoint/folder\
   --output converted_checkpoint.pt
The code is specifically tuned on RTX 4090, CUDA 12.6, but it should work on similar platforms so long as torch and triton themselves work.
Checking Performance
You can check the inference time on you local machine by
python3 benchmark.py --num_views 3 --prompt_len 0 --chunk_size 50 --model_version dm0
Correctness / Consistency Testing (Pi0 & Pi05)
We provide test.py to compare Triton vs JAX outputs for both Pi0 and Pi05 (simple MAE report per-dimension).
Example (Pi05):
python3 test.py \
  --model_version pi05 \
  --triton_path converted_checkpoint.pkl \
  --jax_path /path/to/jax/checkpoint/folder \
  --norm_stats_dir /path/to/norm_stats_dir \
  --config_name <openpi_config_name> \
  --prompt "your task prompt" \
  --tokenizer_path /path/to/paligemma-3b-pt-224 \
  --discrete_state_input
Example (Pi0):
python3 test.py \
  --model_version pi0 \
  --triton_path converted_checkpoint.pkl \
  --jax_path /path/to/jax/checkpoint/folder \
  --norm_stats_dir /path/to/norm_stats_dir \
  --config_name <openpi_config_name>
Structure of the Code
The implementation is organized into three main components: a vision encoder, an LLM, and an action expert. Each component is decomposed into fundamental operations, with the entire computation graph simplified to 24 GEMM-like operations and associated scalar operators. This modular structure allows for efficient Triton kernel optimization at each computational stage.
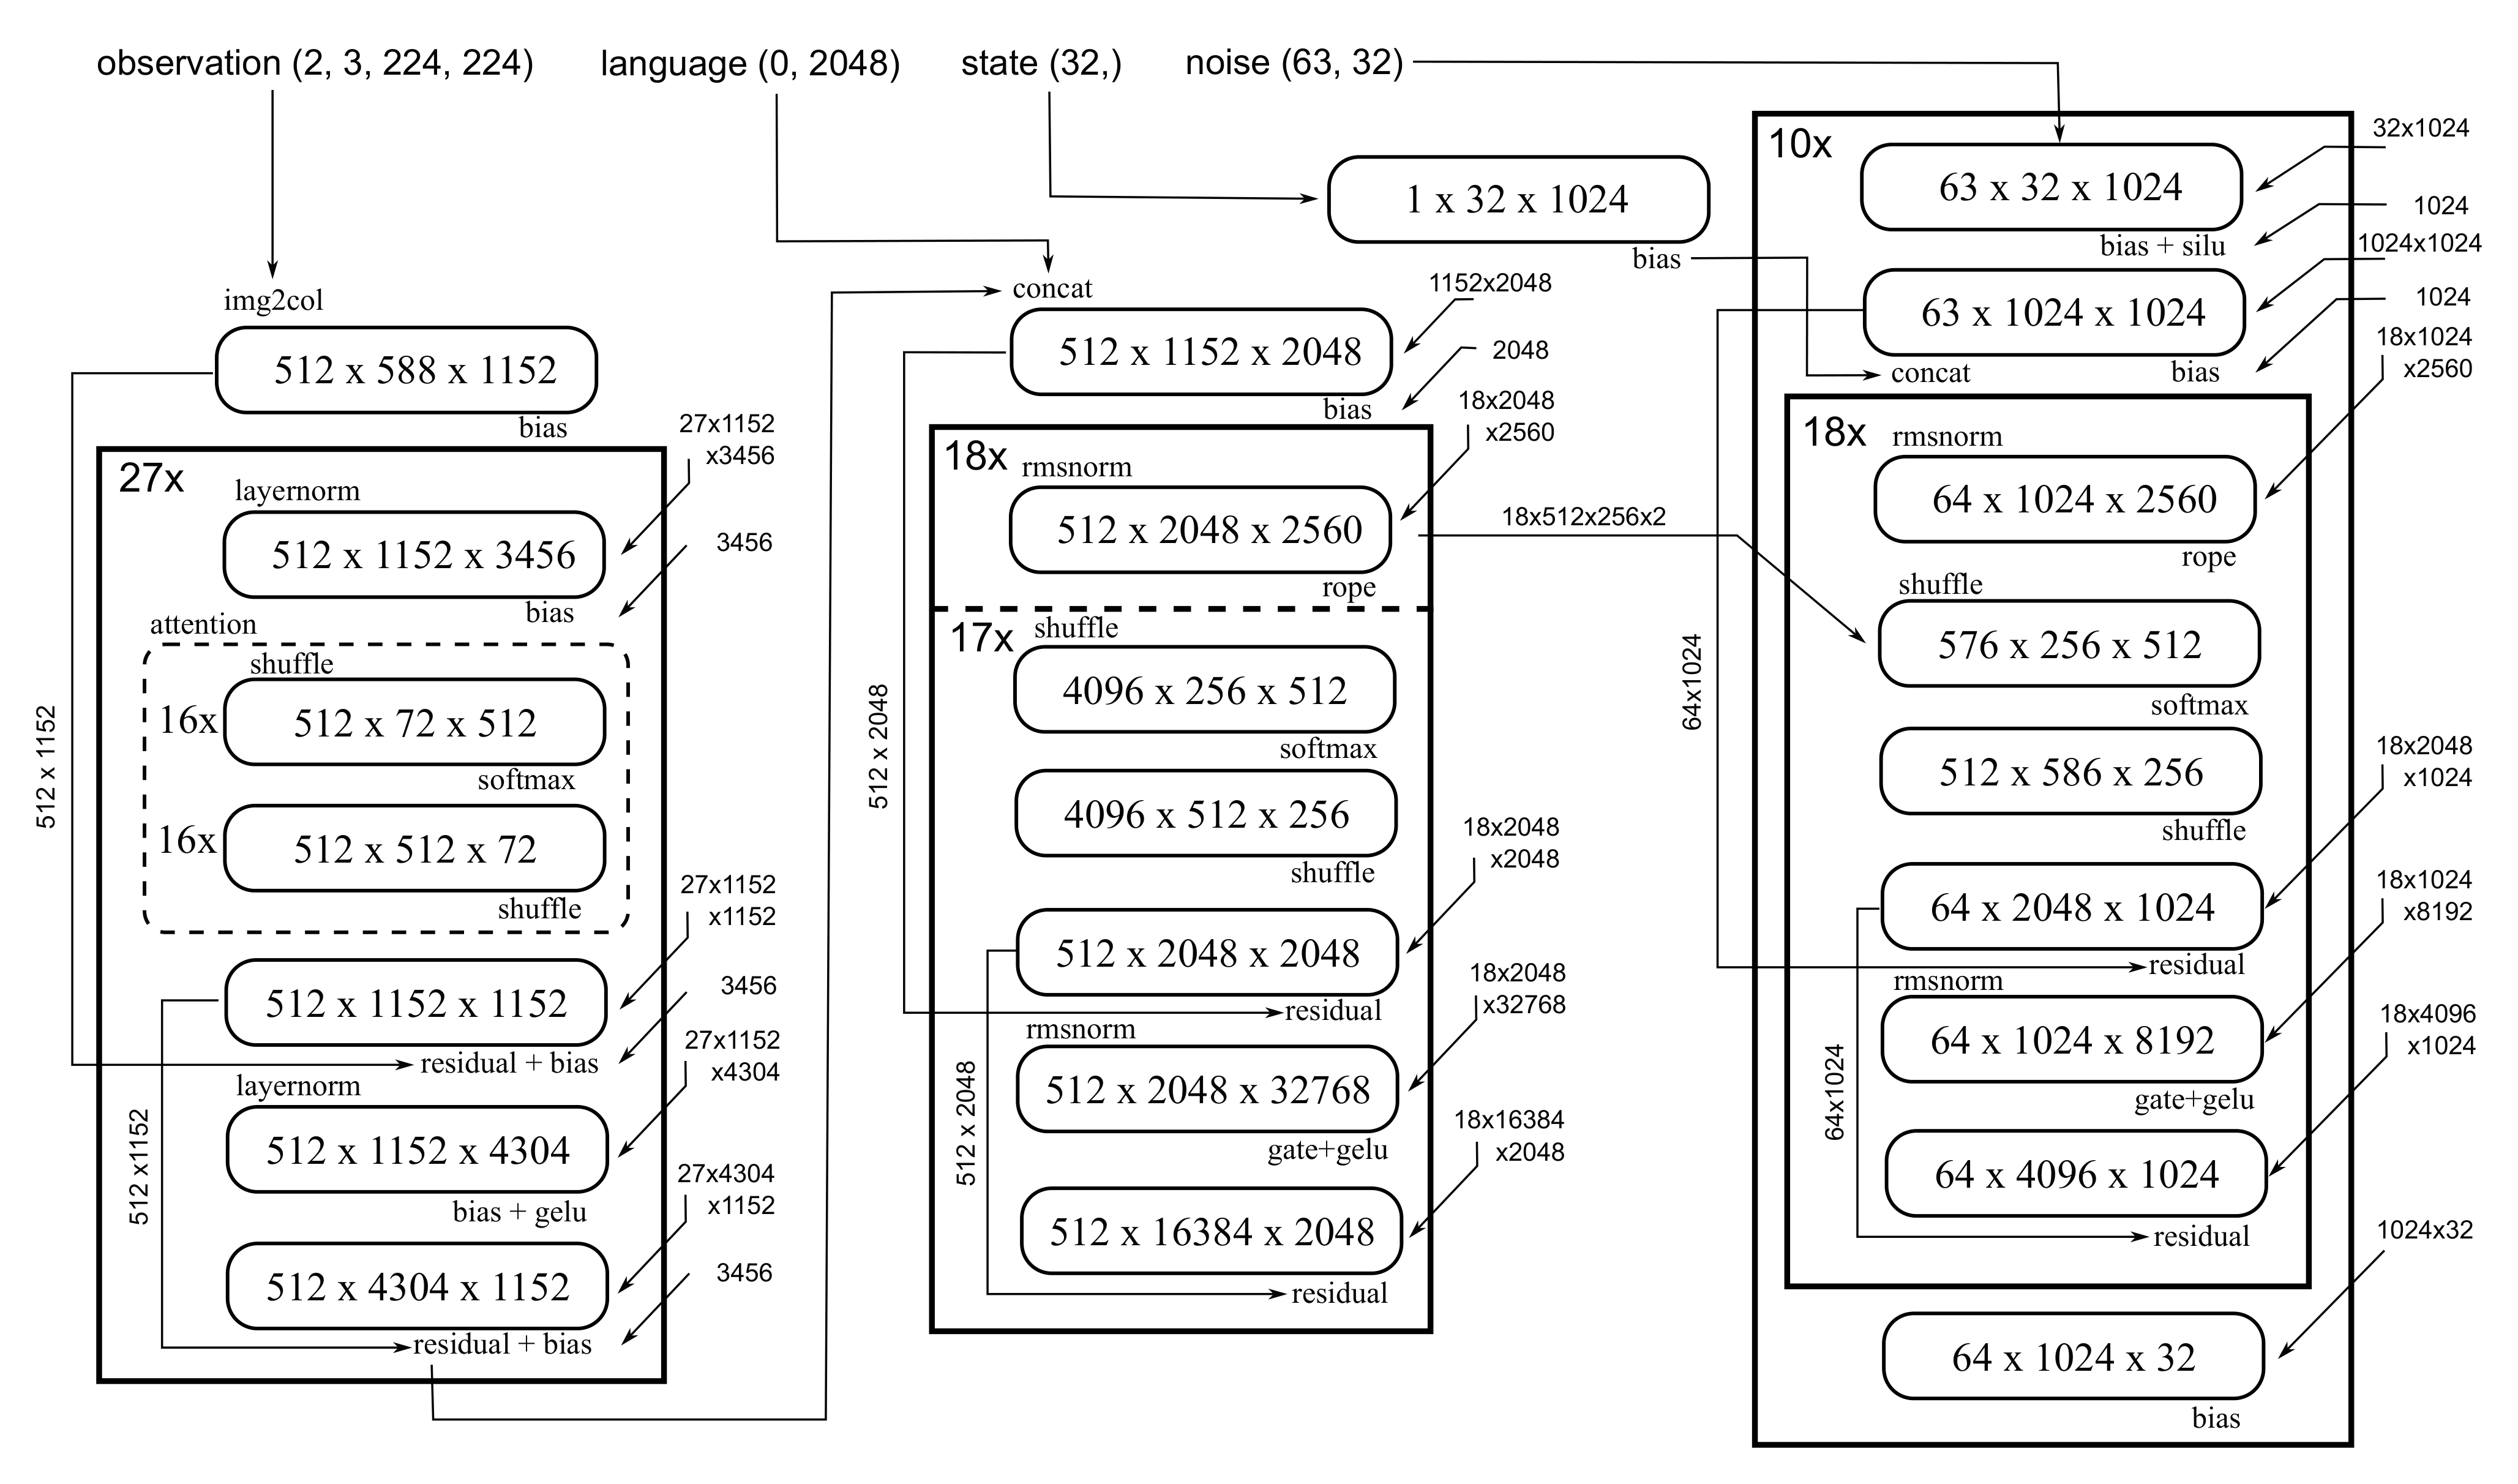 Simplified computation graph showing the 24 GEMM-like operations that constitute the core of the inference pipeline.
Acknowledgements
This project is developed based on Physical Intelligence's OpenPI project.
Citation
If you want, you can cite this work with:
@article{ma2025runningvlasrealtimespeed,
  title={Running VLAs at Real-time Speed},
  author={Ma, Yunchao and Zhou, Yizhuang and Yang, Yunhuan and Wang, Tiancai and Fan, Haoqiang},
  journal={arXiv preprint arXiv:2510.26742},
  year={2025}
}