
dcarrero/awesome-code-review-prompts
dcarrero/awesome-code-review-prompts has 32 GitHub stars and 3 forks. GitHot measured +1 stars in 24 hours. Last checked 2026-11-17 02:10 UTC. Last push 2026-07-16.
Measured star growth
- in 24h
- +1
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Master prompts to make Claude (and other AI models) review code for security, performance, accessibility, usability and quality — language-agnostic, with add-ons for 18+ stacks. Bilingual EN/ES.
SecurityREADME.md
Original🧠 Awesome Code Review Prompts


A curated, battle-tested collection of master prompts for asking an AI assistant (built for Claude Fable 5 and compatible with any frontier model — GPT-5.6 / GPT-5.x, Gemini, Grok, and more) to review your code across the dimensions that actually matter: security, cybersecurity, performance, accessibility, usability/UX, testing, AI/LLM safety, and code quality.
Language-agnostic master prompts + 30 stack-specific add-ons (14 languages, 16 frameworks) — every prompt in English and Spanish.
🌍 Español: README-ES.md — every prompt has a Spanish twin ending in -ES.md.
📖 How to use it well: docs/how-to-use.md
🗒️ Changelog: CHANGELOG.md · 🧭 Roadmap: ROADMAP.md
✍️ Author: David Carrero Fernández-Baillo — carrero.es · github.com/dcarrero
📦 Repository: https://github.com/dcarrero/awesome-code-review-prompts
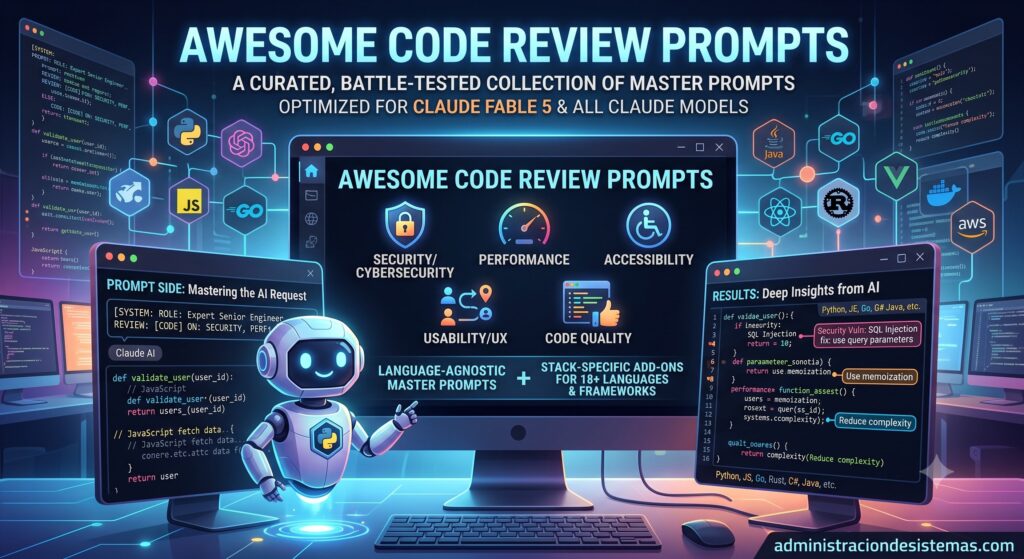
📝 Featured guide: Code and Infrastructure Review, With and Without AI: A Practical Guide for System Administrators and Developers — the companion article that explains the why and how behind this collection.
Why this exists
AI reviewers are only as good as the prompt you give them. "Review my code" produces vague, shallow feedback. A well-structured prompt that assigns a role, defines scope, sets a method, and fixes the output format turns the same model into a focused senior reviewer that finds real issues and hands you copy-ready fixes.
This repo gives you those prompts, ready to paste, for any project and any language.
How to use
- Pick a dimension from
prompts/general/(e.g., security, performance). - Paste the master prompt into your Claude conversation.
- Add your code: paste a
git difffor a fast PR gate, or a file/folder for a deep audit. - (Optional) Stack it: append the matching add-on from
prompts/languages/orprompts/frameworks/to get language-specific checks on top of the general review. - Ship with confidence using the prioritized fix list the prompt produces.
👉 For patterns, examples, and workflows (PR gate, CI, learning), read
docs/how-to-use.md.
💡 Every master prompt ends by asking the model to request up to 3 clarifying questions before reviewing — so it gathers context instead of guessing.
🤖 Model compatibility
Every prompt here is plain text — nothing is hard-wired to one vendor. The collection is authored and tuned against Claude Fable 5 (the recommended default), and the same prompts work with any other frontier model that can follow a structured instruction set.
| Model | How to use it |
|---|---|
| Claude Fable 5 — recommended | The default these prompts are tuned for. Paste the text block, then your diff. |
| Claude Opus 4.x / Sonnet | Same Claude family; drop-in. |
| OpenAI GPT-5.6 (and the GPT-5.x family) | Drop-in; paste the same text block. |
| Google Gemini | Drop-in; give explicit scope on large diffs. |
| xAI Grok · DeepSeek · other frontier models | Work with the same prompts; keep the clarifying-questions step. |
💡 The prompts don't depend on any model-specific feature. If a model reliably respects the Output contract and asks the clarifying questions, you'll get comparable results.
Language convention
Every file is English by default (name.md) with a Spanish counterpart
(name-ES.md). E.g. security.md ·
security-ES.md.
📑 Index — general master prompts
| Dimension | English | Español | What it catches |
|---|---|---|---|
| 🔒 Application Security | security.md | security-ES.md | Injection, XSS, broken auth/access control, crypto, OWASP Top 10, CWE |
| 🛡️ Cybersecurity & Infra | cybersecurity.md | cybersecurity-ES.md | Secrets, dependency CVEs, containers, IaC, CI/CD, supply chain, threat model |
| ⚡ Performance | performance.md | performance-ES.md | Complexity, N+1, concurrency, memory, caching, payloads, scalability |
| ♿ Accessibility | accessibility.md | accessibility-ES.md | WCAG 2.2 AA: semantics, keyboard, ARIA, contrast, forms, motion |
| 🎯 Usability / UX | usability-ux.md | usability-ux-ES.md | Clarity, flows, feedback/state, error recovery, microcopy, consistency |
| 🧹 Code Quality | code-quality.md | code-quality-ES.md | Correctness, design, tests, readability, maintainability |
| 🧪 Testing & Test Quality | testing.md | testing-ES.md | Behavior coverage, assertion strength, flakiness, over-mocking, missing regression tests |
| 🤖 AI / LLM Code Safety | ai-llm-safety.md | ai-llm-safety-ES.md | Prompt injection, insecure output handling, excessive agency, RAG access control, data leakage (OWASP LLM Top 10) |
| 🧭 All-in-One | all-in-one.md | all-in-one-ES.md | Runs every dimension and produces a single scored release report |
📑 Index — language add-ons
Append one of these after a general master prompt for deeper, idiomatic checks.
| Language | English | Español |
|---|---|---|
| JavaScript / TypeScript | javascript-typescript.md | ·-ES.md |
| Python | python.md | ·-ES.md |
| Ruby | ruby.md | ·-ES.md |
| PHP (modern, framework-agnostic) | php-modern.md | ·-ES.md |
| PHP / WordPress | php-wordpress.md | ·-ES.md |
| Java | java.md | ·-ES.md |
| Go | go.md | ·-ES.md |
| C# / .NET | csharp-dotnet.md | ·-ES.md |
| Swift / iOS | swift-ios.md | ·-ES.md |
| Kotlin / Android | kotlin-android.md | ·-ES.md |
| Rust | rust.md | ·-ES.md |
| C / C++ | c-cpp.md | ·-ES.md |
| PowerShell | powershell.md | ·-ES.md |
| SQL / Databases | sql.md | ·-ES.md |
📑 Index — framework & DevOps add-ons
| Stack | English | Español |
|---|---|---|
| React / Next.js | react-nextjs.md | ·-ES.md |
| Vue / Nuxt | vue-nuxt.md | ·-ES.md |
| Angular | angular.md | ·-ES.md |
| Laravel (PHP) | laravel.md | ·-ES.md |
| Symfony (PHP) | symfony.md | ·-ES.md |
| FlightPHP (PHP micro) | flightphp.md | ·-ES.md |
| Ruby on Rails | rails.md | ·-ES.md |
| Django (Python) | django.md | ·-ES.md |
| FastAPI (Python) | fastapi.md | ·-ES.md |
| Spring Boot (Java) | spring-boot.md | ·-ES.md |
| Node.js / Express | nodejs.md | ·-ES.md |
| NestJS | nestjs.md | ·-ES.md |
| Cloudflare Workers | cloudflare-workers.md | ·-ES.md |
| Docker / Kubernetes | docker-kubernetes.md | ·-ES.md |
| Terraform / IaC | terraform.md | ·-ES.md |
| Bash / Shell | bash.md | ·-ES.md |
Recommended combos
- Web app PR gate →
all-in-one+react-nextjs(+nodejsfor the backend). - API/backend hardening →
security+cybersecurity+ your language file. - Laravel / Symfony app →
all-in-one+php-modern+laravel(orsymfony). - Infra change →
cybersecurity+docker-kubernetes/terraform. - Public UI release →
accessibility+usability-ux+react-nextjs. - Legacy cleanup →
code-quality+performance+ your language file.
What makes these prompts effective
Every prompt follows the same proven structure:
- Role — casts the model as a senior specialist, raising the quality bar.
- Scope — an explicit checklist so nothing important is skipped.
- Method — how to reason (trace sources→sinks, prioritize by impact, avoid false positives).
- Output contract — a fixed format (severity, exact location, impact, copy-ready fix, verdict).
- Clarifying questions — the model asks for missing context before judging.
Contributing
New languages, frameworks, and dimension improvements are welcome. See
CONTRIBUTING.md. Please ship every prompt as a pair:
name.md (English) and name-ES.md (Spanish).
License & author
MIT — use, adapt, and share freely.
Created and maintained by David Carrero Fernández-Baillo 🌐 carrero.es · 🐙 github.com/dcarrero
© 2026 David Carrero Fernández-Baillo. If you find this useful, a ⭐ on the repository is appreciated.