
datascale-ai/data_engineering_book
datascale-ai/data_engineering_book has 1,386 GitHub stars and 138 forks. GitHot measured +2 stars in 24 hours. Last checked 2026-11-06 08:43 UTC. Last push 2026-09-09.
大模型数据工程:架构、算法及项目实战
Measured star growth
- in 24h
- +2
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README_en.md
OriginalData Engineering for Large Foundation Models
A Handbook

Version note: The Chinese edition is the current 2026 Springer mainline, frozen at 14 parts, 48 chapters, 15 project case studies, and 8 appendices (A–H), with front matter and an afterword in the site edition. The English edition is being synchronized with a quality-first translation workflow; the documentation site includes an English edition status page.
Introduction
"Data is the new oil, but only if you know how to refine it."
In the era of large models, data quality determines the upper bound of model performance. Yet systematic resources on LLM data engineering remain extremely scarce — most teams are still learning by trial and error.
This book is designed to fill that gap. We systematically cover the complete technical stack from pre-training data cleaning to multimodal alignment, from RAG retrieval augmentation to synthetic data generation, all the way through DataOps platform engineering and privacy-compliant data governance, including:
- 🧹 Pre-training Data Engineering: Extracting high-quality corpora from massive noisy data sources like Common Crawl
- 🖼️ Multimodal Data Processing: Collection, cleaning, and alignment of image-text pairs, video, and audio data
- 🎯 Alignment Data Construction: Automated generation of SFT instruction data, RLHF preference data, and CoT reasoning data
- 🤖 Reasoning & Agent Data: Chain-of-thought, Tool-Use, multi-turn interaction, and memory data engineering
- 🔍 RAG Data Pipeline: Enterprise-grade document parsing, semantic chunking, and multimodal retrieval
- ⚙️ DataOps & Platform Engineering: Team organization, data versioning, and platform observability
- 🔒 Privacy, Compliance & Security: Data governance frameworks, federated learning, and privacy-enhancing technologies
Beyond in-depth theoretical explanations, the Chinese mainline includes 15 end-to-end hands-on project case studies with runnable code where available, architecture designs, and engineering retrospectives for hands-on learning.
Read Online: https://datascale-ai.github.io/data_engineering_book/en/
Book Architecture
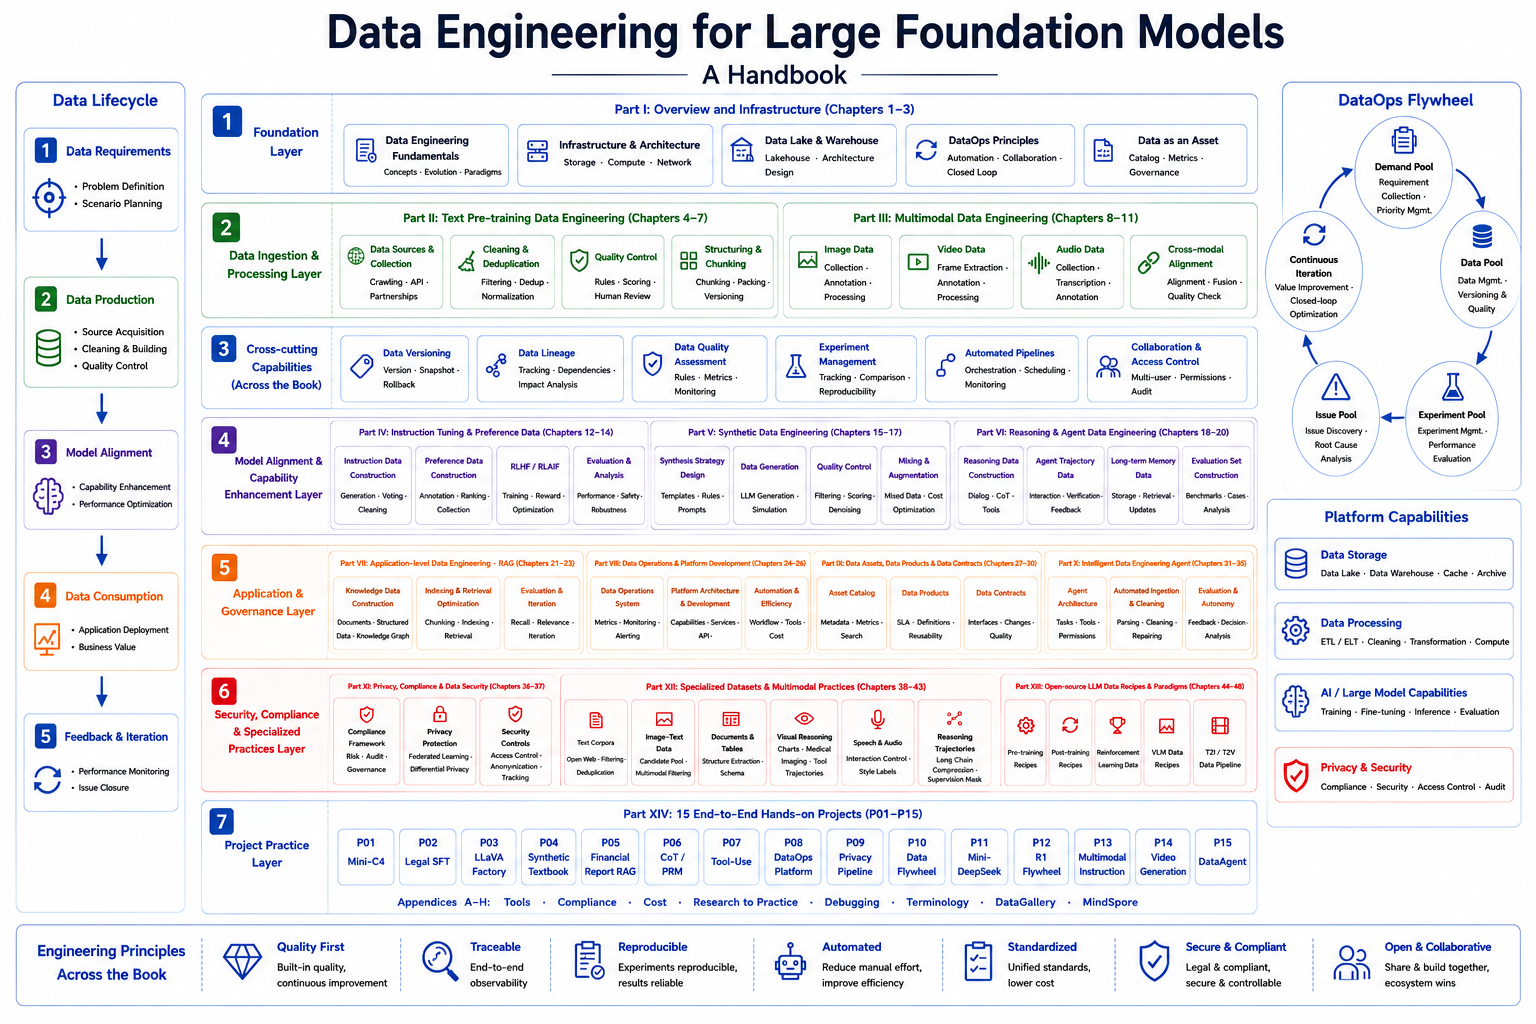
A complete data engineering pipeline from raw data to end-to-end applications
Table of Contents
📖 14 Parts, 48 Chapters + 15 Project Case Studies + 8 Appendices (A–H)
│
├── Part 1: Overview & Infrastructure (Ch01-Ch03)
├── Part 2: Text Pre-training Data Engineering (Ch04-Ch07)
├── Part 3: Multimodal Data Engineering (Ch08-Ch11)
├── Part 4: Instruction Fine-tuning & Preference Data (Ch12-Ch14)
├── Part 5: Synthetic Data Engineering (Ch15-Ch17)
├── Part 6: Reasoning & Agent Data Engineering (Ch18-Ch20)
├── Part 7: Application-Level Data Engineering (Ch21-Ch23)
├── Part 8: DataOps & Platform Engineering (Ch24-Ch26)
├── Part 9: Data Assets, Data Products & Data Contracts (Ch27-Ch30)
├── Part 10: Agentic Data Engineering (Ch31-Ch35)
├── Part 11: Privacy, Compliance & Data Security (Ch36-Ch37)
├── Part 12: Specialized Datasets and Multimodal Data Engineering Practice (Ch38-Ch43)
├── Part 13: Open-source Model Data Recipes (Ch44-Ch48)
└── Part 14: Project Case Studies (P01-P15)
Key Highlights
Comprehensive Theory
- Data-Centric AI philosophy throughout
- Covers the full LLM data lifecycle: Pre-training → Fine-tuning → RLHF → RAG → DataOps
- In-depth coverage of Scaling Laws, data quality evaluation, multimodal alignment, privacy compliance, and more
Modern Tech Stack
| Domain | Technologies |
|---|---|
| Distributed Computing | Ray Data, Spark, Dask |
| Data Storage | Parquet, WebDataset, Vector Databases (Milvus/Qdrant) |
| Text Processing | Trafilatura, KenLM, MinHash LSH, fastText Quality Scoring |
| Multimodal | CLIP, ColPali, img2dataset |
| Data Versioning | DVC, LakeFS, MLflow |
| Platform Observability | Great Expectations, Evidently AI, Apache Airflow |
| Privacy & Security | Federated Learning, Differential Privacy, Secure MPC |
Rich Capstone Projects
| Project | Core Technologies | Output |
|---|---|---|
| Mini-C4 Pre-training Set | Trafilatura + Ray + MinHash | High-quality text corpus |
| Legal Expert SFT | Self-Instruct + CoT | Domain instruction dataset |
| LLaVA Multimodal Instruction | Bbox alignment + multi-image interleaving | Visual instruction dataset |
| Synthetic Math Textbook | Evol-Instruct + sandbox verification | PoT reasoning dataset |
| Financial Report RAG | ColPali + Qwen-VL | Multimodal QA system |
| CoT Reasoning + PRM | Process Reward Modeling | Reasoning process dataset |
| Agent Tool-Use Factory | Tool-call chains + trajectory annotation | Agent training dataset |
| DataOps Platform | Airflow + DVC + quality monitoring | Enterprise data ops system |
| Privacy Pipeline | Federated Learning + Differential Privacy | Compliant training pipeline |
| LLM Data Flywheel | Online feedback + continuous iteration | End-to-end closed-loop system |
| Mini-DeepSeek Reproduction | Multi-source mixing + deduplication + tokenizer | Open-source pre-training data recipe |
| R1 Reasoning Flywheel | Multi-sampling + verifier + rejection sampling | Reasoning data loop |
| Multimodal Instruction Factory | VLM generation + judge filtering + multilingual expansion | Multimodal SFT dataset |
| Video Generation Dataset | Shot detection + motion filtering + multi-frame captioning | T2V training data pipeline |
| DataAgent Semantic NL2SQL Assistant | Semantic layer + Text-to-SQL + permission audit | Enterprise query-agent case study |
Local Development
Requirements
- Python 3.8+
- MkDocs Material
- mkdocs-static-i18n (i18n support)
Install & Preview
# Clone the repository
git clone https://github.com/datascale-ai/data_engineering_book.git
cd data_engineering_book

# Install dependencies
pip install mkdocs-material mkdocs-glightbox pymdown-extensions "mkdocs-static-i18n[material]"

# Local preview
mkdocs serve
Visit http://127.0.0.1:8000 to preview the book (with Chinese/English/Japanese language switcher).
Build Static Site
mkdocs build
The generated static files are located in the site/ directory.
Project Structure
data_engineering_book/
├── docs/
│   ├── zh/                    # Chinese content
│   │   ├── index.md           # Chinese homepage
│   │   └── part1/ ~ part14/   # Chinese Springer mainline chapters
│   ├── en/                    # English content
│   ├── ja/                    # Japanese content
│   ├── images/                # Image assets (shared)
│   ├── stylesheets/           # Custom styles
│   └── javascripts/           # JavaScript (MathJax etc.)
├── .github/workflows/         # GitHub Actions CI/CD
├── images/                    # Project image assets
├── mkdocs.yml                 # MkDocs configuration
├── LICENSE                    # License
├── README.md                  # 中文说明
├── README_en.md               # English README (this file)
└── README_ja.md               # 日本語 README
Target Audience
- LLM R&D Engineers
- Data Engineers / MLOps / DataOps Engineers
- AI Product Managers (Technical)
- Researchers interested in LLM data pipelines
Laboratory Information:
National Engineering Laboratory for Speech and Language Information Processing, University of Science and Technology of China;
Multimedia Computing and Intelligent Robotics Research Center, Department of Automation, University of Science and Technology of China;
Joint Research Center for Multi-Modal Intelligent Agents, Department of Automation, University of Science and Technology of China
Contributing
Contributions are welcome! Feel free to submit Issues and Pull Requests.
- Fork this repository
- Create a feature branch (
git checkout -b feature/AmazingFeature) - Commit your changes (
git commit -m 'Add some AmazingFeature') - Push to the branch (
git push origin feature/AmazingFeature) - Open a Pull Request
License
This project is licensed under the MIT License - see the LICENSE file for details.
Contact
- GitHub Issues: Submit an issue
- Read Online: https://datascale-ai.github.io/data_engineering_book/en/
If you find this book helpful, please give it a Star! ⭐
Explore related projects
codecrafters-io/build-your-own-x
Master programming by recreating your favorite technologies from scratch.
560,520 starspublic-apis/public-apis
A collective list of free APIs
496,809 starsmorluto/rea
Reverse engineer anything with agents, from app behavior down to native binaries.
438,740 starsopenclaw/openclaw
The AI that really does things. Any OS. Any Platform. The lobster way. 🦞
394,093 stars