
cxcscmu/IdeaTaste
cxcscmu/IdeaTaste has 32 GitHub stars and 3 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-12 13:58 UTC. Last push 2026-11-03.
IdeaTaste - A benchmark for research taste: let LLM agents propose research ideas, then check how many of them the research area actually went on to do.
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalIdeaTaste


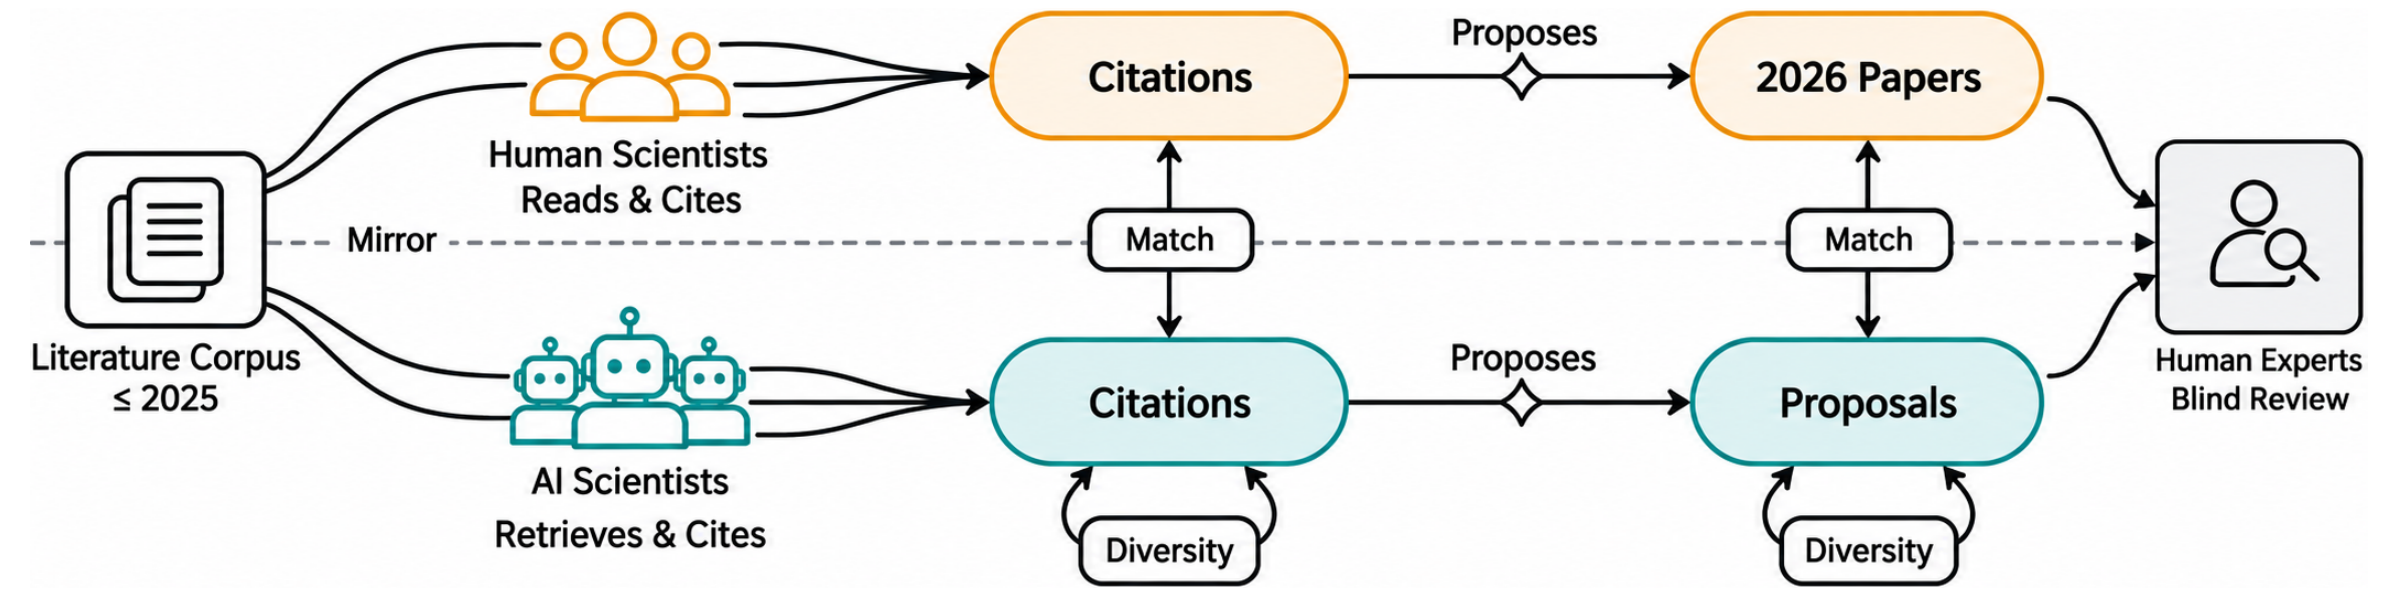
IdeaTaste is a benchmark for research taste. LLM agents read a literature corpus frozen at 2025 and write research proposals; those proposals are then scored against the papers the same communities published in 2026. Proposals and papers are compared both on the literature they cite and on the ideas they state, giving four metrics: citation matching, idea matching, citation diversity and idea diversity.
Install
pip install -e ".[dev]"
python -m pytest            # runs on the small sample in tests/fixtures/data
Data
The benchmark inputs (about 530 MB) are on huggingface.co/datasets/cx-cmu/IdeaTaste. This downloads them into data/areas/ (skipping areas already there) and prints what each file holds, with a few example rows:
python data/download_and_preview.py
Run
Copy .env.example to .env and fill in the API keys of the models you use, then:
ideataste generate --method topic --model deepseek-v4-flash --area auto_research --n 300 --out runs/topic
ideataste evaluate --area auto_research --proposals runs/topic/proposals.jsonl --out runs/topic/eval
generatewritesproposals.jsonl,trajectories.jsonlandllm_calls.jsonl. Re-running the same command resumes the run.evaluatedoes three things:- extracts idea schemas with DeepSeek-V4-Pro;
- retrieves candidate pairs and judges them slot by slot with GPT-5.6 Luna;
- writes the verdicts and
scores.json.
- Cost: both call paid APIs. A 300-proposal population takes up to 6,000 agent calls. Evaluating it takes about 300 extraction calls, plus one judge call per candidate pair: 5 per 2026 paper, and up to 1,500 diversity pairs.
The paper's settings are the defaults: 300 proposals, 20 steps, and FRONTIER in two rounds.
- method: what the LLM agent is told about its area.
free: only that it is a researcher in the area.topic: one research topic, allocated in proportion to the corpus with recent years upweighted.landscape: the area's most common 2025 task tags, method tags and task–method pairs with their shares, plus a<tag_papers>action to retrieve papers by tag.frontier: TOPIC run in two rounds; the second round can search and read the first round's proposals and research traces.
- model: the LLM behind the agent, one of
llama-4-scout,claude-haiku-4.5,gemini-3.5-flash-lite,deepseek-v4-flash,qwen3.8-27bandk2-horizon(set insrc/ideataste/configs/models.yaml).qwen3.8-27bexpects a local vLLM server;llama-4-scoutruns on AWS Bedrock. - area: the research community, one of
ml_systems,code_generation,world_modelsandauto_research. It fixes the corpus the agent searches, the area definition in its prompt, and the 2026 papers its proposals are compared with.
Extending:
- A new model: add an entry to
src/ideataste/configs/models.yaml. Any OpenAI-compatible endpoint works without code changes. - A new method: subclass
Method(methods/base.py), overridepopulation,system_promptortools, and register it inmethods/__init__.py.
Citation
@article{zhong2026ideataste,
  title   = {IdeaTaste: Do LLMs Share the Research Taste of Human Researchers?},
  author  = {Zhong, Shanshan and Xu, Chen and Ning, Jingjie and Liu, Zhengzhong and Kumar, Aviral and Xiong, Chenyan},
  journal = {arXiv preprint arXiv:2611.03424},
  year    = {2026}
}
Explore related projects
affaan-m/ECC
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
301,951 starsNousResearch/hermes-agent
The agent that grows with you
262,950 starsmultica-ai/andrej-karpathy-skills
A single CLAUDE.md file to improve Claude Code behavior, derived from Andrej Karpathy's observations on LLM coding pitfalls.
232,515 starsfirecrawl/firecrawl
Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥
200,932 stars