Projects View on GitHub
bradleyboyuyang/Statistical-Arbitrage
bradleyboyuyang/Statistical-Arbitrage has 290 GitHub stars and 58 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-19 07:21 UTC. Last push 2023-07-30.
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
High-frequency statistical arbitrage
AIREADME.md
OriginalStatistical-Arbitrage
In this project we provide a backtesting pipeline for intraday statistical arbitrage. Both traditional spread models (i.e. pairs trading with cointegration tests, time series analysis) and continuous time trading models (i.e. Ornstein-Uhlenbeck process) are used to model the spread portfolios.
Scripts
data: intraday data files, including stocks, options, and dual listing stocksutils: arbitrage tool functions including cointegration tests and regression analysismodels: simulations and parameter estimations for stochastic models and option greeksBM.py: brownian motion related functionsVasicek.py: OU-process related functionsBS_model.py: Black-Scholes model and option greeks
statistical_arbitrage: notebook for realizing pair trading based on limit orderbook stock datares: results for positions, thresholds, and PnLs
Backtesting
Spread Portfolios
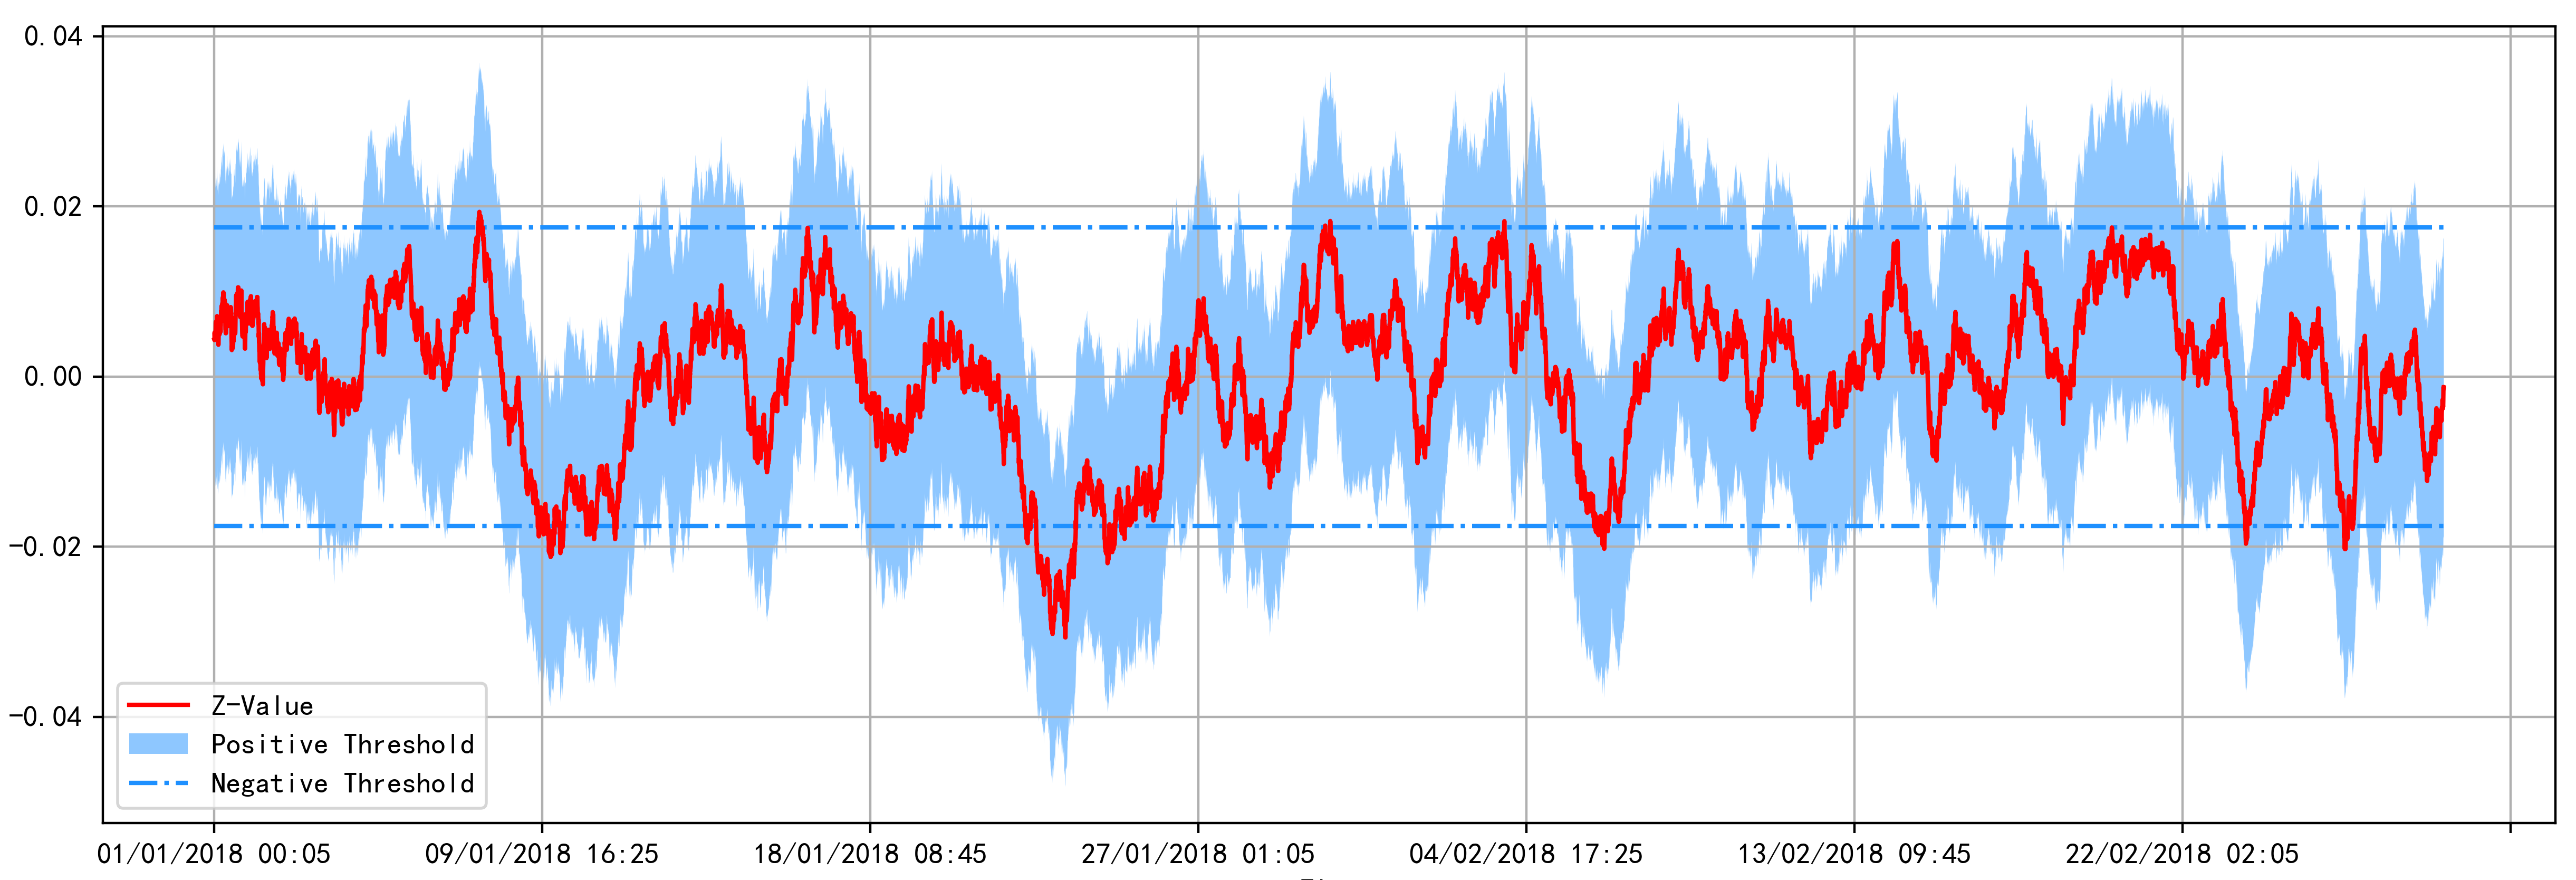
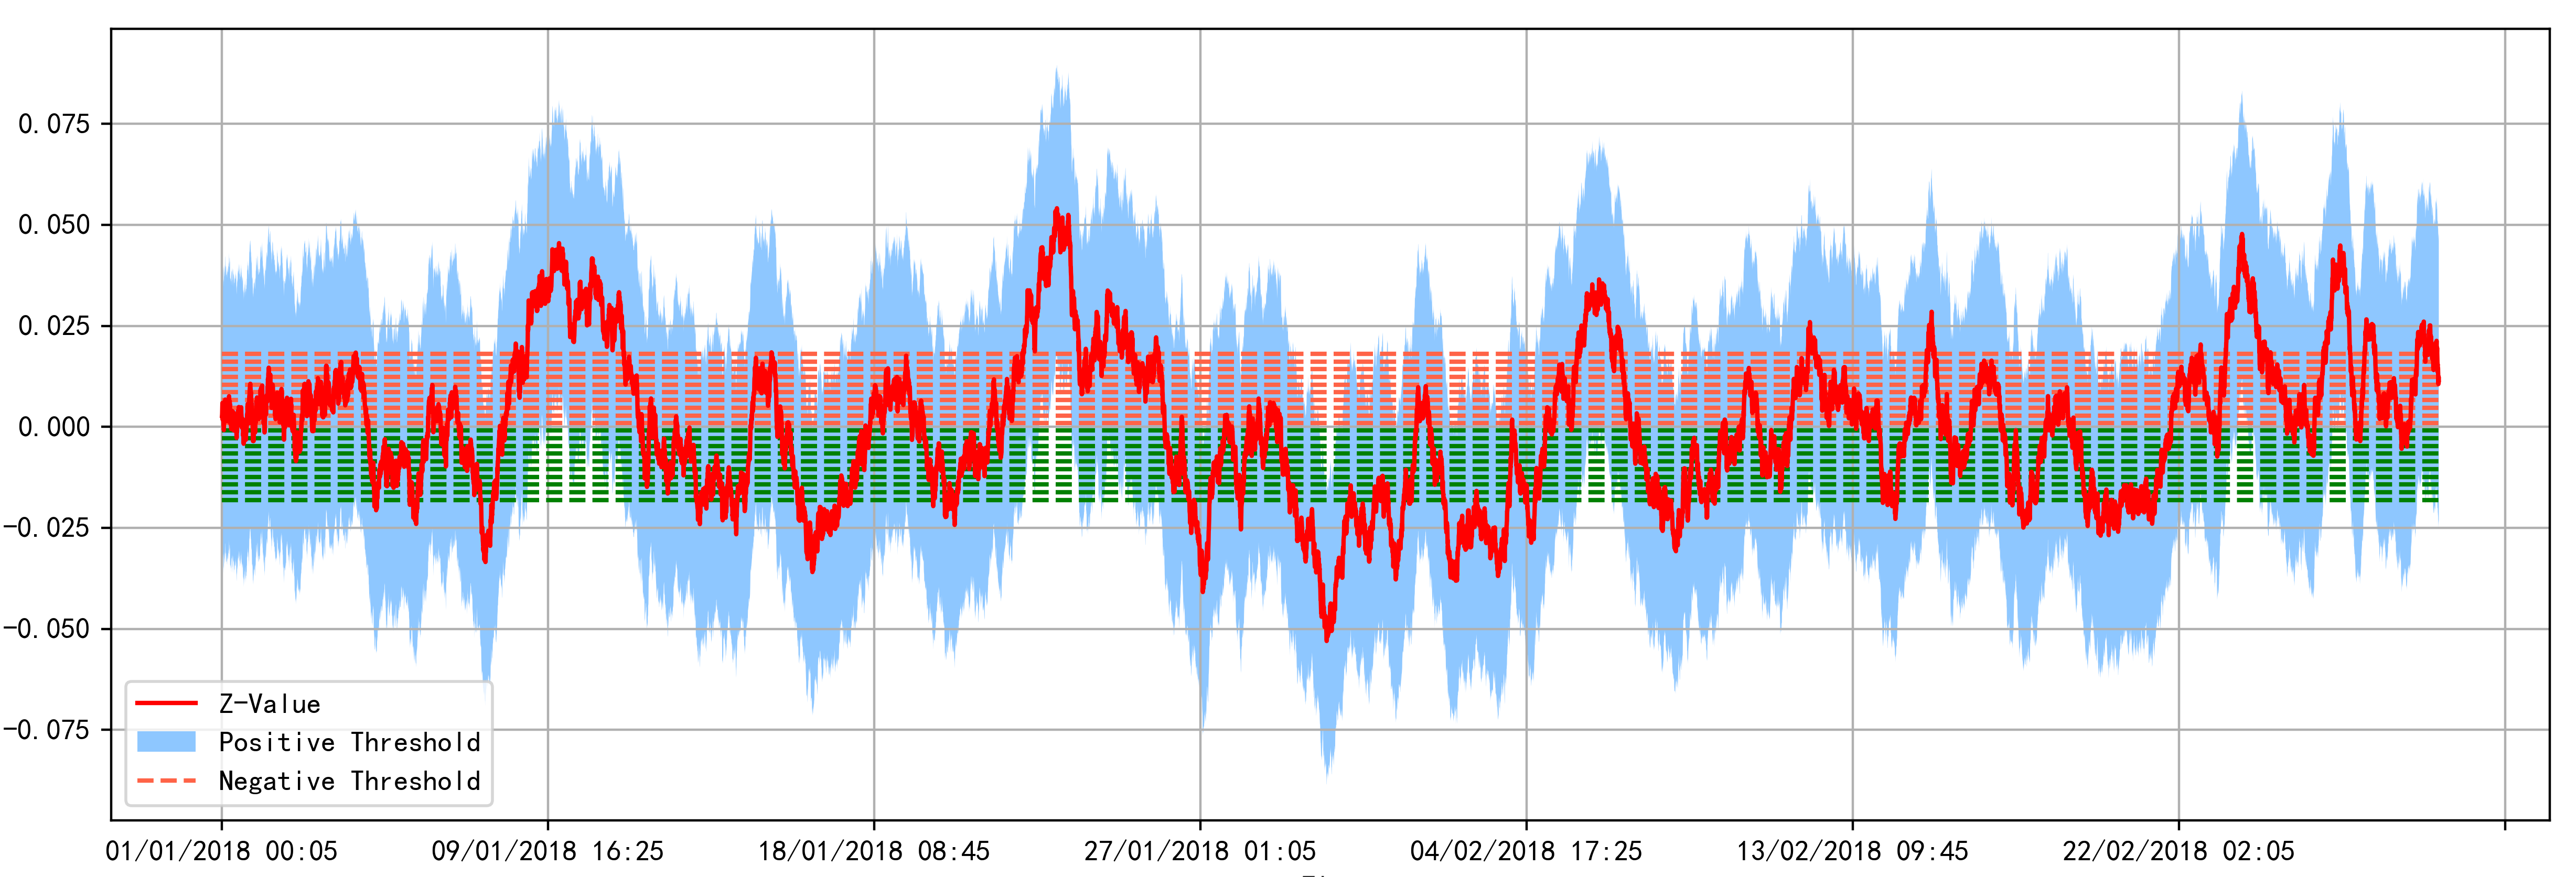
Threshold Analysis
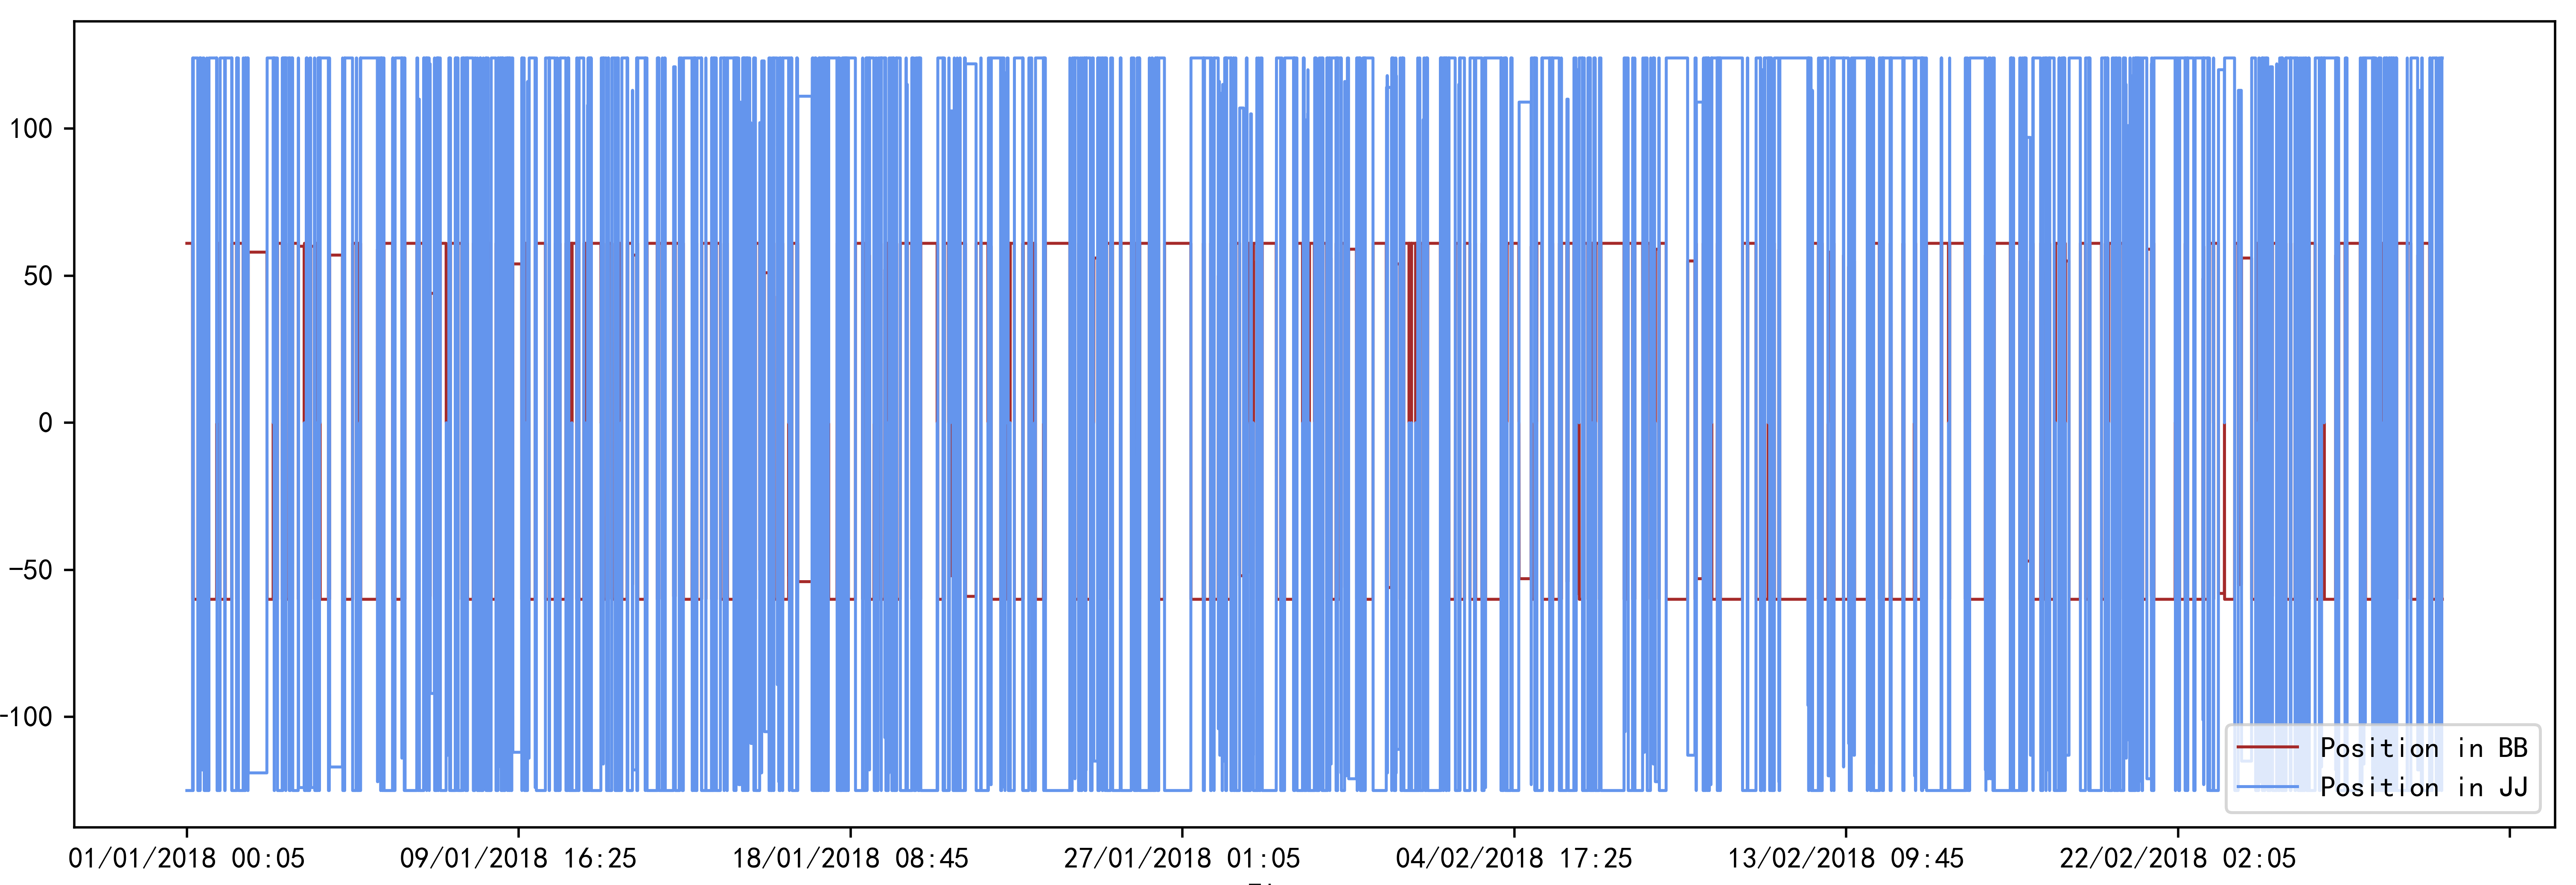
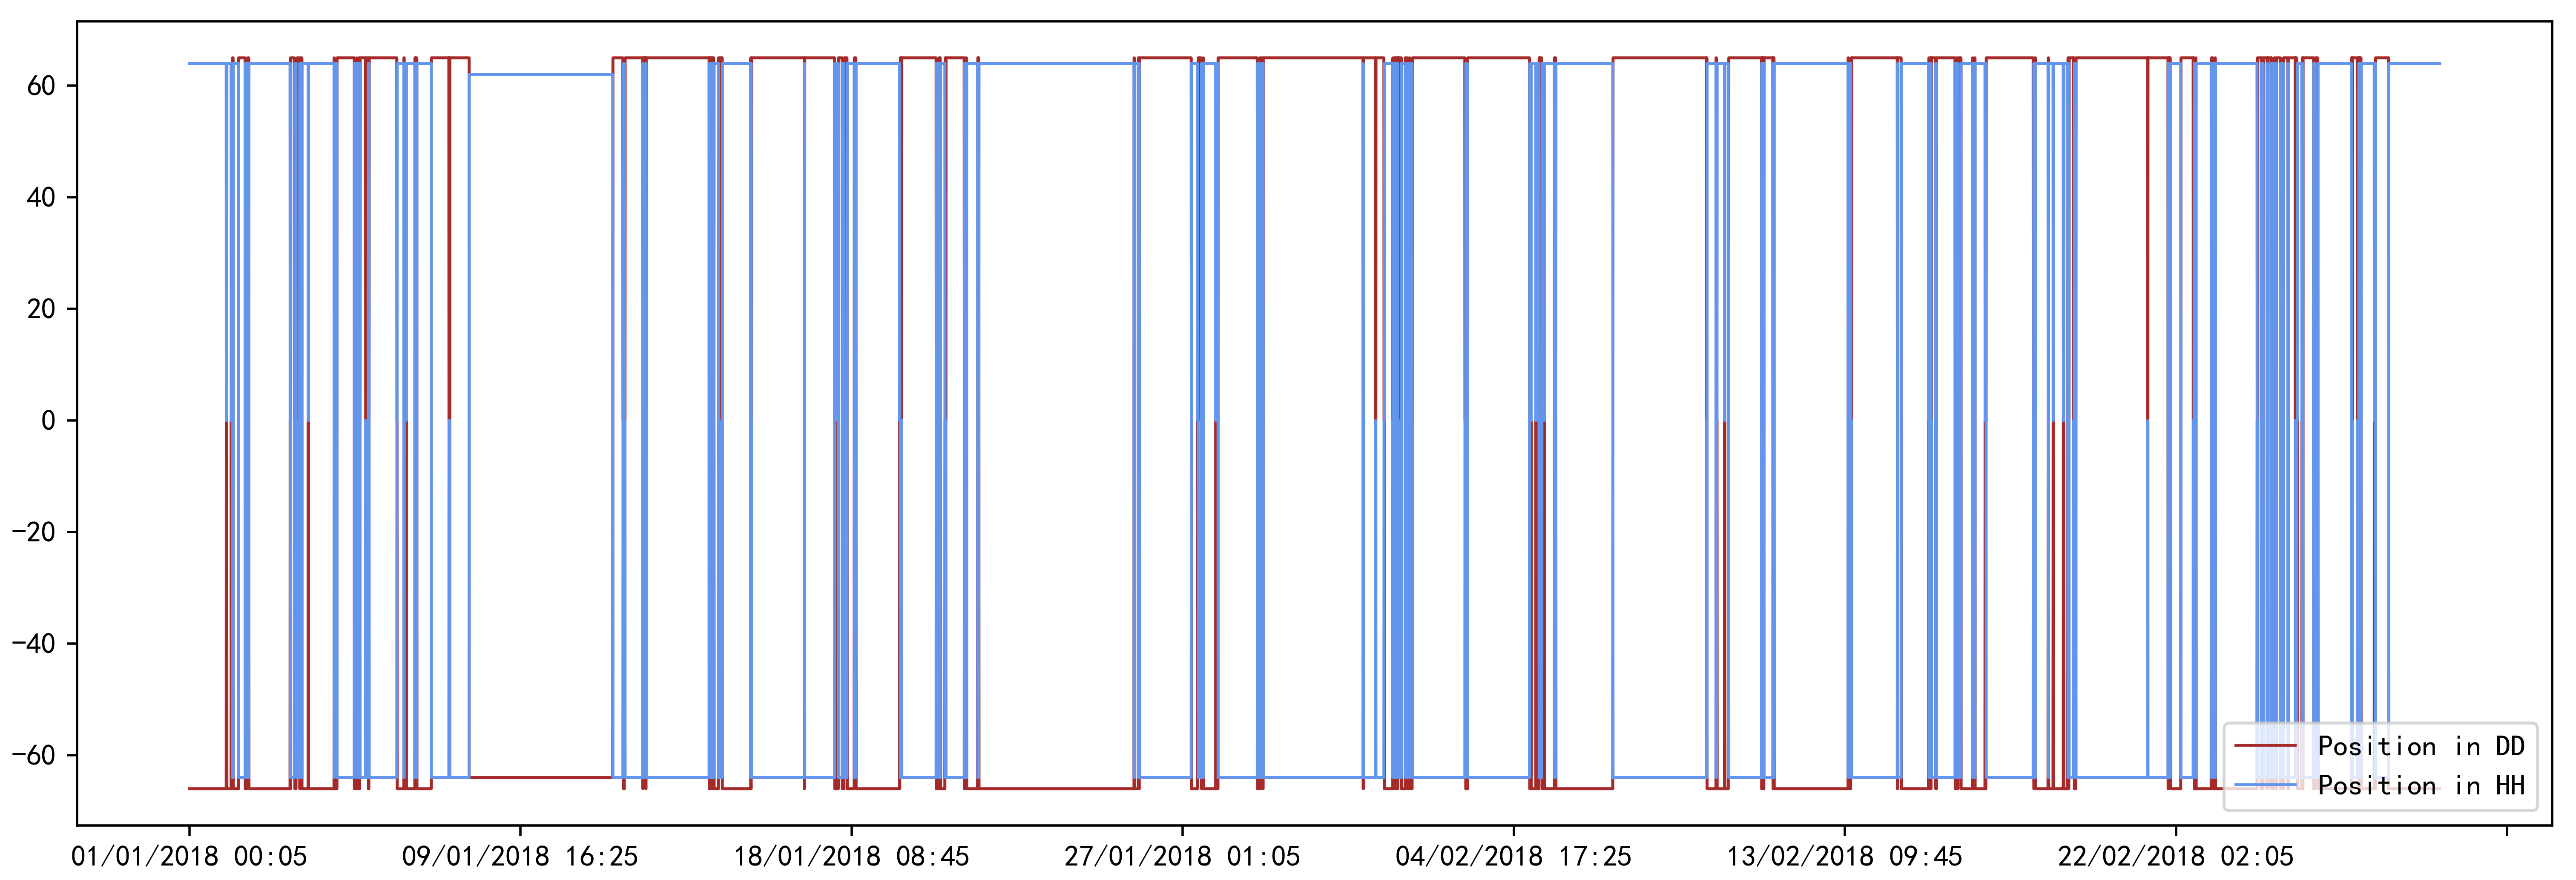
Position Analysis
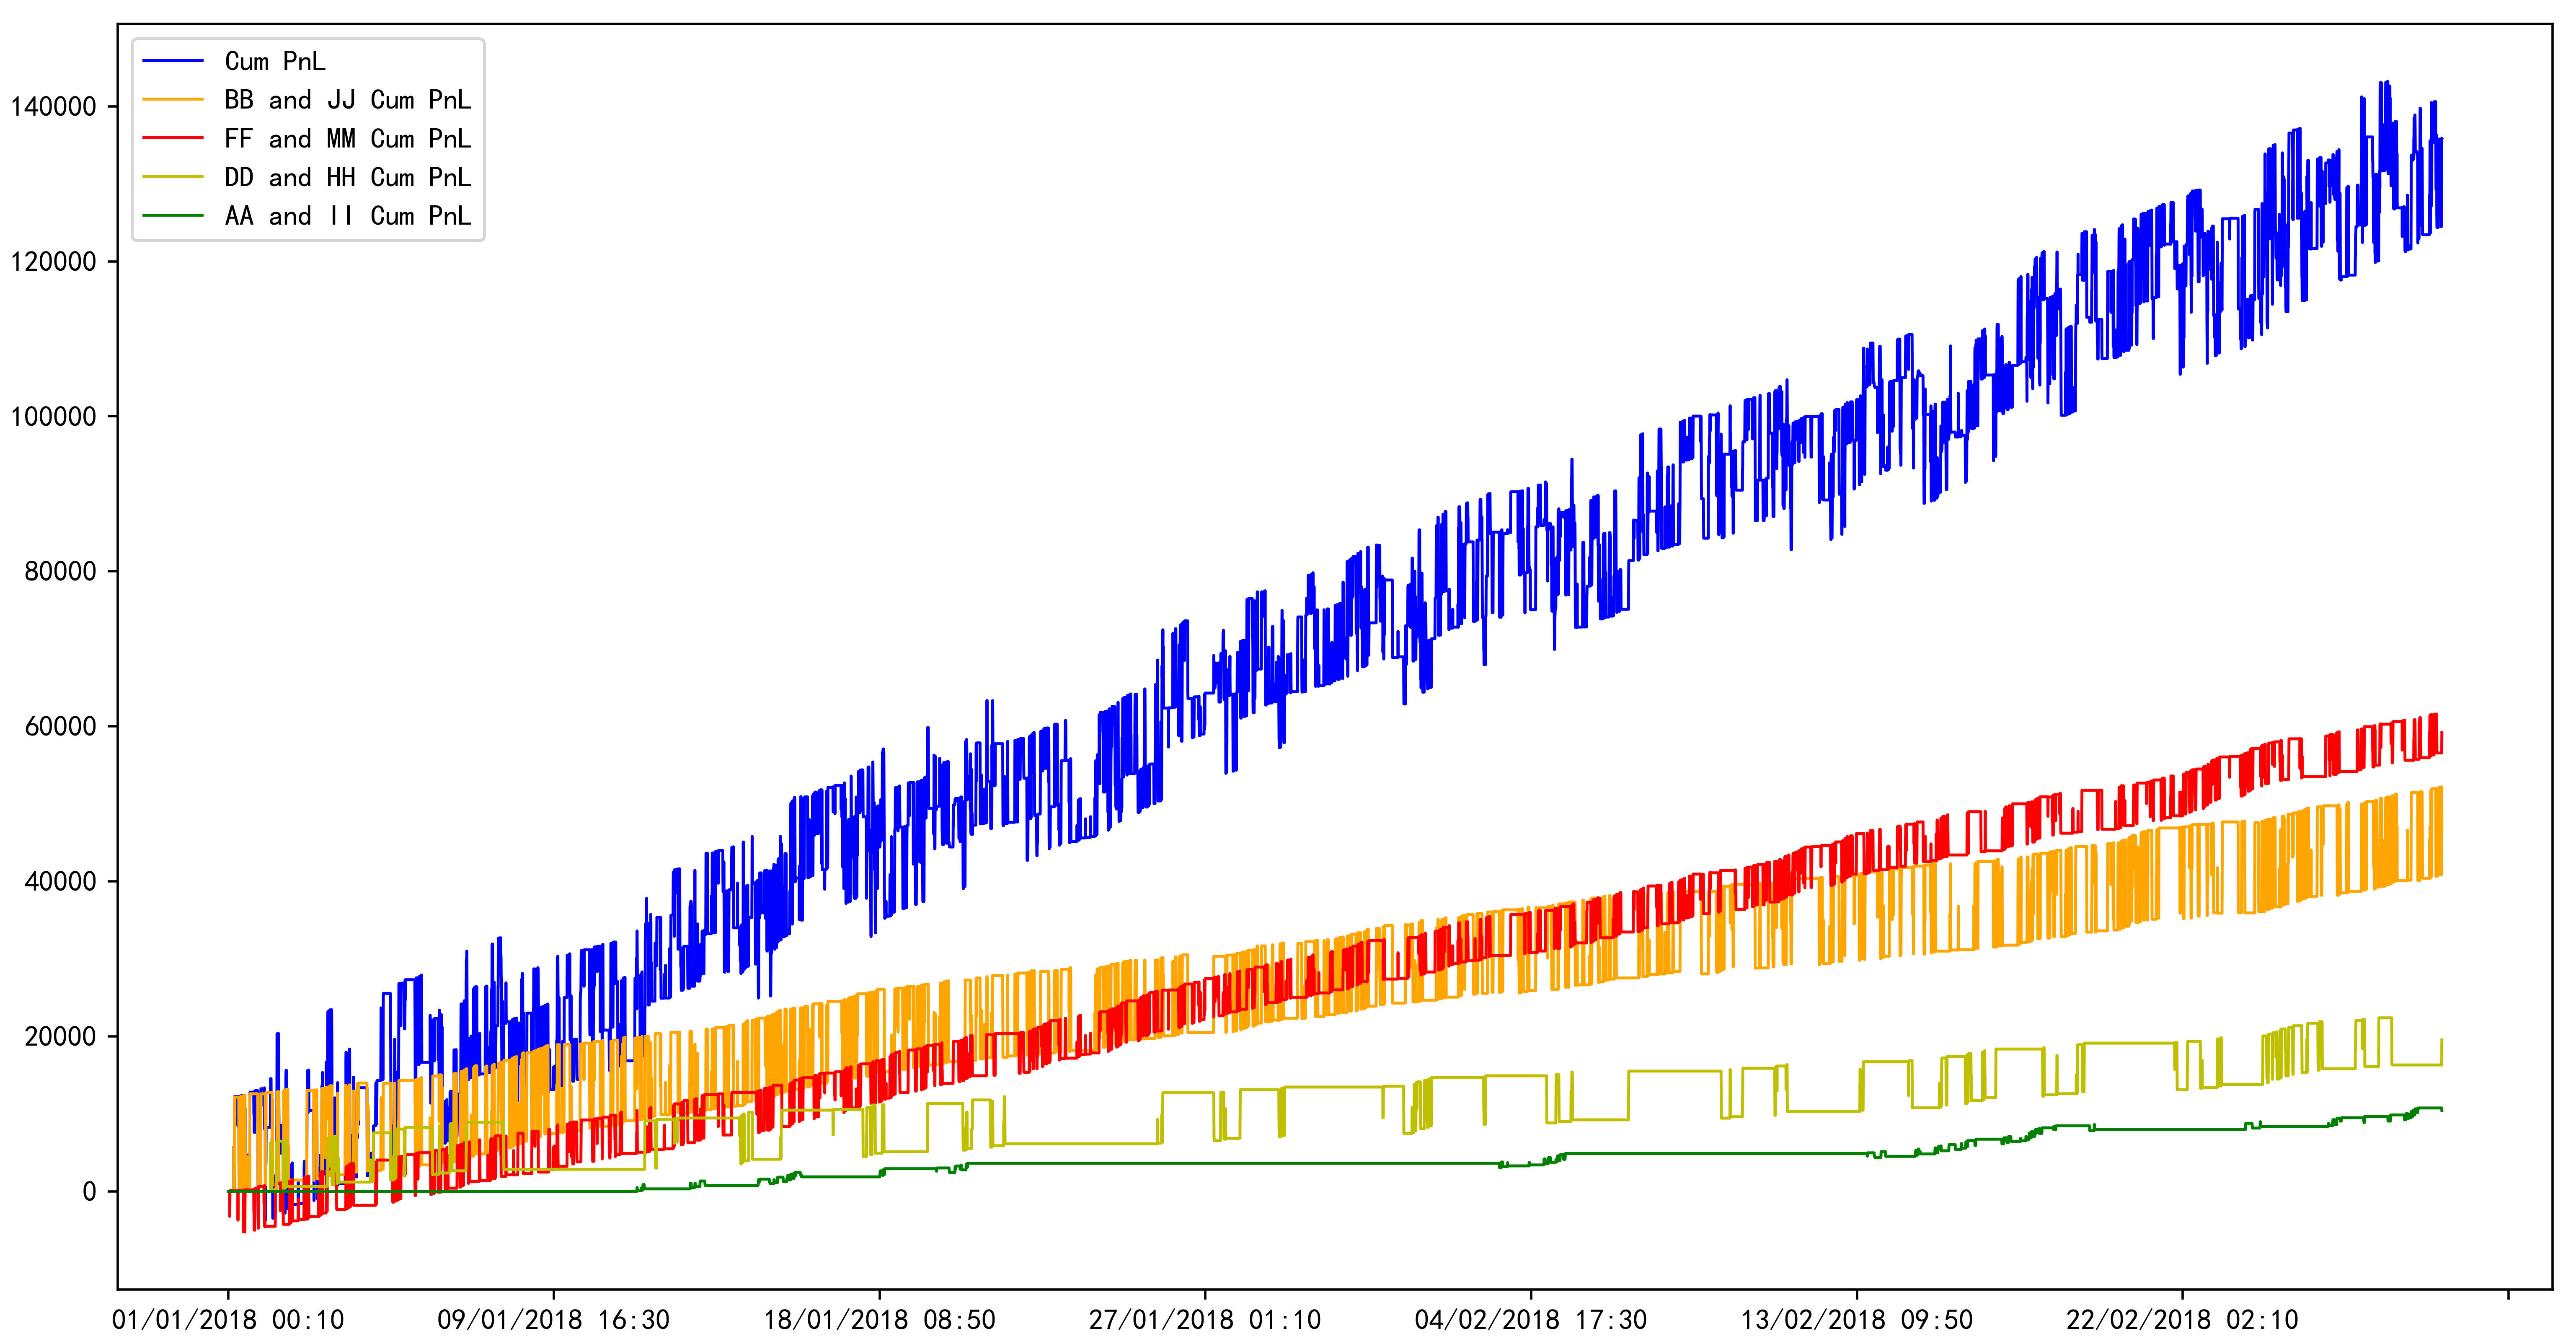
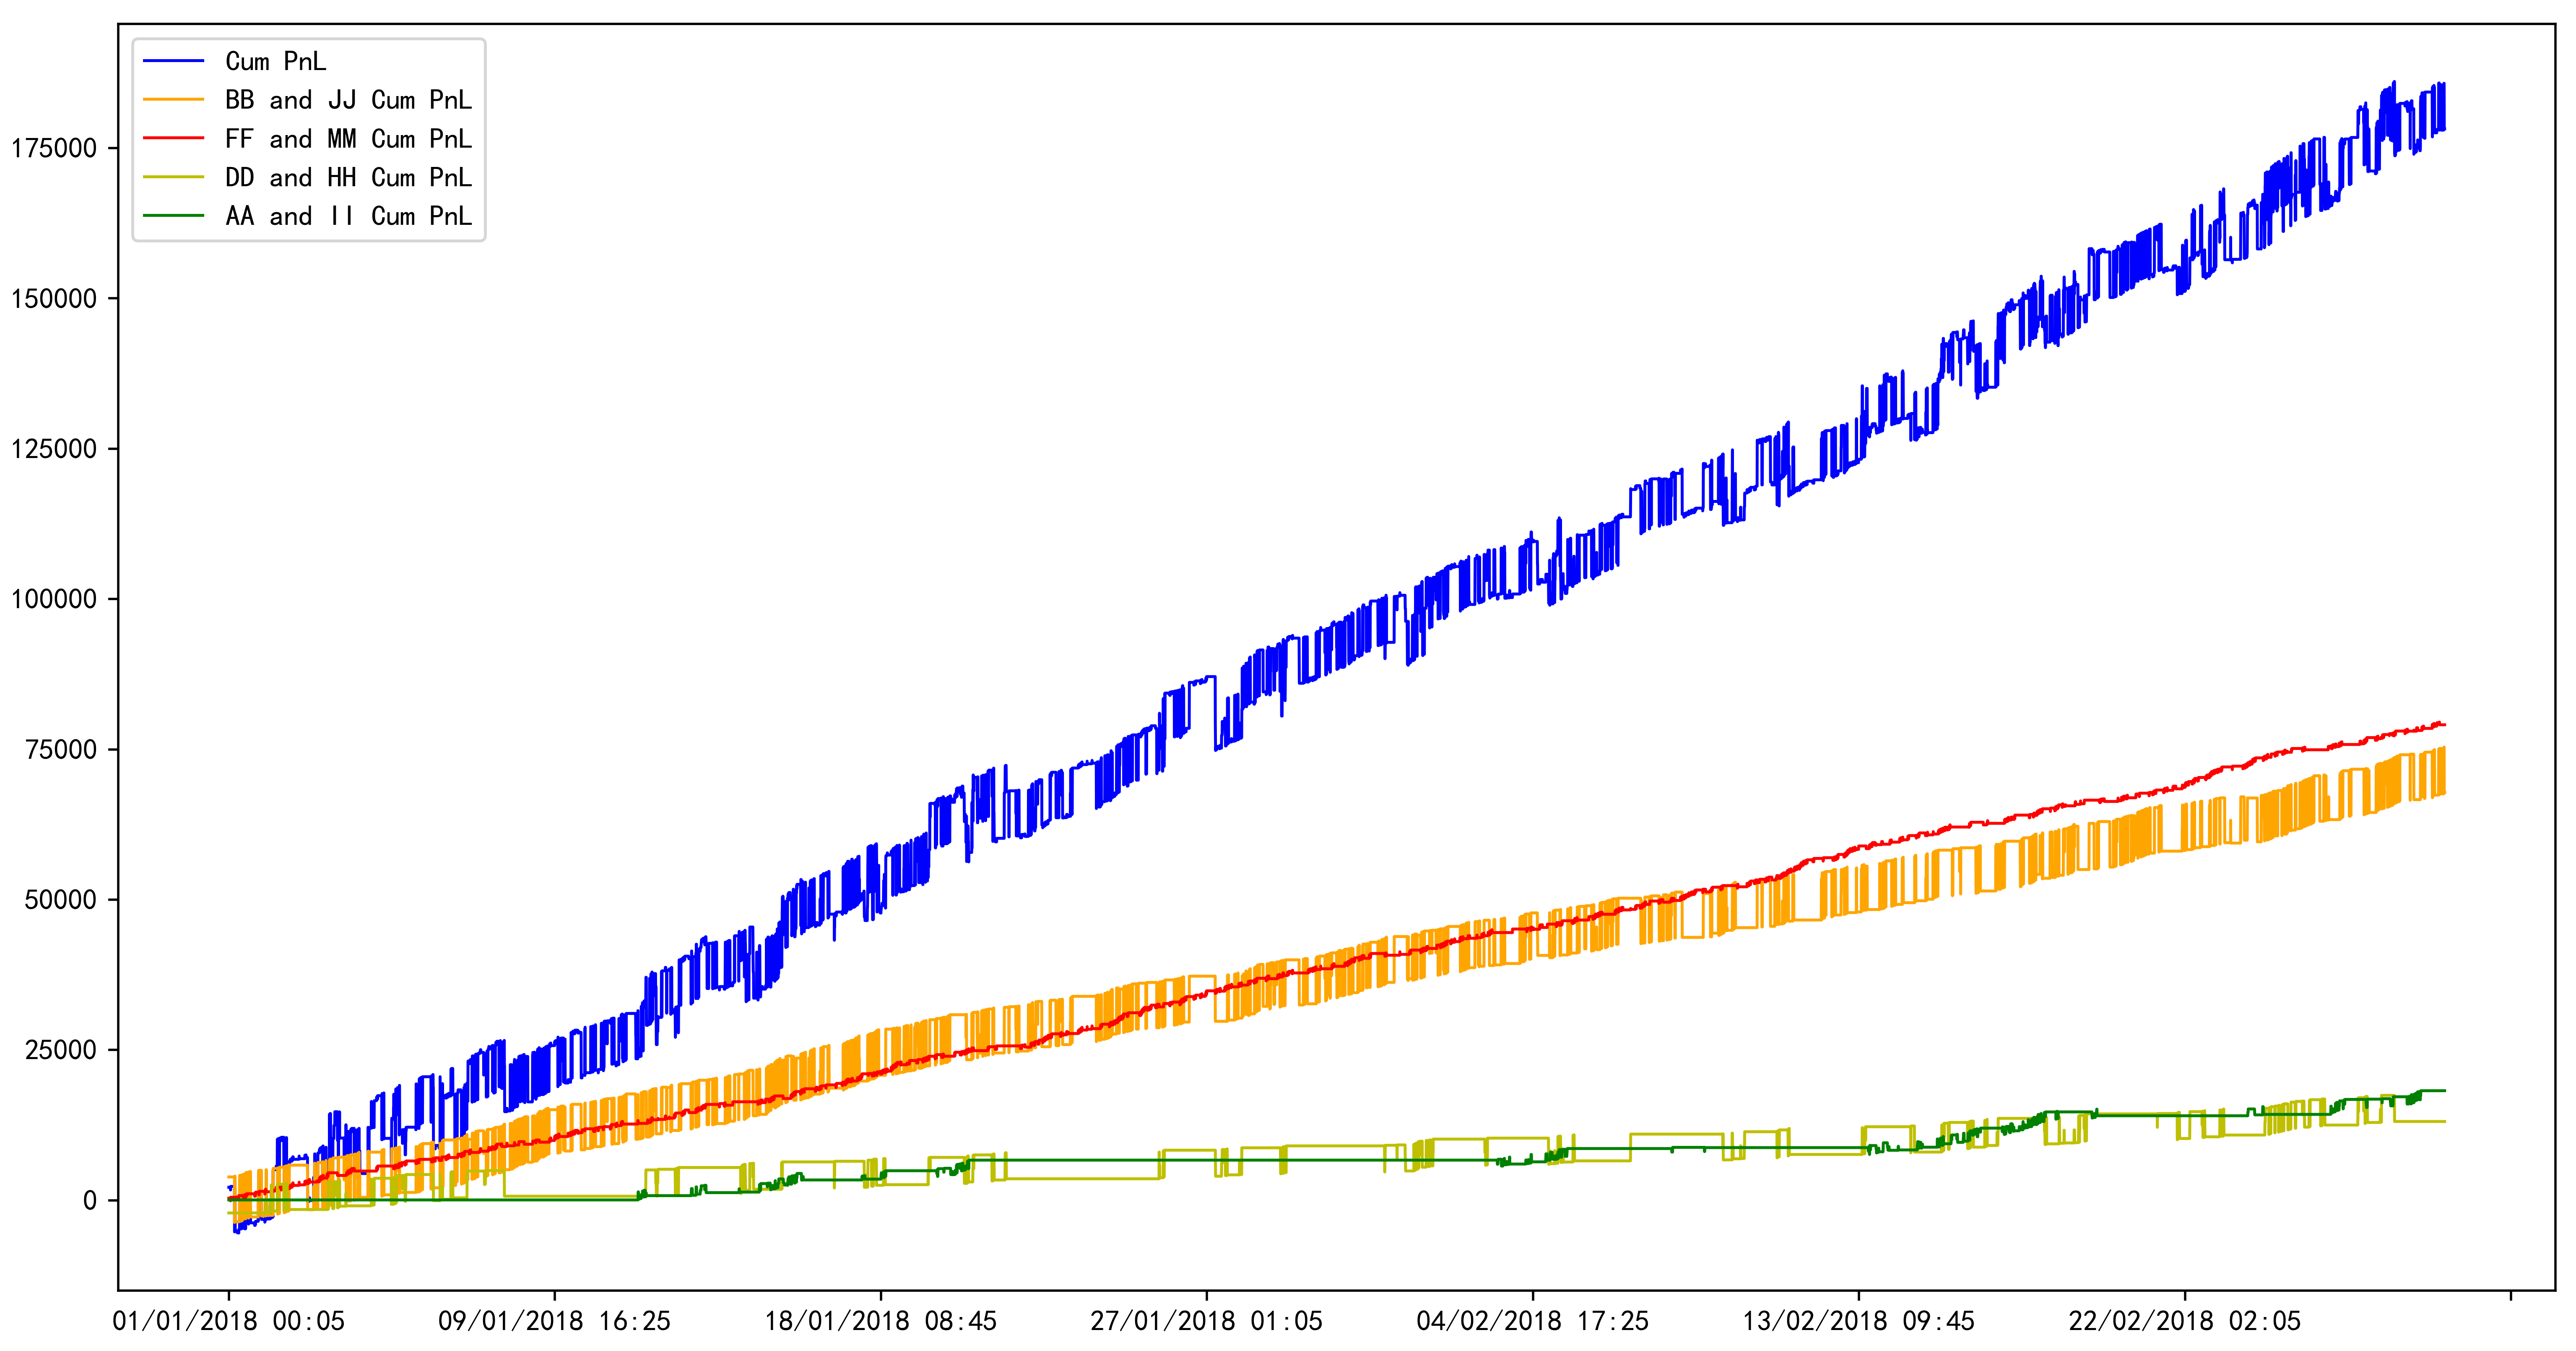
PnL Visualization
Note
- Higher the transaction costs, larger the optimal entry points for arbitrage, lower the trading frequency.
- Sensitivity analysis needs to be conducted with respect to the level of transaction costs (price impact, bid-ask spread, and commission fees).