
beam-cloud/beta9
beam-cloud/beta9 has 1,843 GitHub stars and 176 forks. GitHot measured 0 stars in 24 hours and +9 in 7 days. Last checked 2026-11-04 12:48 UTC. Last push 2026-11-03.
Ultrafast serverless GPU inference, sandboxes, and background jobs
What you can do
- Fast Cold Starts: Launch containers in under a second using a custom container runtime, scheduler, and embedded caching
- Parallelization and Concurrency: Fan out workloads to 100s of containers
- First-Class Developer Experience: Hot-reloading, webhooks, and scheduled jobs
- Scale-to-Zero: Workloads are serverless by default
Measured star growth
- in 24h
- 0
- in 7 days
- +9
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original
Run AI Workloads at Scale




Beam is a fast, open-source runtime for serverless AI workloads. It gives you a Pythonic interface to deploy and scale AI applications with zero infrastructure overhead.
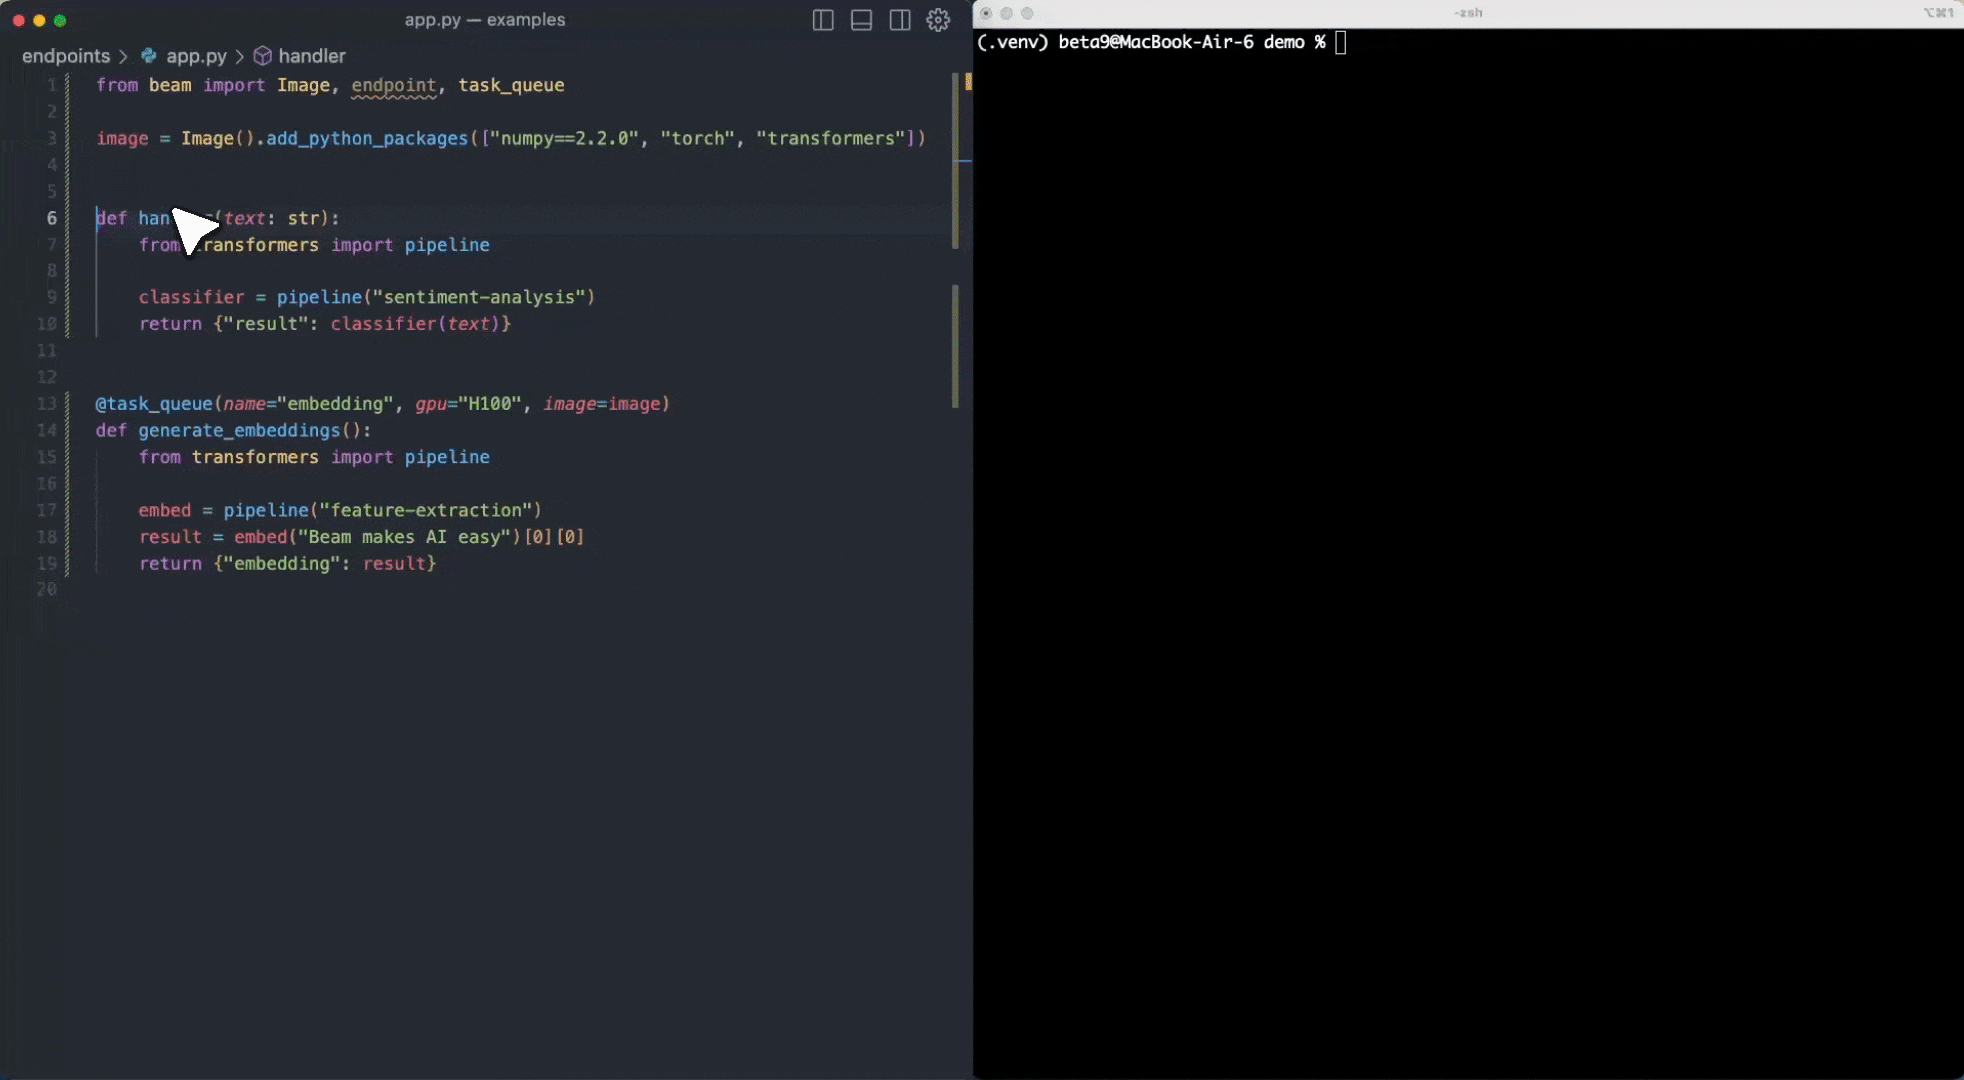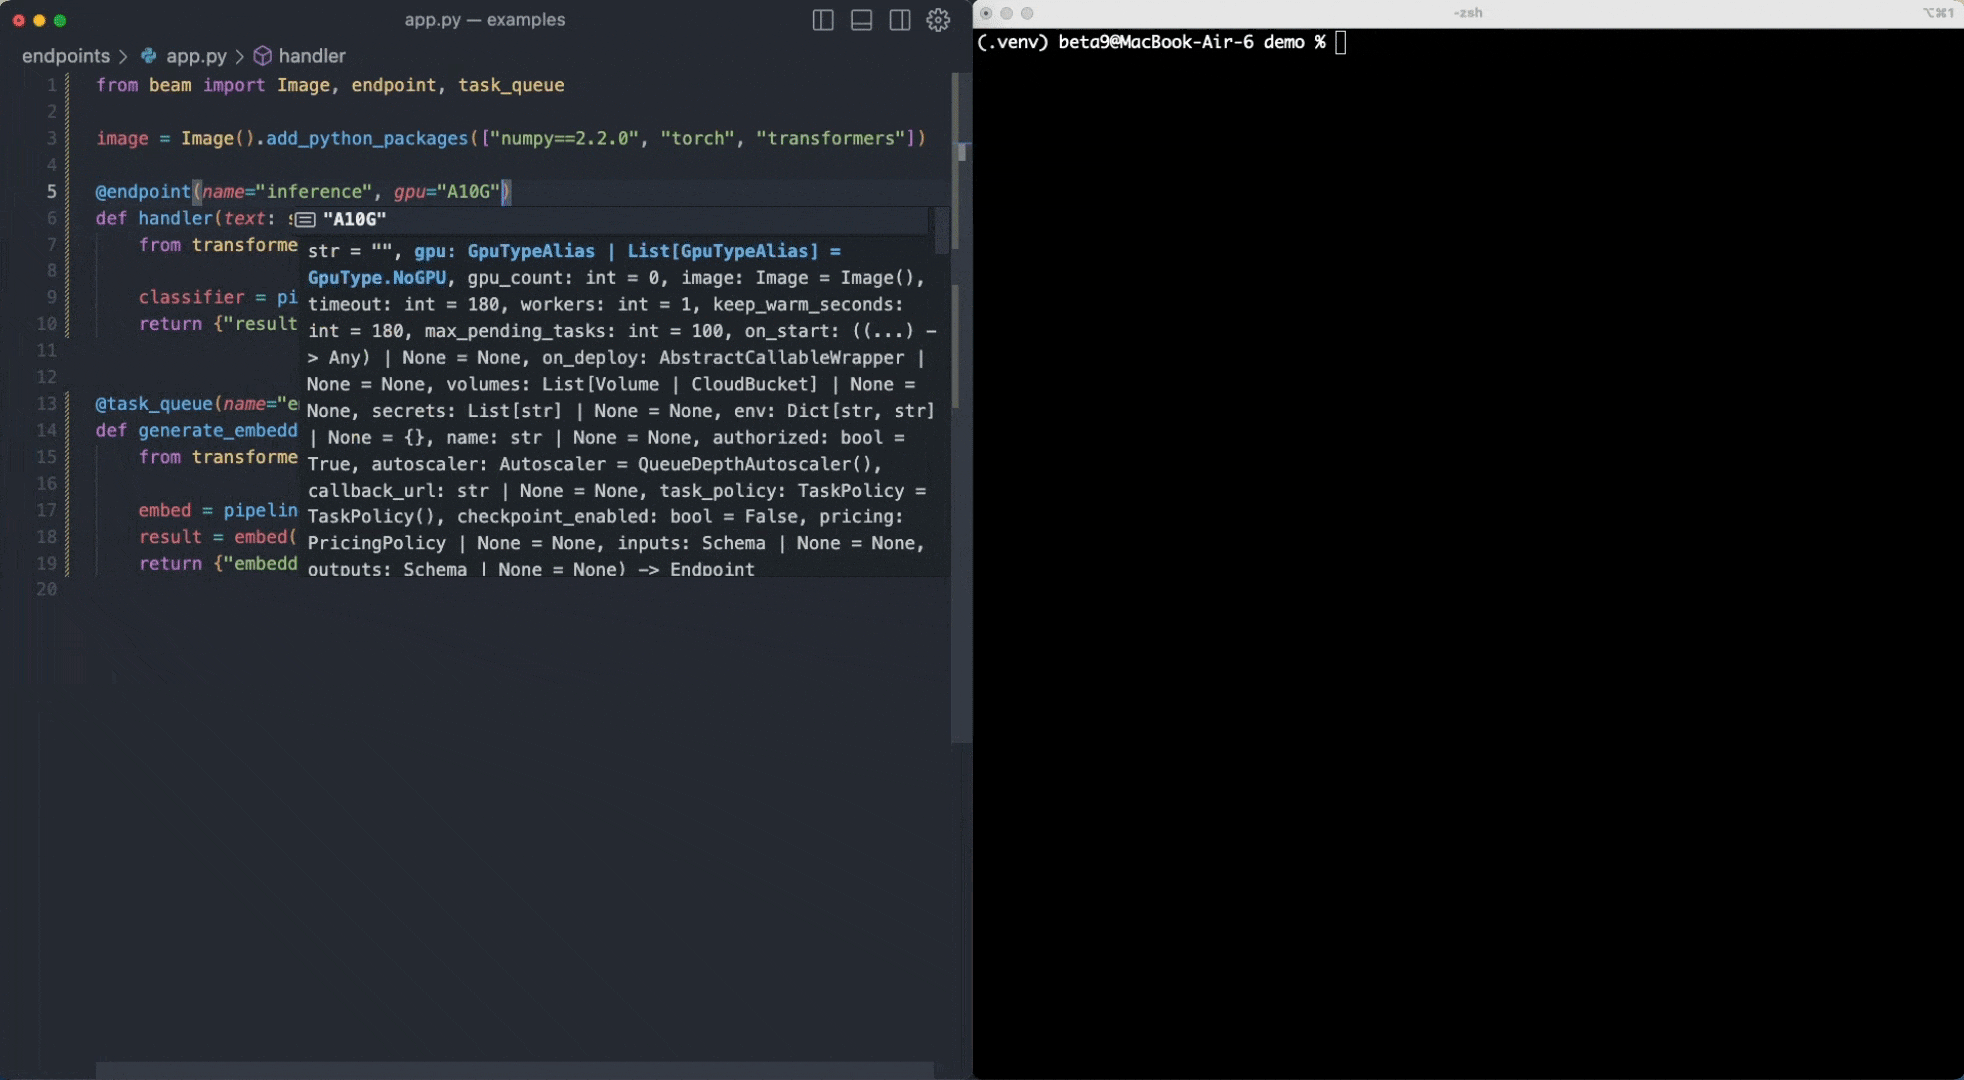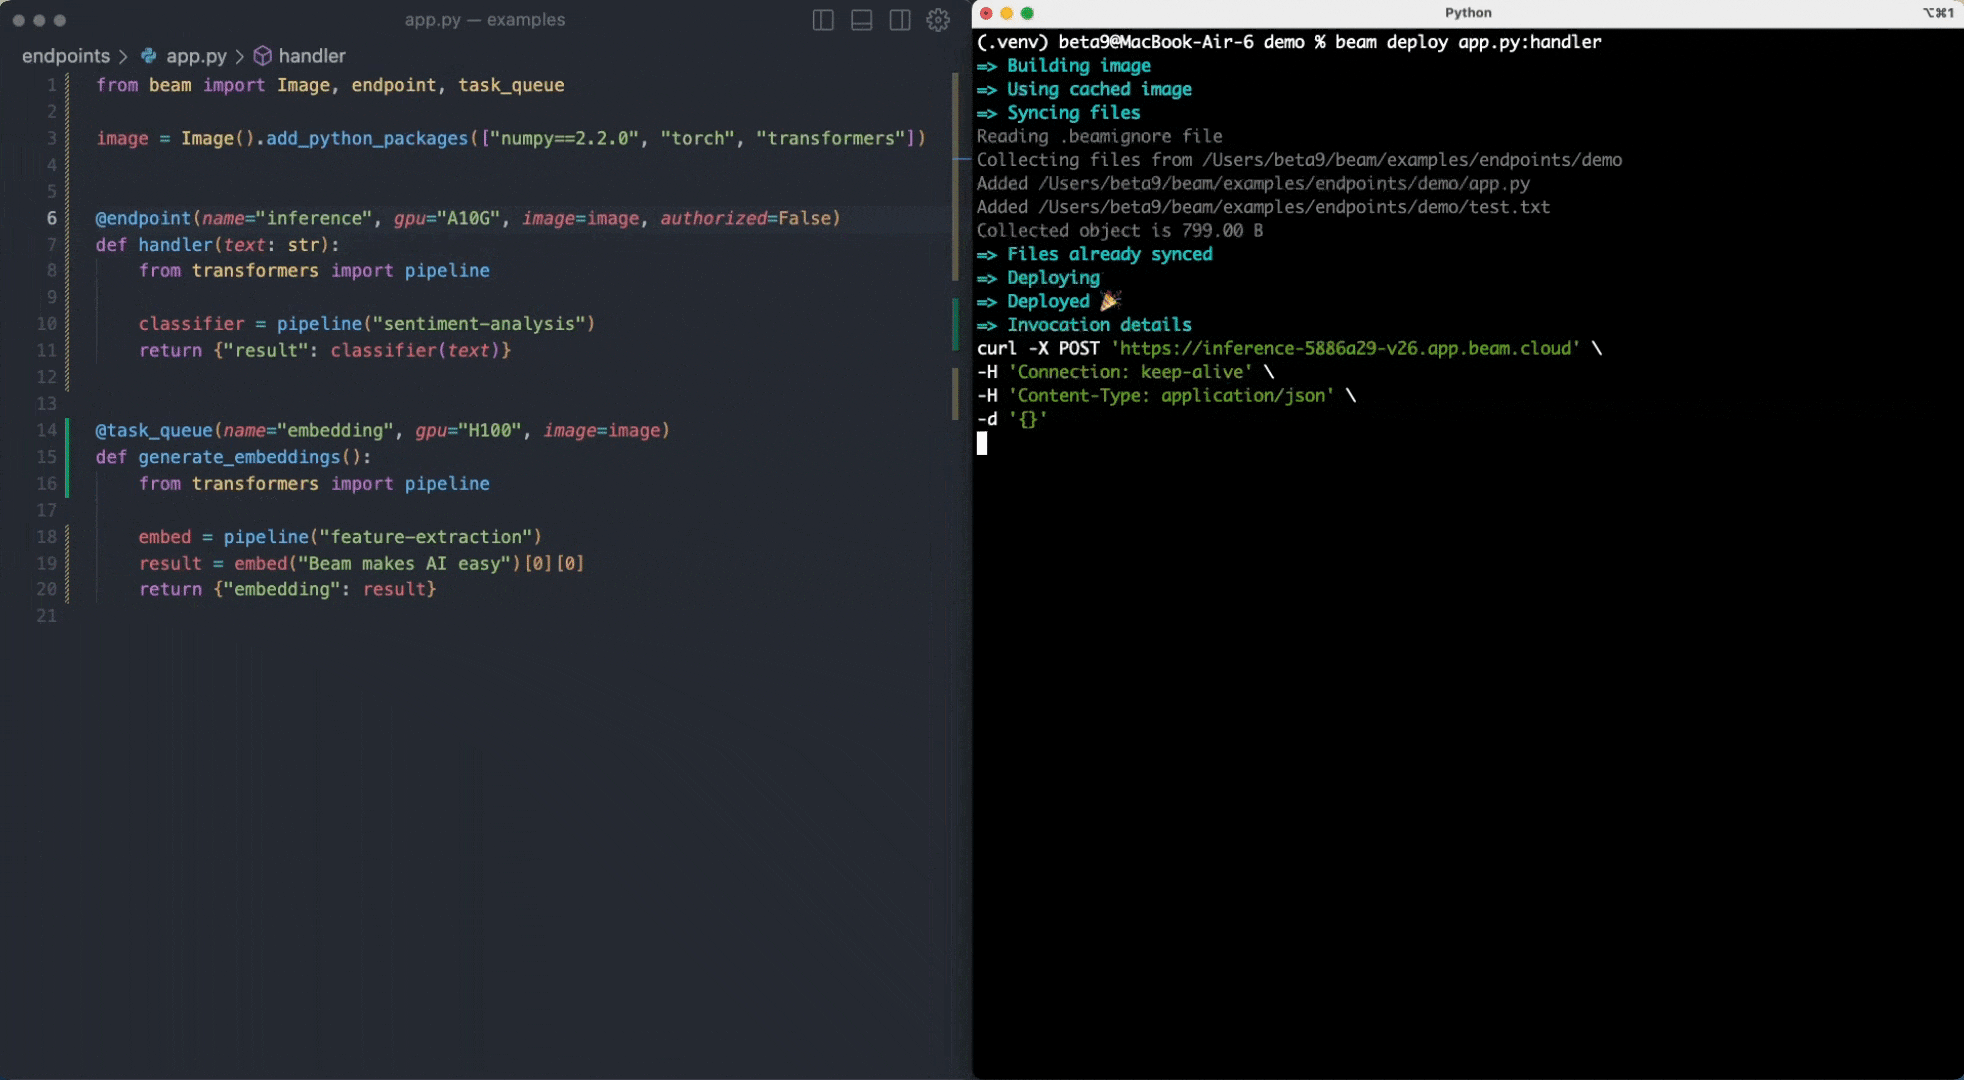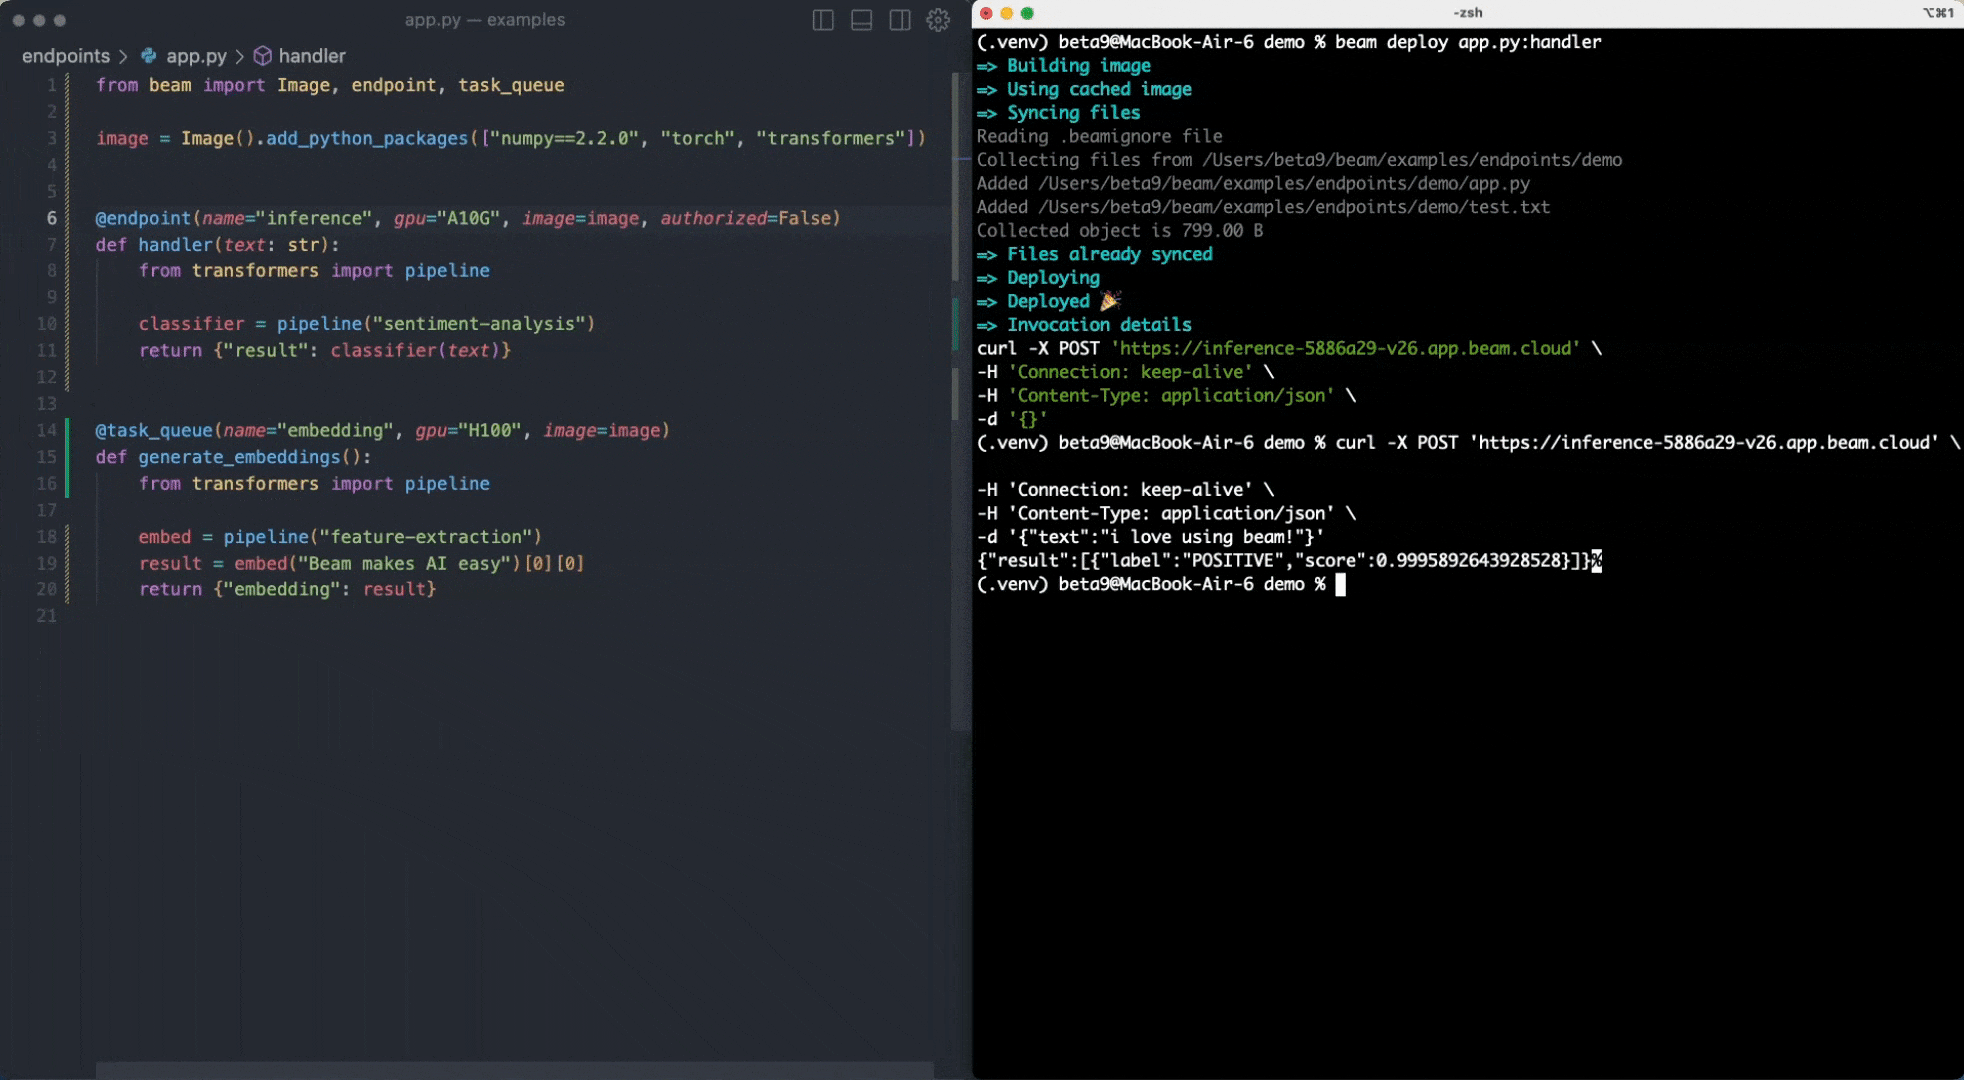
✨ Features
- Fast Cold Starts: Launch containers in under a second using a custom container runtime, scheduler, and embedded caching
- Parallelization and Concurrency: Fan out workloads to 100s of containers
- First-Class Developer Experience: Hot-reloading, webhooks, and scheduled jobs
- Scale-to-Zero: Workloads are serverless by default
- Volume Storage: Mount distributed storage volumes
- GPU Support: Run on our cloud (4090s, H100s, and more) or bring your own GPUs
📦 Installation
pip install beam-client
⚡️ Quickstart
- Create an account here
- Follow our Getting Started Guide
Creating a sandbox
Spin up isolated containers to run LLM-generated code:
from beam import Image, Sandbox


sandbox = Sandbox(image=Image()).create()
response = sandbox.process.run_code("print('I am running remotely')")

print(response.result)
Deploy a serverless inference endpoint
Create an autoscaling endpoint for your custom model:
from beam import Image, endpoint
from beam import QueueDepthAutoscaler

@endpoint(
    image=Image(python_version="python3.11"),
    gpu="A10G",
    cpu=2,
    memory="16Gi",
    autoscaler=QueueDepthAutoscaler(max_containers=5, tasks_per_container=30)
)
def handler():
    return {"label": "cat", "confidence": 0.97}
Run background tasks
Schedule resilient background tasks (or replace your Celery queue) by adding a simple decorator:
from beam import Image, TaskPolicy, schema, task_queue


class Input(schema.Schema):
    image_url = schema.String()


@task_queue(
    name="image-processor",
    image=Image(python_version="python3.11"),
    cpu=1,
    memory=1024,
    inputs=Input,
    task_policy=TaskPolicy(max_retries=3),
)
def my_background_task(input: Input, *, context):
    image_url = input.image_url
    print(f"Processing image: {image_url}")
    return {"image_url": image_url}


if __name__ == "__main__":
    # Invoke a background task from your app (without deploying it)
    my_background_task.put(image_url="https://example.com/image.jpg")

    # You can also deploy this behind a versioned endpoint with:
    # beam deploy app.py:my_background_task --name image-processor
Self-Hosting vs Cloud
Beta9 is the open-source engine powering Beam, our fully-managed cloud platform. You can self-host Beta9 for free or choose managed cloud hosting through Beam.
👋 Contributing
We welcome contributions big or small. These are the most helpful things for us:
- Submit a feature request or bug report
- Open a PR with a new feature or improvement
❤️ Thanks to Our Contributors
Explore related projects
affaan-m/ECC
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
297,506 starsNousResearch/hermes-agent
The agent that grows with you
260,720 starsmultica-ai/andrej-karpathy-skills
A single CLAUDE.md file to improve Claude Code behavior, derived from Andrej Karpathy's observations on LLM coding pitfalls.
229,671 starsfirecrawl/firecrawl
Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥
198,759 stars