
baaivision/NOVA has 661 GitHub stars and 21 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-09 02:28 UTC. Last push 2025-10-29.
[ICLR 2025] Autoregressive Video Generation without Vector Quantization
Measured star growth
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalAutoregressive Video Generation without Vector Quantization


Haoge Deng1,4*, Ting Pan2,4*, Haiwen Diao3,4*, Zhengxiong Luo4*, Yufeng Cui4
Huchuan Lu3, Shiguang Shan2, Yonggang Qi1†, Xinlong Wang4†
BUPT1, ICT-CAS2, DLUT3, BAAI4
* Equal Contribution, † Corresponding Author
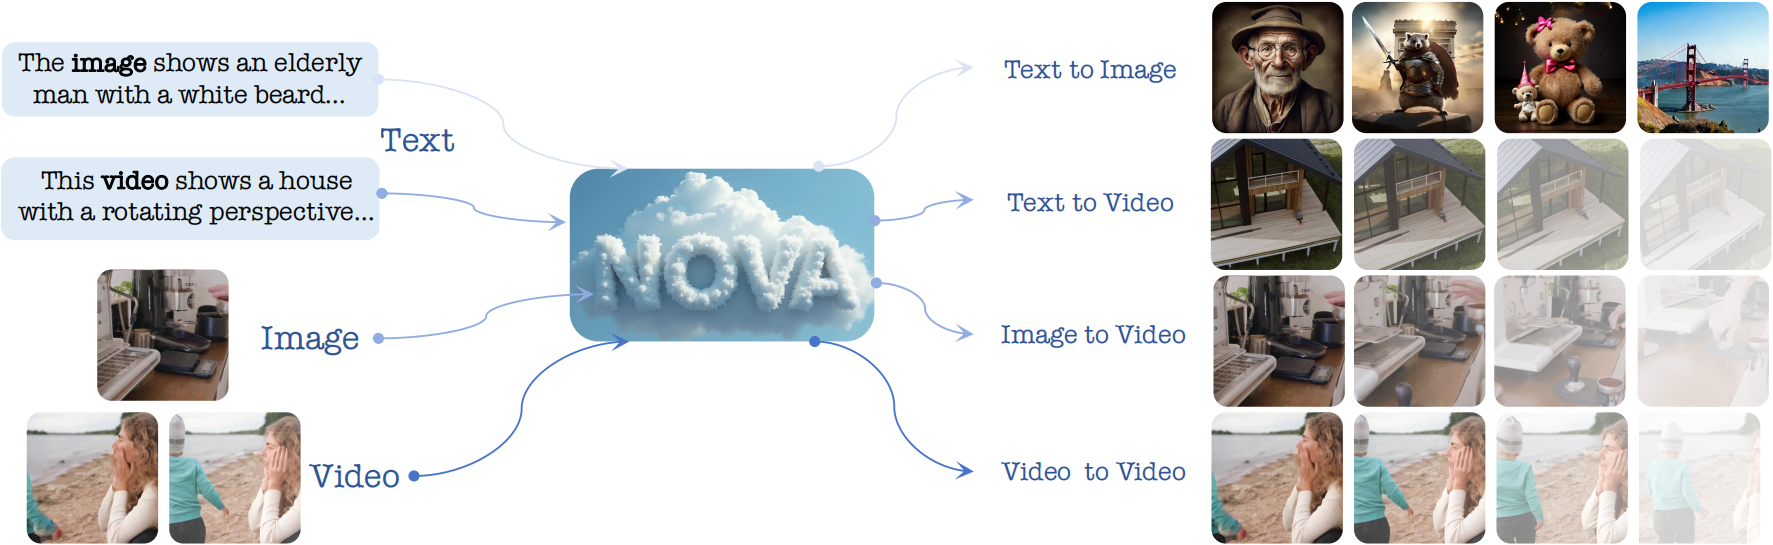
We present NOVA (NOn-Quantized Video Autoregressive Model), a model that enables autoregressive image/video generation with high efficiency. NOVA reformulates the video generation problem as non-quantized autoregressive modeling of temporal frame-by-frame prediction and spatial set-by-set prediction. NOVA generalizes well and enables diverse zero-shot generation abilities in one unified model.
🚀News
[Oct 2025]Released our next video generation model 🐻 URSA.[Jul 2025]Codebase refactor with Accelerate, OmegaConf and Wandb.[Feb 2025]Released Evaluation Guide.[Feb 2025]Released Training Guide[Jan 2025]Accepted by ICLR 2025. [OpenReview] & [Poster].[Dec 2024]Released Project Page[Dec 2024]Released 🤗 Online Demo (T2I, T2V)[Dec 2024]Released paper, weights, and Quick Start guide and Gradio Demo local code .
✨Hightlights
- 🔥 Novel Approach: Non-quantized video autoregressive generation.
- 🔥 State-of-the-art Performance: High efficiency with state-of-the-art t2i/t2v results.
- 🔥 Unified Modeling: Multi-task capabilities in a single unified model.
🗄️Model Zoo
See detailed description in Model Zoo
Text to Image
| Model | Parameters | Resolution | Data | Weight | GenEval | DPGBench |
|---|---|---|---|---|---|---|
| NOVA-0.6B | 0.6B | 512x512 | 16M | 🤗 HF link | 0.75 | 81.76 |
| NOVA-0.3B | 0.3B | 1024x1024 | 600M | 🤗 HF link | 0.67 | 80.60 |
| NOVA-0.6B | 0.6B | 1024x1024 | 600M | 🤗 HF link | 0.69 | 82.25 |
| NOVA-1.4B | 1.4B | 1024x1024 | 600M | 🤗 HF link | 0.71 | 83.01 |
Text to Video
| Model | Parameters | Resolution | Data | Weight | VBench |
|---|---|---|---|---|---|
| NOVA-0.6B | 0.6B | 33x768x480 | 20M | 🤗 HF link | 80.12 |
📖Table of Contents
1. Installation
1.1 From Source
Clone this repository to local disk and install:
pip install diffusers transformers accelerate imageio-ffmpeg omegaconf wandb
git clone https://github.com/baaivision/NOVA.git
cd NOVA && pip install .
1.2 From Git
You can also install from the remote repository if you have set your Github SSH key:
pip install diffusers transformers accelerate imageio-ffmpeg omegaconf wandb
pip install git+ssh://[email protected]/baaivision/NOVA.git
2. Quick Start
2.1 Text to Image
import torch
from diffnext.pipelines import NOVAPipeline

model_id = "BAAI/nova-d48w768-sdxl1024"
model_args = {"torch_dtype": torch.float16, "trust_remote_code": True}
pipe = NOVAPipeline.from_pretrained(model_id, **model_args)
pipe = pipe.to("cuda")

prompt = "a shiba inu wearing a beret and black turtleneck."
image = pipe(prompt).images[0]

image.save("shiba_inu.jpg")
2.2 Text to Video
import os
import torch
from diffnext.pipelines import NOVAPipeline
from diffnext.utils import export_to_image, export_to_video
os.environ["PYTORCH_CUDA_ALLOC_CONF"] = "expandable_segments:True"

model_id = "BAAI/nova-d48w1024-osp480"
low_memory = False

model_args = {"torch_dtype": torch.float16, "trust_remote_code": True}
pipe = NOVAPipeline.from_pretrained(model_id, **model_args)

if low_memory:
    # Use CPU model offload routine and expandable allocator if OOM.
    pipe.enable_model_cpu_offload()
else:
    pipe = pipe.to("cuda")

# Text to Video
prompt = "Many spotted jellyfish pulsating under water."
video = pipe(prompt, max_latent_length=9).frames[0]
export_to_video(video, "jellyfish.mp4", fps=12)

# Increase AR and diffusion steps for better video quality.
video = pipe(
  prompt,
  max_latent_length=9,
  num_inference_steps=128,  # default: 64
  num_diffusion_steps=100,  # default: 25
).frames[0]
export_to_video(video, "jellyfish_v2.mp4", fps=12)

# You can also generate images from text, with the first frame as an image.
prompt = "Many spotted jellyfish pulsating under water."
image = pipe(prompt, max_latent_length=1).frames[0, 0]
export_to_image(image, "jellyfish.jpg")
2.3 Image to Video
import os, torch, PIL.Image, numpy as np
from diffnext.pipelines import NOVAPipeline
from diffnext.utils import export_to_image, export_to_video
os.environ["PYTORCH_CUDA_ALLOC_CONF"] = "expandable_segments:True"

model_id = "BAAI/nova-d48w1024-osp480"
low_memory = False

model_args = {"torch_dtype": torch.float16, "trust_remote_code": True}
pipe = NOVAPipeline.from_pretrained(model_id, **model_args)

if low_memory:
    # Use CPU model offload routine and expandable allocator if OOM.
    pipe.enable_model_cpu_offload()
else:
    pipe = pipe.to("cuda")

prompt = "Many spotted jellyfish pulsating under water."

# Step1: Generate or select an image that matches the resolution 768x480.
image = pipe(prompt, max_latent_length=1).frames[0, 0]
export_to_image(image, "jellyfish.jpg")

# Step2: Use this image to generate subsequent frames.
video = pipe(prompt, image=np.array(PIL.Image.open("jellyfish.jpg")), max_latent_length=9).frames[0]
export_to_video(video, "jellyfish.mp4", fps=12)
3. Gradio Demo
# For text-to-image demo
python scripts/app_nova_t2i.py --model "BAAI/nova-d48w1024-sdxl1024" --device 0

# For text-to-video demo
python scripts/app_nova_t2v.py --model "BAAI/nova-d48w1024-osp480" --device 0
4. Train
- See Training Guide
5. Evaluation
- See Evaluation Guide
6. Inference
- See Inference Guide
📋Todo List
- Model zoo
- Quick Start
- Gradio Demo
- Training guide
- Evaluation guide
- Inference guide
- Prompt Writer
- Larger model size
- Additional downstream tasks: Image editing, Video editing, Controllable generation
Citation
If you find this repository useful, please consider giving a star ⭐ and citation 🦖:
@article{deng2025ursa,
  title={Uniform Discrete Diffusion with Metric Path for Video Generation},
  author={Deng, Haoge and Pan, Ting and Zhang, Fan and Liu, Yang and Luo, Zhuoyan and Cui, Yufeng and Shen, Chunhua and Shan, Shiguang and Zhang, Zhaoxiang and Wang, Xinlong},
  journal={arXiv preprint arXiv:2510.24717},
  year={2025}
}
@article{deng2024nova,
  title={Autoregressive Video Generation without Vector Quantization},
  author={Deng, Haoge and Pan, Ting and Diao, Haiwen and Luo, Zhengxiong and Cui, Yufeng and Lu, Huchuan and Shan, Shiguang and Qi, Yonggang and Wang, Xinlong},
  journal={arXiv preprint arXiv:2412.14169},
  year={2024}
}
Acknowledgement
We thank the repositories: MAE, MAR, MaskGIT, DiT, Open-Sora-Plan, CogVideo, FLUX, OpenMuse and CodeWithGPU.
License
Code and models are licensed under Apache License 2.0.
Explore related projects
ytdl-org/youtube-dl
Command-line program to download videos from YouTube.com and other video sites
141,500 starsexcalidraw/excalidraw
Virtual whiteboard for sketching hand-drawn like diagrams
135,396 starsgodotengine/godot
Godot Engine – Multi-platform 2D and 3D game engine
119,840 starsmrdoob/three.js
JavaScript 3D Library.
117,905 stars