
apache/druid
apache/druid has 14,098 GitHub stars and 3,814 forks. GitHot measured +2 stars in 24 hours. Last checked 2026-11-06 17:23 UTC. Last push 2026-11-04.
Apache Druid: a high performance real-time analytics database.
Measured star growth
- in 24h
- +2
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original

| Workflow | Status |
|---|---|
| ⚙️ CodeQL Config |  |
| 🔍 CodeQL |  |
| 🕒 Cron Job ITS |  |
| 🏷️ Labeler |  |
| 🛠️ Static Checks |  |
| 🧪 Unit and Integration Tests Unified |  |


Apache Druid
Druid is a high performance real-time analytics database. Druid's main value add is to reduce time to insight and action.
Druid is designed for workflows where fast queries and ingest really matter. Druid excels at powering UIs, running operational (ad-hoc) queries, or handling high concurrency. Consider Druid as an open source alternative to data warehouses for a variety of use cases. The design documentation explains the key concepts.
Getting started
You can get started with Druid with our local or Docker quickstart. For Kubernetes deployments, the druid-operator is maintained in a separate repository.
Druid provides a rich set of APIs (via HTTP and JDBC) for loading, managing, and querying your data. You can also interact with Druid via the built-in web console (shown below).
Load data
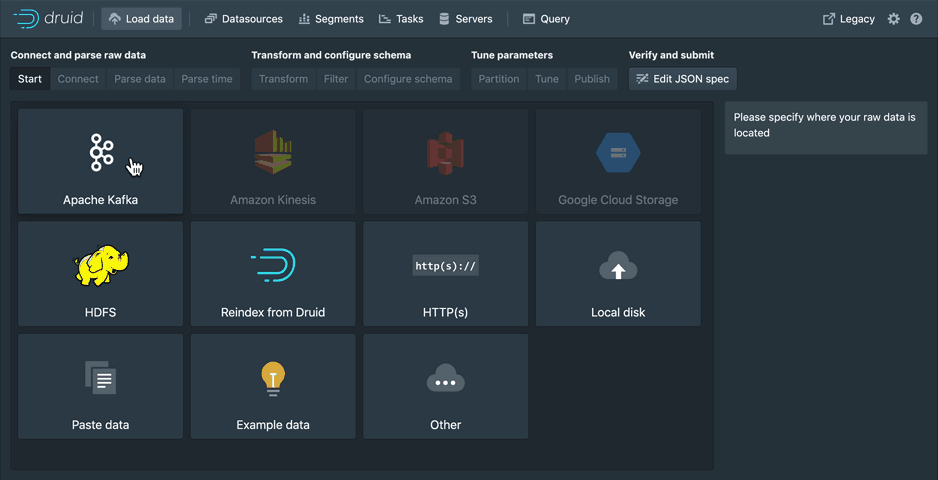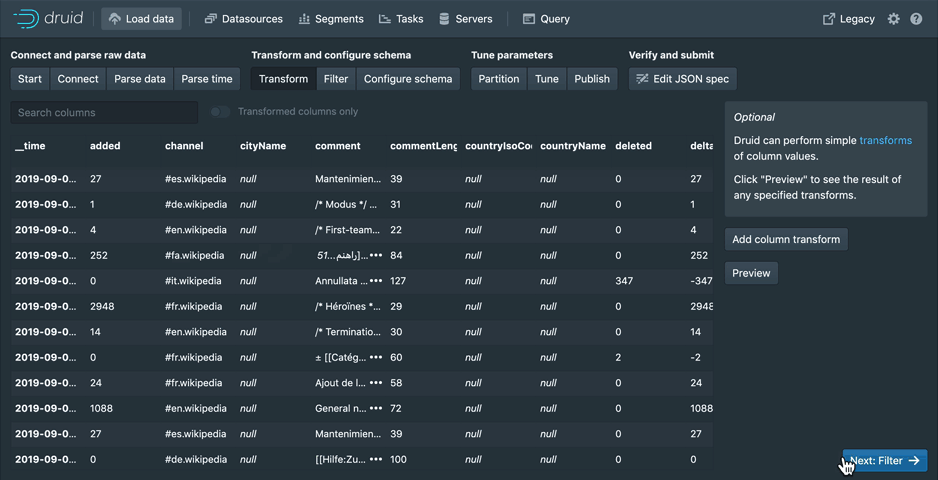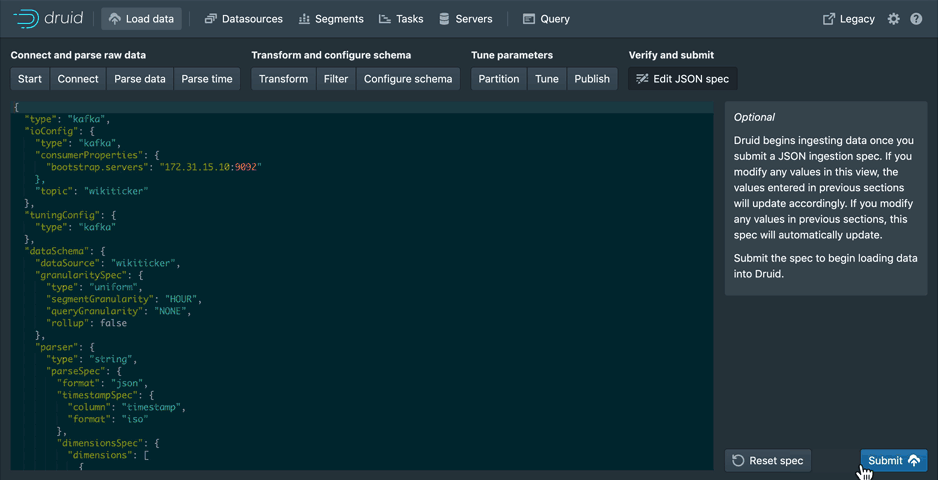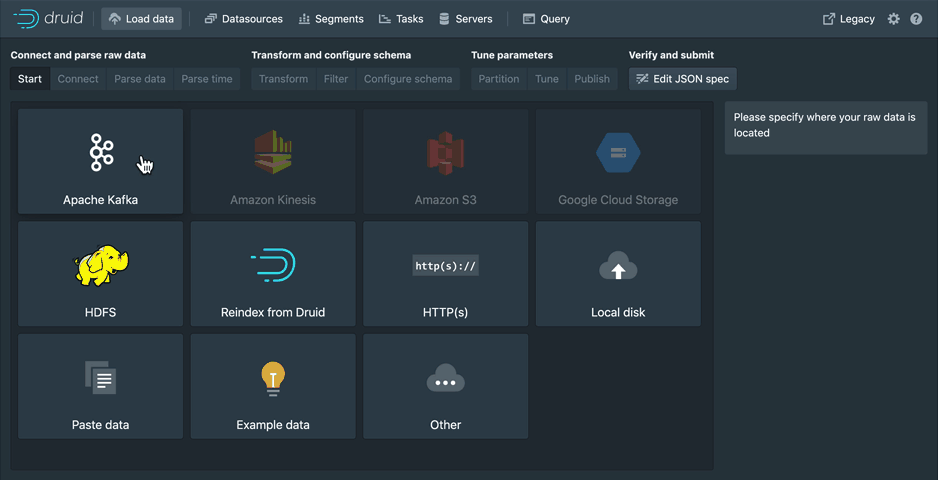
Load streaming and batch data using a point-and-click wizard to guide you through ingestion setup. Monitor one off tasks and ingestion supervisors.
Manage the cluster

Manage your cluster with ease. Get a view of your datasources, segments, ingestion tasks, and services from one convenient location. All powered by SQL systems tables, allowing you to see the underlying query for each view.
Issue queries
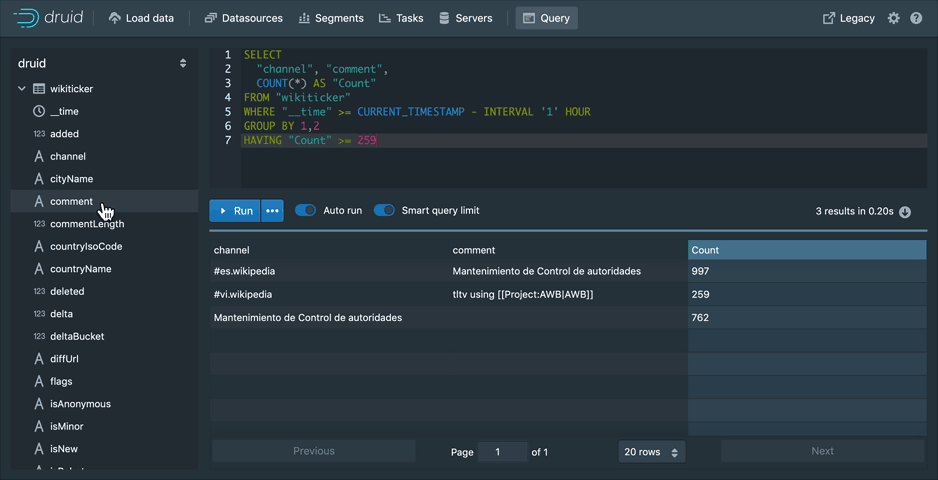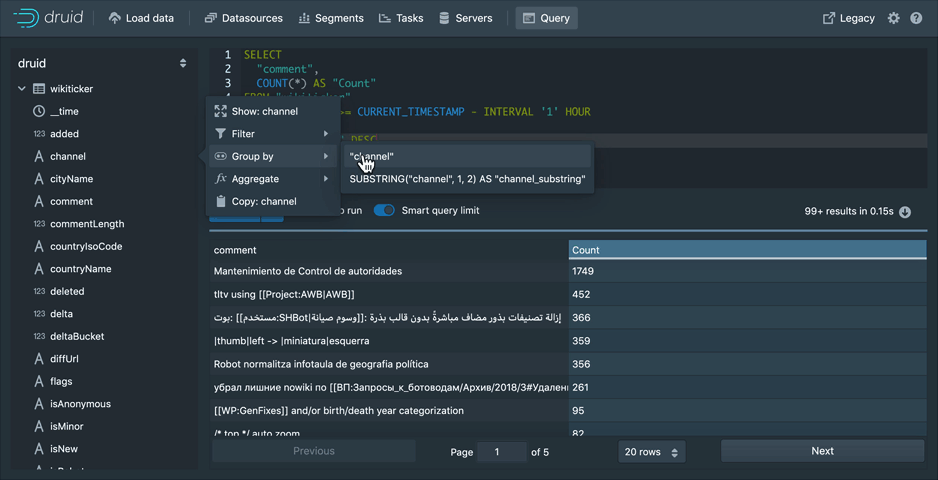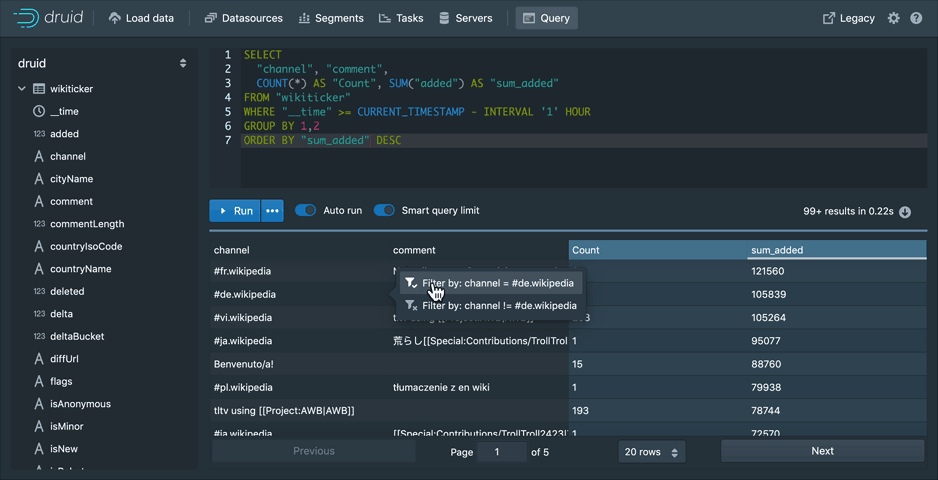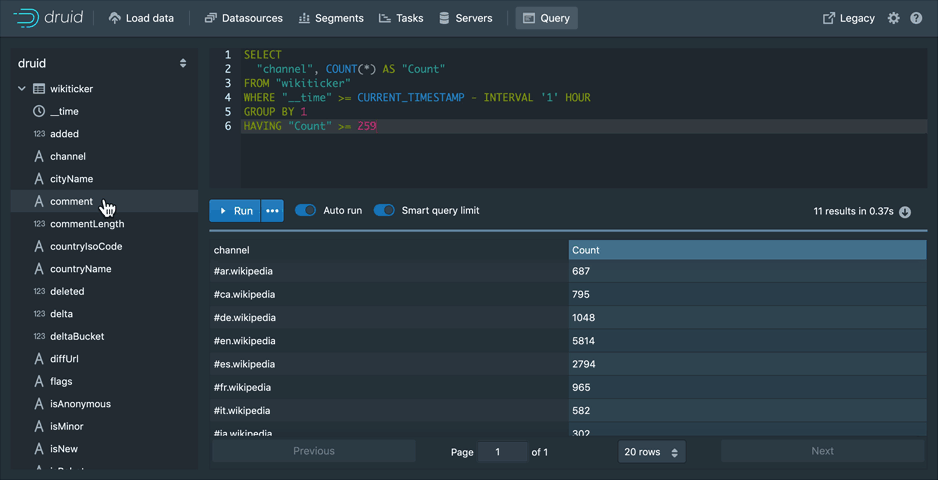
Use the built-in query workbench to prototype DruidSQL and native queries or connect one of the many tools that help you make the most out of Druid.
Documentation
See the latest documentation for the documentation for the current official release. If you need information on a previous release, you can browse previous releases documentation.
Make documentation and tutorials updates in /docs using Markdown or extended Markdown (MDX). Then, open a pull request.
To build the site locally, you need Node 22 or higher and to install Docusaurus 3 with npm|yarn install in the website directory. Then you can run npm|yarn start to launch a local dev preview of the docs.
If you're looking to update non-doc pages like Use Cases, those files are in the druid-website-src repo.
For more information, see the README in the ./website directory.
Community
Visit the official project community page to read about getting involved in contributing to Apache Druid, and how we help one another use and operate Druid.
- Druid users can find help in the
druid-usermailing list on Google Groups, and have more technical conversations in#troubleshootingon Slack. - Druid development discussions take place in the
druid-devmailing list ([email protected]). Subscribe by emailing [email protected]. For live conversations, join the#devchannel on Slack.
Check out the official community page for details of how to join the community Slack channels.
Find articles written by community members and a calendar of upcoming events on the project site - contribute your own events and articles by submitting a PR in the apache/druid-website-src repository.
Building from source
Please note that JDK 25 is required to build Druid.
See the latest build guide for instructions on building Apache Druid from source.
Contributing
Please follow the community guidelines for contributing.
For instructions on setting up IntelliJ dev/intellij-setup.md
License
Explore related projects
Asabeneh/30-Days-Of-Python
The 30 Days of Python programming challenge is a step-by-step guide to learn the Python programming language in 30 days. This challenge may take more than 100 days. Follow your own pace. These videos may help too: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,303 starsgrafana/grafana
The open and composable observability and data visualization platform. Visualize metrics, logs, and traces from multiple sources like Prometheus, Loki, Elasticsearch, InfluxDB, Postgres and many more.
77,725 starsredis/redis
For developers, who are building real-time data-driven applications, Redis is the preferred, fastest, and most feature-rich cache, data structure server, and document and vector query engine.
77,268 starsapache/superset
Apache Superset is a Data Visualization and Data Exploration Platform
75,439 stars