
alenisaw/awesome-kaz-models
alenisaw/awesome-kaz-models has 36 GitHub stars and 0 forks. GitHot measured +1 stars in 24 hours. Last checked 2026-11-12 13:58 UTC. Last push 2026-11-04.
Curated, research-grade catalog of public AI models with substantial support for the Kazakh language.
Measured star growth
- in 24h
- +1
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original
 Awesome Kazakh Models
A curated, research-grade catalog of public AI models with substantial support for the Kazakh language.


About · Text & NLP · Speech · Vision & OCR · Watchlist · Contributing · License
✨ Explore Kazakh datasets across every domain — awesome-kaz-datasets
About
Public Kazakh-capable models are scattered across Hugging Face, GitHub, and institutional pages, with no reliable map of what's actually obtainable today. A search for "Kazakh" mixes genuinely Kazakh-trained models with generic multilingual foundations, packaging clones of the same checkpoint, and paper-only experiments with no published weights.
Every entry below is checked against its primary source, with release date, license, access terms, and evidence of Kazakh training recorded rather than assumed. Resources that are announced or not yet independently verifiable go in the Watchlist instead of the main tables. See CONTRIBUTING.md for the full inclusion policy and CHANGELOG.md for what's new.
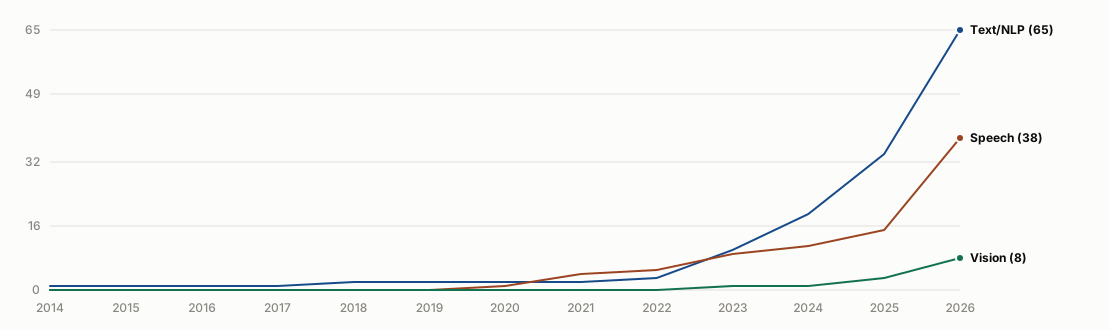
Cumulative Kazakh model-family releases over time, by section.
Text, NLP, and LLM
| ID | Released | Model | Task | Description | Storage | Parameters |
|---|---|---|---|---|---|---|
| 1 | 2026-10 | Qwen3-1.7B Kazakh Text-to-SQL (GRPO) Rakhat Masat Open |
QA | Kazakh natural-language to SQLite query translation model fine-tuned from Qwen3-1.7B-Base via a three-stage curriculum (SFT -> DPO -> GRPO with execution reward). | 3.22 GB | – ≈1.7B – Qwen3-1.7B (QLoRA SFT + DPO + GRPO) (base: Qwen/Qwen3-1.7B-Base) |
| 2 | 2026-10 | KazRoBERTa Spelling Detector Daniyar Open |
GEC · TC | Token classification model for detecting spelling and orthographic errors in Kazakh text, fine-tuned from kaz-roberta-conversational for the Turan Text Corrector. | 328.6 MB | – ≈110M – RoBERTa (token classification) (base: kz-transformers/kaz-roberta-conversational) |
| 3 | 2026-10 | Yandex-8B-WMT26 Yandex researchers Open |
MT | 8B causal language model fine-tuned for the WMT26 General Machine Translation shared task, translating English into Kazakh, Russian, Belarusian, and Armenian. | 14.97 GB | – ≈8B – YandexGPT-5-Lite-8B (base: yandex/YandexGPT-5-Lite-8B-pretrain) |
| 4 | 2026-09 | Kazakh Trilingual GLiNER Ardak Shalkar Open |
NER | Trilingual (Kazakh, Russian, English) zero-shot Named Entity Recognition model based on GLiNER (multilingual DeBERTa-v3), supporting open-vocabulary entity extraction without retraining. | 2.17 GB | – ≈209M – GLiNER (Multilingual DeBERTa-v3) (base: urchade/gliner_multi-v2.1) |
| 5 | 2026-09 | Darmm Chat Kazakh 8B Rakhat Zhumabek Open |
IF · TG | Conversational assistant for Kazakh (retaining Russian and English), trained as a QLoRA instruction fine-tune of Qwen3-8B on 105k instruction pairs (65k Kazakh). | 15.27 GB | – ≈8.2B – Qwen3-8B + QLoRA (base: Qwen/Qwen3-8B) |
| 6 | 2026-09 | Darmm Embed Kazakh v2 Rakhat Zhumabek Open |
EMB | Second-generation dense retrieval and text embedding model for Kazakh, fine-tuned from BAAI/bge-m3 on 373k Kazakh structural and cross-lingual pairs. | 2.13 GB | – ≈568M – BGE-M3 (XLM-RoBERTa, 1024-dim) (base: BAAI/bge-m3) |
| 7 | 2026-08 | ISSAI Qwen3.5 Kazakh ISSAI researchers Open |
LLM · IF | ISSAI's Kazakh adaptation of Qwen3.5 (4B/9B/35B-A3B), combining tokenizer-extended continued pretraining with a chat-vector merge that restores the official instruct alignment. | 70.3 GB | – 4B / 9B / 35B-A3B (MoE) – Qwen3.5 (dense 4B/9B; MoE 35B-A3B), continued-pretrained then chat-vector merged with the official instruct model (base: Qwen/Qwen3.5 family (4B / 9B / 35B-A3B)) |
| 8 | 2026-08 | Qwen3.8-27B Kazakh SFT (Tohirju) Tohir Saidzoda Gated |
IF | Kazakh instruction/tool-use fine-tune family (SFT, tool-calling, and GRPO-refined tool-calling variants) of a ~27B Qwen-architecture model, part of a multi-language (Tajik/Uzbek/Kyrgyz/Kazakh) fine-tune series by the same author. | 53.8 GB | – ≈26.9B – Qwen3.5-family text architecture (~27B; exact upstream base checkpoint undisclosed) |
| 9 | 2026-07 | Granite-278m-kk Tim2190 Open |
EMB | IBM Granite multilingual embedding model fine-tuned for Kazakh RAG/retrieval. | 556.1 MB | – 278M – Granite Embedding (base: ibm-granite/granite-embedding-278m-multilingual) |
| 10 | 2026-07 | Kimi-K3-0.40B Kazakh CPT (59M tokens) Yeraly Gainulla Open |
LLM | Experimental hybrid KDA+MLA+MoE Kimi-K3 checkpoint continued-pretrained on Kazakh text, having seen roughly 59 million cumulative Kazakh tokens. | 791.2 MB | – 395.6M – Kimi K3 (hybrid KDA + MLA + MoE, 8 layers, 8 routed experts top-2 + 1 shared expert) (base: inference-optimization/Kimi-K3-0.40B) |
| 11 | 2026-06 | Kazakh Morphological Analysis (QazCorpora ensemble) TilQazyna Gated |
MORPH | Ensemble of trained classifiers and small PyTorch lemmatization networks for Kazakh morphological analysis (part-of-speech attribute prediction and lemmatization), evaluated on the QazCorpora corpus. | 11.2 MB | – Ensemble: scikit-learn classifiers/vectorizers (joblib) for morphological attribute tagging plus small PyTorch feed-forward networks for lemma suffix/rule prediction |
| 12 | 2026-05 | FogGen ISSAI researchers Open |
IF | ISSAI research family (Qwen3/Gemma3-based, 270M-1.7B) exploring edge-cloud routing, verbalized confidence, and continual learning, trained with Kazakh-culture data. | 1.2 GB | – 270M-1.7B – Qwen3 / Gemma3 (base: Qwen3 / Gemma3 family) |
| 13 | 2026-05 | Kazakh E5 RAG embedding shyngys879 Open |
EMB | KazEmbed-V5 further fine-tuned for Kazakh RAG/retrieval on a Kazakh Wikipedia RAG dataset. | 1.1 GB | – 278M – XLM-RoBERTa (E5) (base: Nurlykhan/KazEmbed-V5) |
| 14 | 2026-04 | SozKZ Core Qwen 500M (kk base) Saken Tukenov Gated |
LLM | Qwen2-architecture Kazakh-only language model trained from scratch by an independent researcher. | 895.0 MB | – 447.5M – Qwen2 |
| 15 | 2026-04 | SozKZ Core TinyLlama kk-ru Saken Tukenov Gated |
LLM | Bilingual Kazakh-Russian continued pretraining of TinyLlama-1.1B via tokenizer extension and progressive multi-stage training. | 2.3 GB | – 1.14B – Llama (TinyLlama) (base: TinyLlama/TinyLlama-1.1B-intermediate-step-1431k-3T) |
| 16 | 2026-04 | EkiTil (bilingual Kazakh-Russian Qwen3 family) Saken Tukenov Gated |
LLM | Family of Qwen3-architecture bilingual Kazakh-Russian language models trained from scratch, in 123M/300M/600M sizes. | 2.7 GB | – 123M-674M – Qwen3 (causal LM, from scratch) |
| 17 | 2026-04 | SozKZ GEC (Qwen 500M) Saken Tukenov Gated |
GEC | Qwen-architecture 500M model iteratively fine-tuned for Kazakh grammatical error correction, via a preference-optimization pipeline. | 895.0 MB | – 447.5M – Qwen2 (base: sozkz-core-qwen-500m-kk-base) |
| 18 | 2026-04 | SozKZ mGPT kk-ru translation Saken Tukenov Gated |
MT | mGPT-1.3B-kazakh further fine-tuned for bilingual Kazakh-Russian translation. | 2.8 GB | – 1.42B – mGPT (base: ai-forever/mGPT-1.3B-kazakh) |
| 19 | 2026-04 | SozKZ NLLB-1B Kazakh GEC Saken Tukenov Gated |
GEC | NLLB-200-1.3B fine-tuned for Kazakh grammatical error correction (spelling, morphology, punctuation, word order), trained in a two-stage pretrain-then-finetune pipeline on synthetic and mixed GEC corpora. | 2.78 GB | – 1.37B – NLLB-200-1.3B (M2M100ForConditionalGeneration) (base: facebook/nllb-200-1.3B) |
| 20 | 2026-03 | SozKZ Core (Llama-family Kazakh base models) Saken Tukenov Gated |
LLM | Family of small Llama-architecture Kazakh language models trained from scratch by an independent researcher, ranging from 8M to ≈1.08B parameters. | 2.2 GB | – 8M-1.08B (multiple models) – Llama (GQA, from scratch) |
| 21 | 2026-02 | Darmm Text Generation (v2, Qwen2.5-Coder) Darmm Open |
TG | QLoRA adapter fine-tuning Qwen2.5-Coder-7B-Instruct for Kazakh instruction-following text generation. | 646.0 MB | – ≈7B base (QLoRA adapter ≈646MB) – Qwen2.5-Coder (QLoRA adapter) (base: Qwen/Qwen2.5-Coder-7B-Instruct) |
| 22 | 2026-02 | Tencent Kazakh 7B Adapter Defetya Open |
MT | LoRA adapter for tencent/HY-MT1.5-7B that outputs Kazakh in Cyrillic script (the base model defaults to Arabic script) for Russian-to-Kazakh translation. | 54.6 MB | – LoRA adapter over tencent/HY-MT1.5-7B (base: tencent/HY-MT1.5-7B) |
| 23 | 2026-01 | Darmm Text Generation (v1, mT5) Darmm Open |
TG | mT5-base fine-tuned for Kazakh text generation. | 3.9 GB | – 966.6M – mT5 (base: google/mt5-base) |
| 24 | 2026-01 | Kazakh Question Answering (mBERT KazQAD) Rayvan Open |
QA | Multilingual BERT fine-tuned on the KazQAD dataset for extractive question answering in Kazakh. | 709.1 MB | – 177.3M – BERT (multilingual) (base: google-bert/bert-base-multilingual-cased) |
| 25 | 2026-01 | Kazakh Sentiment BERT R3iwan Open |
SC | mBERT fine-tuned for 3-class Kazakh sentiment classification on entertainment reviews. | 711.4 MB | – 177.9M – BERT (multilingual) (base: google-bert/bert-base-multilingual-cased) |
| 26 | 2026-01 | Darmm Kazakh Sentiment Darmm Open |
SC | mBERT fine-tuned for Kazakh sentiment classification. | 711.5 MB | – ≈177.9M – BERT (multilingual) (base: google-bert/bert-base-multilingual-cased) |
| 27 | 2026-01 | Darmm Embedding Multilingual Darmm Open |
EMB | BGE-M3 fine-tuned for Kazakh/Russian/English multilingual sentence embeddings. | 2.3 GB | – 567.8M – BGE-M3 (base: BAAI/bge-m3) |
| 28 | 2026-01 | Qwen2.5-3B History of Kazakhstan Ramazan Syrlybay Open |
QA | Qwen2.5-3B QLoRA-fine-tuned on an 11th-grade Kazakhstan history textbook for Kazakh/Russian/English question answering. | 6.2 GB | – ≈3.09B – Qwen2.5 (QLoRA fine-tune, merged) (base: Qwen/Qwen2.5-3B) |
| 29 | 2025-12 | KazBERT-NERD Eraly-ml Open |
NER | KazBERT fine-tuned for Kazakh named-entity recognition on KazNERD. | 440.3 MB | – 110.1M – BERT (base: Eraly-ml/KazBERT) |
| 30 | 2025-12 | KazEmbed-V5 Nurlykhan Open |
EMB | multilingual-e5-base fine-tuned on 61,255 Kazakh pairs (KazQAD, KazQAD-Retrieval, Kazakh dialogue) for retrieval-quality Kazakh embeddings. | 1.1 GB | – 278M – XLM-RoBERTa (E5) (base: intfloat/multilingual-e5-base) |
| 31 | 2025-11 | Kaz-RoBERTa NER shoplikov Open |
NER | Kaz-RoBERTa Conversational fine-tuned for Kazakh named-entity recognition on KazNERD. | 331.6 MB | – 82.9M – RoBERTa (base: kz-transformers/kaz-roberta-conversational) |
| 32 | 2025-11 | XLM-RoBERTa Kazakh POS Tagger (TilQazyna) TilQazyna Gated |
POS | XLM-RoBERTa fine-tuned for Kazakh part-of-speech tagging, with per-tag performance and confusion-matrix evaluation artifacts included in the repo. | 1.1 GB | – ≈278.1M – XLM-RoBERTa (token classification) (base: FacebookAI/xlm-roberta-base) |
| 33 | 2025-10 | e5-base-kazakh sultanbi Open |
EMB | multilingual-e5-base fine-tuned on Kazakh-translated NLI (SNLI) pairs for Kazakh sentence embeddings. | 1.1 GB | – 278M – XLM-RoBERTa (E5) (base: intfloat/multilingual-e5-base) |
| 34 | 2025-05 | KazBERT Duplicates Yeraly Gainulla Open |
TC | KazBERT fine-tuned on the KazakhTextDuplicates dataset for semantic duplicate and near-duplicate text detection in Kazakh. | 442.5 MB | – 110.6M – BERT (base: Eraly-ml/KazBERT) |
| 35 | 2025-04 | DalaT5 crossroderick Open |
TR | T5-small fine-tuned for Kazakh Cyrillic-to-Latin transliteration. | 258.4 MB | – 64.6M – T5-small (base: t5-small) |
| 36 | 2025-04 | HPLT Kazakh-English MT HPLT Project Open |
MT | HPLT project's bidirectional Kazakh-English translation models, trained on HPLT parallel data only. | 615.9 MB | – Transformer (Marian-style) |
| 37 | 2025-04 | HPLT+OPUS Kazakh-English MT HPLT Project Open |
MT | HPLT project's bidirectional Kazakh-English translation models, trained on HPLT parallel data augmented with OPUS corpora. | 615.9 MB | – Transformer (Marian-style) |
| 38 | 2025-03 | KazBERT Eraly-ml Open |
MLM | BERT-style masked-language model pretrained with a Kazakh-tailored tokenizer on Kazakh/Russian/English web and Wikipedia text. | 442.6 MB | – 110.7M – BERT |
| 39 | 2025-03 | RoBERTa Large KazQAD Informatics Arailym Tleubayeva Open |
QA | RoBERTa Large KazQAD further fine-tuned for informatics/computer-science domain QA in Kazakh. | 1.4 GB | – 354.3M – RoBERTa-large (base: nur-dev/roberta-large-kazqad) |
| 40 | 2025-03 | Arailym Kazakh text classifier Arailym Tleubayeva Open |
TC | RoBERTa Kazakh Large fine-tuned for text classification on a curated small Kazakh corpus. | 1.4 GB | – 355.4M – RoBERTa-large (base: nur-dev/roberta-kaz-large) |
| 41 | 2025-02 | Sherkala-Chat 8B Sherkala research team Gated |
LLM · IF | Kazakh-primary instruction-tuned Llama 3.1 adaptation continued-pretrained on 45.3B multilingual tokens and aligned with multilingual, Kazakhstan-specific, and Kazakh safety instructions. | 66.3 GB | – ≈8.29B – Llama 3.1 (8B) with a Kazakh-balanced expanded tokenizer (base: meta-llama/Llama-3.1-8B) |
| 42 | 2025-02 | Llama 3.1 8B kk-ru PolynomeAI Open |
MT | Llama 3.1 8B fine-tuned for bidirectional Russian-Kazakh translation. | 27.3 MB | – 8B – Llama 3.1 (base: meta-llama/Llama-3.1-8B) |
| 43 | 2025-01 | Kundyzka Informatics QA (mBERT) Kundyz Maksutova Open |
QA | mBERT fine-tuned for Kazakh informatics/computer-science question answering. | Not reported | – BERT (multilingual) (base: google-bert/bert-base-multilingual-cased) |
| 44 | 2024-12 | KazLLM 1.0 ISSAI researchers Gated |
LLM | Kazakh-focused Llama 3.1 adaptation released in 8B and 70B variants by ISSAI. | 16.1 GB | – 8B / 70B – Llama 3.1 (base: Meta Llama 3.1) |
| 45 | 2024-10 | KazRush kk-ru deepvk Open |
MT | T5-based Kazakh-to-Russian machine translation model trained on KazParC. | 787.9 MB | – 197M – T5 |
| 46 | 2024-09 | llama-kaz-instruct-8B-1 TilQazyna Gated |
IF | Llama 3 8B continued-pretrained and instruction-tuned for Kazakh by the TilQazyna team. | 16.1 GB | – 8B – Llama 3 (base: meta-llama/Meta-Llama-3-8B) |
| 47 | 2024-08 | Llama 1.9B Kazakh nur-dev Gated |
LLM | 1.9B-parameter Llama-architecture model trained from scratch on Kazakh text. | 7.8 GB | – 1.94B – Llama |
| 48 | 2024-08 | RoBERTa Large KazQAD nur-dev Open |
QA | RoBERTa Kazakh Large fine-tuned for extractive question answering on KazQAD. | 1.4 GB | – 354.3M – RoBERTa-large (base: nur-dev/roberta-kaz-large) |
| 49 | 2024-07 | RoBERTa Kazakh Large nur-dev Open |
MLM | RoBERTa-large trained from scratch on a multidomain Kazakh corpus; serves as the base for several downstream QA/classification fine-tunes in this catalog. | 1.4 GB | – 355.4M – RoBERTa-large |
| 50 | 2024-06 | Nothingger Literary Translation Nothingger Open |
MT | Tilmash fine-tuned on a Kazakh-Russian-English literary parallel corpus for literary-domain translation. | 5.5 GB | – 1.37B – NLLB/M2M100-derived (via Tilmash) (base: issai/tilmash) |
| 51 | 2024-04 | HPLT BERT Base Kazakh HPLT Project Open |
MLM | LTG-BERT-style monolingual encoder for Kazakh, one of many per-language models in the HPLT project's second data/model release. | 625.8 MB | – ≈153M – LTG-BERT (encoder) |
| 52 | 2024-03 | Irbis-7B Gen2B Open |
LLM | Mistral-7B-architecture Kazakh language model with a tokenizer expanded from 32k to 60k tokens and continued-pretrained on a predominantly Kazakh (with some Russian) corpus. | 14.9 GB | – ≈7.47B – Mistral (7B) |
| 53 | 2023-12 | Llama 2 Kazakh 7B (ver2) Mussa Aman Open |
QA | Llama 2 7B fine-tuned for Kazakh-language question answering, the second (ver2) iteration of an instruction fine-tune trained on a self-instruct Kazakh dataset. | 13.5 GB | – ≈6.74B – Llama 2 (7B) (base: meta-llama/Llama-2-7b-hf) |
| 54 | 2023-10 | KazSAnDRA RemBERT (polarity classification) ISSAI researchers Gated |
SC | RemBERT fine-tuned for Kazakh sentiment polarity classification on the KazSAnDRA review dataset. | 2.3 GB | – RemBERT (base: google/rembert) |
| 55 | 2023-10 | Tilmash ISSAI researchers Gated |
MT | ISSAI's NLLB-based machine translation model for Kazakh, Russian, English, and Turkish (12 directional pairs), trained on the KazParC corpus. | 5.5 GB | – 1.37B – NLLB-200-distilled-1.3B (fine-tuned) (base: facebook/nllb-200-distilled-1.3B) |
| 56 | 2023-08 | mGPT 1.3B Kazakh AI Forever (Sber AI) Open |
LLM · TG | Multilingual 1.3B GPT model continuously pretrained on Kazakh web and corpus text for 150,000 steps to specialize for Kazakh text generation. | 5.8 GB | – 1.3B – mGPT (GPT-2-based multilingual causal LM) (base: ai-forever/mGPT) |
| 57 | 2023-05 | XLM-R Large KazNERD Rustem Yeshpanov Open |
NER | XLM-RoBERTa-large fine-tuned for Kazakh named-entity recognition on KazNERD. | 2.2 GB | – 558.9M – XLM-RoBERTa-large (base: FacebookAI/xlm-roberta-large) |
| 58 | 2023-05 | KazakhBERTmulti Amandyk Kartbayev Open |
MLM | BERT masked-language model trained on Kazakh text with a large (100k-token) Kazakh-tailored vocabulary — despite the "multi" in its name, a Kazakh-only model. | 651.8 MB | – ≈163.0M – BERT |
| 59 | 2023-04 | Kaz-RoBERTa Conversational kz-transformers Open |
MLM | RoBERTa-base trained from scratch on a 25GB multidomain Kazakh corpus spanning formal and conversational text. | 334.0 MB | – 83.5M – RoBERTa |
| 60 | 2022-09 | Uzbek-Kazakh Machine Translation Sanatbek Matlatipov Open |
MT | Transformer (JoeyNMT) machine translation model trained from scratch for Uzbek-to-Kazakh translation, released with training-step checkpoints and dev/test hypothesis files. | 174.0 MB | – Transformer (JoeyNMT toolkit; 6 encoder/decoder layers, 4 attention heads, 256-dim embeddings) |
| 61 | 2018 | fastText Kazakh word vectors (cc.kk.300) E. Grave, P. Bojanowski, P. Gupta, A. Joulin, T. Mikolov Open |
EMB | CBOW word embeddings with character n-grams trained on Common Crawl and Wikipedia Kazakh text, part of Facebook AI's 157-language release. | 4.5 GB | – fastText CBOW + character n-grams |
| 62 | 2014-05 | Apertium Kazakh morphological transducer (apertium-kaz) Washington et al. Open |
MORPH · POS | Free and open-source rule-based finite-state morphological analyzer, generator, and constraint-grammar POS tagger for Kazakh with 22K+ lexical stems. | 14.5 MB | – Finite-state transducer (HFST / lttoolbox / Constraint Grammar) |
| 63 | Unknown | Stanza Kazakh pipeline (kk_ktb) Stanford NLP Group Open |
POS · DEP | Stanford Stanza's Kazakh Universal Dependencies pipeline (tokenize/POS/lemma/dependency parsing), trained on the KTB treebank. | 400.2 MB | – Stanza UD pipeline (biaffine parser + neural taggers) |
Speech and audio
| ID | Released | Model | Task | Description | Storage | Parameters |
|---|---|---|---|---|---|---|
| 1 | 2026-11 | Nemotron-3.5-Transcribe-kk-v2 Sherkhan243 Open |
ASR | Kazakh speech recognition fine-tune of NVIDIA Nemotron-3.5-Transcribe-30B-A4B with hybrid Mamba-Transformer MoE backbone, producing punctuated and cased Kazakh transcripts. | 62.89 GB | – 30B (4.3B active) – Hybrid Mamba-Transformer MoE (~4.3B active / 30B total), LoRA (base: nvidia/NVIDIA-Nemotron-3.5-Transcribe-30B-A4B) |
| 2 | 2026-10 | k5 Kazakh-Russian STT (streaming, 600M) Alibi Serikbay Open |
ASR | Streaming Conformer-CTC speech-to-text model for Kazakh, Russian, and code-switched speech fine-tuned from GigaAM-Multilingual on 2,364 hours of speech with KenLM decoding and inverse text normalization. | 11.81 GB | – 600M – Conformer-CTC (streaming) + KenLM (base: ai-sage/GigaAM-Multilingual (large_ctc)) |
| 3 | 2026-10 | k5 Kazakh OmniVoice Alibi Serikbay Open |
TTS | Zero-shot text-to-speech and voice cloning model for Kazakh and Russian fine-tuned from OmniVoice (diffusion LM on Qwen3-0.6B backbone) on KazakhTTS2 and KazEmoTTS. | 2.3 GB | – ≈613M – OmniVoice (diffusion LM on Qwen3-0.6B backbone) (base: k2-fsa/OmniVoice) |
| 4 | 2026-09 | Kazakh-Russian Mixed STT Alibi Serikbay Open |
ASR | Acoustic speech recognition model tailored for mixed Kazakh-Russian conversational speech, telephony, and code-switching, built on Wav2Vec2 with CTC and KenLM decoding. | 8.63 GB | – ≈317M – Wav2Vec2 + CTC + KenLM |
| 5 | 2026-08 | Chatterbox Multilingual Kazakh (t3 fine-tune) Saidzoda Lab Gated |
TTS | Fine-tune of the t3 text-to-speech-token transformer of Chatterbox Multilingual for Kazakh Cyrillic voice cloning, with the s3gen and voice-encoder components frozen from the base model. | 3.21 GB | – Chatterbox Multilingual (t3 text-token transformer fine-tuned; s3gen + voice encoder frozen from base) (base: ResembleAI/chatterbox) |
| 6 | 2026-08 | CosyVoice3 Kazakh (499k-sample fine-tune) Saidzoda Lab Gated |
TTS | Fine-tune of the CosyVoice3-0.5B LLM component for Kazakh zero-shot text-to-speech, trained on 499,627 curated Kazakh audio clips with the flow/vocoder components retained from the base model. | 5.42 GB | – CosyVoice3 (LLM component fine-tuned; flow/vocoder components unchanged from base) (base: FunAudioLLM/CosyVoice3-0.5B) |
| 7 | 2026-07 | GigaAM Multilingual Kuzmenko et al. Open |
ASR | Conformer-based multilingual speech foundation and CTC ASR family (220M/600M), pretrained on 2 million hours across more than 70 languages and fine-tuned for Russian, English, Kazakh, Kyrgyz, and Uzbek. | 2.3 GB | – 220M / 600M – Conformer encoder + character-wise CTC |
| 8 | 2026-07 | Persona-ASR ISSAI, Nazarbayev University Open |
TS-ASR | Bilingual Kazakh-English target-speaker ASR system that transcribes only an enrolled speaker in overlapping/multi-speaker mixtures, rejecting non-target speech. | 1.2 GB | – ECAPA-TDNN + WavLM-Base+ (FiLM-modulated, multi-head CTC) (base: microsoft/wavlm-base-plus) |
| 9 | 2026-07 | KazakhTTS OmniVoice Shyngys Kozhakhmetov Open |
TTS | OmniVoice multilingual voice-design and speech-synthesis model fine-tuned on ISSAI KazakhTTS2 and synthetic voice-design data for Kazakh text-to-speech. | 2.5 GB | – 612.6M – OmniVoice (base: k2-fsa/OmniVoice) |
| 10 | 2026-07 | Kokoro TTS Kazakh (km_m1) Mambetaly et al. Open |
TTS | Lightweight 82M single-speaker Kazakh text-to-speech voice built by fine-tuning Kokoro-82M on ISSAI KazakhTTS2 with a StyleTTS2 pipeline, running in real-time on CPU. | 313.7 MB | – 82M – Kokoro-82M (StyleTTS2) (base: hexgrad/Kokoro-82M) |
| 11 | 2026-06 | Kazakh Whisper Large-v3 Turbo (shyngys879) Shyngys Sovetkhan Open |
ASR | Full fine-tune of Whisper Large-v3 Turbo for Kazakh ASR, merged into a standalone Transformers model (no LoRA required), trained on eight public Kazakh speech datasets. | 1.6 GB | – ≈0.8B – Whisper large-v3-turbo full fine-tune (base: openai/whisper-large-v3-turbo) |
| 12 | 2026-06 | Kazakh Omni ASR CTC (nileq) Nurislam Open |
ASR | Wav2Vec2-style CTC Kazakh ASR model built on the OmniASR/wav2vec2.5-large architecture via the fairseq2/omnilingual-asr framework. | 1.3 GB | – ≈0.3B – Wav2Vec2ForCTC (24 layers, 1024 hidden) |
| 13 | 2026-05 | IndexTTS2 Kazakh (GPT fine-tune) AnuarSv Open |
TTS | Fine-tune of the GPT component of IndexTTS-2 for Kazakh speech synthesis, trained on a single-speaker 4.8GB subset of the ISSAI-KSC2-Structured dataset; voice cloning does not generalize beyond the training speaker. | 16.62 GB | – IndexTTS-2 GPT component fine-tune (2,000-token Kazakh-specific BPE vocabulary) (base: IndexTeam/IndexTTS-2) |
| 14 | 2026-05 | KRASR Kazakh-Russian Whisper-Small (full fine-tune) Madiyar & Danial Open |
ASR | Fully fine-tuned Whisper-small model for Kazakh and Kazakh-Russian code-switched automatic speech recognition, developed as Astana IT University thesis research. | 967.0 MB | – 241.7M – Whisper-small full fine-tune (WhisperForConditionalGeneration) (base: openai/whisper-small) |
| 15 | 2026-04 | Musa505 Kazakh Whisper ASR Musa505 Open |
ASR | Despite the repository name "kazakh-tts," this is a Whisper-small fine-tune for Kazakh automatic speech recognition, not a text-to-speech model — pipeline_tag, architecture, and the model card all describe ASR. | 967.0 MB | – 241.7M – Whisper-small full fine-tune (WhisperForConditionalGeneration) (base: openai/whisper-small) |
| 16 | 2026-03 | Whisper Large v3 Tulpar Olzhas Alseitov Open |
ASR | Full fine-tune of Whisper Large v3 for Kazakh ASR, combining ISSAI KSC, Farabi-Lab, FLEURS kk_kz, and curated YouTube audio. | 6.2 GB | – 1.55B – Whisper large-v3 full fine-tune (base: openai/whisper-large-v3) |
| 17 | 2026-03 | SozKZ OmniAudio Saken Tukenov Gated |
ASR | Family of from-scratch Kazakh ASR models (CTC and encoder-decoder variants) ranging from ≈50M to ≈1B parameters, trained entirely on Kazakh speech with no pretrained components. | 278.4 MB | – 50M-1B (multiple model sizes) – Custom encoder-decoder (Llama-style decoder: RoPE, RMSNorm, SwiGLU) |
| 18 | 2026-03 | Qwen3-TTS Kazakh Emotional futureDoctor Open |
TTS | Qwen3-TTS-12Hz-1.7B-Base fine-tune for emotional Kazakh speech synthesis, trained on a single female speaker with six emotion categories. | 3.1 GB | – 1.92B – Qwen3-TTS (Qwen3TTSForConditionalGeneration, includes bundled speech tokenizer) (base: Qwen/Qwen3-TTS-12Hz-1.7B-Base) |
| 19 | 2026-03 | VibeVoice ASR Kazakh InflexionLab Open |
ASR | LoRA fine-tune (merged weights) of Microsoft's VibeVoice-ASR model for Kazakh speech recognition, trained on roughly 1,200 hours of Kazakh speech spanning six domains. | 17.35 GB | – 8.67B – VibeVoice-ASR, LoRA fine-tuned with merged weights (VibeVoiceForASRTraining) (base: microsoft/VibeVoice-ASR) |
| 20 | 2026-02 | VoxCPM Kazakh TTS LoRA ErnarBahat Open |
TTS | LoRA adapter (rank 32, alpha 16) for VoxCPM1.5 that adds Kazakh text-to-speech and zero-shot voice cloning while retaining the base model's Chinese/English capability. | 98.6 MB | – LoRA adapter (rank 32) over openbmb/VoxCPM1.5 – VoxCPM1.5 + LoRA adapter (rank 32, alpha 16) (base: openbmb/VoxCPM1.5) |
| 21 | 2026-01 | Spark-TTS Kazakh ErnarBahat Open |
TTS | Kazakh fine-tune of Spark-TTS supporting both Cyrillic and Töte Zhazu (Latin-based) script input, with voice cloning from 3-10 seconds of reference audio. | 3.1 GB | – Spark-TTS (BiCodec + LLM inference engine) (base: SparkAudio/Spark-TTS-0.5B) |
| 22 | 2025-09 | Estimin3n Bekzat Uteulin Open |
ASR · LLM | Gemma 3n audio-text-to-text fine-tune for Kazakh speech transcription and Kazakh/Russian conversational response generation. | 15.7 GB | – ≈8B – Gemma 3n (LoRA SFT, audio + text submodules) (base: unsloth/gemma-3n-E4B-it) |
| 23 | 2025-05 | Keyword-MLP LangID / SCR (Kazakh) Artur Muratov Open |
KWS · LID | Unified multitask Keyword-MLP model performing speech command recognition and language identification, with a dedicated Kazakh-only model alongside multilingual LangID variants. | 5.2 MB | – Keyword-MLP (multitask SCR + LangID) |
| 24 | 2025-05 | Whisper Turbo KSC2 (abilmansplus) abilmansplus Open |
ASR | Whisper Large-v3-Turbo fine-tuned for Kazakh ASR on KSC2, with a bilingual Kazakh-Russian LoRA adapter variant built on top of it. | 3.2 GB | – ≈0.8B – Whisper large-v3-turbo full fine-tune + LoRA adapter (base: openai/whisper-large-v3-turbo) |
| 25 | 2025-03 | AIT-ASR Nurgali Kadyrbek Gated |
ASR | Whisper-small fine-tune for Kazakh automatic speech recognition, trained on the farabi-lab/kazakh-stt dataset. | 967.0 MB | – ≈244M – Whisper small fine-tune (base: openai/whisper-small) |
| 26 | 2024-08 | Whisper Base Kazakh (akuzdeuov) akuzdeuov Open |
ASR | Whisper base fine-tuned for Kazakh ASR on the KSC2 corpus. | 290.4 MB | – ≈74M – Whisper base fine-tune (base: openai/whisper-base) |
| 27 | 2024 | KazEmoTTS ISSAI, Nazarbayev University Open |
TTS | Emotional text-to-speech model for Kazakh (six emotion categories) using Grad-TTS with a HiFi-GAN vocoder. | 243.9 MB | – Grad-TTS + HiFi-GAN vocoder |
| 28 | 2023-09 | MMS-TTS Kazakh (facebook/mms-tts-kaz) MMS project team Open |
TTS | Per-language Kazakh (kaz) VITS text-to-speech checkpoint from Meta's Massively Multilingual Speech (MMS) project. | 145.2 MB | – ≈36.3M – VITS (per-language checkpoint) |
| 29 | 2023 | TurkicASR Mussakhojayeva et al. Open |
ASR | Multilingual ESPnet Transformer ASR system covering ten Turkic languages including Kazakh, released as joint "Turkic languages" and "all languages" downloadable archives. | 609.0 MB | – ESPnet Transformer, multilingual joint training |
| 30 | 2023 | Multilingual Speech Command Recognition (Keyword-MLP) ISSAI, Nazarbayev University Open |
KWS | Keyword-MLP keyword-spotting classifier with a dedicated Kazakh monolingual model (Mono-35-kk) plus multilingual Kazakh/Tatar/Russian variants, for voice-controlled robotics and smart systems. | Not reported | – Keyword-MLP classifier |
| 31 | 2023 | TurkicTTS Yeshpanov et al. Open |
TTS | Cross-Turkic TTS system whose acoustic model is trained solely on Kazakh data and extended to nine other Turkic languages via IPA-based transliteration. | 122.9 MB | – Tacotron2 + ParallelWaveGAN (IPA-based cross-lingual transliteration) |
| 32 | 2022 | KSC2 Kazakh ASR (best-performing model) Mussakhojayeva et al. Open |
ASR | ESPnet Transformer ASR model with language-model rescoring, trained on the large-scale KSC2 Kazakh speech corpus; the best-performing model from the KSC2 paper. | 544.0 MB | – ESPnet Transformer ASR + language model rescoring |
| 33 | 2021-04 | KazakhTTS Mussakhojayeva et al. Open |
TTS | Open-source Kazakh text-to-speech acoustic and vocoder models, later expanded by the KazakhTTS2 corpus/models. | 614.8 MB | – Tacotron2 / FastSpeech acoustic models + Parallel WaveGAN vocoders |
| 34 | 2021 | IS2AI Multilingual ASR (Kazakh-Russian-English) ISSAI, Nazarbayev University Open |
ASR | Large Transformer ASR system with monolingual Kazakh, Russian, and English variants plus combined/independent multilingual variants, from the ISSAI multilingual ASR study. | 288.0 MB | – Large Transformer (ESPnet) |
| 35 | 2021 | Wav2Vec2-Large-XLSR-53 Kazakh aismlv Open |
ASR | Community fine-tune of wav2vec2-large-XLSR-53 for Kazakh CTC ASR, produced during Hugging Face's 2021 XLSR Fine-Tuning Week. | 1.3 GB | – ≈0.3B – wav2vec2-large-XLSR-53 fine-tune (CTC) (base: facebook/wav2vec2-large-xlsr-53) |
| 36 | 2020-10 | SAIDA Kazakh ASR Mussakhojayeva et al. Open |
ASR | ESPnet Transformer ASR baseline released with the original Kazakh Speech Corpus (KSC), one of the first open Kazakh ASR models. | 126.6 MB | – ESPnet Transformer encoder-decoder ASR |
| 37 | Unknown | Piper Kazakh Voices Open |
TTS | Three official Kazakh (kk_KZ) voices — iseke, issai, raya — in the Piper/VITS neural TTS voice catalog, trained from scratch on the IS2AI KazakhTTS dataset. | 184.1 MB | – VITS (Piper) |
Vision, OCR, and multimodal
| ID | Released | Model | Task | Description | Storage | Parameters |
|---|---|---|---|---|---|---|
| 1 | 2026-09 | Darmm Kazakh OCR VL-3B Rakhat Zhumabek Open |
OCR | Vision-language OCR model fine-tuned from Qwen2.5-VL-3B-Instruct for printed Kazakh Cyrillic text, reading entire document pages and line/word crops directly without an external text detector. | 7.0 GB | – ≈3.75B – Qwen2.5-VL-3B-Instruct + LoRA (base: Qwen/Qwen2.5-VL-3B-Instruct) |
| 2 | 2026-07 | TurkicOCR-SVTRv2-B Issayev & Zhalgas Open |
OCR | Lightweight (≈35M-parameter) line-grounded OCR recognizer for Kazakh and Kyrgyz Cyrillic script (plus Russian mixed text), built on SVTRv2-B with a CTC head. | 90.1 MB | – ≈35M – SVTRv2-B (OpenOCR) + CTC (base: OpenOCR/SVTRv2-B) |
| 3 | 2026-05 | Kazakh TrOCR (fine-tuned) Kamilya Nazarkhanova Open |
OCR | TrOCR vision-encoder-decoder model fine-tuned specifically for Kazakh printed-text OCR, adapted from a Russian-handwritten TrOCR model with token embeddings resized for nine Kazakh-specific Cyrillic letters. | 1.3 GB | – ≈334M – VisionEncoderDecoder (TrOCR) (base: kazars24/trocr-base-handwritten-ru) |
| 4 | 2026-04 | Qolda-AVL Arystanbekov et al. Open |
AVL | Audio-vision-language extension of Qwen3-VL adding a fine-tuned Whisper encoder and audio-projection module, with all three modalities adapted to Kazakh. Released as 5B/9B/34B variants sharing one architecture and training recipe. | Not reported | – 5B / 9B / 34B – Qwen3-VL-Thinking + Whisper-large-v3-turbo (DeepStack audio projection) (base: Qwen3-VL-Thinking + openai/whisper-large-v3-turbo) |
| 5 | 2026-04 | Beynele Aikyn et al. Open |
T2I | Lumina-Image 2.0-based text-to-image diffusion transformer adapted for Kazakh-language prompts and Kazakh cultural visual content via a data-centric fine-tuning pipeline. | 26.5 GB | – ≈2.6B – Lumina-Image 2.0 (flow-based diffusion transformer) (base: Alpha-VLLM/Lumina-Image-2.0 + google/gemma-2-2b) |
| 6 | 2025-12 | HordeVision Zubitskii et al. Gated |
OCR · IC · VLM | Kazakh vision-language model built on a 4-bit-quantized Qwen3-VL-8B-Instruct, fine-tuned via SFT + GRPO on roughly 50,000 culturally relevant Kazakh images for OCR, captioning, VQA, reasoning, and instruction-following. | 6.4 GB | – ≈8.8B (4-bit quantized) – Qwen3-VL-8B-Instruct (4-bit) + LoRA SFT + GRPO (base: Qwen/Qwen3-VL-8B-Instruct) |
| 7 | 2025-11 | Qolda Arystanbekov et al. Open |
VLM · OCR | Compact vision-language model combining InternVL3.5's InternViT-300M encoder/projector with a Qwen3-4B language model, explicitly trained and evaluated for Kazakh alongside Russian and English. | 8.7 GB | – ≈4.3B – InternViT-300M + MLP projector (from InternVL3.5-4B) + Qwen3-4B (base: OpenGVLab/InternVL3_5-4B + Qwen/Qwen3-4B) |
| 8 | 2023-02 | Kazakh Image Captioning (ExpansionNet v2) Arystanbekov et al. Open |
IC | ExpansionNet v2 image-captioning model fine-tuned to generate Kazakh-language captions, trained on COCO images with captions machine-translated into Kazakh. | 2.7 GB | – ExpansionNet v2 |
Watchlist / announced resources
Resources below are announced, described in a paper without a public artifact, of unclear provenance, or not yet independently verifiable as substantively Kazakh-trained models. They are intentionally not part of the main catalog above, but could plausibly still qualify once verification succeeds.
- Söyle — The IS2AI GitHub repository and its ICAIIC 2024 paper are real, but the only pretrained-model link in the README (
dhcppc0/soyle_onnxon Hugging Face) resolves to HTTP 401 (invalid credentials) for anonymous access — not independently obtainable. The official ISSAI project page links the code and a companion dataset but no model under theissaiorg — currently training-code-only, the same pattern as the official KazNERD repository. - AIT-Syn Kazakh TTS — A Qwen3-TTS-12Hz-1.7B-Base fine-tune for Kazakh/Russian/English/Uzbek voice cloning (
nur-dev/ait-syn-4L) is real and was indexed with a full model card (confirmed via third-party search results), but the repository currently returns HTTP 401 for anonymous access at both the API and page level — unlike the org's other gated repos (e.g.nur-dev/ait-asr), whose cards remain publicly readable. Could not be independently re-verified this pass. - Darmm Kazakh Cyrillic OCR — A VisionEncoderDecoderModel with real, downloadable safetensors weights (333.9M F32 params) exists at
Darmm/darmm-ocr-kazakh-cyrillic-modeland is presumably a Kazakh Cyrillic OCR model based on its name and architecture, but the repository carries no model card, no license, no stated training data, and no evaluation metrics — there is currently no primary-source basis to confirm its architecture details, training corpus, or actual OCR performance. - Kazakh HTR model — A VisionEncoderDecoderModel with real, downloadable safetensors weights (61.6M F32 params, size consistent with the claimed parameter count) exists at
abacoding/kazakh-htr-modeland is presumably a Kazakh handwriting-recognition model based on its name, but the repository has no model card, no license, and no documented training data or evaluation — its task, training corpus, and accuracy cannot currently be independently verified. - TilQazyna Kazakh morphology (Qwen LoRA) — A LoRA adapter for structured Kazakh morphological analysis (
TilQazyna/kazakh-morpho-qwen-unified) has real downloadable weights behind a manual-approval gate, but its documented base model is internally inconsistent — the adapter directory name (qwen_2.5_05B_model) implies Qwen2.5-0.5B while the model card prose states Qwen2.5-4B-Instruct, andcardData.base_modelis left as the unresolved stringqwen— and no evaluation metrics are published despite an evaluation-metrics image file being present in the repository.
Abbreviations
| ASR — Automatic speech recognition | AVL — Audio-vision-language modelling | DEP — Dependency parsing | EMB — Embeddings / dense retrieval | GEC — Grammar correction | IC — Image captioning |
| IF — Instruction following | KWS — Keyword spotting | LID — Language identification | LLM — Large language model | MLM — Masked language modelling / encoder | MORPH — Morphological analysis |
| MT — Machine translation | NER — Named entity recognition | OCR — Optical character recognition | POS — POS tagging | QA — Question answering | SC — Sentiment classification |
| T2I — Text-to-image | TC — Text classification | TG — Text generation | TR — Transliteration | TS-ASR — Target-speaker ASR | TTS — Text-to-speech |
| VLM — Vision-language modelling |
Contributing
Missing a Kazakh model, or spotted outdated metadata? Contributions are welcome:
- Add a model — open a submission issue or send a PR directly.
- Fix or update an entry — edit
data/models.yamland open a PR. - Report a stale number — Hugging Face download/like counts drift; flag it with the current value, though note the catalog does not treat these as intrinsic model properties.
See CONTRIBUTING.md for the full inclusion criteria, required metadata, and PR format.
Contributors
|
Alen Issayev |
 Assel Yermekova |
License
This catalog's own content — the repository structure, documentation, generated tables, and scripts — is released under the MIT License. Models linked from this catalog remain under their own respective licenses (recorded per entry above); this MIT license does not extend to their contents.
Explore related projects
affaan-m/ECC
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
302,086 starsNousResearch/hermes-agent
The agent that grows with you
263,013 starsmultica-ai/andrej-karpathy-skills
A single CLAUDE.md file to improve Claude Code behavior, derived from Andrej Karpathy's observations on LLM coding pitfalls.
232,586 starsfirecrawl/firecrawl
Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥
201,294 stars