
alanhuangyoo/crux has 186 GitHub stars and 36 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-11 04:24 UTC. Last push 2026-10-07.
Taking the pi coding agent to Claude Code-level performance: 0.539 → 0.773 pass@1 on Terminal-Bench 2.1 with the same self-hosted 27B model, by re-engineering the agent.
Measured star growth
- in 24h
- 0
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalCrux
A coding agent built on pi, re-engineered for long-horizon terminal tasks.
Terminal-Bench 2.1 pass@1 from 0.539 to 0.773 — on par with Claude Code on the same model.


English · 简体中文
Results
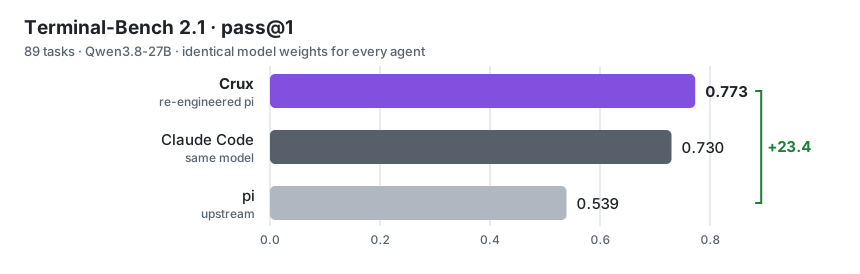
| Agent | Terminal-Bench 2.1 pass@1 |
|---|---|
| Crux | 0.773 0.793 on a rerun |
| Claude Code, same model | 0.730 |
| pi, upstream | 0.539 |
Self-hosted Qwen3.8-27B, identical weights for every agent · 89 tasks · pass@1 over whole runs.
What changed from pi
All changes are in the agent layer; the model is untouched.
- Context engine. Compaction requests are sized to fit the window, retried smaller on rejection, and summarize single-task sessions in full; the task's original wording is carried verbatim through every compaction. Compaction success: 14% → 100%.
- Agent loop. Recovery paths live in one explicit state machine: two-phase recovery from truncated output, the reasoning tail handed back after a cut, stall detection, and pacing against each task's own deadline. Truncated outputs: 18.0% → 0.7%.
- Runtime. A stream idle watchdog, a default command timeout, process-tree reaping and resume after an OOM kill keep multi-hour runs alive. Idle time in timed-out runs: 94% → 3%.
- Tools. A failed edit shows the nearest matching region of the file, long command output keeps both its head and its tail, and the model keeps short visible notes beside its tool calls.
Evaluation
benchmark/ holds the harness behind these numbers: it runs the
agent in task containers via harbor, classifies every trial's outcome, and
compares versions task by task with a paired sign test.
cd benchmark && uv sync
harbor run --dataset terminal-bench/terminal-bench-2-1 \
  --agent crux.pi_agent:CruxPiAgent --model openai/<model>
Acknowledgements
Built on pi by Earendil Works
(earendil-works/pi). Licensed as
upstream; see LICENSE.
Explore related projects
affaan-m/ECC
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
301,316 starsNousResearch/hermes-agent
The agent that grows with you
262,717 starsmultica-ai/andrej-karpathy-skills
A single CLAUDE.md file to improve Claude Code behavior, derived from Andrej Karpathy's observations on LLM coding pitfalls.
232,194 starsfirecrawl/firecrawl
Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥
200,932 stars