
airscholar/e2e-data-engineering
airscholar/e2e-data-engineering has 371 GitHub stars and 159 forks. GitHot measured +1 in 7 days. Last checked 2026-11-09 16:59 UTC. Last push 2025-02-14.
An end-to-end data engineering pipeline that orchestrates data ingestion, processing, and storage using Apache Airflow, Python, Apache Kafka, Apache Zookeeper, Apache Spark, and Cassandra. All components are containerized with Docker for easy deployment and scalability.
Measured star growth
- in 24h
- Update delayed
- in 7 days
- +1
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalRealtime Data Streaming | End-to-End Data Engineering Project
Table of Contents
- Introduction
- System Architecture
- What You'll Learn
- Technologies
- Getting Started
- Watch the Video Tutorial
Introduction
This project serves as a comprehensive guide to building an end-to-end data engineering pipeline. It covers each stage from data ingestion to processing and finally to storage, utilizing a robust tech stack that includes Apache Airflow, Python, Apache Kafka, Apache Zookeeper, Apache Spark, and Cassandra. Everything is containerized using Docker for ease of deployment and scalability.
System Architecture
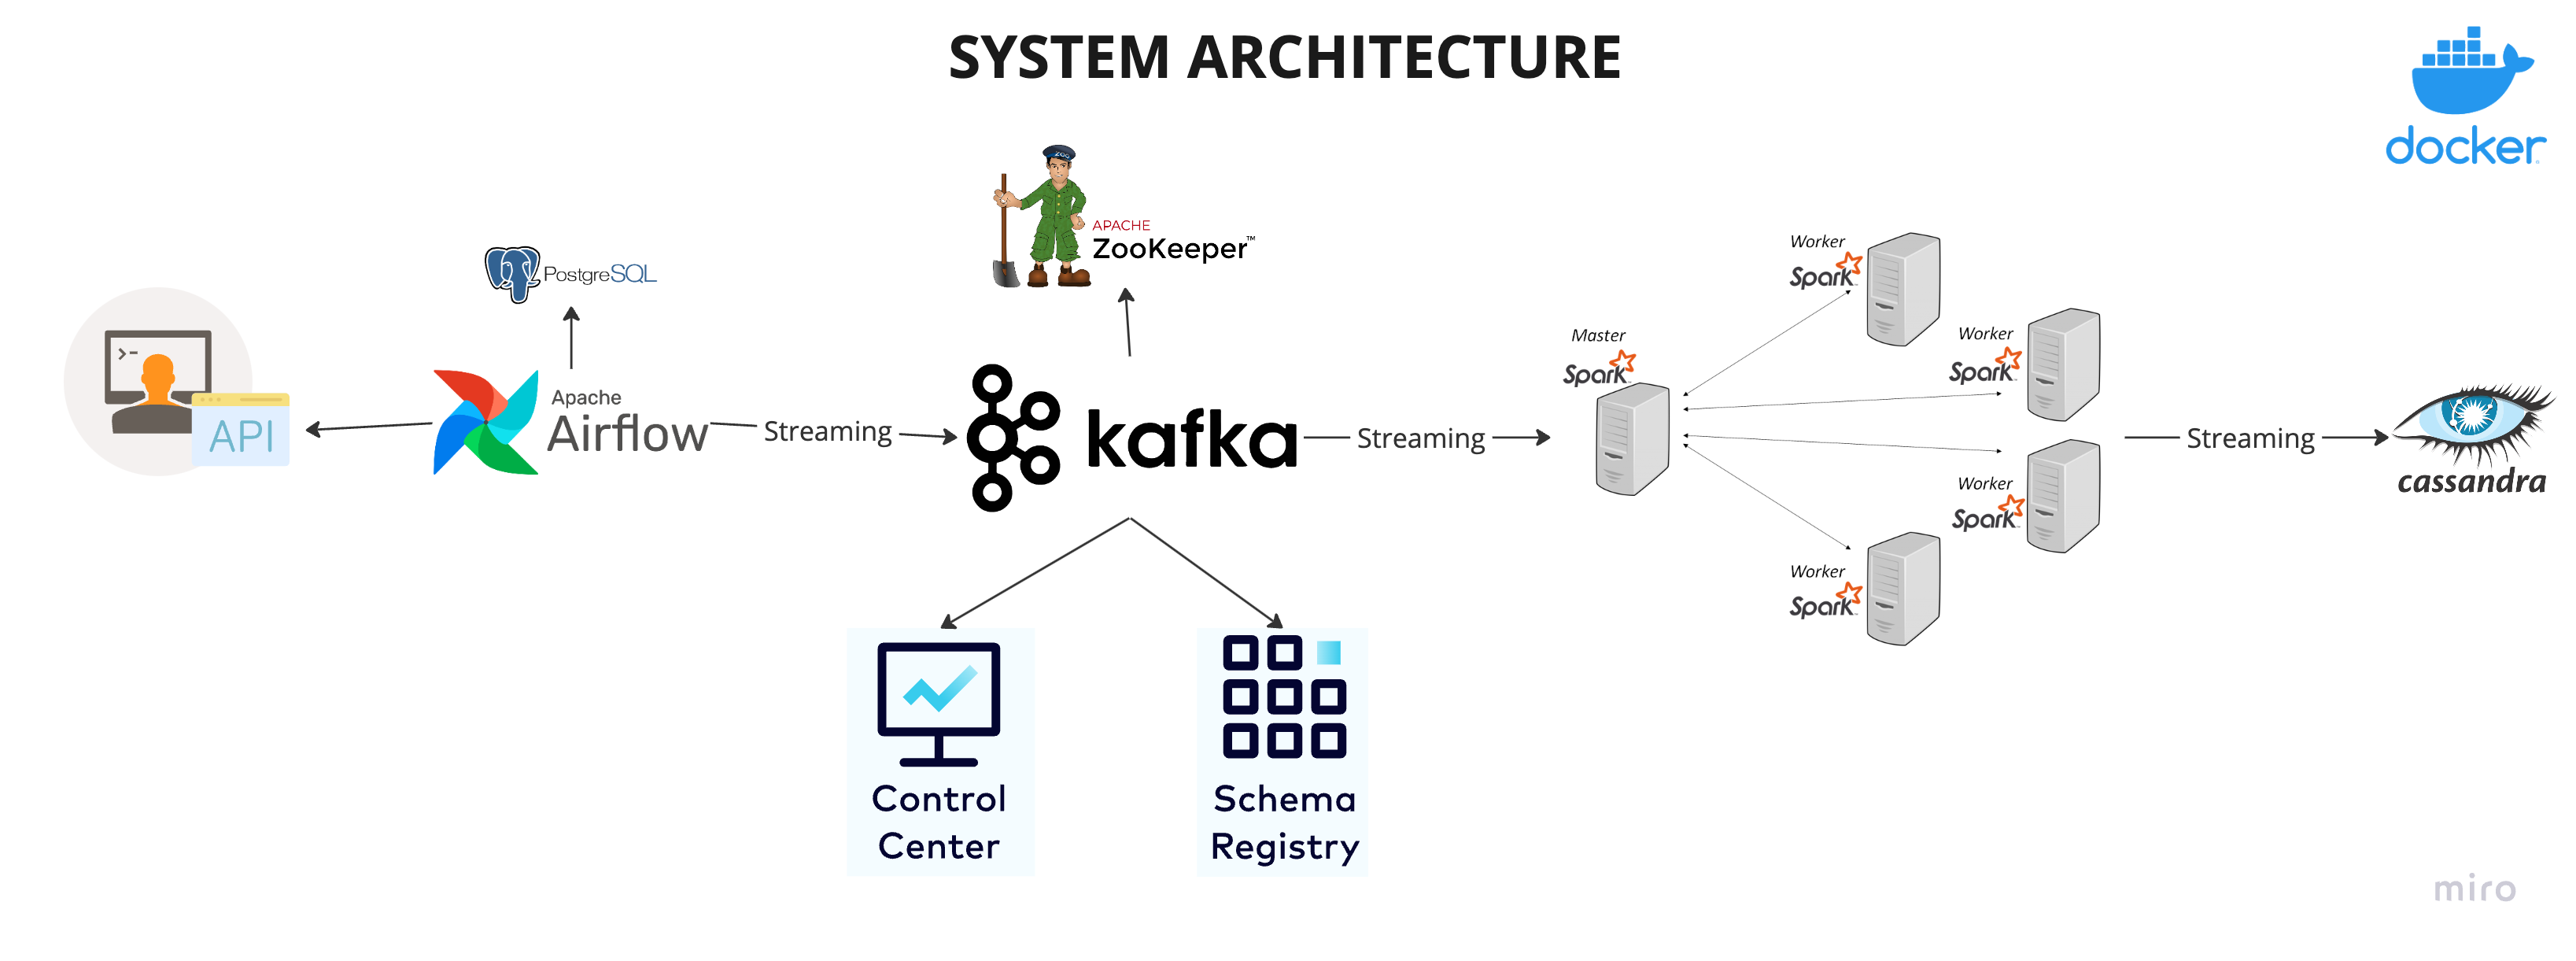
The project is designed with the following components:
- Data Source: We use
randomuser.meAPI to generate random user data for our pipeline. - Apache Airflow: Responsible for orchestrating the pipeline and storing fetched data in a PostgreSQL database.
- Apache Kafka and Zookeeper: Used for streaming data from PostgreSQL to the processing engine.
- Control Center and Schema Registry: Helps in monitoring and schema management of our Kafka streams.
- Apache Spark: For data processing with its master and worker nodes.
- Cassandra: Where the processed data will be stored.
What You'll Learn
- Setting up a data pipeline with Apache Airflow
- Real-time data streaming with Apache Kafka
- Distributed synchronization with Apache Zookeeper
- Data processing techniques with Apache Spark
- Data storage solutions with Cassandra and PostgreSQL
- Containerizing your entire data engineering setup with Docker
Technologies
- Apache Airflow
- Python
- Apache Kafka
- Apache Zookeeper
- Apache Spark
- Cassandra
- PostgreSQL
- Docker
Getting Started
Clone the repository:
git clone https://github.com/airscholar/e2e-data-engineering.gitNavigate to the project directory:
cd e2e-data-engineeringRun Docker Compose to spin up the services:
docker-compose up
For more detailed instructions, please check out the video tutorial linked below.
Watch the Video Tutorial
For a complete walkthrough and practical demonstration, check out our YouTube Video Tutorial.
Explore related projects
Asabeneh/30-Days-Of-Python
The 30 Days of Python programming challenge is a step-by-step guide to learn the Python programming language in 30 days. This challenge may take more than 100 days. Follow your own pace. These videos may help too: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,486 starsgrafana/grafana
The open and composable observability and data visualization platform. Visualize metrics, logs, and traces from multiple sources like Prometheus, Loki, Elasticsearch, InfluxDB, Postgres and many more.
77,790 starsredis/redis
For developers, who are building real-time data-driven applications, Redis is the preferred, fastest, and most feature-rich cache, data structure server, and document and vector query engine.
77,332 starsapache/superset
Apache Superset is a Data Visualization and Data Exploration Platform
75,455 stars