
adithya-s-k/FineEnvs
adithya-s-k/FineEnvs has 563 GitHub stars and 78 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-15 21:08 UTC. Last push 2026-11-14.
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
FineEnvs — RL Environments 101: building and scaling RL environments in the age of LLMs
AIREADME.md
Original
FineEnvs
Open source RL environments for LLM agents
Build · Deploy · Train · Eval — end to end, reproducible, in the open.


Why this exists
The RL environment ecosystem is moving fast. New frameworks land every few weeks, each with its own vocabulary for the same handful of ideas, and most of what's written about them is either a launch post or a spec. Meanwhile the actual bottleneck in RL for LLMs has quietly shifted: the algorithm isn't the hard part any more — the environment is.
So we're building the resource we wanted. Open source, end to end, and reproducible: how to design an environment, how to build it, how to deploy it, how to train against it, and how to scale it to thousands of concurrent sessions. Real code you can run, not diagrams of code someone else ran.
Every environment here works. Every rollout has been executed. Every training curve came from a job you can launch yourself, in one command, without a GPU of your own.
Where things live: source, recipes and notebooks in this repo · environments, datasets, models and demos on 🤗 huggingface.co/FineEnvs.
Projects
Each numbered folder is a self-contained, end-to-end project — its own environments, notebooks, results and README, plus the Hub repos it owns. They read in order but stand alone.
| # | Project | What you get | Envs | Frameworks | Deployed | Status |
|---|---|---|---|---|---|---|
| 00 | RL Environments 101 | Three environments, six frameworks, side by side. | 3 | 6 | 8 | ✅ stable |
| 01 | LaTeX OCR | Train Qwen3-VL-2B to read math images into LaTeX, with a verifiable reward. | 1 | 1 | 1 | ✅ stable |
| 02 | Watercolour | Train Qwen3.5-35B-A3B to paint watercolours by writing p5.brush sketches, rewarded by an aesthetic preference model. | 1 | 1 | 0 | ✅ trained |
| 03 | GeoGuesser | Drop a VLM at a random street corner on Earth and score it on kilometres of error. | 1 | 1 | 1 | ✅ stable |
| 04 | SmolDataEnvs | Data-analysis tasks, verified SFT traces and a single-turn GRPO tutorial on HF Jobs. | 1 | 1 | 0 | 🚧 wip |
| 05 | SmolDataEnvs: multi-harness RL | Train on SmolDataEnvs with SETA, native OpenCode or Harbor, using HF Jobs or Slurm. | 3 | 1 | 0 | 🚧 wip |
| 06 | Multilingual | Document OCR over a million pages in 22 languages and speech recognition over 102, each behind one OpenEnv server, and Gemma 4 trained to read and hear Kannada. | 2 | 1 | 2 | ✅ trained |
| 07 | PortSimEnv v1 by Adithya S Kolavi (Hugging Face) agentenv port by Edgar Arakelyan (Scale AI) |
Re-plan a broken week of container-ship dockings at the Port of Barcelona, graded against a proven optimum. | 1 | 2 | 1 | 🚧 wip |
| 07 | PortSimEnv v2–v5: live, marine, wind and lines by Edgar Arakelyan (Scale AI) |
Run a Port of Barcelona quay through a week as it unfolds, with live news, pilots and tugs, real wind and shipping lines that answer back. | 1 | 1 | 0 | 🚧 wip |
| 07 | AirOpsEnv v1–v3: the storm day, the ops control center and its passengers by Edgar Arakelyan (Scale AI) |
Run JetBlue through a real storm day, from one hub's desk to the whole network's control center, where two desks talk, then three with the passengers on board. | 1 | 1 | 0 | 🚧 wip |
Generated from each project's project.yaml by tools/build_index.py. Adding a project means
editing that manifest, not this table.
00 · RL Environments 101 3 environments · 6 frameworks · 8 live Spaces
One env, six ways. Three environments, each implemented six times — same logic, six framework
dialects. Diff any two server.py files and the differences are the lesson.
| Environment | Turns | Tools | Backend |
|---|---|---|---|
| Jupyter agent | multi | 4 | E2B sandbox, real code execution |
| Wordle | multi | 1 | pure Python, no backend |
| Desktop | multi | 19 | E2B Desktop, vision-driven |
Across openenv · ors · nemo_gym · verifiers · skyrl_gym · gem — 18 implementations, 8 of
them deployed as Spaces you can hit right now.
01 · LaTeX OCR train a VLM against a served reward
The full loop. Project 00 shows you what an environment is; this one takes a single environment all the way to a trained model.
Qwen3-VL-2B learns to read rendered math into LaTeX with GRPO, scored by a reward served from a live OpenEnv Space. The scorer compares normalized LaTeX using edit distance and exact match, with a guard against padded completions. Runs on a GPU you spin up in one command; no cluster, no local GPU. The environment source, notebook, and HF Jobs scripts live together with reproducible smoke tests. Browse the LaTeX OCR collection for the environment, model, dashboards, and run data.
02 · Watercolour train against an aesthetic reward
RL over taste. Project 01 trains against a verifiable reward. This one asks what happens when there is no correct answer at all.
Qwen3.5-35B-A3B learns to paint watercolours by writing p5.brush sketches. Headless Chromium renders each sketch, and the render is scored by an aesthetic preference model plus a VLM judge comparing it against a hand-rated reference pool, so the reward is somebody's taste. Three reward mixes trained and compared, every artifact published, and the full story in the blog post.
03 · GeoGuesser train a VLM to place itself on Earth
A game as an environment. Projects 01 and 02 score one shot. This one is multi-turn: the agent looks around, walks down the road, zooms on a sign, pins a candidate, and commits.
Qwen3.5-4B learns visual geolocation with GRPO against a
playable OpenEnv Space serving real
Mapillary panoramas, scored on kilometres of error. It ends up ahead of gpt-5.4-mini and
claude-haiku-4.5 on a 200-task held-out split and behind only claude-sonnet-5, for about $100.
Ten hours on four A100s, or one GPU if you are in no hurry. Three training runs, the reward
redesigned once, and every measurement bug written down in
the article.
04 · SmolDataEnvs 5.5K+ RL tasks in code and data science
A dataset, not a single run. The first three projects each train one model against one environment. This one ships the environments: 5,394 verified data-analysis tasks built from real Kaggle notebooks, where the agent gets a sandbox with the tables in it and has to compute the answer.
Grading is an exact comparison against a known answer — numeric tolerances, list normalisation, symbolic equivalence — so no LLM sits in the reward path. Every task had to be solved in a live sandbox before it was let in, which means a zero says something about your model rather than about the task. Three ways in: flat rows with a bundled grader, 4,677 verified trajectories to fine-tune on, and three Harbor suites you can serve straight into a trainer. A notebook takes you from one task to a trained small model in a sitting.
Browse the tasks in the Harbor Visualiser, or the whole SmolDataEnvs collection.
05 · SmolDataEnvs: multi-harness RL one model, three ways to run the tool loop
Same tasks, different harness. Project 04 ships the tasks. This one trains on them while changing who runs the agent loop: TRL calling Python tools directly, native OpenCode in a sandbox, or Harbor rotating OpenCode, Claude Code, Codex and Mini-SWE-Agent.
Three readable TRL scripts train LFM2.5-2.6B or Qwen3.5-2B on HF Jobs or Slurm, with a fixed pass@1 evaluation in every harness. The article walks through the experiments, and the collection holds the Spaces, datasets and trained models.
06 · Multilingual reading and hearing many languages, two servers
Two corpora as environments. ocr/ serves a million scanned pages in
22 languages from a bucket as 11 million tasks, with Sarvam Indic OCR Bench beside them as evaluation
splits. asr/ serves all of FLEURS, 102 languages of read speech. Both play
in the browser.
Gemma 4 E4B was trained on Kannada in each. Reading, it makes 16% fewer character errors on the benchmark's Kannada slice, mostly by learning to stay in the script. Hearing, it makes 45% fewer on clips it never saw, but only once the trainer actually fed it the audio: TRL drops audio from the forward pass its loss comes from, and the project shows the fix and the numbers. Part of the Multilingual Multimodal Envs collection.
07 · Simulation environments a catalog of simulation environments and their evals
Real-world work as an environment. Each environment rebuilds one real job from the records it leaves behind and grades the agent once, deterministically, against an answer that can be proven best. The catalog credits every author and gives each environment an eval card in the same format.
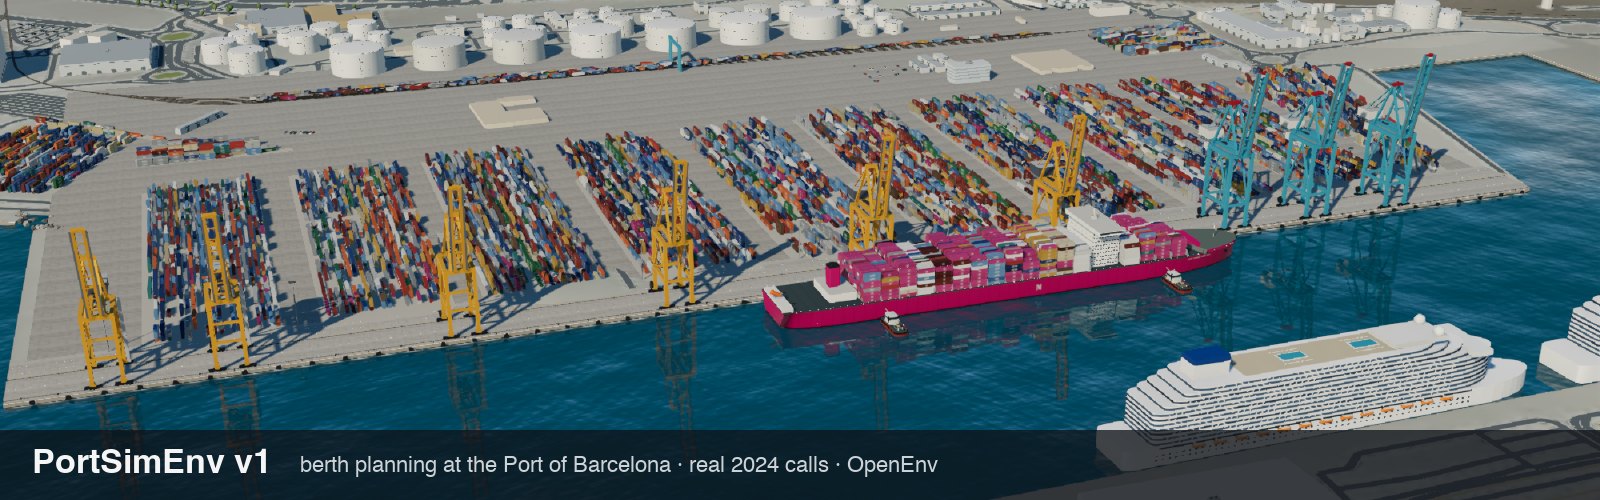
- PortSimEnv v1. The agent re-plans a broken week of container-ship dockings at the Port of Barcelona, built from the port's real 2024 records. It has three tools, and its plan is graded against the optimum CP-SAT proves. GPT-6.1 Sol leads the six-model eval at 0.888. Play it in the Space, watch every eval rollout in 3D, or run it on AgentEnv.
- PortSimEnv v2–v5, by Edgar Arakelyan (Scale AI), on AgentEnv. The same weeks play out watch by watch: live news and freezes (v2), pilots and tugs (v3), real wind and forecasts (v4), and shipping lines that answer back (v5). Over 60 weeks Claude Opus 5.5 and GPT-6 Astra lead at 0.857 and 0.851, and Qwen3.8-27B finds a valid plan in 1 of 60. Every run replays in the Space, and the article's chapter walks through each version.
Everything is in the Simulation RL Envs collection, and the article covers all of it. Built a simulation environment? Add it to the catalog.
More coming. Each new project is another end-to-end recipe: an environment, a training run, and the artifacts on the Hub. Proposals and contributions welcome →
Tooling
Apps for exploring and evaluating RL environments, in tooling/:
- HF RL Explorer (Space): every RL environment on the Hub in one place (Harbor datasets, OpenEnv Spaces, NeMo Gym, Verifiers, verl and SkyRL, MiMo), what each task asks and how it is graded, and agent rollouts on any of them, graded and compared.
- MiMo RL Environment Explorer
(Space): the 7,780 MiMo-V2.6-RL environments,
rollouts on MiMo's own harness, and
mimo_harbor, their conversion to Harbor datasets.
Articles & talks
Long-form writing and conference talks. Sources live in content/; each one ships to the
Hub as a Space.
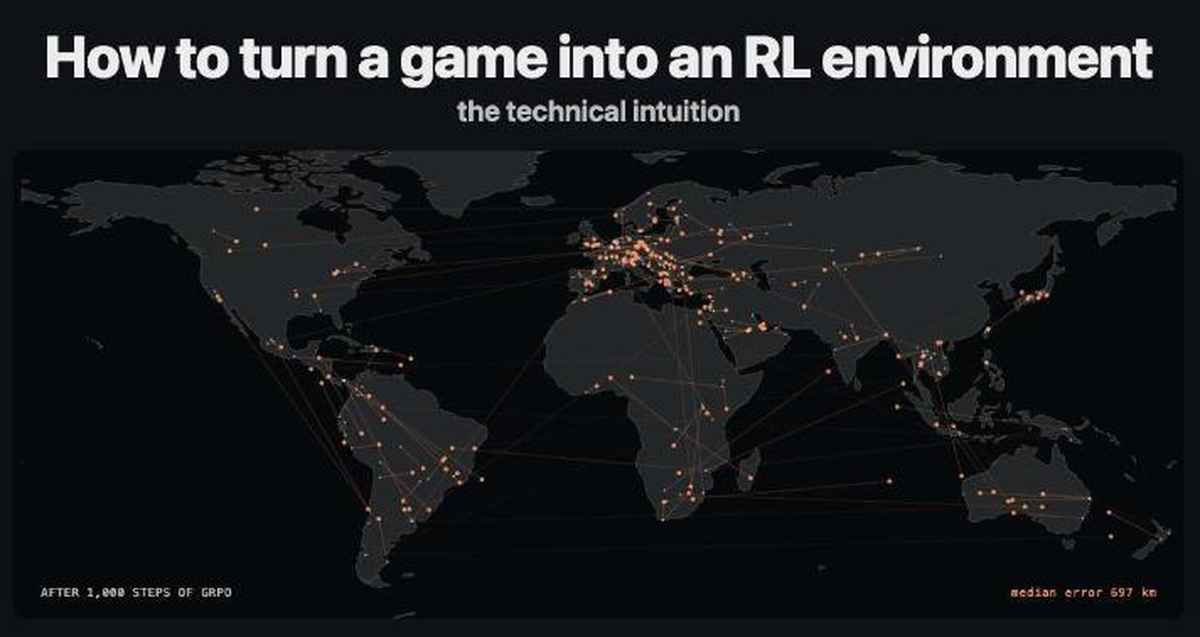
How to turn a game into an RL environment
The technical intuition, worked end to end: curating the data, designing the environment, shipping it
with OpenEnv, and training a 4B against it with TRL until it outscored 📂 |
The Ultimate Guide to RL Environments
Building and scaling RL environments in the LLM era — how frameworks are built, how rewards are wired, and how they scale to thousands of concurrent sessions. |
RL Environments 101
From "what is an env?" to training your own. RL fundamentals → environment anatomy → OpenEnv → training with TRL. The original 30-minute talk. |
Scaling RL for LLMs
What an environment actually is, how reward hacking happens, and how to build and train against your own. The 20-minute cut, for AMD AI Dev Day. |
Multi-Harness Training
OpenEnv × Harbor — why an environment's failure model decides whether it can be trained against: in-process agent loops vs. an HTTP boundary, and what it takes to capture trainable tokens. |
The Ultimate Guide to Multi-Harness RL
Train open models with RL inside real agent harnesses: one set of data tasks, trained through TRL's own tools, native OpenCode and Harbor, and evaluated in each. 📂 |
Simulation RL Environments
Turning real-world work into RL environments. Part 1 builds PortSimEnv from the Port of Barcelona's 2024 records; the community has since added v2–v5 and RailSimEnv. 📂 |
Training a Coding Agent Through a Harness You Did Not Write
The multi-harness RL talk: one small model trained with GRPO inside four unmodified coding agents (OpenCode, Claude Code, Codex, Mini-SWE-Agent), and what changes when you do. PDF and PPTX in the Space. 📂 source in the Space · project |




Quickstart
Run an environment. Wordle is pure Python with no external backend — the fastest full rollout:
git clone https://github.com/adithya-s-k/FineEnvs
cd FineEnvs
cp .env.example .env          # HF_TOKEN, plus E2B_API_KEY for sandbox-backed envs

cd 00-environments-101/envs/wordle/verifiers
uv sync && uv run python rollout.py
Train a model against one. No GPU, no cluster, no setup — one command spins up a GPU with the notebooks loaded and prints a JupyterLab URL:
curl -sSL https://raw.githubusercontent.com/adithya-s-k/FineEnvs/main/tools/jupyter_launch.py | python3 -
Windows (PowerShell): irm https://raw.githubusercontent.com/adithya-s-k/FineEnvs/main/tools/jupyter_launch.py | python -. Set FLAVOR=t4-small for a cheaper GPU. Track jobs at huggingface.co/settings/jobs.
Build your own environment
Five SKILL.md-spec agent skills turn a plain-English description into a runnable RL environment across four frameworks. They work in any project — with Claude Code, Cursor, Codex, OpenCode, Gemini CLI and others.
npx skills add adithya-s-k/FineEnvs
| Skill | What it builds |
|---|---|
rl-env-from-description |
Orchestrator — interviews you, then ports across all four frameworks |
generate-openenv-env |
OpenEnv (Hugging Face / Meta) — HTTP + MCP |
generate-ors-env |
OpenReward (ORS) — per-tool-call rewards |
generate-verifiers-env |
Verifiers (Prime Intellect) — in-process + rubrics |
generate-nemo-gym-env |
NeMo Gym (NVIDIA) — HTTP + post-episode /verify |
"make me an env where the agent plays connect-four" — that's the whole interface.
Repository layout
FineEnvs/
├── 00-environments-101/     3 environments × 6 frameworks
├── 01-latex-ocr/            train a VLM against a served reward
├── 02-watercolour/          train against an aesthetic reward
├── 03-geoguesser/           a multi-turn game as an environment
├── 04-smoldataenvs/         5.5K+ verified data-analysis tasks
├── 05-multi-harness-rl/     the same tasks trained through TRL, OpenCode and Harbor
├── 06-multilingual/         OCR over 22 languages and ASR over 102, two OpenEnv servers
├── 07-simulation-environments/  a catalog of simulation environments: PortSimEnv v1–v5 and more
├── content/
│   ├── articles/            long-form sources (Astro → Docker Space)
│   └── slides/              talk decks (Vite → static Space)
├── tooling/
│   ├── hf-rl-explorer/      every RL environment on the Hub, with rollouts (Space + admin)
│   └── mimo-rl-explorer/    the MiMo-V2.6-RL environments, rollouts, Harbor conversion
├── tools/                   launcher, Space deploy, index generation
├── assets/                  brand + content thumbnails
└── .claude/skills/          the five environment-authoring agent skills
Inside a project the folders always mean the same thing: envs/ (implementations, shared logic in
core/), train/ (configs + launch), notebooks/, results/.
Contributing
We're actively looking for new end-to-end recipes — a task, an environment, a training run, and honest results. Domains we don't cover yet are especially welcome: web browsing, SQL, games, robotics sims, tool-use over real APIs, long-horizon software engineering.
Half-finished counts. A recipe with real numbers and a gap beats a polished one nobody ran — open an issue and we'll help you land it. New framework ports, reproductions that disagree with ours, and corrections to the guide are all just as welcome.
See CONTRIBUTING.md. The fastest path to a new environment is the
rl-env-from-description skill.
Citation
@misc{fineenvs,
  author = {Kolavi, Adithya S},
  title  = {FineEnvs: Open Source RL Environments for LLM Agents},
  year   = {2026},
  url    = {https://github.com/adithya-s-k/FineEnvs}
}