
ZhuLinsen/LiteMoE
ZhuLinsen/LiteMoE has 32 GitHub stars and 2 forks. GitHot measured +1 stars in 24 hours. Last checked 2026-11-15 03:22 UTC. Last push 2026-11-03.
Measured star growth
- in 24h
- +1
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
A MoE inference engine you can read in an afternoon.
AIREADME.md
Original
A MoE inference engine you can read in an afternoon.
About 1,600 lines of Python. 5-9% more throughput than vLLM on fixed batches.
English · 简体中文
Tutorial: how LLM inference works · Interactive demo
git clone https://github.com/ZhuLinsen/LiteMoE && cd LiteMoE
pip install -e '.[vllm]'
litemoe "Explain mixture-of-experts in one sentence."
Benchmark
| 12-point geomean vs vLLM 0.32.0, same session | Granite 1B | Granite 3B | Overall |
|---|---|---|---|
| NVIDIA A100 | 110.6% | 107.1% | 108.8% |
| NVIDIA L4 | 105.5% | 105.0% | 105.3% |
Reproduce it on your GPU with bash tools/reproduce.sh.
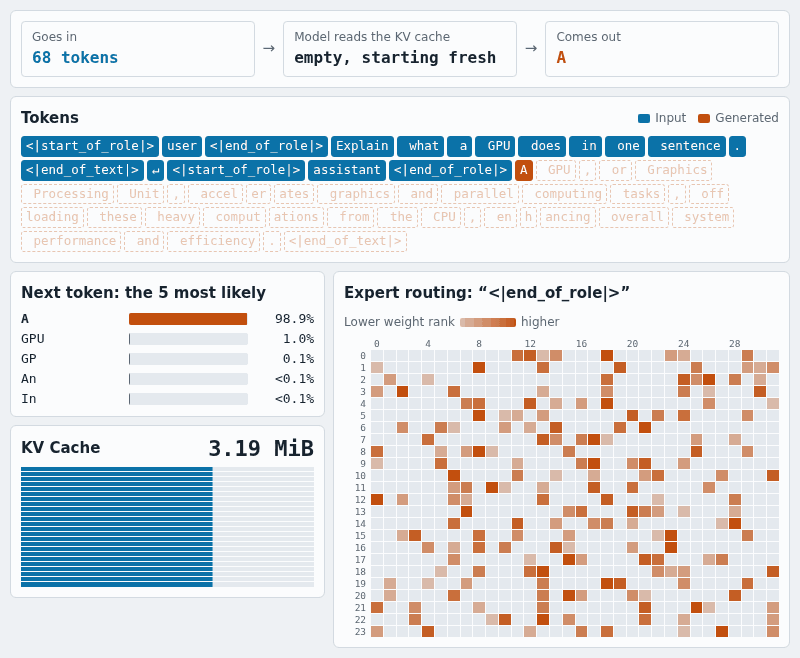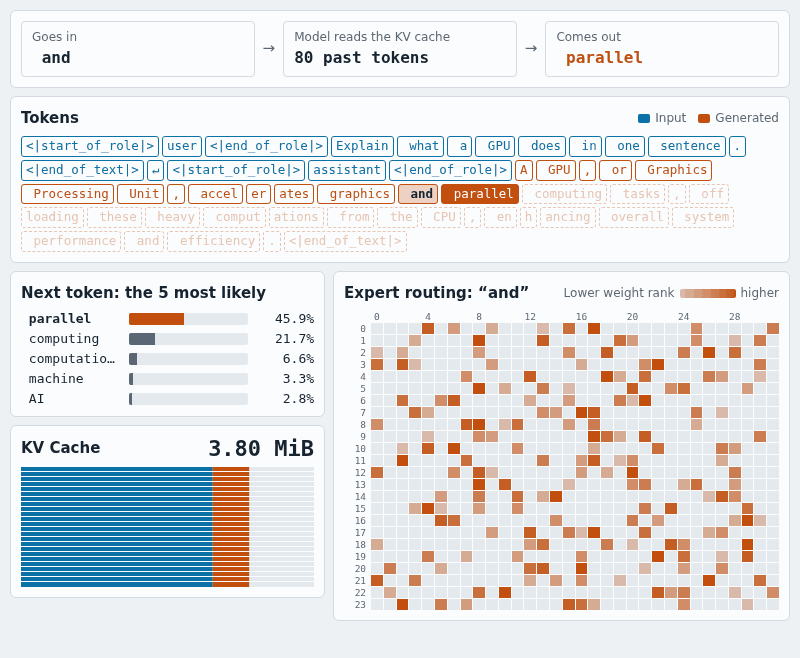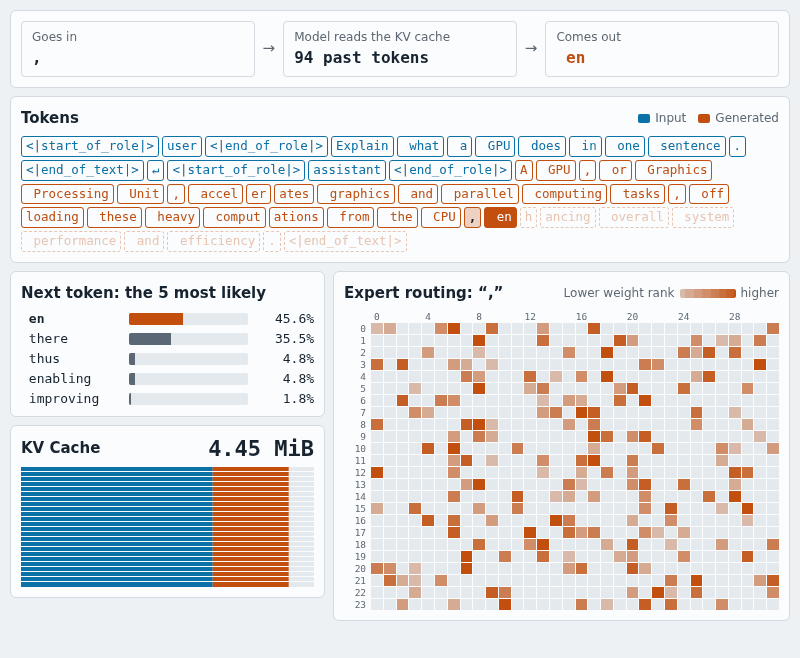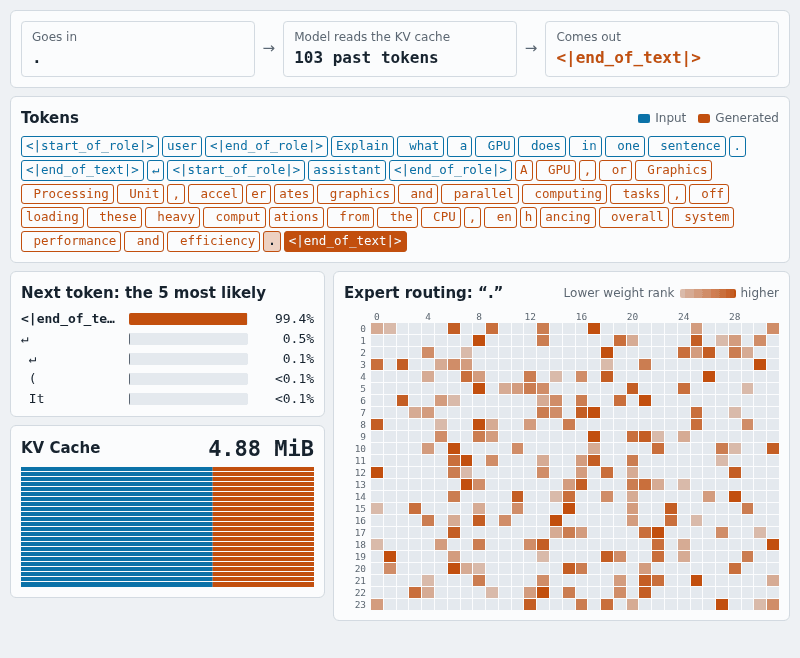
What this does and doesn't mean: LiteMoE calls vLLM's expert, attention and router kernels, and owns forward, KV and the generation loop. These runs use fixed batches, greedy decoding and one GPU. vLLM also runs a scheduler and a full serving stack, which LiteMoE doesn't have.
Accuracy: on all 1,319 GSM8K test problems (Granite 3B, A100), LiteMoE scored 46.2% and vLLM 47.2%, a difference of -0.9 points (95% CI -2.9 to +1.1). No loss was detected, but outputs aren't identical and this is one task on one model. Quality results and known limits
Where the speed comes from
Most of the gain comes from removing work that can't affect live requests: per-layer masks, index lookups and output copies in Decode. Whole Decode steps run as a CUDA Graph.
Start reading at litemoe/model.py.
Status
| Works | Granite 3.1 1B (3.5 GB GPU memory) and 3B (7.5 GB), one NVIDIA GPU with BF16, greedy decoding, up to 4,096 tokens of context |
| Tested on | Ubuntu 24.04, Python 3.12, CUDA 13.0, A100 and L4 |
| Not yet | Other models, multi-GPU, sampling, serving, dynamic batching |
Use vLLM for production. Use LiteMoE to learn how MoE inference works, or as a small base for experiments.
License
Apache-2.0. Not affiliated with vLLM, IBM or DeepSeek. Third-party notices
Community
Thanks to the LINUX DO community.