
WisconsinAIVision/MixNMatch
WisconsinAIVision/MixNMatch has 964 GitHub stars and 185 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-09 19:15 UTC. Last push 2020-07-07.
Pytorch implementation of MixNMatch
Measured star growth
- in 24h
- 0
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalMixNMatch: Multifactor Disentanglement and Encoding for Conditional Image Generation
[Paper]
Yuheng Li,
Krishna Kumar Singh,
Utkarsh Ojha,
Yong Jae Lee
UC Davis
In CVPR, 2020
1/31/2020 update: Code and models released.
Demo Video
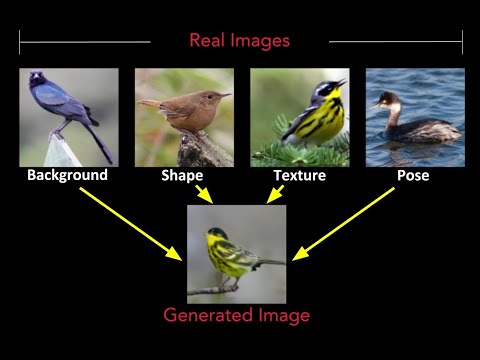
This is our CVPR2020 presentation video link
Web Demo
For interactive web demo click here. This web demo is created by Yang Xue.
Requirements
- Linux
- Python 3.7
- Pytorch 1.3.1
- NVIDIA GPU + CUDA CuDNN
Getting started
Clone the repository
git clone https://github.com/Yuheng-Li/MixNMatch.git
cd MixNMatch
Setting up the data
Download the formatted CUB data from this link and extract it inside the data directory
Downloading pretrained models
Pretrained models for CUB, Dogs and Cars are available at this link. Download and extract them in the models directory.
Evaluating the model
In code
- Run
python eval.py --z path_to_pose_source_images --b path_to_bg_source_images --p path_to_shape_source_images --c path_to_color_source_images --out path_to_ourput --mode code_or_feature --models path_to_pretrained_models - For example
python eval.py --z pose/pose-1.png --b background/background-1.png --p shape/shape-1.png --c color/color.png --mode code --models ../models --out ./code-1.png- NOTE:(1) in feature mode pose source images will be ignored; (2) Generator, Encoder and Feature_extractor in models folder should be named as G.pth, E.pth and EX.pth
Training your own model
In code/config.py:
- Specify the dataset location in
DATA_DIR.- NOTE: If you wish to train this on your own (different) dataset, please make sure it is formatted in a way similar to the CUB dataset that we've provided.
- Specify the number of super and fine-grained categories that you wish for FineGAN to discover, in
SUPER_CATEGORIESandFINE_GRAINED_CATEGORIES. - For the first stage training run
python train_first_stage.py output_name - For the second stage training run
python train_second_stage.py output_name path_to_pretrained_G path_to_pretrained_E- NOTE: output will be in
output/output_name - NOTE:
path_to_pretrained_Gwill beoutput/output_name/Model/G_0.pth - NOTE:
path_to_pretrained_Ewill beoutput/output_name/Model/E_0.pth
- NOTE: output will be in
- For example
python train_second_stage.py Second_stage ../output/output_name/Model/G_0.pth ../output/output_name/Model/E_0.pth
Results
1. Extracting all factors from differnet real images to synthesize a new image

2. Comparison between the feature and code mode

3. Manipulating real images by varying a single factor

4. Inferring style from unseen data
| Cartoon -> image | Sketch -> image |
|---|---|
 |
 |
5. Converting a reference image according to a reference video

Citation
If you find this useful in your research, consider citing our work:
@inproceedings{li-cvpr2020,
  title = {MixNMatch: Multifactor Disentanglement and Encoding for Conditional Image Generation},
  author = {Yuheng Li and Krishna Kumar Singh and Utkarsh Ojha and Yong Jae Lee},
  booktitle = {CVPR},
  year = {2020}
}
Explore related projects
tensorflow/tensorflow
An Open Source Machine Learning Framework for Everyone
201,427 starshuggingface/transformers
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
168,711 starsAUTOMATIC1111/stable-diffusion-webui
Stable Diffusion web UI
165,274 starsComfy-Org/ComfyUI
The most powerful and modular diffusion model GUI, api and backend with a graph/nodes interface. The fastest local inference engine in the world.
146,024 stars