
Walter0807/MotionBERT
Walter0807/MotionBERT has 1,463 GitHub stars and 184 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-07 06:07 UTC. Last push 2026-03-14.
[ICCV 2023] PyTorch Implementation of "MotionBERT: A Unified Perspective on Learning Human Motion Representations"
Measured star growth
- in 24h
- 0
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalMotionBERT: A Unified Perspective on Learning Human Motion Representations


This is the official PyTorch implementation of the paper "MotionBERT: A Unified Perspective on Learning Human Motion Representations" (ICCV 2023).
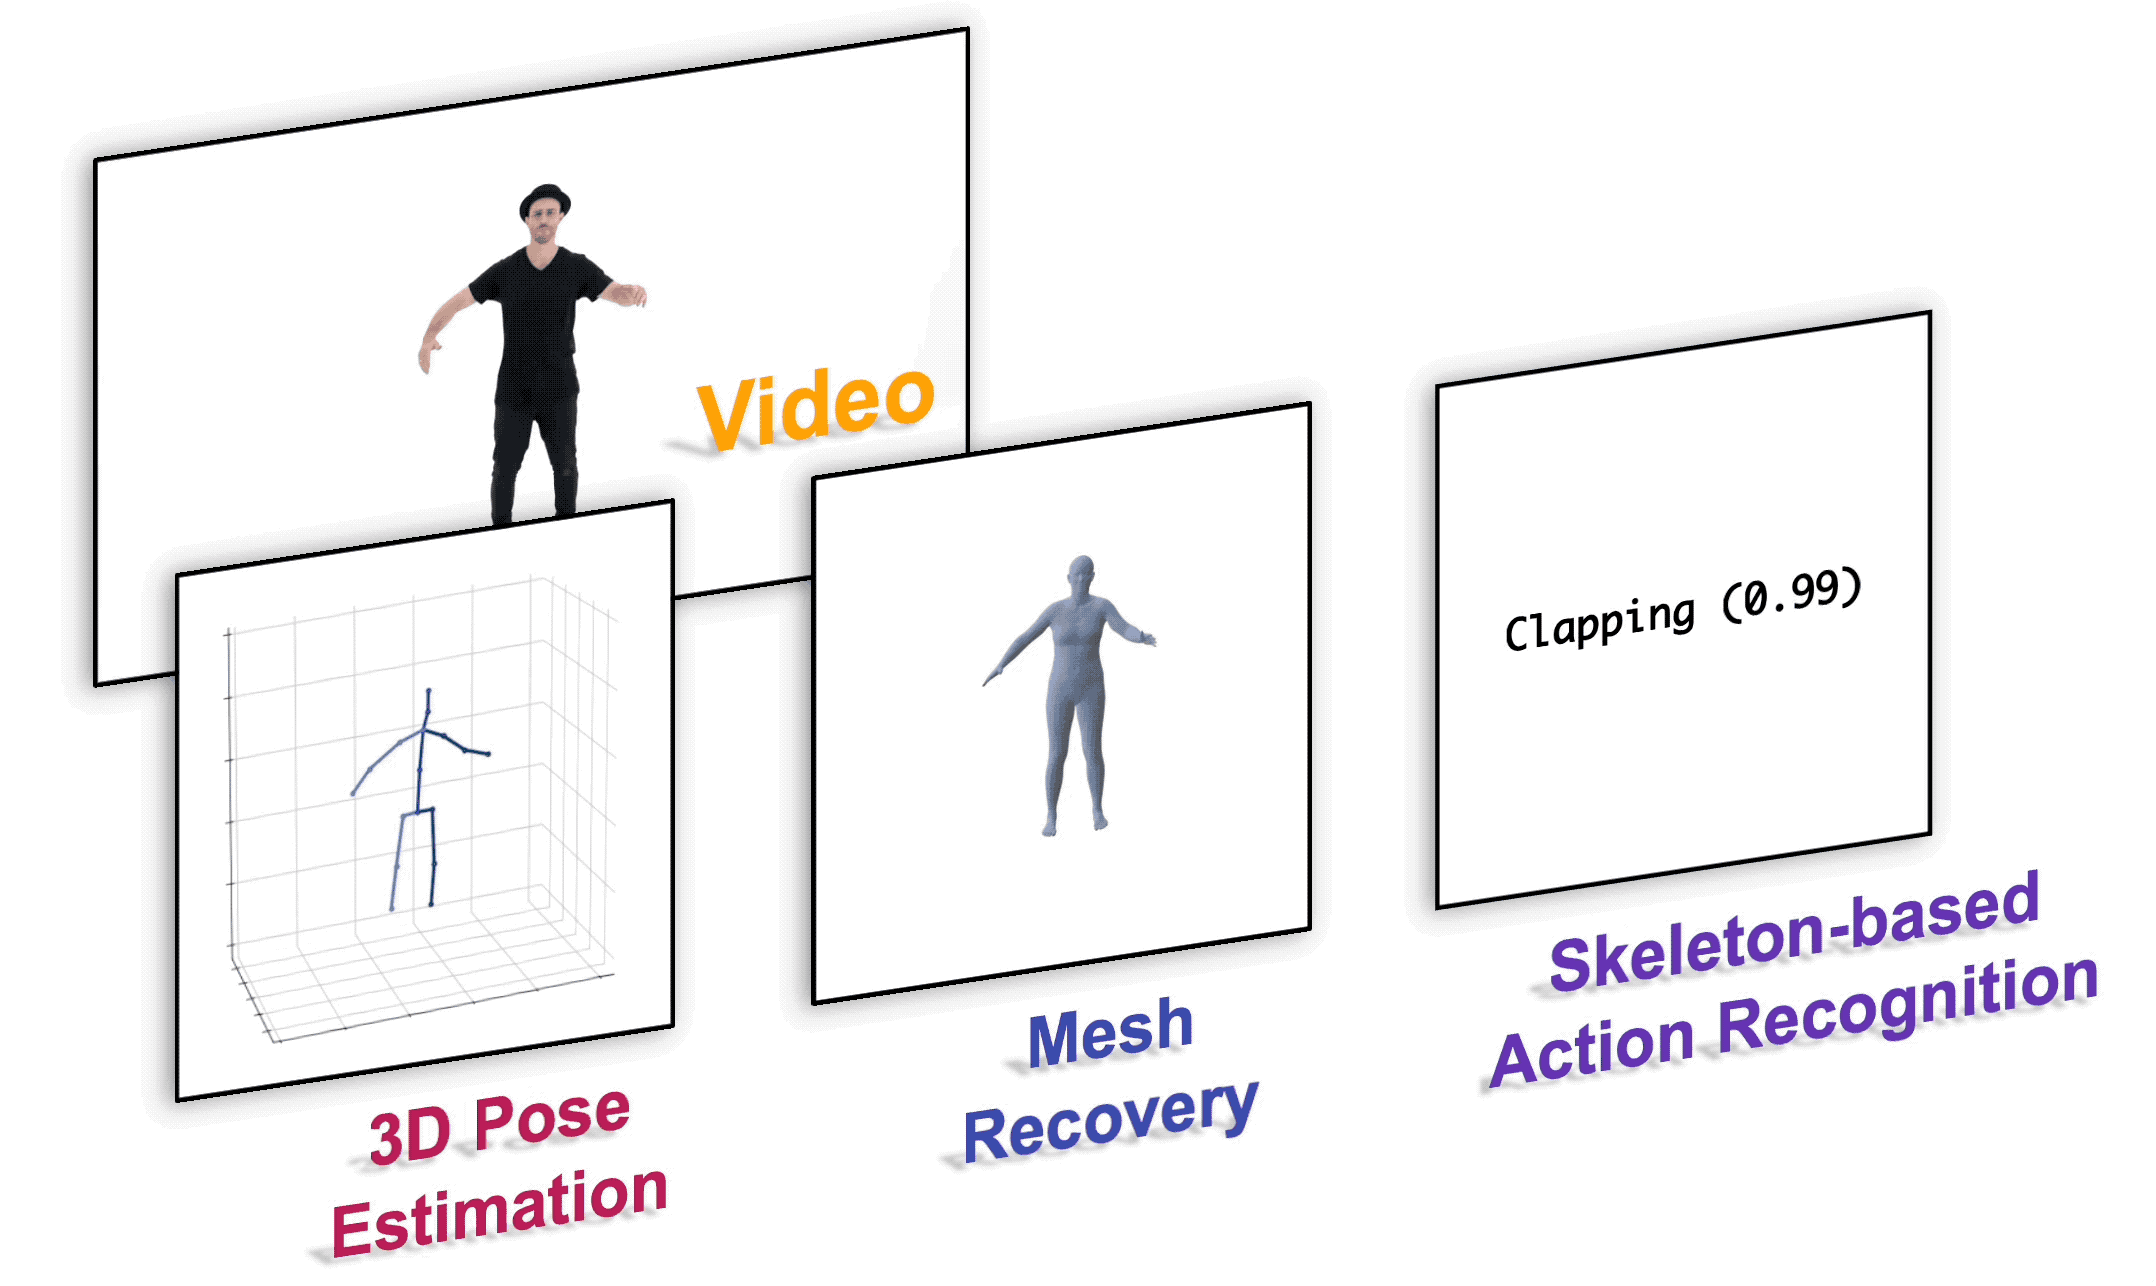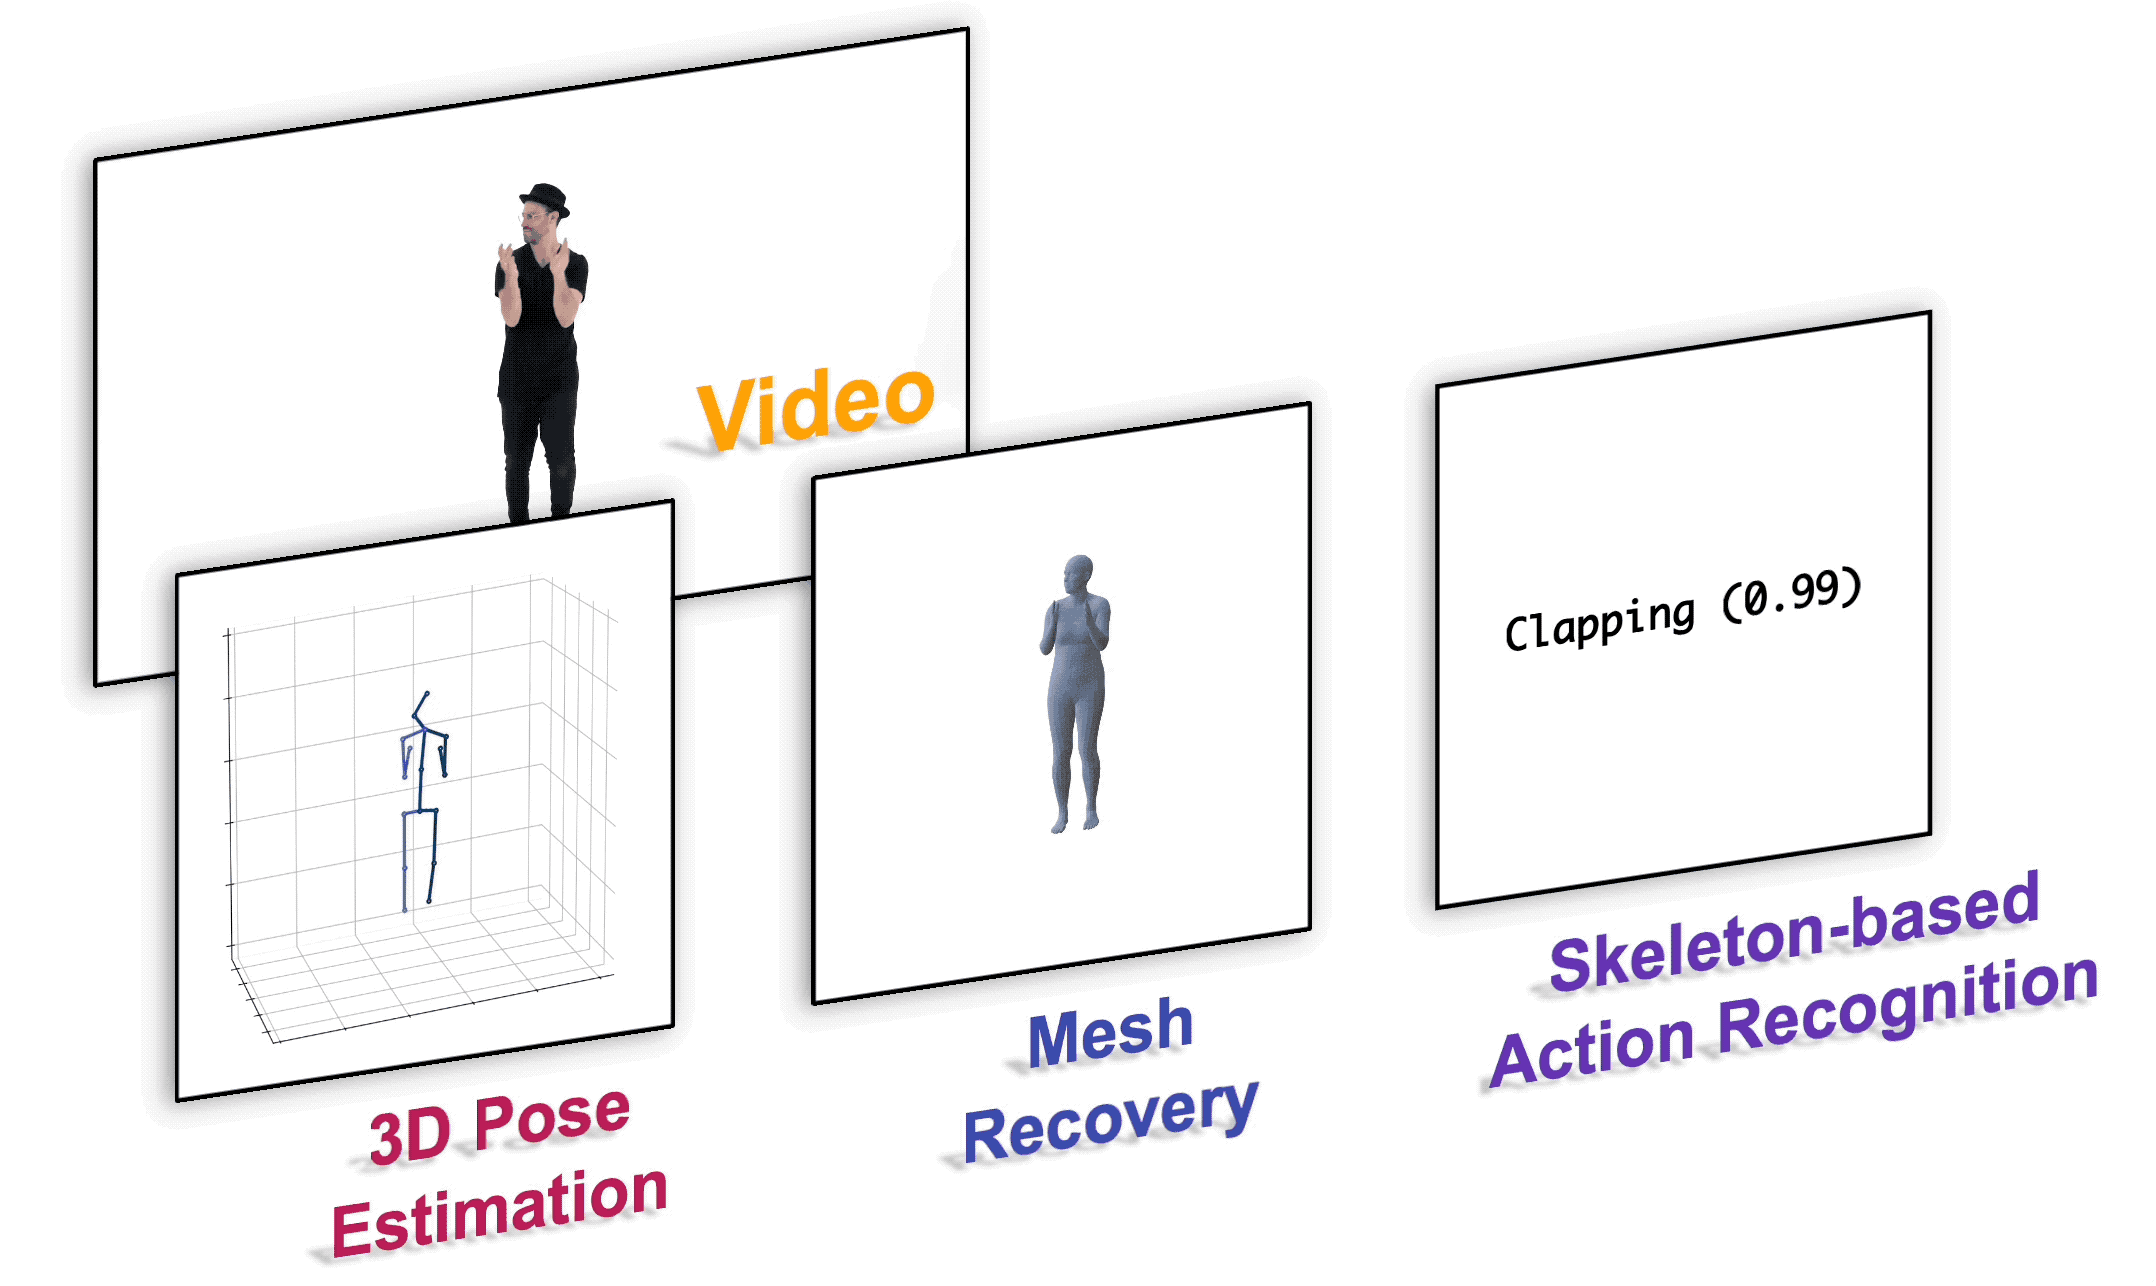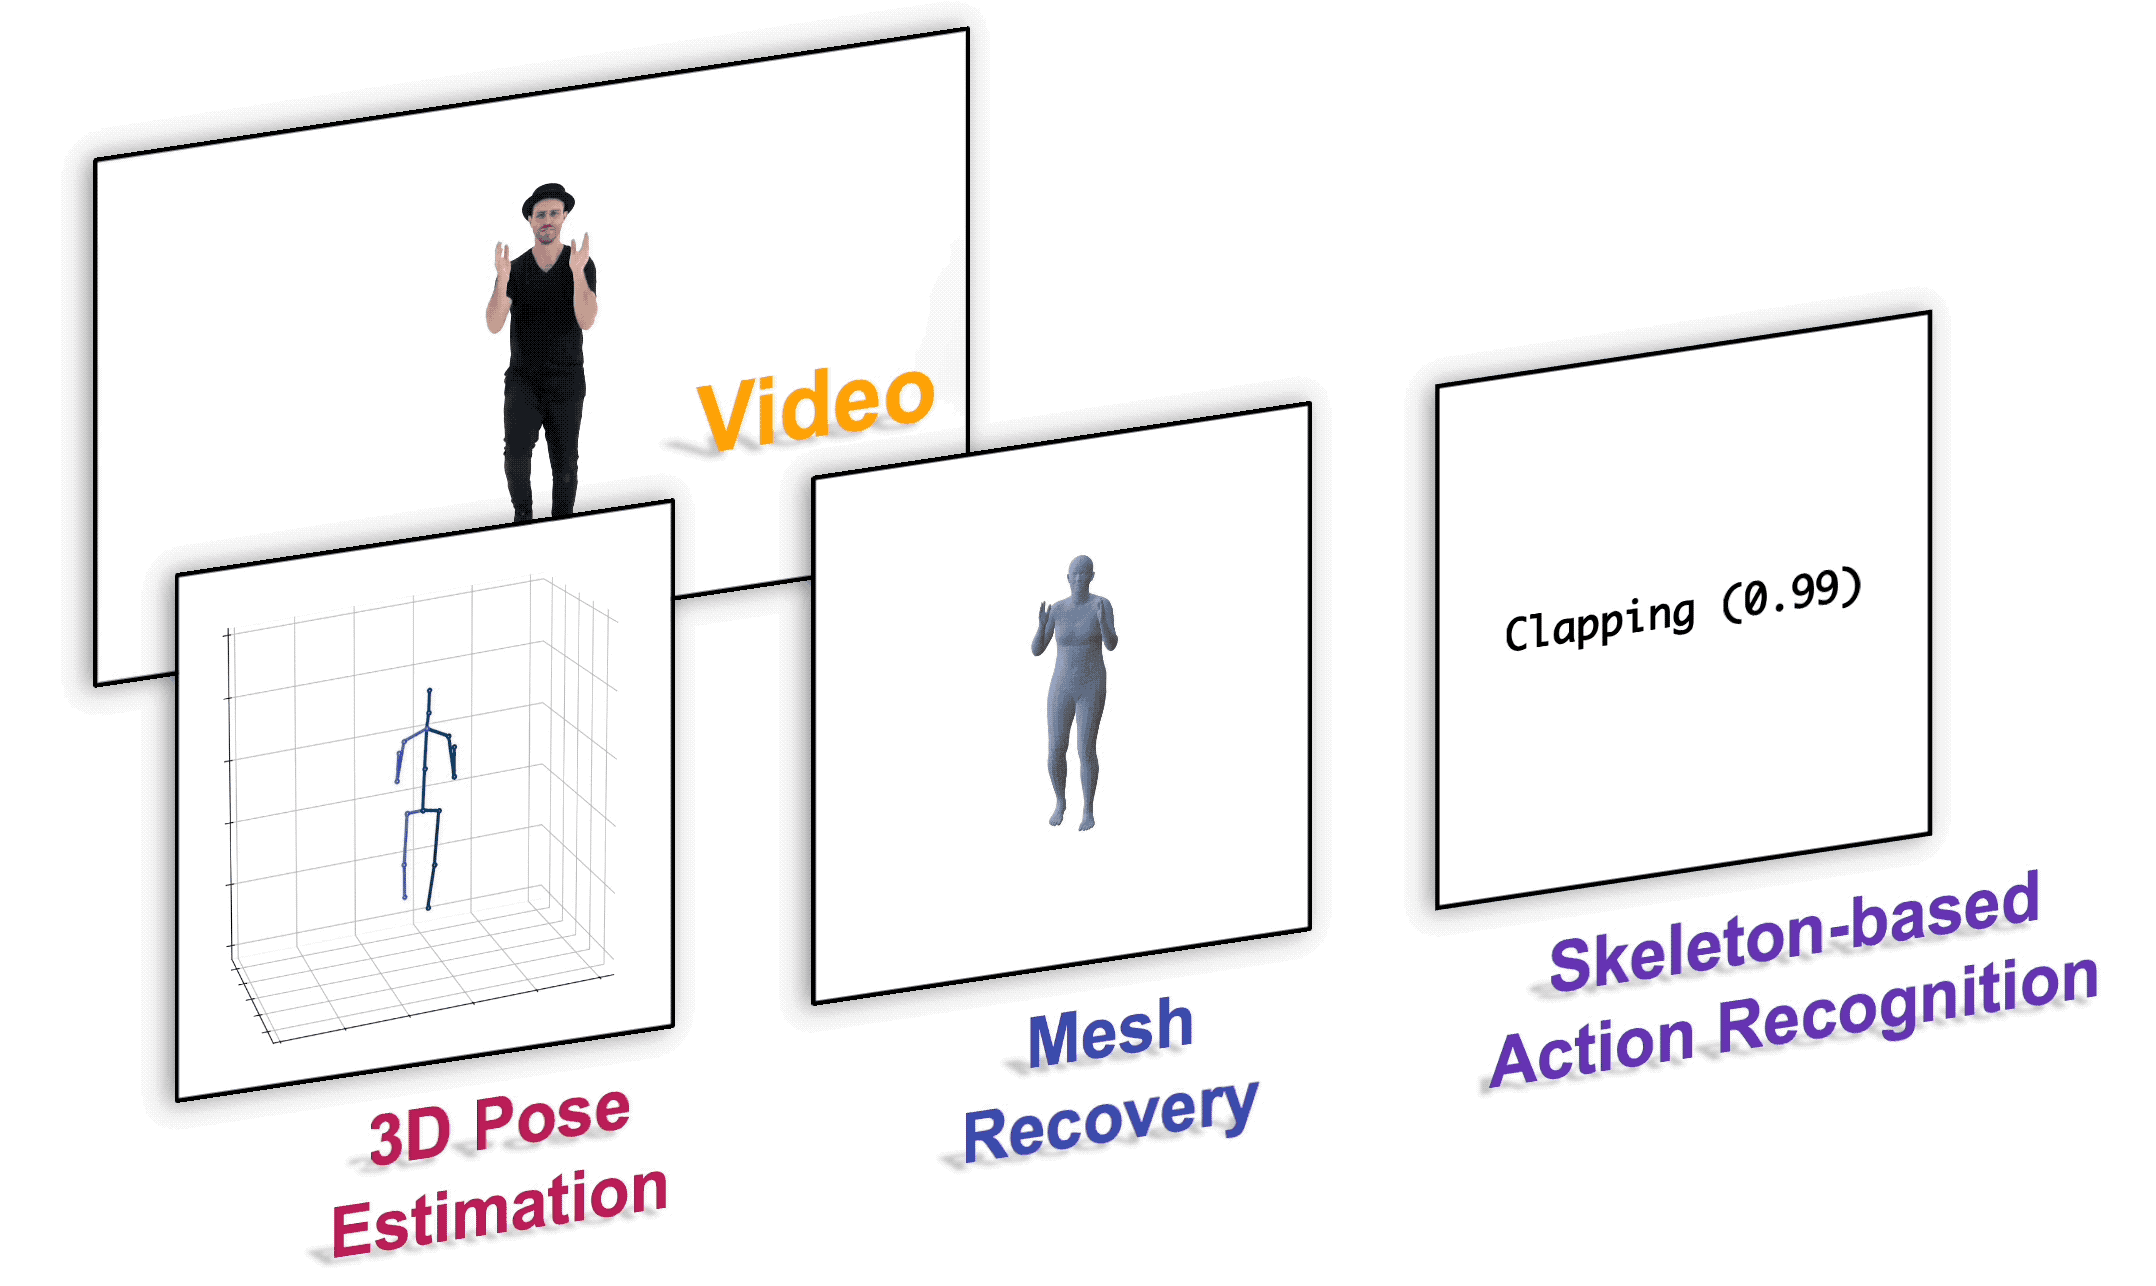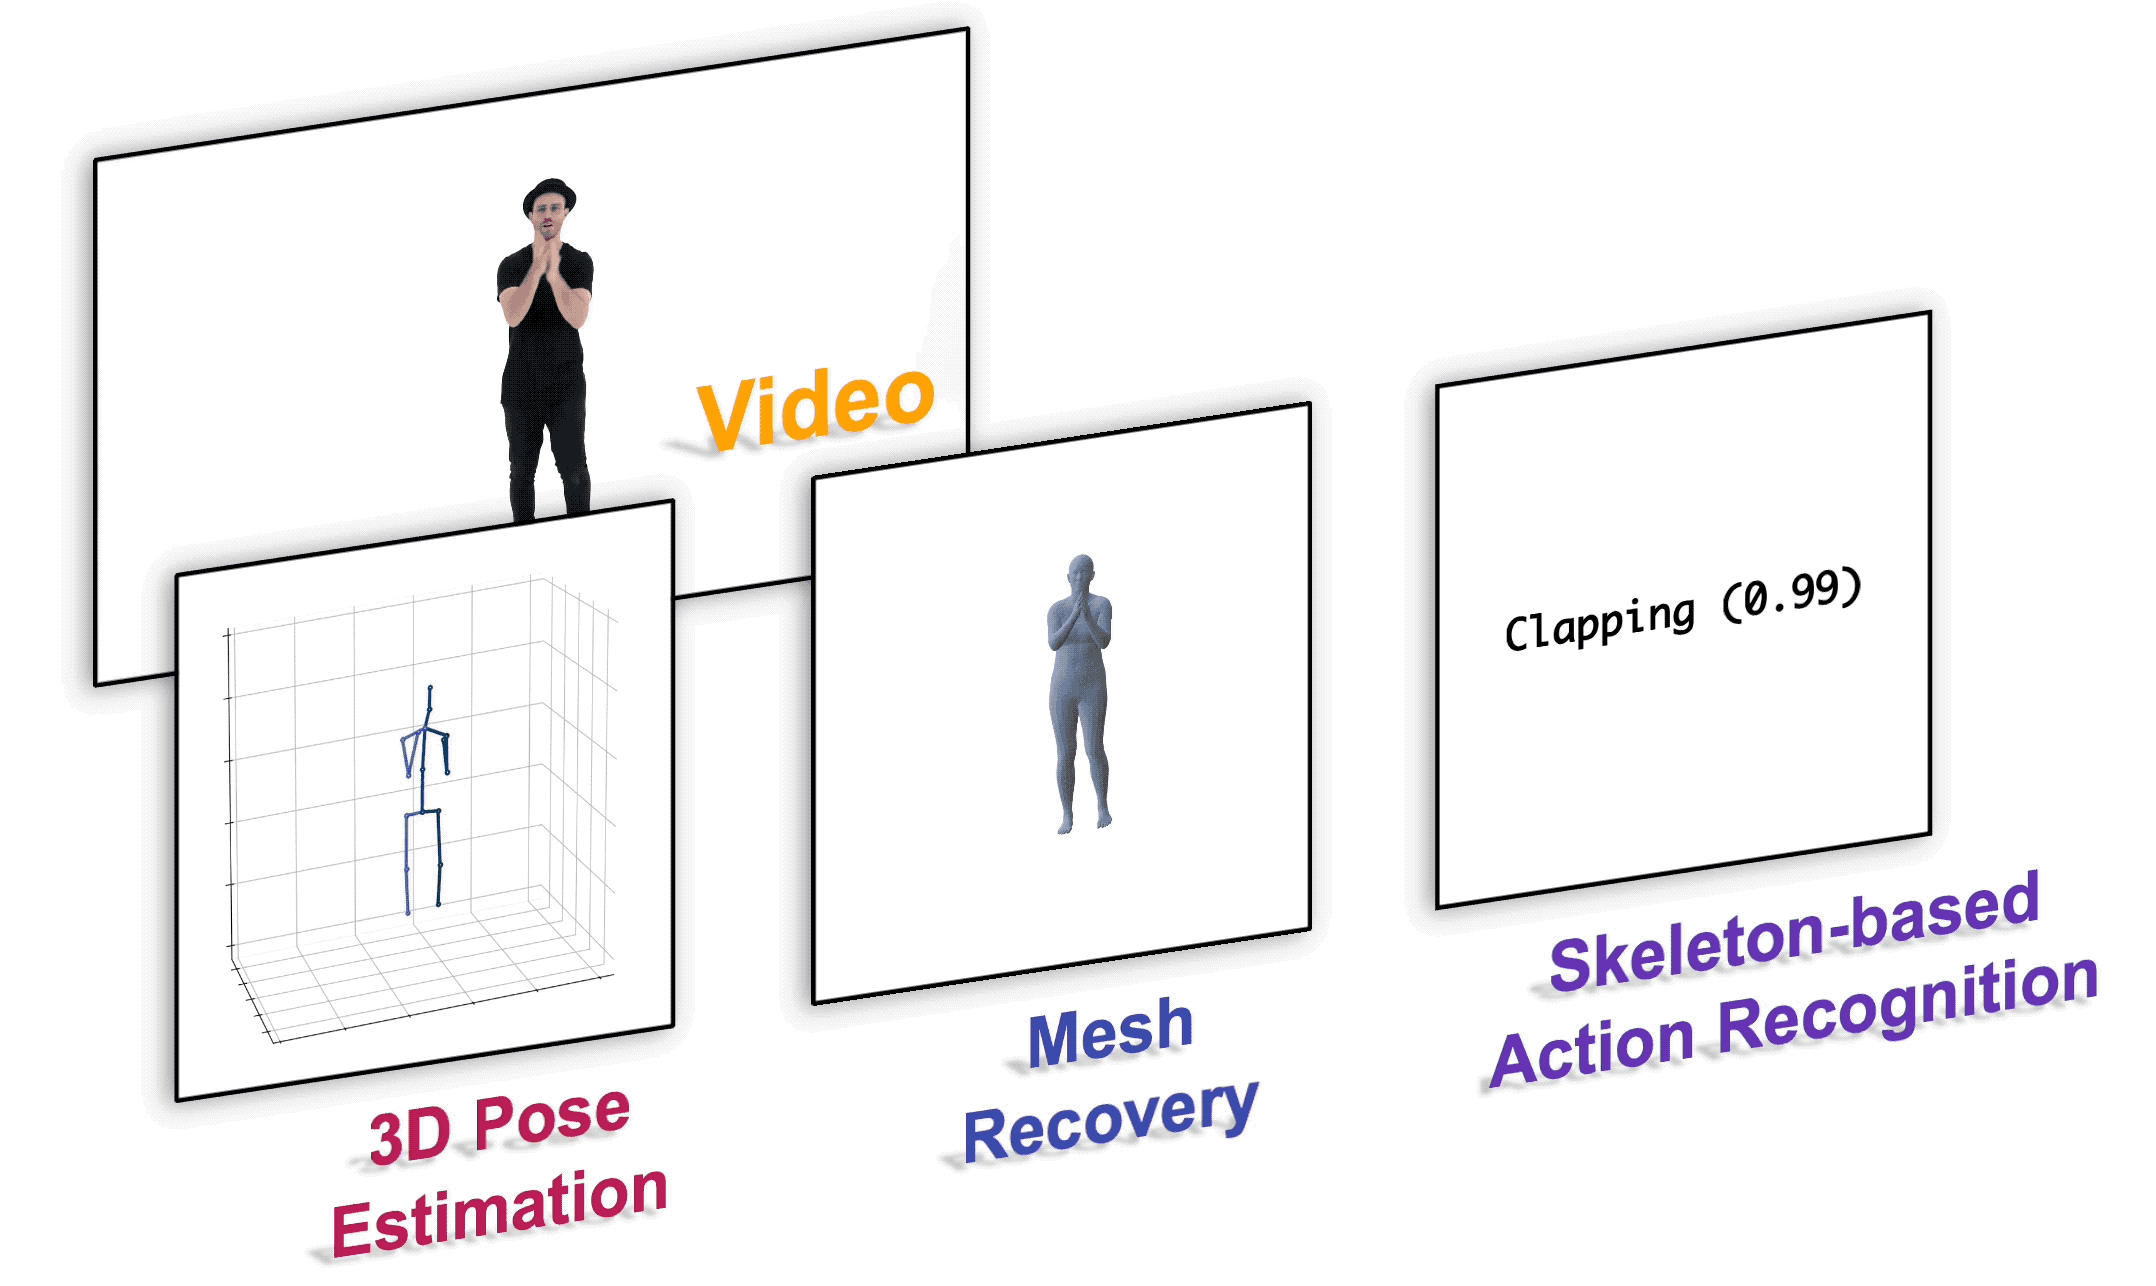
Installation
conda create -n motionbert python=3.7 anaconda
conda activate motionbert
# Please install PyTorch according to your CUDA version.
conda install pytorch torchvision torchaudio pytorch-cuda=11.6 -c pytorch -c nvidia
pip install -r requirements.txt
Getting Started
| Task | Document |
|---|---|
| Pretrain | docs/pretrain.md |
| 3D human pose estimation | docs/pose3d.md |
| Skeleton-based action recognition | docs/action.md |
| Mesh recovery | docs/mesh.md |
Applications
In-the-wild inference (for custom videos)
Please refer to docs/inference.md.
Using MotionBERT for human-centric video representations
'''
  x: 2D skeletons
    type = <class 'torch.Tensor'>
    shape = [batch size * frames * joints(17) * channels(3)]

  MotionBERT: pretrained human motion encoder
    type = <class 'lib.model.DSTformer.DSTformer'>

  E: encoded motion representation
    type = <class 'torch.Tensor'>
    shape = [batch size * frames * joints(17) * channels(512)]
'''
E = MotionBERT.get_representation(x)
Hints
- The model could handle different input lengths (no more than 243 frames). No need to explicitly specify the input length elsewhere.
- The model uses 17 body keypoints (H36M format). If you are using other formats, please convert them before feeding to MotionBERT.
- Please refer to model_action.py and model_mesh.py for examples of (easily) adapting MotionBERT to different downstream tasks.
- For RGB videos, you need to extract 2D poses (inference.md), convert the keypoint format (dataset_wild.py), and then feed to MotionBERT (infer_wild.py).
Model Zoo
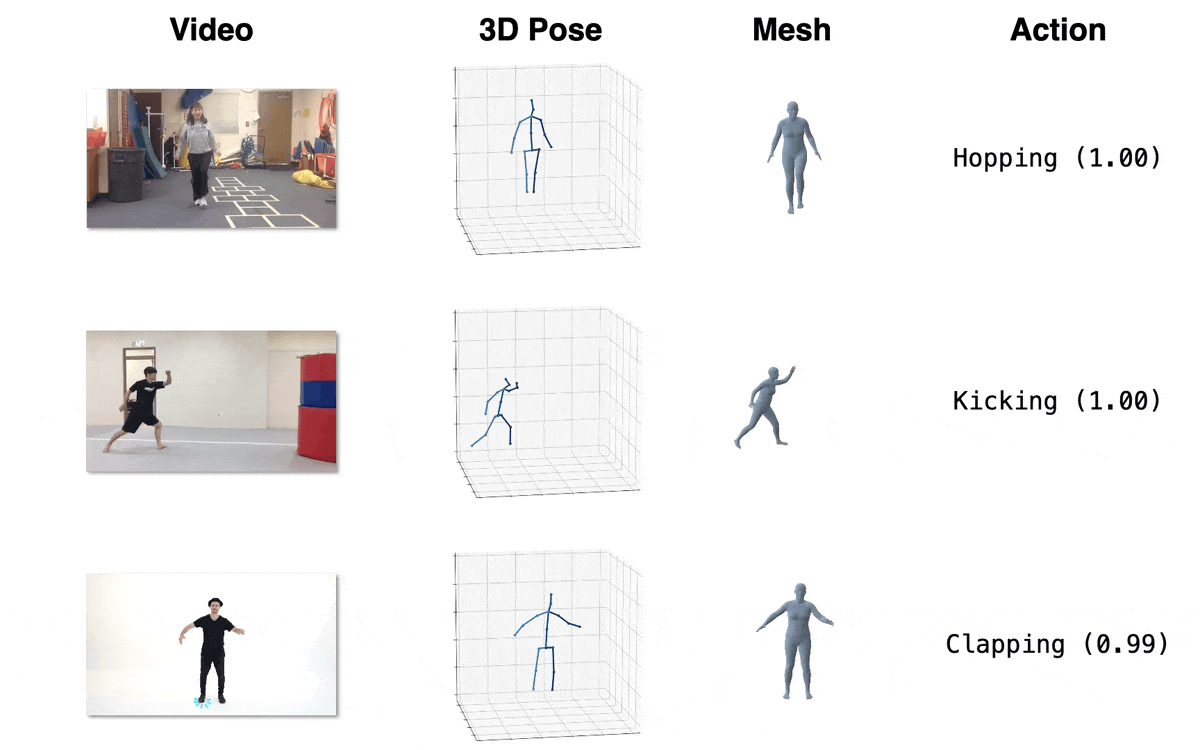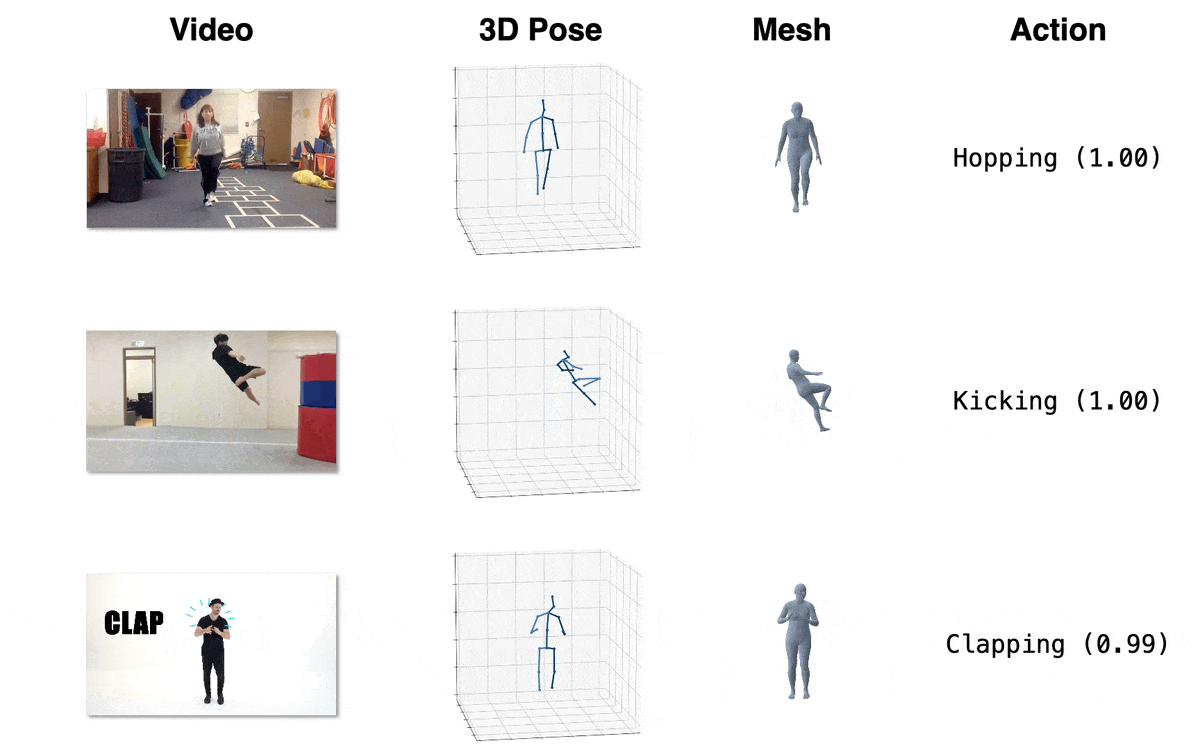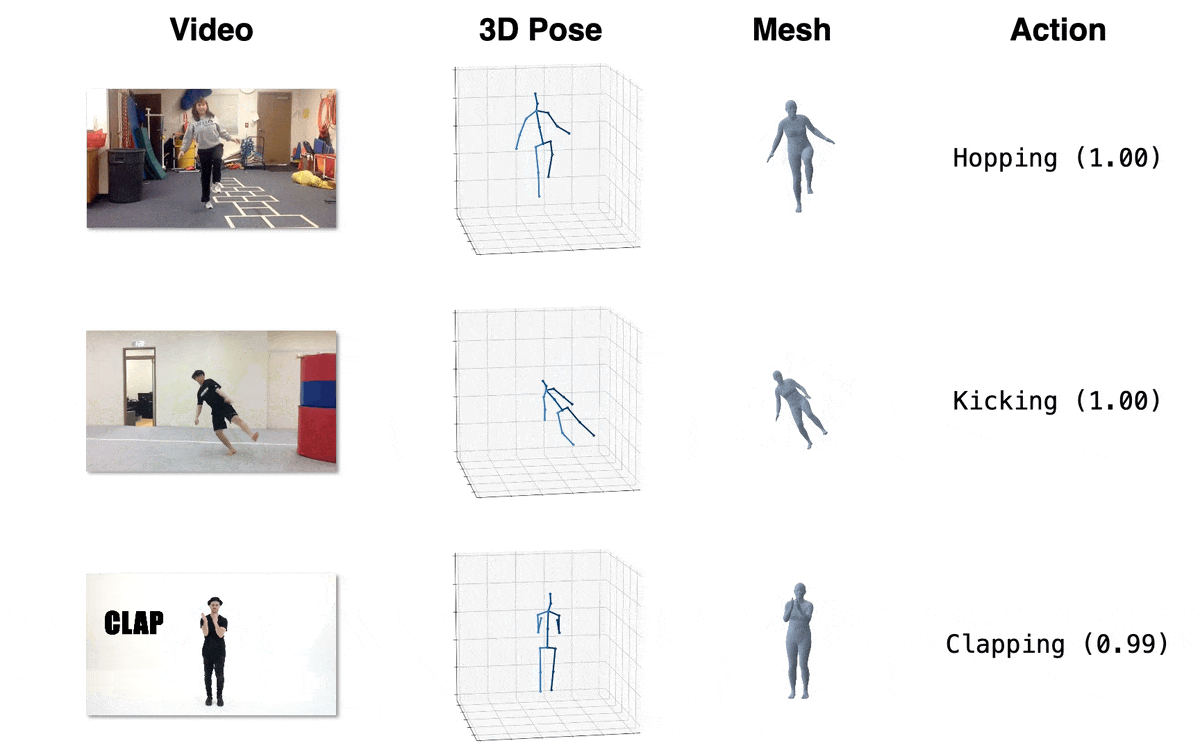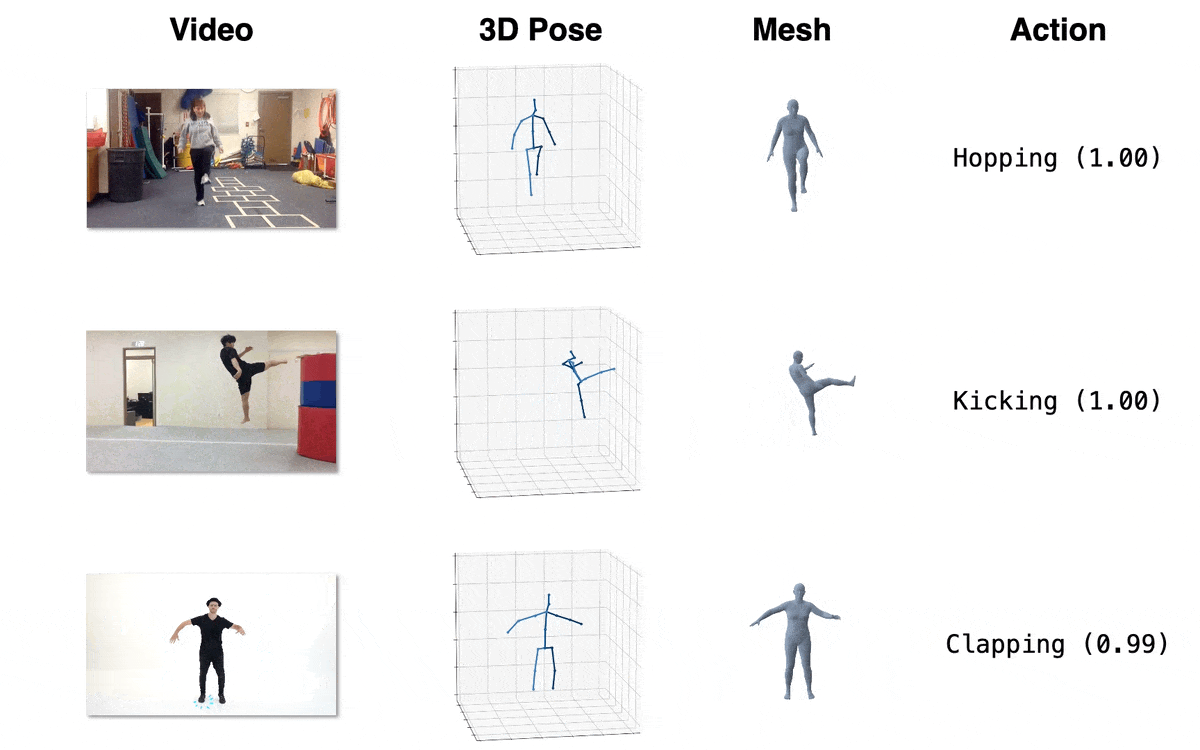
| Model | Download Link | Config | Performance |
|---|---|---|---|
| MotionBERT (162MB) | OneDrive | pretrain/MB_pretrain.yaml | - |
| MotionBERT-Lite (61MB) | OneDrive | pretrain/MB_lite.yaml | - |
| 3D Pose (H36M-SH, scratch) | OneDrive | pose3d/MB_train_h36m.yaml | 39.2mm (MPJPE) |
| 3D Pose (H36M-SH, ft) | OneDrive | pose3d/MB_ft_h36m.yaml | 37.2mm (MPJPE) |
| Action Recognition (x-sub, ft) | OneDrive | action/MB_ft_NTU60_xsub.yaml | 97.2% (Top1 Acc) |
| Action Recognition (x-view, ft) | OneDrive | action/MB_ft_NTU60_xview.yaml | 93.0% (Top1 Acc) |
| Mesh (with 3DPW, ft) | OneDrive | mesh/MB_ft_pw3d.yaml | 88.1mm (MPVE) |
In most use cases (especially with finetuning), MotionBERT-Lite gives a similar performance with lower computation overhead.
TODO
Scripts and docs for pretraining
Demo for custom videos
Citation
If you find our work useful for your project, please consider citing the paper:
@inproceedings{motionbert2022,
  title     =   {MotionBERT: A Unified Perspective on Learning Human Motion Representations},
  author    =   {Zhu, Wentao and Ma, Xiaoxuan and Liu, Zhaoyang and Liu, Libin and Wu, Wayne and Wang, Yizhou},
  booktitle =   {Proceedings of the IEEE/CVF International Conference on Computer Vision},
  year      =   {2023},
}
Explore related projects
tensorflow/tensorflow
An Open Source Machine Learning Framework for Everyone
201,367 starshuggingface/transformers
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
168,609 starsAUTOMATIC1111/stable-diffusion-webui
Stable Diffusion web UI
165,245 starsComfy-Org/ComfyUI
The most powerful and modular diffusion model GUI, api and backend with a graph/nodes interface. The fastest local inference engine in the world.
145,470 stars