
Unknown-333/awesome-data-engineering-skills
Unknown-333/awesome-data-engineering-skills has 27 GitHub stars and 1 forks. Star changes are not measured yet. Last checked 2026-11-14 02:46 UTC. Last push 2026-08-30.
Measured star growth
- in 24h
- Collecting history
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
36 data-engineering skills for AI coding agents — dbt, Airflow, Dagster, Prefect, Spark, Snowflake, BigQuery, Databricks, Kafka, Iceberg. Portable SKILL.md Agent Skills (the format Anthropic launched as Claude Skills), with idempotency, backfill, and data-quality know-how. Runs in Claude Code, Cursor, Codex, Copilot, Gemini CLI and more.
DataREADME.md
Original
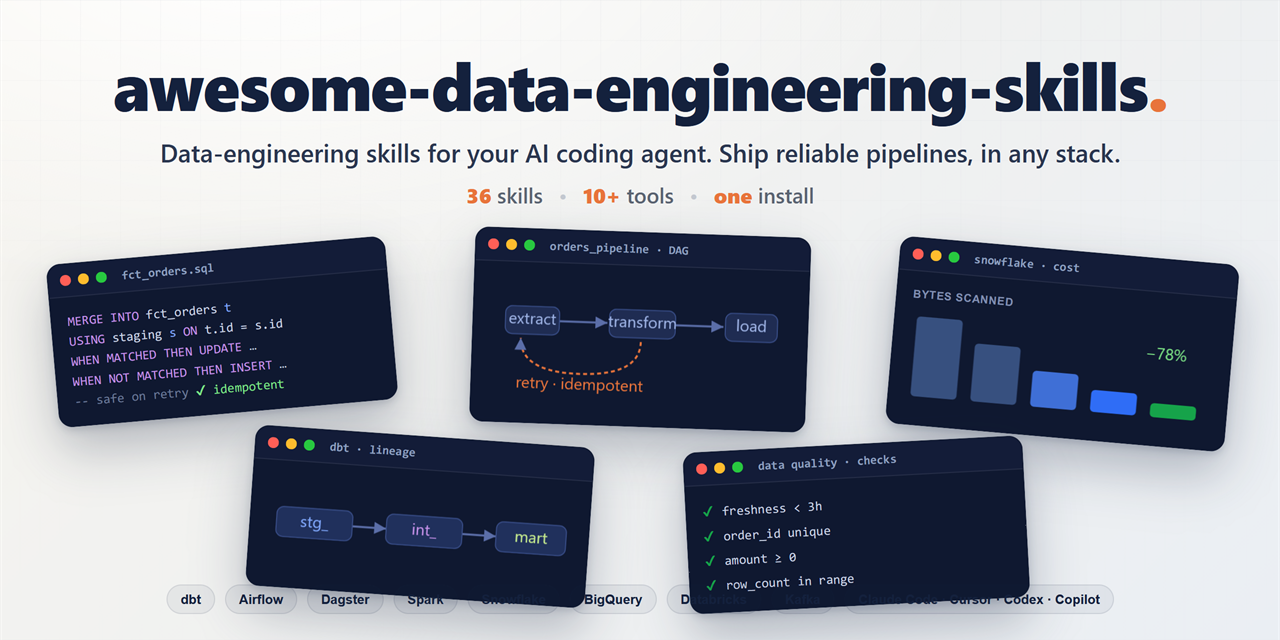
Awesome Data Engineering Skills


A curated, portable collection of Agent Skills that make AI coding agents genuinely useful for data engineering work — dbt, Airflow, Dagster, Spark, Snowflake, BigQuery, Databricks, data quality, idempotency, backfills, and pipeline operations.
Each skill is a folder with a SKILL.md the agent loads only when relevant, so
your context stays lean until you need the expertise. Skills follow the open Agent
Skills standard and work across Claude Code, Cursor, Codex, GitHub Copilot,
Gemini CLI, and other compatible agents.
Built from real, recurring data-engineering pain points (idempotency & backfills, silent schema changes, data quality incidents, warehouse cost, testing pipelines) — not generic advice.
Why skills for data engineering?
Data bugs are expensive and quiet: a non-idempotent retry duplicates a fact table,
a backfill rewrites yesterday's revenue, a SELECT * becomes a recurring bill.
These skills encode the correct default so the agent gets it right the first time.
Skill catalog
SQL & data modeling
| Skill | Use it when |
|---|---|
| optimizing-sql-queries | A query is slow/expensive, scans too much, or spills — across Postgres, Snowflake, BigQuery, Spark, Redshift |
| modeling-dimensional-data | Designing star/snowflake schemas, choosing grain, or tracking history with SCDs |
| writing-idempotent-transformations | A retry could duplicate data, or a load must be backfill-safe |
dbt
| Skill | Use it when |
|---|---|
| building-dbt-models | Creating/refactoring models, choosing materialization, writing incremental logic |
| testing-dbt-projects | Adding tests, catching data quality regressions, source freshness |
| debugging-dbt-runs | dbt run/build fails, incremental is stale/duplicated, CI differs from local |
| documenting-dbt-models | Adding descriptions, exposures, and generated docs/lineage |
Orchestration
| Skill | Use it when |
|---|---|
| authoring-airflow-dags | Writing DAGs, scheduling, retries/backfills, fixing non-idempotent tasks |
| debugging-airflow-pipelines | A task fails or is stuck queued, scheduler won't run, zombie tasks |
| building-dagster-assets | Building software-defined assets, partitions, resources, asset checks |
| orchestrating-prefect-flows | Writing Prefect flows/tasks, retries, caching, deployments/schedules |
Distributed processing
| Skill | Use it when |
|---|---|
| optimizing-pyspark-jobs | A Spark job is slow, spills, OOMs, or has skew/large shuffles |
| engineering-databricks-pipelines | Building Delta/DLT pipelines, Auto Loader, Unity Catalog |
Lakehouse & storage
| Skill | Use it when |
|---|---|
| designing-medallion-architecture | Organizing a lakehouse into bronze/silver/gold layers |
| building-iceberg-tables | Creating/maintaining Iceberg tables, partitioning, compaction, time travel |
| optimizing-parquet-storage | Slow/costly Parquet reads, small-files problem, compression/layout |
Warehouses & cost
| Skill | Use it when |
|---|---|
| optimizing-snowflake-workloads | Snowflake is slow/expensive, warehouses spill/queue, sizing decisions |
| optimizing-bigquery-queries | BigQuery bytes billed are high or a query full-scans |
Data quality & contracts
| Skill | Use it when |
|---|---|
| implementing-data-quality-checks | Catching bad data before consumers — freshness, volume, schema, integrity |
| designing-data-contracts | A producer change could silently break downstream pipelines |
| handling-schema-evolution | Adding/renaming/retyping columns without breaking readers |
Ingestion & streaming
| Skill | Use it when |
|---|---|
| building-ingestion-pipelines | Extracting from DBs/APIs/files — incremental, CDC, watermarks, pagination |
| processing-streaming-data | Kafka/Spark/Flink streaming — delivery semantics, windowing, late data |
| building-kafka-consumers | Writing Kafka consumers/producers, offsets, consumer groups, dead-letter |
| implementing-cdc-with-debezium | Replicating an OLTP DB with CDC, capturing deletes, applying change streams |
Pipeline engineering & ops
| Skill | Use it when |
|---|---|
| debugging-data-pipelines | Numbers look wrong, data missing/duplicated, a dashboard is stale |
| designing-backfills-and-replays | Backfilling history or reprocessing after a fix — safely |
| implementing-pipeline-observability | Failures are found by stakeholders, not alerts; setting SLAs/monitoring |
| reviewing-data-pipeline-code | Reviewing a data PR for idempotency, grain, cost, tests, PII |
| implementing-data-cicd | Adding CI (lint/compile/test), dbt Slim CI, environment promotion |
| managing-data-lineage-openlineage | Cross-tool lineage, impact analysis, scoping incidents/backfills |
| migrating-legacy-etl | Migrating SSIS/Informatica/stored procs/on-prem to dbt/Spark/cloud |
| generating-synthetic-test-data | Realistic seeded test data, edge cases, referential integrity |
Platform, governance & ML
| Skill | Use it when |
|---|---|
| terraform-for-data-infra | Provisioning warehouses/buckets/IAM/orchestration as code |
| masking-pii-data | Masking/tokenizing PII, dynamic masking, GDPR/CCPA/HIPAA, deletion |
| building-feature-pipelines | ML features, point-in-time joins, offline/online parity, feature stores |
Install
Skills live in this repo under skills/. Point your agent at them by copying or
symlinking into the tool's skills directory. .agents/skills/ is recognized by the
widest set of tools.
Quick install (macOS/Linux)
./scripts/install.sh claude     # -> ./.claude/skills/   (Claude Code)
./scripts/install.sh cursor     # -> ./.cursor/skills/   (Cursor)
./scripts/install.sh codex      # -> ./.codex/skills/    (Codex)
./scripts/install.sh copilot    # -> ./.github/skills/   (GitHub Copilot)
./scripts/install.sh agents     # -> ./.agents/skills/   (broadest support)
# add --user for a global install, --copy to copy instead of symlink
Per-tool skills directories
| Tool | Project path | Personal (global) path |
|---|---|---|
| Claude Code | .claude/skills/ or .agents/skills/ |
~/.claude/skills/ |
| Cursor | .cursor/skills/ or .agents/skills/ (also reads .claude/, .codex/) |
~/.cursor/skills/, ~/.agents/skills/ |
| Codex | .codex/skills/ |
~/.codex/skills/ |
| GitHub Copilot | .github/skills/, .claude/skills/, or .agents/skills/ |
~/.copilot/skills/, ~/.agents/skills/ |
Claude Code plugin (optional)
Install the whole set as a plugin marketplace:
/plugin marketplace add <your-org>/awesome-data-engineering-skills
/plugin install data-engineering-skills@awesome-data-engineering-skills
How skills load
- Discovery — the agent preloads each skill's
name+description(~tiny). - Activation — when your task matches, it reads the full
SKILL.md. - Resources — deeper
references/*.mdload only when needed.
You can also invoke a skill directly by typing / in chat and picking it by name.
Portability
Phase-1 skills use only the portable spec frontmatter (name, description) so
they behave identically across tools. Tool-specific extensions (dynamic command
injection, forked subagents, paths) are intentionally avoided. See
CONTRIBUTING.md.
Contributing
New skills and improvements welcome — see CONTRIBUTING.md. Validate before opening a PR:
python scripts/validate_skills.py   # frontmatter, naming, references
python scripts/check_evals.py       # every skill has trigger/non-trigger evals
Each skill has description-tuning eval cases in evals/triggering.json (prompts that should and should not activate it) to keep discovery accurate.
Roadmap (backlog)
The initial catalog above covers the core plus the first expansion set. Candidate
future skills: writing-great-expectations-suites · tuning-warehouse-costs ·
building-realtime-analytics · managing-data-catalogs · orchestrating-dbt-airflow.
License
Explore related projects
Asabeneh/30-Days-Of-Python
The 30 Days of Python programming challenge is a step-by-step guide to learn the Python programming language in 30 days. This challenge may take more than 100 days. Follow your own pace. These videos may help too: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,710 starsgrafana/grafana
The open and composable observability and data visualization platform. Visualize metrics, logs, and traces from multiple sources like Prometheus, Loki, Elasticsearch, InfluxDB, Postgres and many more.
77,892 starsredis/redis
For developers, who are building real-time data-driven applications, Redis is the preferred, fastest, and most feature-rich cache, data structure server, and document and vector query engine.
77,490 starsapache/superset
Apache Superset is a Data Visualization and Data Exploration Platform
75,521 stars