
ThinkFlowLab/agentdescent
ThinkFlowLab/agentdescent has 220 GitHub stars and 29 forks. GitHot measured +1 stars in 24 hours. Last checked 2026-11-16 00:08 UTC. Last push 2026-11-15.
Measured star growth
- in 24h
- +1
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Gradient descent, but the parameters are agents — a parallel, asynchronous framework for self-evolving agents (skills, prompts, harnesses). Diffs are the gradients; the aggregator is the optimizer.
AIREADME.md
OriginalAgentDescent
Website & interactive demo · Get started · Documentation
Gradient descent — but the parameters are agents. AgentDescent evolves prompts, skills, agent directories, agent code and host plugins against your own examples. N workers propose edits in parallel, one aggregator merges them into a version-controlled artifact, and a held-out gate decides what is kept. Use it from Python with one
evolve()call, from the CLI, or from inside Claude Code, Codex, OpenCode, DeepSeek Harness or Grok Bot — and swap in any of the named algorithms or twenty-three published-method ports on the same engine.


Install
pip install "agentdescent[mcp]>=0.10.0"
agentdescent demo                         # a complete evolution, offline, no API key, ~10 s
agentdescent doctor                       # which agent CLIs and provider keys this machine has
Host / MCP default loop is Path A (doctor → plan → start → apply); advanced MCP tools need agentdescent mcp --advanced — see docs/mcp-path-a.md.
[mcp] adds the agent-facing MCP server and needs Python ≥ 3.10; the library
itself supports 3.9, where you drop [mcp] and drive it with the CLI. Research examples are outside the wheel: to run
python -m examples.run_demo or any algorithm port, clone the repo and follow
install and first run:
git clone https://github.com/ThinkFlowLab/agentdescent && cd agentdescent
pip install -e ".[dev,mcp]"
agentdescent demo builds a skill whose rules name the wrong CSV column, twelve
cases with known totals and a local program as the agent, then runs the real
loop — only the model is replaced — and ends with:
held-out reward: 1.000 outcomes: {'committed': 1}
what it learned: rules.md -> 'COLUMN: amount'
60-second quickstart
Runnable as-is — no API key, no dependencies. Three functions are the whole contract: how to run a task, how to score it, and what to propose on a failure.
from agentdescent import Task, evolve

tasks = [Task(id=f"t{i}", prompt=f"item {i}") for i in range(12)]

def reward(task, output):                  # must return [0, 1]
    return 1.0 if "2026" in output else 0.0

def run(rendered, task):                   # your solver
    return "answer" + (" 2026" if "year" in rendered else "")

def propose(rendered, task, output, reward):   # what to add on a failure
    return "always state the year"

result = evolve(tasks, reward, run=run, propose=propose,
                rounds=6, n_workers=3, max_concurrency=3)
print(result.rendered, result.final_reward, result.error)
With a real model and a real dataset
Credentials are read from the environment at call time — never from code — and the base URL picks the provider (every provider →):
export OPENAI_BASE_URL=https://api.deepseek.com   # or GLM, Ark, a local vLLM, OpenAI itself
export OPENAI_API_KEY=sk-...                      # your key for *that* endpoint
from agentdescent import SingleSlot, evolve, openai_compatible, reflector, scorer, tasks_from
from agentdescent.dataloader import hf_rows

rows = hf_rows("hotpotqa/hotpot_qa", "validation", config="distractor", limit=40)
model = openai_compatible(model="deepseek-v4-flash")

tasks = tasks_from(rows, prompt="question", gold="answer")     # rows -> Task objects
run = lambda instruction, task: model(f"{instruction}\n\n{task.prompt}")

result = evolve(tasks, scorer("exact"), run=run, propose=reflector(model),
                strategy=SingleSlot(initial_value="You are a helpful assistant."),
                rounds=8, n_workers=8, max_concurrency=8, held_out_frac=0.3,
                patience=3, target_reward=0.98)

print(result.rendered)        # the instruction it learned
print(result.final_reward)    # held-out reward
print(result.outcomes())      # why it went that way
On 40 HotpotQA items (12 held out) this took held-out exact match from 0.167
to 0.583, learning "Respond with only the requested answer, omitting any extra
explanation or restatement." That evolves an instruction (SingleSlot), not
an Agent Skill folder — for a library run agentdescent demo --kind skill_library.
Pass agent=LLMAgent(claude_code()) (or any
agent or LLM) instead of
run/propose to evolve against a tool-using CLI agent.
Quickstart — dataset to skill →
From the CLI, on a file or directory
agentdescent init ./my-skill --data cases.jsonl --out spec.json   # cases: {"prompt": ..., "gold": ...} per line
agentdescent plan spec.json            # validates and prices it; runs nothing
agentdescent evolve spec.json --detach
agentdescent status                    # then: show <run_id>, apply <run_id> --dry-run, apply <run_id>
Nothing is written back until apply, which backs up first.
Call any algorithm
Every named algorithm is a set of defaults over the same engine, selectable by name from the CLI, a spec, MCP, or the host plugins:
agentdescent algorithms list                   # ace, archive_selection, dgm, evoskill, gepa, rrsi, skillopt, …
agentdescent algorithms show gepa              # what it changes, its parameters
agentdescent algorithms run gepa ./prompt.txt cases.jsonl --rounds 1 --workers 1   # writes a spec and plans it
agentdescent demo --algorithm archive_selection   # watch one run offline
In a spec it is one field — "algorithm": "gepa" or
{"name": "gepa", "params": {...}} — and every explicit field still wins.
The catalog →
Cards vs ports: Path A names cards (wheel mechanism slices). The
twenty-three research ports are source-only under examples/ — same slug is
not the same fidelity; never read a card run as paper numbers
(decision tree, #384).
Ports run from a checkout, each with a --dry-run that needs no API key:
- Benchmark-faithful (8): ACE · GEPA · EvoSkill · SkillOpt · ADAS · DGM · OpenEvolve · ERA
- Microports and analogues (15): PromptBreeder · AFlow · Self-Refine · Reflexion · SICA · Gödel Agent · Voyager · SkillWeaver · Absolute Zero · R-Zero · Agent0 · gskill · TextGrad · Dynamic Cheatsheet · Genesis
python -m examples.gepa.gepa_prompt_evolution --dry-run
python -m examples.ace.ace_context_evolution --model claude-haiku-4-5 --async   # barrier-free
Fidelity is declared per port and follows each project's released code; analogues are not benchmark reproductions. All twenty-three, with measured results →
Add an algorithm
A named card, in one PR — a
build(ctx, params) -> Overridesthat fills policy slots andevolve()knobs. Copyagentdescent/algorithms/_TEMPLATE.py, register it, and regenerate the catalog withpython -m tools.gen_algorithms_docs. Register a named Algorithm card →From your own package — no fork needed; expose it as an entry point and
agentdescent algorithms listpicks it up:[project.entry-points."agentdescent.algorithms"] my_method = "my_pkg:ALGORITHM"A full research port — porting checklist (benchmark-faithful) or MethodPolicy checklist (microports).
Use it from your agent
The same engine as a plugin: a shared skill teaches the host when to reach
for it, an MCP server exposes doctor / plan / start / status / show / apply / cancel / resume (and the algorithm, audit and archive tools), and the CLI
mirrors them, so a run started from an agent can be inspected from a shell.
| host | install | then |
|---|---|---|
| Claude Code | agentdescent install claude-code |
claude --plugin-dir ~/.agentdescent/plugins/claude-code |
| Codex | codex plugin marketplace add ThinkFlowLab/agentdescent && codex plugin add agentdescent@agentdescent |
codex mcp list |
| OpenCode | agentdescent install opencode |
opencode mcp list |
| DeepSeek Harness | agentdescent install dsh |
dsh --profile web --dump-config | grep agentdescent |
| Grok Bot | agentdescent install grok-bot (a scaffold, not one-click) |
read HOST.md; MCP via agentdescent mcp --transport streamable-http --http-token-env AGENTDESCENT_MCP_TOKEN behind an HTTPS tunnel, with that bearer token as the connector's header |
From a checkout, bash scripts/setup-hosts.sh installs AgentDescent and wires
every agent CLI it finds. Then say "improve this prompt against these
examples" inside the agent: it runs doctor, writes a spec, quotes the call
count before starting, waits for your yes, runs detached, and asks again
before it writes anything back. No cases yet is not a blocker — it drafts 8–20
for you to check first.
kind is text, skill_dir, skill_library (multi-file */SKILL.md tree),
agent_dir, agent_code, policy_slot — or plugin: the host plugins
themselves are evolvable, each rollout in an isolated copy of the host with
hooks and permissions frozen and a recursion guard. Flagship library demo:
agentdescent demo --kind skill_library.
The plugin, step by step →
· set it up and test it →
How it works
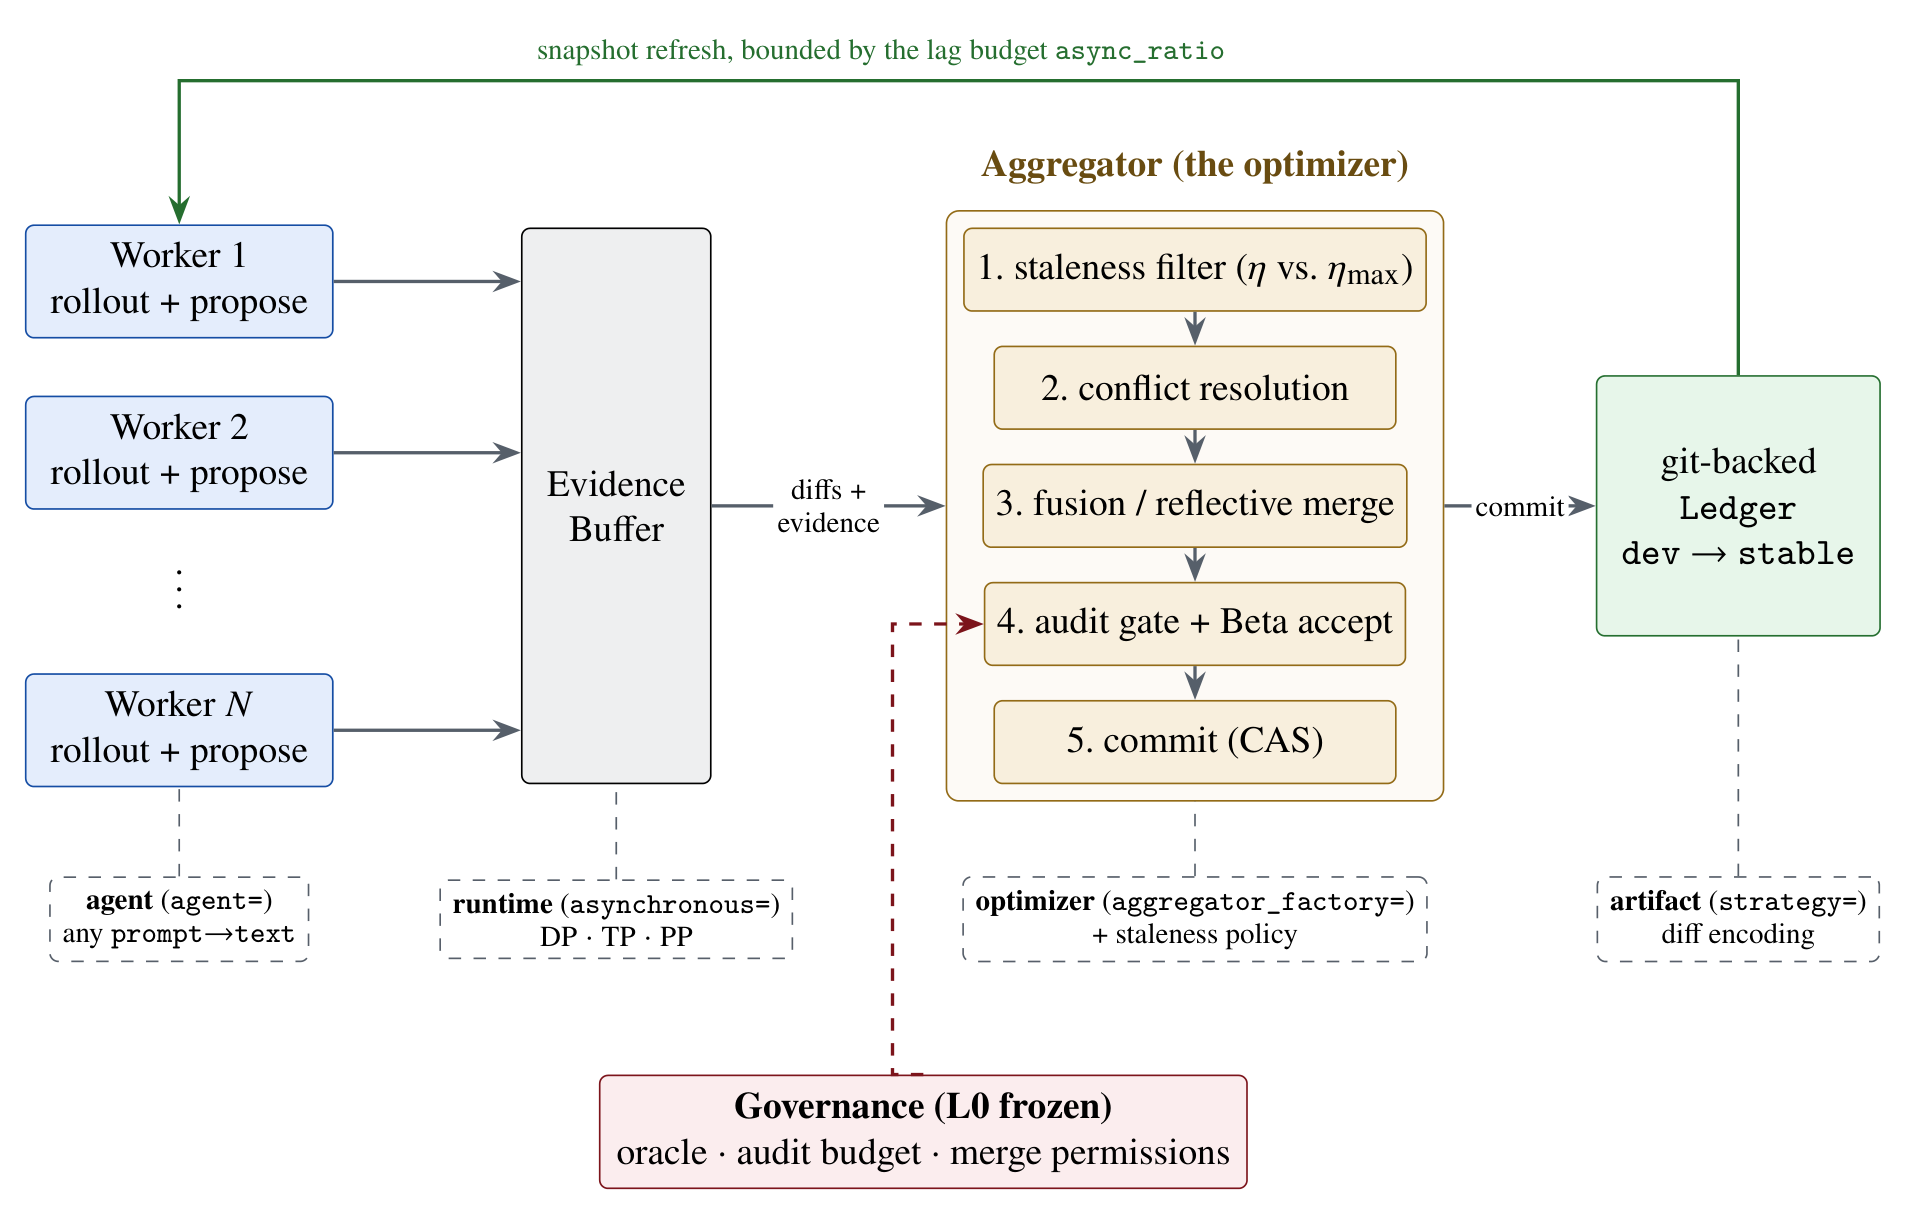
Serial self-improvement is bounded at one accepted change per iteration;
merging concurrent edits is the attempt to lift that bound. The analogy breaks
exactly where the design lives: gradients add, diffs do not, so aggregation
is conflict resolution, fusion, statistical acceptance and a transactional
commit rather than averaging. The governance layer (red) is deliberately not a
seam — a self-modifying system must not be able to replace its own evaluator.
The figure is regenerated from TikZ by
tools/gen_architecture_figure.py.
What you can replace. Two typing.Protocol seams carry the algorithm:
- the strategy — what evolves.
AppendRules(lessons; proposals almost always fuse),KeyedRules(one entry per category),FileTree(a directory, one key per path),SingleSlot(one value; proposals always contradict), or your own three-method class. Its key space decides whether concurrent edits can fuse at all. - eight policy slots — the rules of evolution:
selection,task_sampler,proposal,staleness,conflict,fusion,acceptance,promotion. Each defaults to the shipped rule; a driver refuses a field it cannot honour rather than ignoring it. Mechanisms that need state the pipeline does not keep take theaggregator_factoryexit. How to fill a slot →
What it measures
Every row names the setting that produced it; the results page also reports the runs where there was nothing left to learn.
| measured | setting | |
|---|---|---|
| An artifact held in one key, where a keyed union can never fuse | keyed union fuses 0 of 48 merges · reflective merge 42 of 48 | BBH dyck_languages, GLM-5.2, N=4, 4 seeds |
| What that costs, at a pinned rollout budget | 40% fewer model calls (95% CI 27–54%, same direction on every seed) | the same runs |
| Wall-clock against a faithful serial control | median 6.8× (three seeds, 3.1–9.5×) | GEPA on HotpotQA, N=4, 16 rollouts pinned |
| The one-call path, end to end | held-out exact match 0.167 → 0.583 | 40 HotpotQA items, 12 held out |
Quality is claimed only where the design can support it: intervals rather than p-values where a comparison cannot reach significance, and it says so.
Documentation
Full docs: thinkflowlab.github.io/agentdescent.
| Start | Install · The plugin, step by step · Quickstart — dataset to skill · Evolve a directory · Evolve agent code |
| Agents | Use it from your agent · Set it up and test it · Agents & LLMs |
| Algorithms | Named algorithms · Register a card · Twenty-three ports · Port fidelity |
| Engine | The evolve() method · Strategies · Policies · Architecture · Concepts · API reference |
| Results | Measured results · Efficiency · Runtime matrix |
Citing, scope and contributing
Use GitHub's Cite this repository button (CITATION.cff);
per-result raw data is in bench/results/.
A research reference implementation, not a production system. The novelty is
a narrow engineering synthesis — concurrent, staleness-bounded,
conflict-resolved diff-level merge over a git-backed versioned ledger — and its
throughput premise is a testable hypothesis rather than community consensus.
Contributions welcome: CONTRIBUTING.md. The suite is offline
and deterministic, so pytest -q needs no API key.