
Strifee/arabic2english
Strifee/arabic2english has 29 GitHub stars and 6 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-15 15:58 UTC. Last push 2026-04-01.
Measured star growth
- in 24h
- 0
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Arabic to English machine translation with Transformers and Pytorch
Machine LearningREADME.md
OriginalArabic2English - Arabic to English Translator
This is a PyTorch implementation of an Arabic to English Neural Machine Translation built using Transformers architecture (Attention Is All You Need)
Why Arabic→English is Hard
Arabic is morphologically rich — one word can express what takes a full sentence in English. It's also right-to-left with complex root-based derivation. Standard seq2seq models struggle with this — Transformers handle it better due to attention mechanisms capturing long-range dependencies.
Model Architecture
- Custom Transformer (Attention Is All You Need)
- 3 encoder + 3 decoder layers
- 8 attention heads
- Embedding size: 256
- Trained from scratch — no pretrained weights
Setup and Requirements
1. CUDA:
install CUDA before installing the required packages or check if it is already installed
2. Clone the Translate repo:
$ git clone https://github.com/Strifee/arabic2english.git
3. install requirements:
pip install -r requirements.txt
if you have problem with CUDA package try this:
conda install -q pytorch torchvision cudatoolkit=11 -c pytorch-nightly
Data
Arabic to English Translation Sentences :
Arabic to English Translation Sentences is a dataset for machine translation between English and Arabic.
Training
1. Clone the Translate repo:
$ git clone clone https://github.com/Strifee/arabic2english.git
2. Training
$ python translate.py
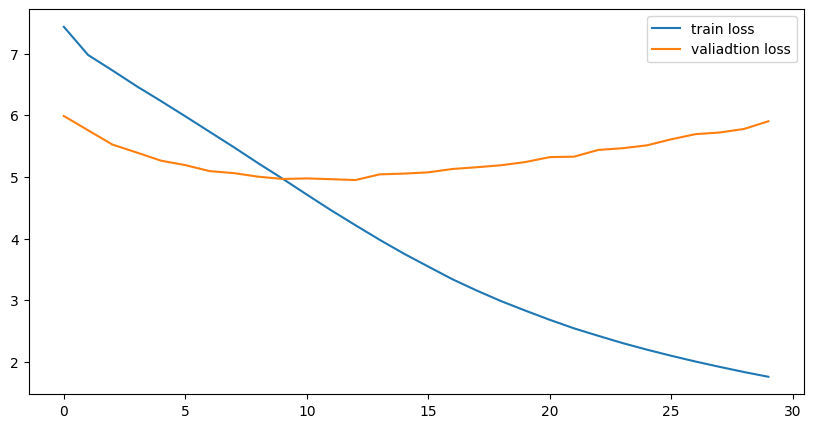
2. Regularization
Hyperparameters :
BATCH_SIZE = 16
learning_rate = 0.0001
num_epochs = 30

num_heads = 8
num_encoder_layers = 3
num_decoder_layers = 3

max_len= 230
dropout = 0.4
embedding_size= 256
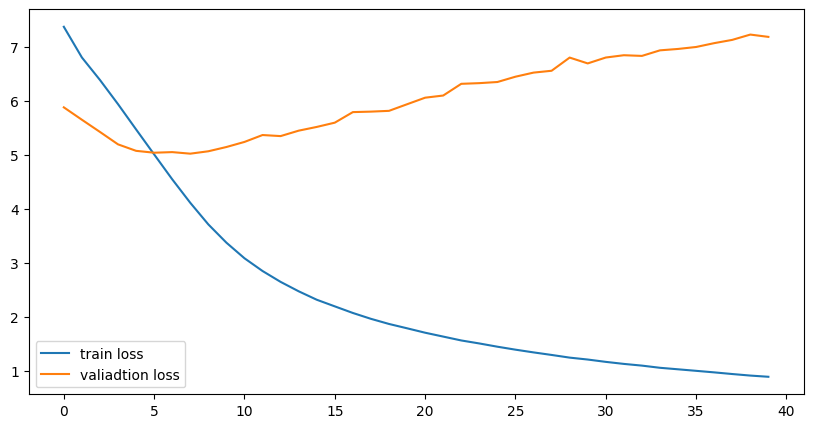
Before regularization :
After regularization :
Results
"I'm ready" -> 'أنا مستعد'
"i'm lucky"  -> 'انا محظوظ'
"I'm sad" -> 'أنا حزين'