
NVlabs/imaginaire
NVlabs/imaginaire has 4,078 GitHub stars and 441 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-06 17:38 UTC. Last push 2022-11-29.
NVIDIA's Deep Imagination Team's PyTorch Library
Measured star growth
- in 24h
- 0
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original
Imaginaire
Docs | License | Installation | Model Zoo
Imaginaire is a pytorch library that contains optimized implementation of several image and video synthesis methods developed at NVIDIA.
License
Imaginaire is released under NVIDIA Software license. For commercial use, please consult NVIDIA Research Inquiries.
What's inside?
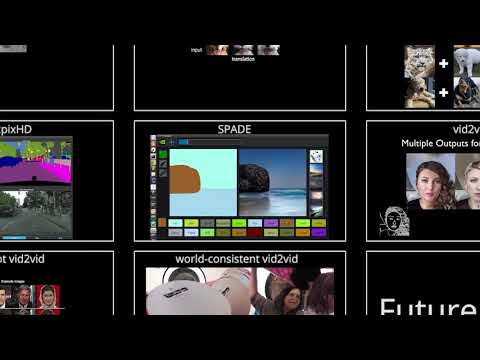
We have a tutorial for each model. Click on the model name, and your browser should take you to the tutorial page for the project.
Supervised Image-to-Image Translation
| Algorithm Name | Feature | Publication |
|---|---|---|
| pix2pixHD | Learn a mapping that converts a semantic image to a high-resolution photorealistic image. | Wang et. al. CVPR 2018 |
| SPADE | Improve pix2pixHD on handling diverse input labels and delivering better output quality. | Park et. al. CVPR 2019 |
Unsupervised Image-to-Image Translation
| Algorithm Name | Feature | Publication |
|---|---|---|
| UNIT | Learn a one-to-one mapping between two visual domains. | Liu et. al. NeurIPS 2017 |
| MUNIT | Learn a many-to-many mapping between two visual domains. | Huang et. al. ECCV 2018 |
| FUNIT | Learn a style-guided image translation model that can generate translations in unseen domains. | Liu et. al. ICCV 2019 |
| COCO-FUNIT | Improve FUNIT with a content-conditioned style encoding scheme for style code computation. | Saito et. al. ECCV 2020 |
Video-to-video Translation
| Algorithm Name | Feature | Publication |
|---|---|---|
| vid2vid | Learn a mapping that converts a semantic video to a photorealistic video. | Wang et. al. NeurIPS 2018 |
| fs-vid2vid | Learn a subject-agnostic mapping that converts a semantic video and an example image to a photoreslitic video. | Wang et. al. NeurIPS 2019 |
World-to-world Translation
| Algorithm Name | Feature | Publication |
|---|---|---|
| wc-vid2vid | Improve vid2vid on view consistency and long-term consistency. | Mallya et. al. ECCV 2020 |
| GANcraft | Convert semantic block worlds to realistic-looking worlds. | Hao et. al. ICCV 2021 |
Explore related projects
tensorflow/tensorflow
An Open Source Machine Learning Framework for Everyone
201,367 starshuggingface/transformers
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
168,609 starsAUTOMATIC1111/stable-diffusion-webui
Stable Diffusion web UI
165,245 starsComfy-Org/ComfyUI
The most powerful and modular diffusion model GUI, api and backend with a graph/nodes interface. The fastest local inference engine in the world.
145,470 stars