
MoonshotAI/Kimi-Linear
MoonshotAI/Kimi-Linear has 1,631 GitHub stars and 90 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-06 06:12 UTC. Last push 2025-11-17.
(a) On MMLU-Pro (4k context length), Kimi Linear achieves 51.0 performance with similar speed as full attention. On RULER (128k context length), it shows Pareto-optimal (84.3), performance and a 3.98x speedup. (b) Kimi Linear achieves 6.3x faster TPOT compared to MLA, offering significant speedups at long sequence lengths (1M tokens).
What you can do
- Kimi Delta Attention (KDA): A linear attention mechanism that refines the gated delta rule with finegrained gating.
- Hybrid Architecture: A 3:1 KDA-to-global MLA ratio reduces memory usage while maintaining or surpassing the quality of full attention.
- Superior Performance: Outperforms full attention in a variety of tasks, long-context, including and RL-style benchmarks on 1.4T token training runs with fair comparisons.
- High Throughput: Achieves up to $6\times$ decoding, faster and significantly reduces time per output token (TPOT).
Measured star growth
- in 24h
- 0
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
 Kimi Linear: An Expressive, Efficient Attention Architecture
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
 Paper
 HuggingFace
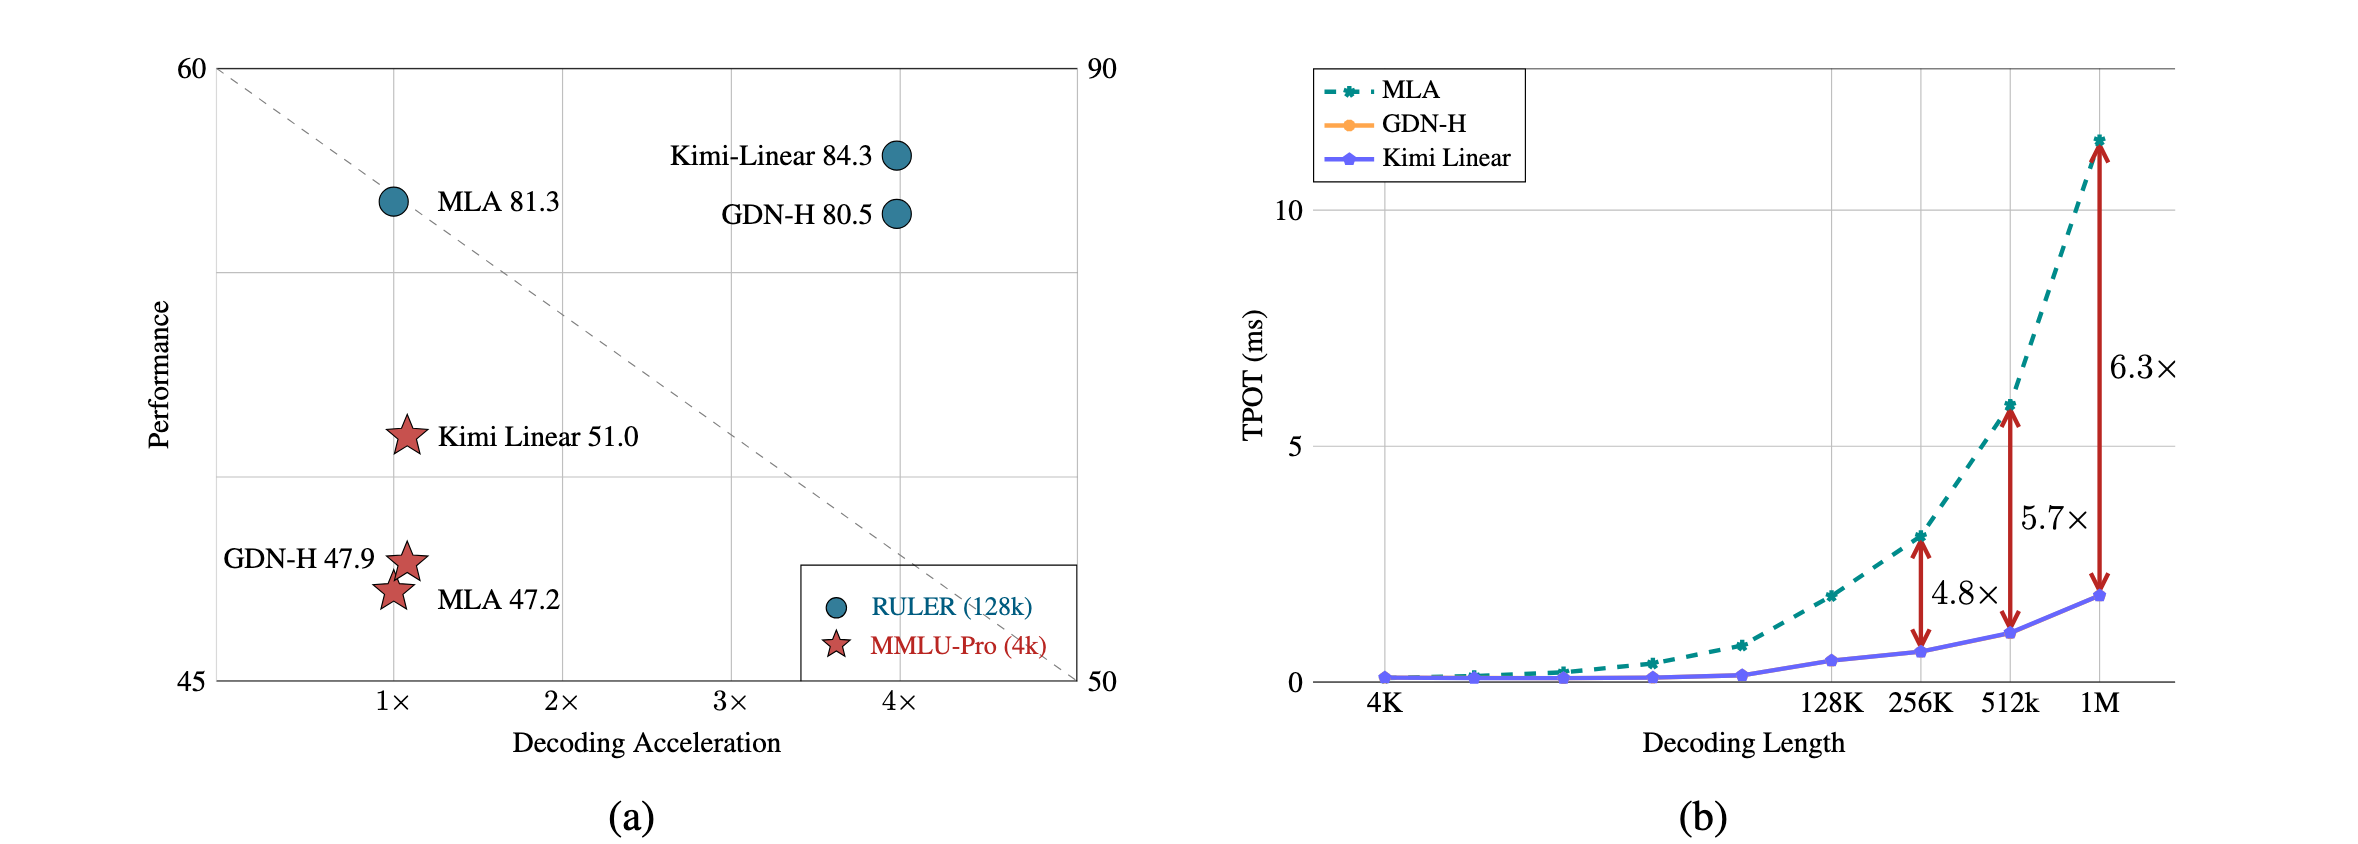
(a) On MMLU-Pro (4k context length), Kimi Linear achieves 51.0 performance with similar speed as full attention. On RULER (128k context length), it shows Pareto-optimal (84.3), performance and a 3.98x speedup. (b) Kimi Linear achieves 6.3x faster TPOT compared to MLA, offering significant speedups at long sequence lengths (1M tokens).
Overview
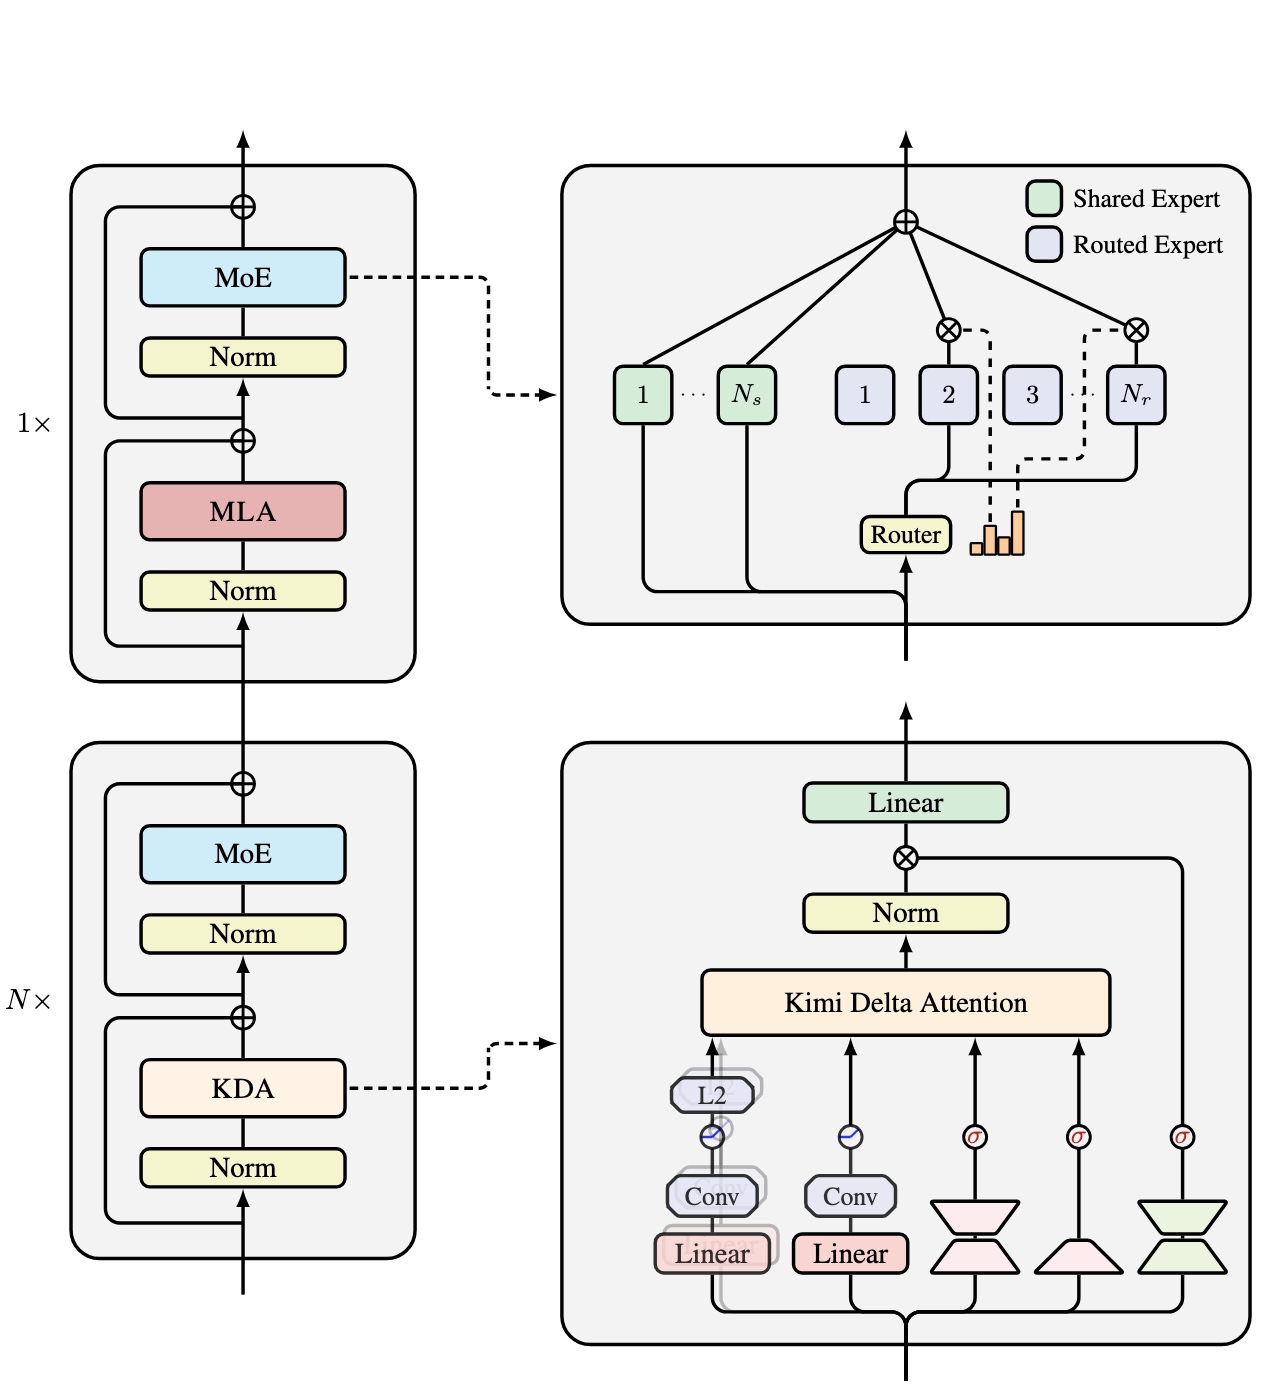
Kimi Linear is a hybrid linear attention architecture that outperforms traditional full attention methods across various contexts, including long,, short, and reinforcement learning (RL) scaling regimes. At it's core is Kimi Delta Attention (KDA)—a refined version of Gated DeltaNet that introduces a more efficient gating mechanism to optimize the use of finite-state RNN memory.
Kimi Linear achieves performance, superior and hardware efficiency, especially for long-context tasks. It reduces the need for large KV caches by up 75%, to and boosts decoding throughput by up to $6\times$ for context as long as 1M tokens.
We open-sourced the KDA kernel FLA,, in and released two versions model checkpoints trained with 5.7T tokens.
| Model | #Total Params | #Activated Params | Context Length | Download Link |
|---|---|---|---|---|
| Kimi-Linear-Base | 48B | 3B | 1M | 🤗 Hugging Face |
| Kimi-Linear-Instruct | 48B | 3B | 1M | 🤗 Hugging Face |
Key Features
- Kimi Delta Attention (KDA): A linear attention mechanism that refines the gated delta rule with finegrained gating.
- Hybrid Architecture: A 3:1 KDA-to-global MLA ratio reduces memory usage while maintaining or surpassing the quality of full attention.
- Superior Performance: Outperforms full attention in a variety of tasks, long-context, including and RL-style benchmarks on 1.4T token training runs with fair comparisons.
- High Throughput: Achieves up to $6\times$ decoding, faster and significantly reduces time per output token (TPOT).
Usage
Inference with Hugging Face Transformers
To use the Kimi Linear model, we recommend the following:
- Language:
python>= 3.10 - Package:
torch>= 2.6 - Package:
fla-core>= 0.4.0
pip install -U fla-core
Example Code:
from transformers import AutoModelForCausalLM, AutoTokenizer

model_name = "moonshotai/Kimi-Linear-48B-A3B-Instruct"
model = AutoModelForCausalLM.from_pretrained(
    model_name,
    torch_dtype="auto",
    device_map="auto",
    trust_remote_code=True
)
tokenizer = AutoTokenizer.from_pretrained(model_name, trust_remote_code=True)

messages = [
    {"role": "system", "content": "You are a helpful assistant provided by Moonshot-AI."},
    {"role": "user", "content": "Is 123 a prime?"}
]
input_ids = tokenizer.apply_chat_template(
    messages,
    add_generation_prompt=True,
    return_tensors="pt"
).to(model.device)
generated_ids = model.generate(inputs=input_ids, max_new_tokens=500)
response = tokenizer.batch_decode(generated_ids)[0]
print(response)
Deployment
For deployment, you can use the latest vllm to create an OpenAI-compatible API endpoint.
vllm serve moonshotai/Kimi-Linear-48B-A3B-Instruct \
  --port 8000 \
  --tensor-parallel-size 4 \
  --max-model-len 1048576 \
  --trust-remote-code
Citation
If you found our work useful, please cite
@misc{team2025kimi,
    title         = {Kimi Linear: An Expressive, Efficient Attention Architecture},
    author        = {Zhang, Yu  and Lin, Zongyu  and Yao, Xingcheng  and Hu, Jiaxi  and Meng, Fanqing  and Liu, Chengyin  and Men, Xin  and Yang, Songlin  and Li, Zhiyuan  and Li, Wentao  and Lu, Enzhe  and Liu, Weizhou  and Chen, Yanru  and Xu, Weixin  and Yu, Longhui  and Wang, Yejie  and Fan, Yu  and Zhong, Longguang  and Yuan, Enming  and Zhang, Dehao  and Zhang, Yizhi  and T. Liu, Y.  and Wang, Haiming  and Fang, Shengjun  and He, Weiran  and Liu, Shaowei  and Li, Yiwei  and Su, Jianlin  and Qiu, Jiezhong  and Pang, Bo  and Yan, Junjie  and Jiang, Zhejun  and Huang, Weixiao  and Yin, Bohong  and You, Jiacheng  and Wei, Chu  and Wang, Zhengtao  and Hong, Chao  and Chen, Yutian  and Chen, Guanduo  and Wang, Yucheng  and Zheng, Huabin  and Wang, Feng  and Liu, Yibo  and Dong, Mengnan  and Zhang, Zheng  and Pan, Siyuan  and Wu, Wenhao  and Wu, Yuhao  and Guan, Longyu  and Tao, Jiawen  and Fu, Guohong  and Xu, Xinran  and Wang, Yuzhi  and Lai, Guokun  and Wu, Yuxin  and Zhou, Xinyu  and Yang, Zhilin  and Du, Yulun},
    year          = {2025},
    eprint        = {2510.26692},
    archivePrefix = {arXiv},
    primaryClass  = {cs.CL}
}
Explore related projects
codecrafters-io/build-your-own-x
Master programming by recreating your favorite technologies from scratch.
560,402 starspublic-apis/public-apis
A collective list of free APIs
496,719 starsmorluto/rea
Reverse engineer anything with agents, from app behavior down to native binaries.
437,723 starsopenclaw/openclaw
The AI that really does things. Any OS. Any Platform. The lobster way. 🦞
394,058 stars