
Megvii-BaseDetection/DeFCN has 494 GitHub stars and 34 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-09 10:49 UTC. Last push 2022-01-10.
End-to-End Object Detection with Fully Convolutional Network
Measured star growth
- in 24h
- 0
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalEnd-to-End Object Detection with Fully Convolutional Network

This project provides an implementation for "End-to-End Object Detection with Fully Convolutional Network" on PyTorch.
Experiments in the paper were conducted on the internal framework, thus we reimplement them on cvpods and report details as below.
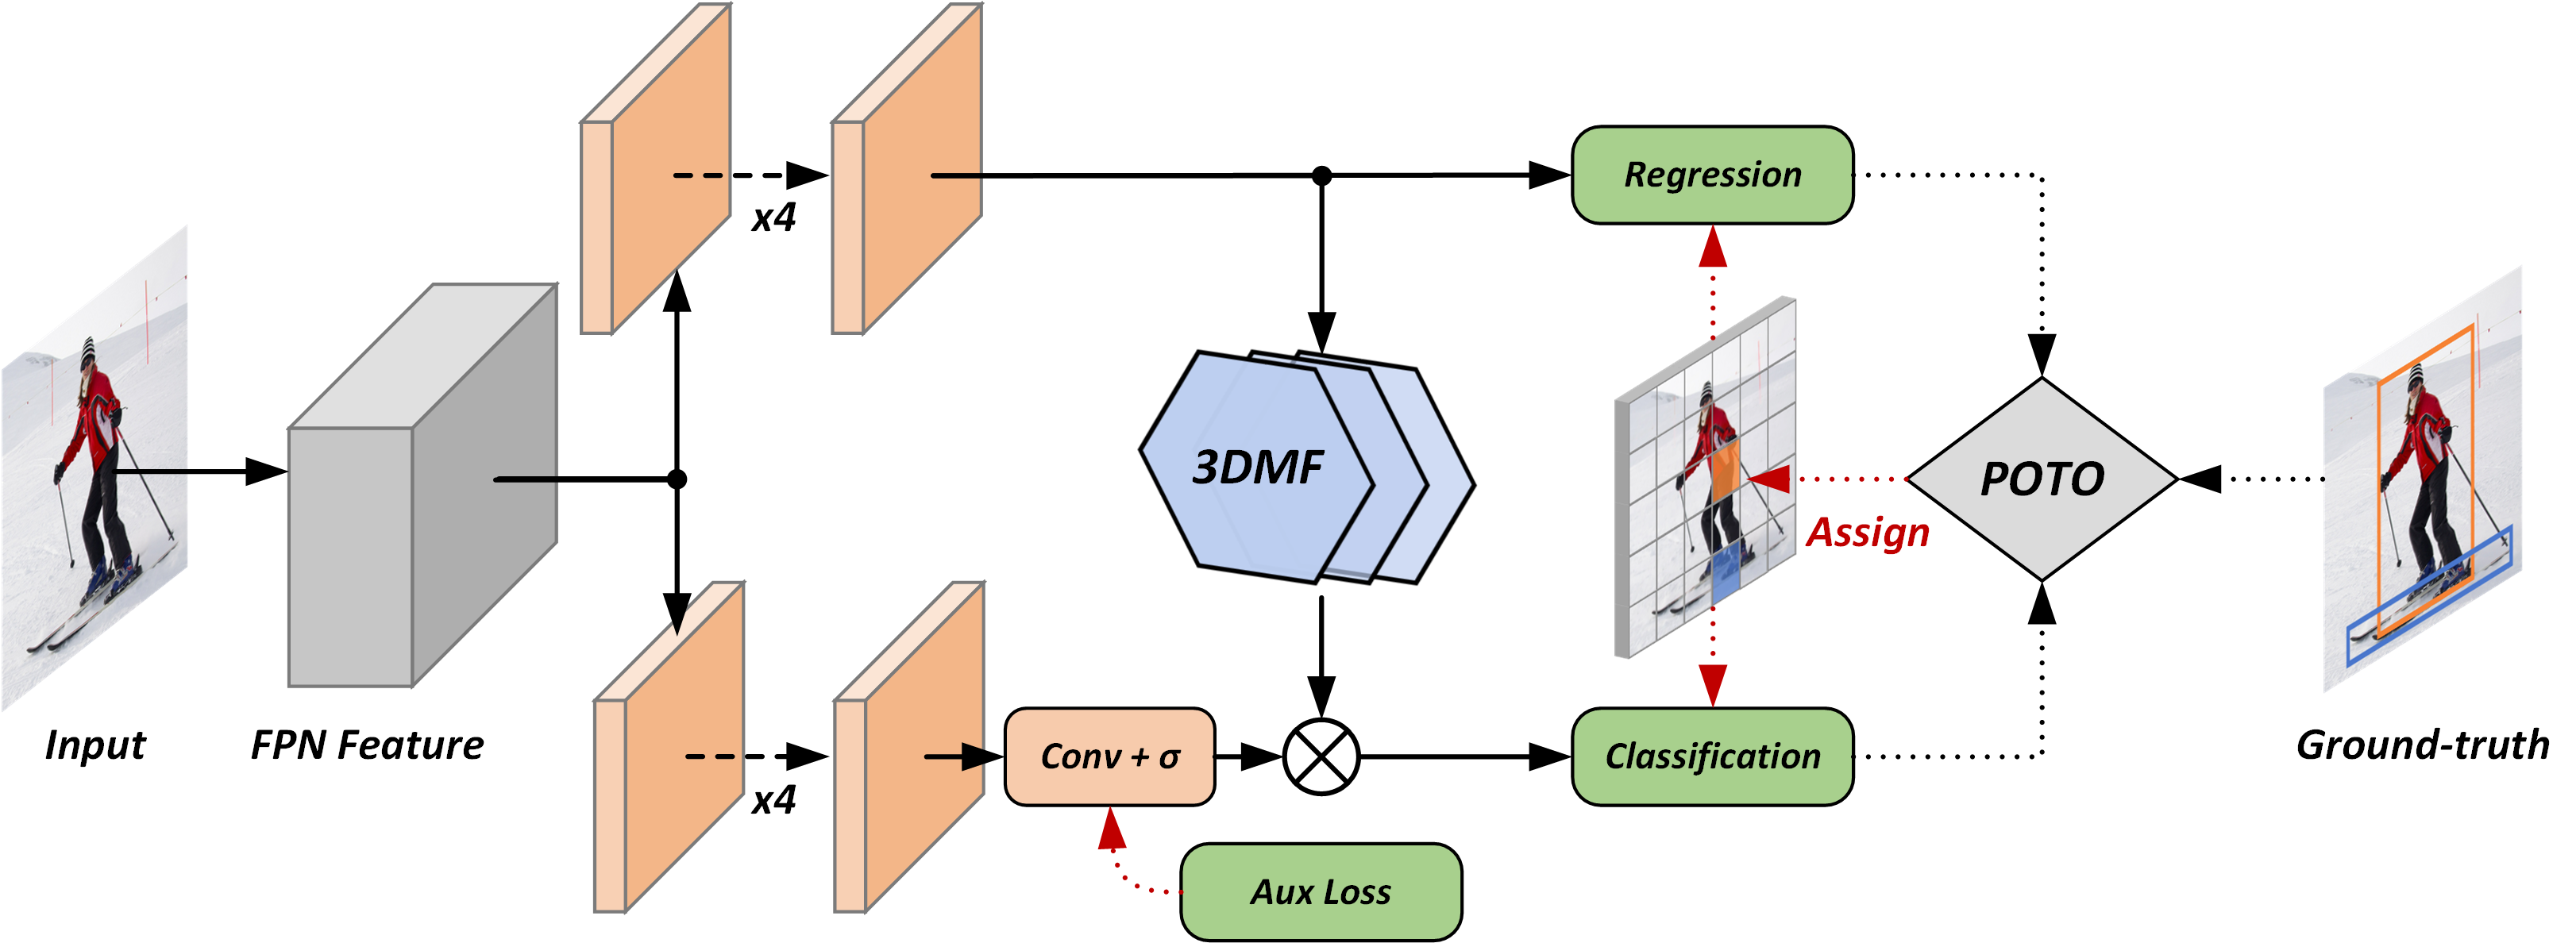
Requirements
- cvpods
- scipy >= 1.5.4
Get Started
- install cvpods locally (requires cuda to compile)
python3 -m pip install 'git+https://github.com/Megvii-BaseDetection/cvpods.git'
# (add --user if you don't have permission)

# Or, to install it from a local clone:
git clone https://github.com/Megvii-BaseDetection/cvpods.git
python3 -m pip install -e cvpods

# Or,
pip install -r requirements.txt
python3 setup.py build develop
- prepare datasets
cd /path/to/cvpods
cd datasets
ln -s /path/to/your/coco/dataset coco
- Train & Test
git clone https://github.com/Megvii-BaseDetection/DeFCN.git
cd DeFCN/playground/detection/coco/poto.res50.fpn.coco.800size.3x_ms  # for example

# Train
pods_train --num-gpus 8

# Test
pods_test --num-gpus 8 \
    MODEL.WEIGHTS /path/to/your/save_dir/ckpt.pth # optional
    OUTPUT_DIR /path/to/your/save_dir # optional

# Multi node training
## sudo apt install net-tools ifconfig
pods_train --num-gpus 8 --num-machines N --machine-rank 0/1/.../N-1 --dist-url "tcp://MASTER_IP:port"
Results on COCO2017 val set
| model | assignment | with NMS | lr sched. | mAP | mAR | download |
|---|---|---|---|---|---|---|
| FCOS | one-to-many | Yes | 3x + ms | 41.4 | 59.1 | weight | log |
| FCOS baseline | one-to-many | Yes | 3x + ms | 40.9 | 58.4 | weight | log |
| Anchor | one-to-one | No | 3x + ms | 37.1 | 60.5 | weight | log |
| Center | one-to-one | No | 3x + ms | 35.2 | 61.0 | weight | log |
| Foreground Loss | one-to-one | No | 3x + ms | 38.7 | 62.2 | weight | log |
| POTO | one-to-one | No | 3x + ms | 39.2 | 61.7 | weight | log |
| POTO + 3DMF | one-to-one | No | 3x + ms | 40.6 | 61.6 | weight | log |
| POTO + 3DMF + Aux | mixture* | No | 3x + ms | 41.4 | 61.5 | weight | log |
* We adopt a one-to-one assignment in POTO and a one-to-many assignment in the auxiliary loss, respectively.
2x + msschedule is adopted in the paper, but we adopt3x + msschedule here to achieve higher performance.- It's normal to observe ~0.3AP noise in POTO.
Results on CrowdHuman val set
| model | assignment | with NMS | lr sched. | AP50 | mMR | recall | download |
|---|---|---|---|---|---|---|---|
| FCOS | one-to-many | Yes | 30k iters | 86.1 | 54.9 | 94.2 | weight | log |
| ATSS | one-to-many | Yes | 30k iters | 87.2 | 49.7 | 94.0 | weight | log |
| POTO | one-to-one | No | 30k iters | 88.5 | 52.2 | 96.3 | weight | log |
| POTO + 3DMF | one-to-one | No | 30k iters | 88.8 | 51.0 | 96.6 | weight | log |
| POTO + 3DMF + Aux | mixture* | No | 30k iters | 89.1 | 48.9 | 96.5 | weight | log |
* We adopt a one-to-one assignment in POTO and a one-to-many assignment in the auxiliary loss, respectively.
- It's normal to observe ~0.3AP noise in POTO, and ~1.0mMR noise in all methods.
Ablations on COCO2017 val set
| model | assignment | with NMS | lr sched. | mAP | mAR | note |
|---|---|---|---|---|---|---|
| POTO | one-to-one | No | 6x + ms | 40.0 | 61.9 | |
| POTO | one-to-one | No | 9x + ms | 40.2 | 62.3 | |
| POTO | one-to-one | No | 3x + ms | 39.2 | 61.1 | replace Hungarian algorithm by argmax |
| POTO + 3DMF | one-to-one | No | 3x + ms | 40.9 | 62.0 | remove GN in 3DMF |
| POTO + 3DMF + Aux | mixture* | No | 3x + ms | 41.5 | 61.5 | remove GN in 3DMF |
* We adopt a one-to-one assignment in POTO and a one-to-many assignment in the auxiliary loss, respectively.
- For
one-to-oneassignment, more training iters lead to higher performance. - The
argmax(also known as top-1) operation is indeed the approximate solution of bipartite matching in dense prediction methods. - It seems harmless to remove GN in 3DMF, which also leads to higher inference speed.
Acknowledgement
This repo is developed based on cvpods. Please check cvpods for more details and features.
License
This repo is released under the Apache 2.0 license. Please see the LICENSE file for more information.
Citing
If you use this work in your research or wish to refer to the baseline results published here, please use the following BibTeX entries:
@article{wang2020end,
  title   =  {End-to-End Object Detection with Fully Convolutional Network},
  author  =  {Wang, Jianfeng and Song, Lin and Li, Zeming and Sun, Hongbin and Sun, Jian and Zheng, Nanning},
  journal =  {arXiv preprint arXiv:2012.03544},
  year    =  {2020}
}
Contributing to the project
Any pull requests or issues about the implementation are welcome. If you have any issue about the library (e.g. installation, environments), please refer to cvpods.
Explore related projects
codecrafters-io/build-your-own-x
Master programming by recreating your favorite technologies from scratch.
561,375 starspublic-apis/public-apis
A collective list of free APIs
497,650 starsmorluto/rea
Reverse engineer anything with agents, from app behavior down to native binaries.
447,211 starsopenclaw/openclaw
The AI that really does things. Any OS. Any Platform. The lobster way. 🦞
394,260 stars