
Jaasssoooonnnnn/FirstLight-Zero
Jaasssoooonnnnn/FirstLight-Zero has 18 GitHub stars and 2 forks. GitHot measured +2 stars in 24 hours. Last checked 2026-11-12 11:28 UTC. Last push 2026-11-04.
AlphaZero-style self-play Clash Royale. It beats a human-data imitation model
Measured star growth
- in 24h
- +2
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original
FirstLight Zero
A small Clash Royale model that learned the 3.0 X-Bow mirror from self-play alone, with no human data.
English · 简体中文

Training history · Training metrics · Getting started · Architecture · Evaluation · Model
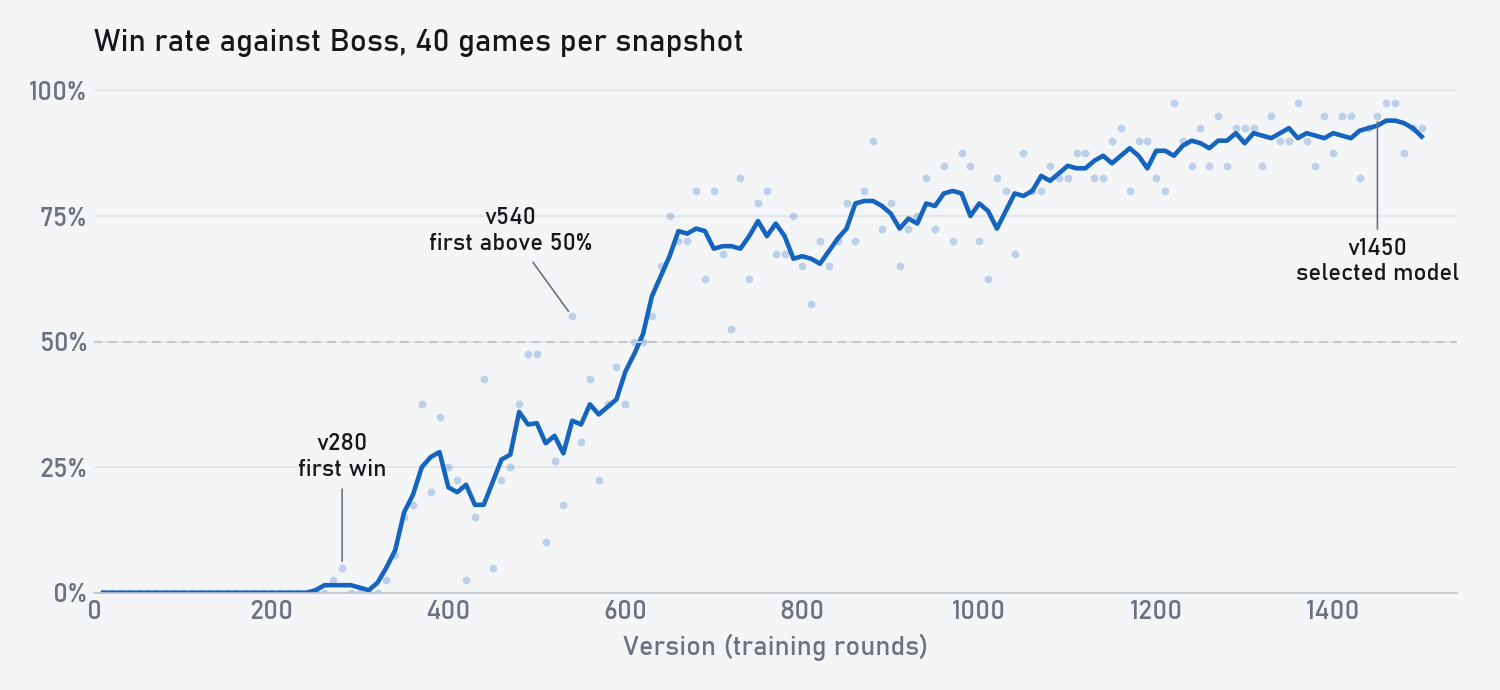
Every strong Clash Royale AI I know of starts from human replays. I wanted to see whether a model could get there without them, so this one started from random weights and only ever played against itself and its older versions. Nobody told it what the deck does.
After 1,450 training rounds, the 1.17M-parameter model beats a 16.8M-parameter imitation model that was trained on 193,530 top ladder games.
Results
40 games, in the X-Bow mirror at level 11. checkpoints/ holds every 50th version from v50 to v1500; v1450 is the one to use.
| Opponent | Size | Trained on | Our version | Win rate |
|---|---|---|---|---|
| IL Model Everlight | 16.8M | 193,530 human games | v1460 | 97.5% |
It was never part of training. The training history has the whole curve and how the model's play changed version by version.
What's here
| Path | Contents |
|---|---|
firstlight_zero/ |
Training and evaluation: features, model, collectors, inference servers, PPO learner, sweeps and round robins |
native_runner/ |
The battle environment layer, trimmed from FirstLight CR, with the probe source in native_runner/probe/ |
tools/ |
Evaluation servers, tactics analysis, replay export and replay checks |
checkpoints/ |
Every 50th version, firstlight-zero-v50.pt to firstlight-zero-v1500.pt |
docs/ |
The guides linked above |
Quick start
You need Python 3.12, a GPU for training, and native battle engines for version 15.535.13. This repository doesn't include the game client. FirstLight CR has the full stack for building an engine from a client you supply: probe, APK tools, environment and a training guide. Getting started lists exactly what this code expects.
pip install -r requirements.txt
python tests/test_consistency.py      # needs no engine

cp engines.example.json engines.json  # one entry per engine process
python firstlight_zero/launch.py prepare --run runs/first
python firstlight_zero/launch.py start --run runs/first > runs/first/supervisor.log 2>&1 &
python tools/status.py runs/first
To train with different settings, pass --set to prepare. To evaluate the included model, see Use the pretrained model.
Acknowledgements
Thanks to daybreak-cr. Its asynchronous training framework inspired the one here, which made my PPO training throughput 1.5 times faster than before.
License
FirstLight Zero is an independent offline project under Apache-2.0, unaffiliated with Supercell. It doesn't distribute the game or its resources and doesn't connect to official servers. See NOTICE.
Explore related projects
tensorflow/tensorflow
An Open Source Machine Learning Framework for Everyone
201,584 starshuggingface/transformers
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
168,917 starsAUTOMATIC1111/stable-diffusion-webui
Stable Diffusion web UI
165,300 starsComfy-Org/ComfyUI
The most powerful and modular diffusion model GUI, api and backend with a graph/nodes interface. The fastest local inference engine in the world.
146,472 stars