
ImIntheMiddle/VATL4Pose-WACV2024
ImIntheMiddle/VATL4Pose-WACV2024 has 44 GitHub stars and 2 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-09 09:11 UTC. Last push 2026-10-15.
[WACV2024] Official PyTorch implimentation for ``Active Transfer Learning for Efficient Video-Specific Human Pose Estimation''
Measured star growth
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalVATL4Pose




Official implementation of Active Transfer Learning for Efficient Video-Specific Human Pose Estimation (WACV 2024).

PoseTrack21 video 018903. Left: the pretrained estimator. Right: the estimator adapted to this video with labels for about 9 % of its people.
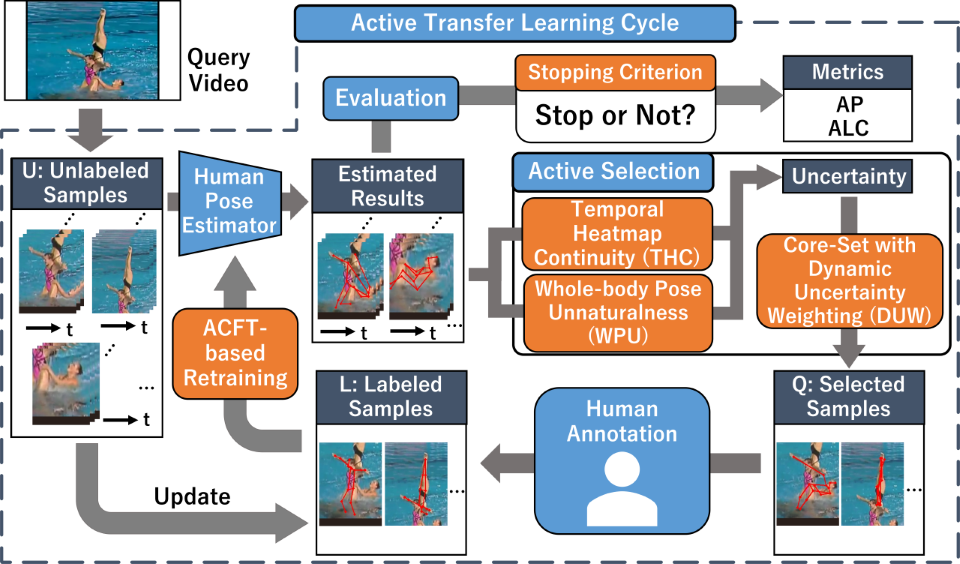
VATL4Pose adapts a pretrained pose estimator to one video. Each round selects the people to annotate with THC, WPU and DUW, and retrains the estimator on the new labels. The code of the paper is at the tag wacv2024.
Installation
git clone https://github.com/ImIntheMiddle/VATL4Pose-WACV2024.git
cd VATL4Pose-WACV2024
uv sync --extra cu124        # cu128 for CUDA 12.8 or newer, cpu without a GPU
source .venv/bin/activate
vatl4pose-download-weights --weights-root pretrained_models
vatl4pose-doctor paths.weights_root=pretrained_models
Reproducing the paper
Download PoseTrack21 and JRDB-Pose into data/.
data/PoseTrack21/posetrack_data/{train,val}/
data/PoseTrack21/images/{train,val}/
data/jrdb-pose/jrdb2022/labels/
data/jrdb-pose/images/image_stitched/
for e in wacv2024_posetrack21 wacv2024_jrdb; do
  vatl4pose-prepare-annotations experiment=$e
  vatl4pose-prepare experiment=$e
  for s in random hp mpe tpc kmeans coreset thc_wpu_duw; do
    vatl4pose-atl experiment=$e strategy=$s run.device=cuda
  done
  vatl4pose-summarize experiment=$e
done
outputs/<experiment>/summary/ holds the ALC of [email protected] of each strategy (Tables 2 and 4 of the paper). docs/guide.md lists the runs of the ablation (Table 3) and of the stopping criteria (Table 5).
Annotating a video in the browser
vatl4pose annotate runs the loop on a video of your own in one browser page. SAMIDARE (CVsports 2026), a tracking-by-segmentation method for crowded scenes, detects and tracks the people. The page then shows the people to annotate with their predicted keypoints. Correct the points and press Train: the estimator retrains on the new labels, and the page shows its keypoints for everyone, so you can annotate another round or finish.
bash annotation/setup.sh       # once: the tool's environment, SAMIDARE, SAM 2 and their checkpoints
annotation/.venv/bin/vatl4pose annotate my_video.mp4 --target-oks 0.8
Open the address that the command prints, http://localhost:8765 by default. On a remote server, forward the same port number (ssh -L 8765:localhost:8765 user@server). --target-oks θ shows the stopping criterion of the paper after every round. The estimator retrains on the GPU; --learning-device cpu frees the GPU after tracking, and a round then takes minutes instead of seconds. The estimator of the last round is atl/tracked/simplebaseline/THC+WPU_Coresetfilter/clip/estimator.pth in the session directory. annotation/README.md describes the options and the outputs.

The editor shows the predicted joints of a selected person, and the video beside it plays the track of that person. Frame from “Appalchian dancers at Rydale Folk Festival” by Wulyum, CC BY-SA 4.0; the screenshot is under the same license.
Your own videos
Put the frames and a COCO keypoints file with track ids in data/mine/. The boxes and track ids come from your detector and tracker.
data/mine/images/clip1/000001.jpg
data/mine/annotations/clip1.json
vatl4pose-prepare dataset=coco_custom dataset.root=mine 'dataset.ids=[clip1]' dataset.keypoints=posetrack21
vatl4pose-atl dataset=coco_custom dataset.root=mine 'dataset.ids=[clip1]' dataset.keypoints=posetrack21 \
  estimator=simplebaseline estimator.weights=posetrack21/simplebaseline_256x192.pth \
  ae.checkpoint=wholebodyAE/Posetrack21/Hybrid/WholeBodyAE_zdim4_v1.pth \
  oracle=coco_file run.name=mine run.device=cuda 'loop.query_ratio=[0.05,0.1,0.2]' loop.save_final_model=true
Each round writes oracle/round_XX_queries.json with the people to annotate and stops. Correct their keypoints in CVAT or Label Studio, keep the annotation ids, save the result as round_XX_answers.json in the same directory and run the command again. After the last round, final_estimator.pth holds the adapted estimator and predictions.json the poses of every person under it.
docs/guide.md lists the commands and settings and covers the annotation format, the output files, other keypoint specs, training, tuning and the pictures of each round.
Citation
@InProceedings{VATL4Pose_WACV24,
  author       = {Taketsugu, Hiromu and Ukita, Norimichi},
  title        = {Active Transfer Learning for Efficient Video-Specific Human Pose Estimation},
  booktitle    = {IEEE/CVF Winter Conference on Applications of Computer Vision (WACV)},
  year         = {2024}}

@InProceedings{VATL4Pose_MVA23,
  author       = {Taketsugu, Hiromu and Ukita, Norimichi},
  title        = {Uncertainty Criteria in Active Transfer Learning for Efficient Video-Specific Human Pose Estimation},
  booktitle    = {2023 18th International Conference on Machine Vision and Applications (MVA)},
  year         = {2023}}
License
The source is under the MIT License, and third_party/hrnet/ keeps its own MIT license. The weights are trained on PoseTrack21 and JRDB-Pose and are for noncommercial research only, under the terms of these datasets. The annotation tool downloads SAMIDARE (MIT License), SAM 2 (Apache License 2.0) and Label Studio (Apache License 2.0) from their sources and contains none of them. The repository history and the tag wacv2024 contain third-party code under its own licenses.
Explore related projects
tensorflow/tensorflow
An Open Source Machine Learning Framework for Everyone
201,427 starshuggingface/transformers
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
168,711 starsAUTOMATIC1111/stable-diffusion-webui
Stable Diffusion web UI
165,274 starsComfy-Org/ComfyUI
The most powerful and modular diffusion model GUI, api and backend with a graph/nodes interface. The fastest local inference engine in the world.
146,024 stars