
Human-Agent-Society/reef has 7,803 GitHub stars and 730 forks. GitHot measured +2 stars in 24 hours. Last checked 2026-11-06 11:08 UTC. Last push 2026-11-02.
Infrastructure for continually self‑improving agents
Measured star growth
- in 24h
- +2
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original
Infrastructure for continually self‑improving agents


English | 中文
Reef is the first open-source infrastructure for continual self-improving agents. It connects agent inference, feedback, learning, and versioned delivery. Use it to train model weights with Slime and SGLang, or improve an agent's harness, including its prompts, rules, and skills.
🚀 Get started | 🗺️ Roadmap | 🗓️ Office Hours | 📣 Launch post | 💬 Join Discord | 📱 Join WeChat Group
🎯 When to use Reef
Use Reef when you want your agent to keep improving simply by learning from how you interact with your agent.
| Your goal | Learning path | What you need |
|---|---|---|
| Keep getting stronger model designed for you | Model weight training | A trainable model, a supported GPU stack, and feedback your recipe can use |
| Get your harness to self-improve | Harness optimization | A model endpoint, representative tasks, and an evaluator; no local training GPUs |
| Scientific discoveries | Test-time training | An execution environment, a correctness checker, and a measurable objective |
🧩 How Reef fits your stack
| Ability | Inference engine (vLLM, SGLang, …) | RL training framework (Slime, veRL, AReaL, …) | Reef |
|---|---|---|---|
| Serves live traffic | ✅ | ❌ | ✅ |
| Trains weights | ❌ | ✅ | ✅ |
| Version management | ❌ | ❌ | ✅ |
| Stays live through updates | ❌ | ❌ | ✅ |
| Evolves beyond weights (skills, harness) | ❌ | ❌ | ✅ |
🔄 How it works
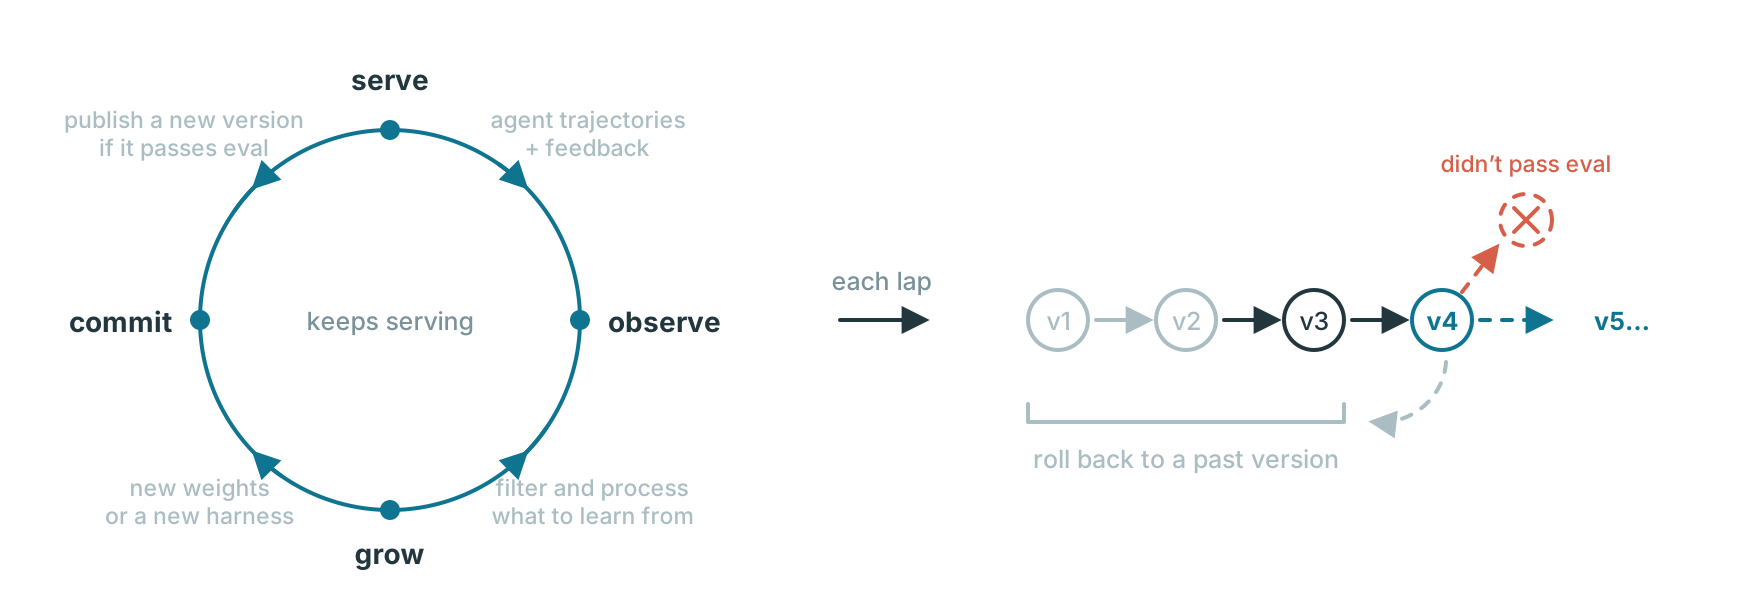
Reef processes each learning cycle in four steps. The table also shows which modules implement each step.
| Step | What happens | Where it lives |
|---|---|---|
| 1 · Serve | Serve agent requests and record interactions. | service/ — agent requests and interaction recordsinference/ — inference and artifact updates |
| 2 · Observe | Match feedback to recorded interactions. | storage/records.py — stored interactions and feedbackrecord2sample/ — feedback matching, eligibility, and samples |
| 3 · Grow | Produce an update from eligible records. | recipe/ — recipe integrationtrain/ — the training pipeline, job data, and training jobs |
| 4 · Commit | Apply the configured selection policy and publish accepted updates. | evaluation/ — candidate evaluationartifact/ — version history and release components |
📦 Installation
💡 Note
Reef's artifact and checkpoint functionality requires the
git-lfssystem package. Reef initializes Git LFS locally for its artifact repositories.
We recommend uv for managing packages, and the commands below use it.
From PyPI
uv venv && source .venv/bin/activate
uv pip install reef-infra
python3 -c "import reef; print(reef.__version__)"
From source
git lfs install
git clone https://github.com/Human-Agent-Society/reef.git
cd reef
uv venv && source .venv/bin/activate
uv pip install -e .
python3 -c "import reef; print(reef.__version__)"
Use the source checkout for development and for the training examples below.
🔧 Using Reef
Reef supports two learning surfaces: model weights and agent harnesses. The deployment's recipe determines which surface its scenarios update.
As a minimal example, start Reef as a pure inference server:
uv run reef serve --inference.model-path Qwen/Qwen2.5-1.5B-Instruct
Weight-training deployment
Start the deployment
The following example starts the SAO (arXiv:2607.07508) example deployment. Run it from a Reef checkout in an environment that satisfies the GPU requirements in Evolve your model.
uv pip install -e ".[slime]" && uv pip install --no-deps --group runtime

export MODEL_PATH="Qwen/Qwen2.5-1.5B-Instruct"
export REEF_TOKEN="reef-local"

reef serve -c recipes/sao/examples/imo_answerbench/serve.yaml \
  --inference.model-path "$MODEL_PATH" \
  --reef.port "8900"

curl -f http://127.0.0.1:8900/healthz          # ready to serve
Send an inference request and report feedback
Send inference requests through Reef and report a score for each response. The SAO recipe uses each eligible scored rollout to run a training step.
Reef's inference endpoint is OpenAI- and Anthropic-compatible: /v1/chat/completions,
/v1/responses and /v1/messages take the provider's own request body. A request includes the
x-reef-scenario header; a new name creates a scenario using the deployment's
configured recipe. Requests do not select recipes.
The response body uses the provider's OpenAI-compatible format. Reef adds the
x-reef-agent-record-id response header. Its value is the receipt that a
later report uses to identify this interaction. A report can contain a numeric
score, textual or structured feedback, and the receipts it evaluates. This
example reports both a score and a short explanation.
import os
import httpx

reef = httpx.Client(
    base_url="http://127.0.0.1:8900",
    headers={"Authorization": f"Bearer {os.environ['REEF_TOKEN']}", "x-reef-scenario": "hello-reef"},
    timeout=300,
)

# Send a provider-compatible inference request
response = reef.post(
    "/v1/chat/completions",
    json={
        "model": os.environ["MODEL_PATH"],
        "messages": [{"role": "user", "content": "Return exactly: reef is ready"}],
    },
)

response.raise_for_status()
receipt = response.headers["x-reef-agent-record-id"]
answer = response.json()["choices"][0]["message"]["content"]

# Sending report about the inference
matched = answer.strip() == "reef is ready"

reef.post(
    "/reef/report",
    json={"score": float(matched), "feedback": "matched" if matched else "wrong answer", "references": [receipt]},
).raise_for_status()
feedback carries the richer signal, plain text or a structured object,
for recipes that read more than a scalar. The endpoint will validate the
report schema (reef/core/reports/).
Watch it learn and grow
Once the recipe has enough feedback, Reef submits a training job to the training component. When a checkpoint that the job saved passes evaluation, the inference runtime loads it as the new snapshot. Later inference requests use the current version without restarting Reef.
Harness-evolving deployment
Evolve a coding agent's skills and rules from scored feedback, using a model API instead of GPUs.
A harness deployment serves reef.recipe.harness:HarnessEvolutionRecipe. The
recipe keeps the agent harness as a tree of text files. At each step, a method
edits a copy of that tree from the step's traces, the evaluation runs the real
agent on tasks with the candidate, and a candidate that wins publishes as a
snapshot that any client can pull. The
harness evolution tutorial runs the
smallest full loop on pi. It needs an OpenAI-compatible endpoint, and Node.js
and npm for pi. From your Reef checkout and activated Python environment:
cd tutorials/evolve-your-harness
./run.sh
configs/serve.yaml names the endpoint (inference.upstream-url, no /v1
suffix) and the model (inference.upstream-model). Edit them to point at your
own provider, and set REEF_UPSTREAM_API_KEY if the endpoint needs a key.
run.sh starts Reef on 127.0.0.1:8900, sends the tasks through it, reports
each score, and pulls the published tree. Each run writes work/replay.html
with the snapshot chain and the files each step changed.
GET /reef/harness serves the published tree, rendered for the deployment's
adapter. The files carry no endpoint, key, or model: a client writes them
where the agent reads them and binds the agent's model to this Reef (see
Use a published tree).
Write the tree outside the project the agent works in: a session can write
files in its project, so a tree there could change what the next session
runs. Evolve agent prompts, rules, and skills
explains the loop and its configuration.
📚 Recipes and examples
Pick a recipe by the task type of your workload and by what it should
evolve, model weights or the agent harness. Weight recipes need the GPU
training stack, while harness recipes need only a model endpoint. Each recipe
below links to its guide and each measured benchmark links to its results
page, and the recipe catalog
adds the code and example for every recipe.
SFT ships with reef-infra
and trains on demonstrations or imported examples for every task type.
The other implementations live in this repository's recipes/ cookbook,
selected by dotted class reference and not shipped in the Reef wheel.
| Task type | Task shape | Evolves the model | Evolves the harness | Standard benchmarks |
|---|---|---|---|---|
| Open-ended discovery | Repeated attempts at one hard problem with a measurable objective and no known answer | TTT-Discover, Guidance-TTT | None yet | Measured: TriMul, circle packing, Erdős minimum overlap. |
| Offline tasks with a known answer | Independent tasks from a fixed set, each with a reference answer | SAO, SDFT, SDPO, OPD | GEPA, Meta-Harness | Measured: IMOAnswerBench, AIME 2024, AIME 2025, SciKnowEval, ToolAlpaca, Terminal-Bench. |
| Online learning from usage | Sessions with a user, where the interaction itself is the signal | OpenClaw-RL | ACE, ReasoningBank | Measured: GSM8K with a simulated student user. |
recipes/basic/ is the record-only starting stack and stays
outside the catalog. For a small walkthrough of feedback, candidate edits, and
publication, start with the coding harness tutorial.
Each result page documents its task, evaluation setup, measurements, and
limitations.
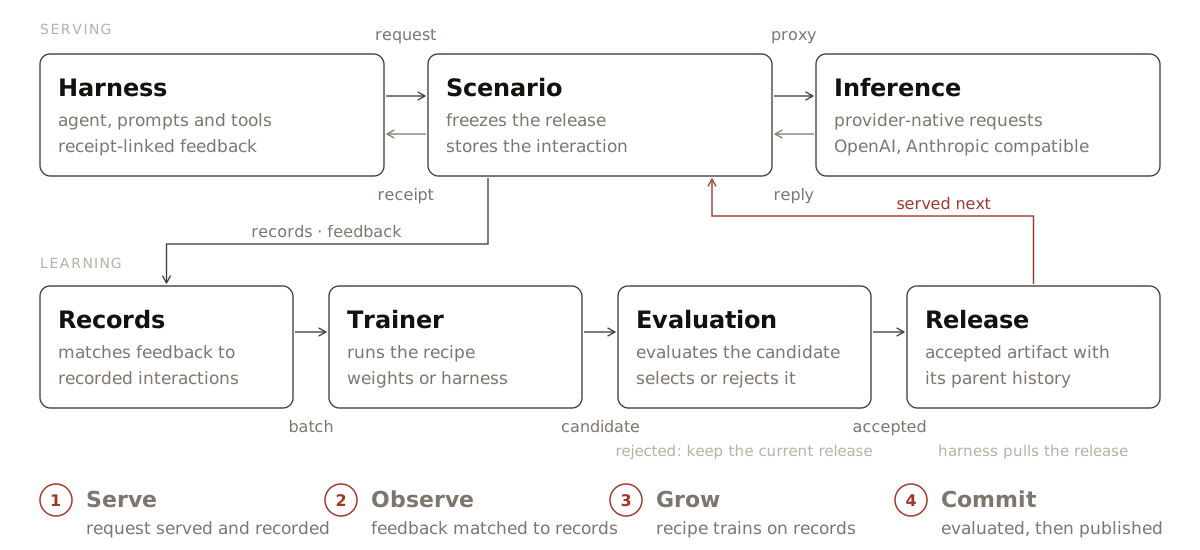
📐 Architecture
📖 Learn more
The documentation is organized in the following order:
- Quickstart: install Reef, connect a client, and inspect the version history
- HTTP API: use the HTTP API and report feedback
- Write a recipe: configure how Reef processes data and produces updates
- Evolve your harness: evolve a harness instead of model weights
- Evolve your model: configure and operate a training deployment
- Recipes: the catalog of cookbook recipes by task type, with code, docs, example, and results for each
- The core loop: The core loop of Reef
- Glossary: Explanation of the terminologies used
🤝 Community & Contributing
Working on continual self-improving agent?
- Join Discord to share your recipes, ask implementation questions, and discuss new features.
- Join the WeChat group: the group is full, so add the assistant and it will invite you.
- Join the GitHub Discussions to ask questions, share ideas, and connect with the community.
- Start contributing with the contribution guide.
- Propose designs through an RFC issue.
- Report suspected vulnerabilities privately by following the security policy.
If Reef looks useful to you, please give it a ⭐ — it helps the community to discover and contribute to the project.
📚 Citation
If you use Reef in your research, please cite:
@misc{reef2026,
  title  = {Reef: Infrastructure for Continually Self-Improving Agents},
  author = {{Reef Contributors}},
  year   = {2026},
  url    = {https://github.com/Human-Agent-Society/reef}
}
Citation metadata is also available in CITATION.cff.
👥 The Team
Reef brings together people exploring how agents can learn from experience and improve over time. The people below help turn that idea into working infrastructure.
This list is non-exhaustive, with team members listed alphabetically by last name:
Wenhao Chai, Shuangrui Ding, Shiyi Zoe Du, Hao He, Haoze He, Chonghe Jiang, Nan Jiang, Xuan Jiang, Xiaochen Li, Paul Liang, Bo Liu, Boyuan Long, Qiuyang Mang, Zhenting Qi, Ao Qu, Mingruo Qu, Yihong Tang, Zhaokai Wang, Xuezhi Yan, Hanfei Yu, Haofei Yu, Simon Yu, Han Zheng, Kaichen Zhou, Zijian Zhou, Jiacheng Zhu, Dingyi Zhuang, Xinkai Zou.
⭐ Star History
🙏 Acknowledgements
We are particularly grateful to these projects which power important parts of Reef:
Explore related projects
affaan-m/ECC
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
298,657 starsNousResearch/hermes-agent
The agent that grows with you
261,248 starsmultica-ai/andrej-karpathy-skills
A single CLAUDE.md file to improve Claude Code behavior, derived from Andrej Karpathy's observations on LLM coding pitfalls.
230,333 starsfirecrawl/firecrawl
Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥
199,303 stars