
HKUST-KnowComp/R-Net has 575 GitHub stars and 209 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-09 16:38 UTC. Last push 2018-08-08.
Tensorflow Implementation of R-Net
Measured star growth
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalR-Net
- A Tensorflow implementation of R-NET: MACHINE READING COMPREHENSION WITH SELF-MATCHING NETWORKS. This project is specially designed for the SQuAD dataset.
- Should you have any question, please contact Wenxuan Zhou ([email protected]).
Requirements
There have been a lot of known problems caused by using different software versions. Please check your versions before opening issues or emailing me.
General
- Python >= 3.4
- unzip, wget
Python Packages
- tensorflow-gpu >= 1.5.0
- spaCy >= 2.0.0
- tqdm
- ujson
Usage
To download and preprocess the data, run
# download SQuAD and Glove
sh download.sh
# preprocess the data
python config.py --mode prepro
Hyper parameters are stored in config.py. To debug/train/test the model, run
python config.py --mode debug/train/test
To get the official score, run
python evaluate-v1.1.py ~/data/squad/dev-v1.1.json log/answer/answer.json
The default directory for tensorboard log file is log/event
See release for trained model.
Detailed Implementaion
- The original paper uses additive attention, which consumes lots of memory. This project adopts scaled multiplicative attention presented in Attention Is All You Need.
- This project adopts variational dropout presented in A Theoretically Grounded Application of Dropout in Recurrent Neural Networks.
- To solve the degradation problem in stacked RNN, outputs of each layer are concatenated to produce the final output.
- When the loss on dev set increases in a certain period, the learning rate is halved.
- During prediction, the project adopts search method presented in Machine Comprehension Using Match-LSTM and Answer Pointer.
- To address efficiency issue, this implementation uses bucketing method (contributed by xiongyifan) and CudnnGRU. The bucketing method can speedup training, but will lower the F1 score by 0.3%.
Performance
Score
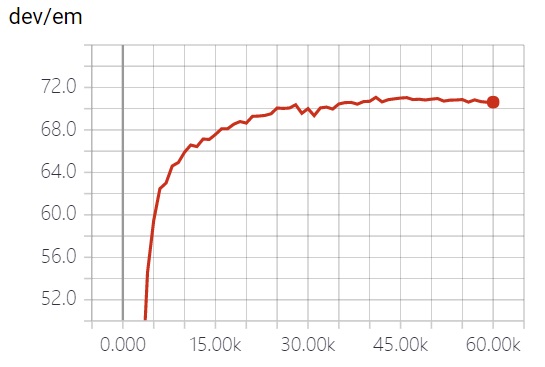
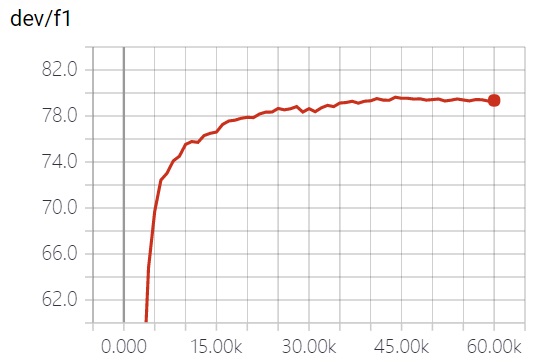
| EM | F1 | |
|---|---|---|
| original paper | 71.1 | 79.5 |
| this project | 71.07 | 79.51 |
Training Time (s/it)
| Native | Native + Bucket | Cudnn | Cudnn + Bucket | |
|---|---|---|---|---|
| E5-2640 | 6.21 | 3.56 | - | - |
| TITAN X | 2.56 | 1.31 | 0.41 | 0.28 |
Extensions
These settings may increase the score but not used in the model by default. You can turn these settings on in config.py.
- Pretrained GloVe character embedding. Contributed by yanghanxy.
- Fasttext Embedding. Contributed by xiongyifan. May increase the F1 by 1% (reported by xiongyifan).
Explore related projects
tensorflow/tensorflow
An Open Source Machine Learning Framework for Everyone
201,427 starshuggingface/transformers
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
168,711 starsAUTOMATIC1111/stable-diffusion-webui
Stable Diffusion web UI
165,274 starsComfy-Org/ComfyUI
The most powerful and modular diffusion model GUI, api and backend with a graph/nodes interface. The fastest local inference engine in the world.
146,024 stars