
EdGENetworks/attention-networks-for-classification
EdGENetworks/attention-networks-for-classification has 607 GitHub stars and 129 forks. GitHot measured 0 stars in 24 hours, +1 in 7 days, and +1 in 15 days. Last checked 2026-11-12 12:37 UTC. Last push 2020-03-04.
Hierarchical Attention Networks for Document Classification in PyTorch
Measured star growth
- in 24h
- 0
- in 7 days
- +1
- in 15 days
- +1
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalHierarchical Attention Networks for Document Classification
We know that documents have a hierarchical structure, words combine to form sentences and sentences combine to form documents. We can try to learn that structure or we can input this hierarchical structure into the model and see if it improves the performance of existing models. This paper exploits that structure to build a classification model.
This is an (close) implementation of the model in PyTorch.
Note:
- I jointly optimize both the word and sentence attention models with the same optimizer.
- The minibatches are padded with zeros. This can be improved, one can sort senteces with similar length together, and minimize the paddings.
- Pytorch does not yet support gradient masking, so padded zeros will have gradients flowing through them during backpropagation. One can create a mask, but since I am interested in using Bidirectional GRU, it is not possible to use a mask. I've seen that variable length RNN supoort is coming soon to Pytorch as well. Update: Pytorch does supoort masked RNN now with pack_padded_sequence method.
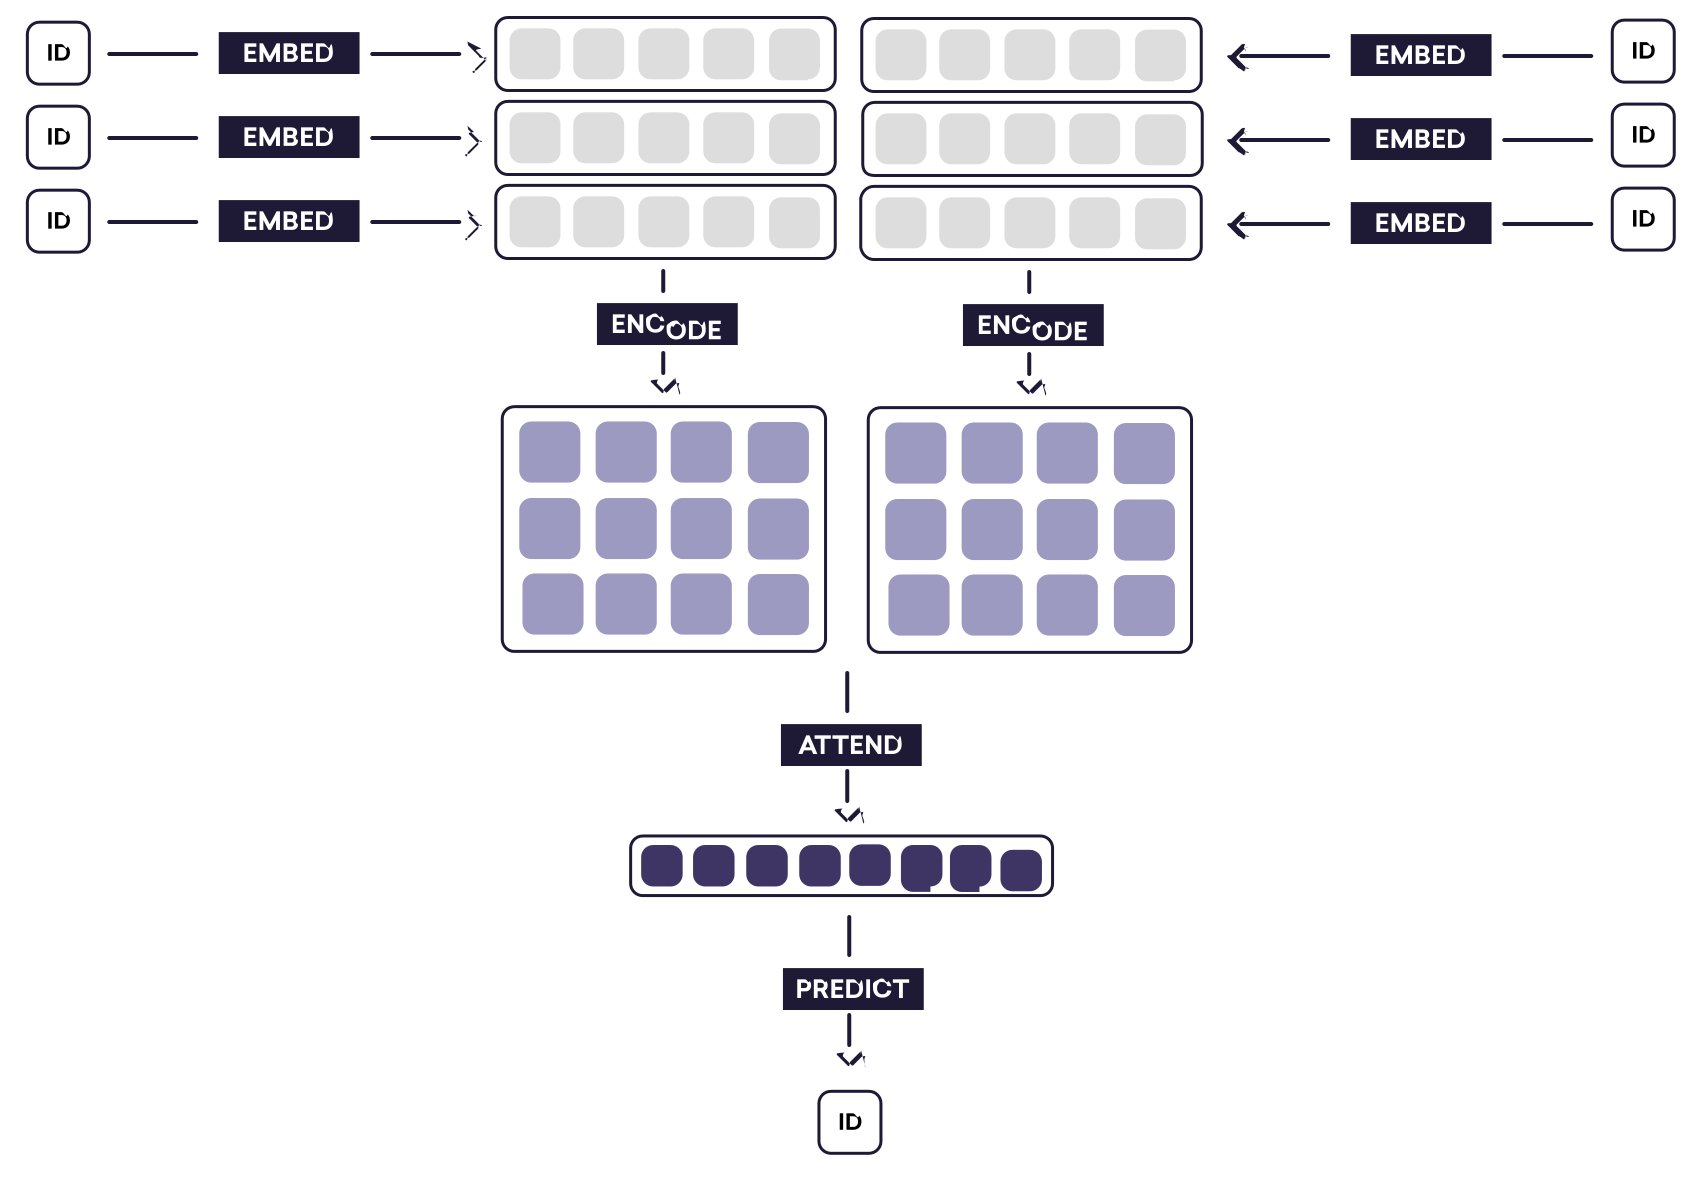
This picture from Explosion blog explains the structure perfectly.
Notebook
The notebook contains an example of trained model on IMDB movie review dataset. I could not get the original IMDB dataset that the paper referred to, so I have used this data
The preprocessed data is available here
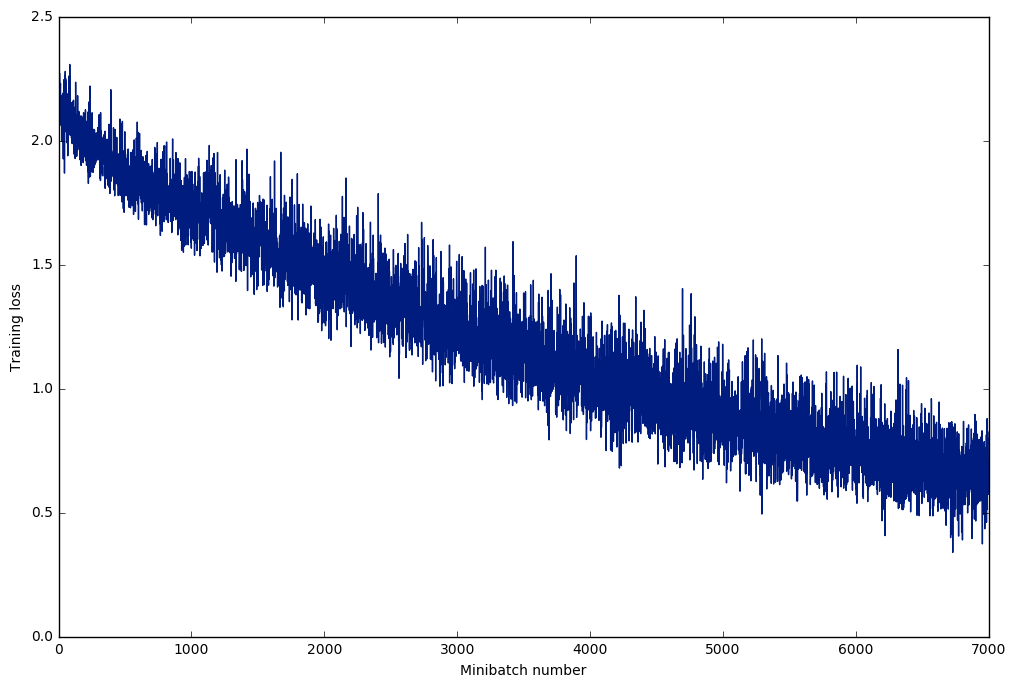
The best accuracy that I got was around ~ 0.35. This dataset has only 84919 samples and 10 classes. Here is the training loss for the dataset.
Explore related projects
tensorflow/tensorflow
An Open Source Machine Learning Framework for Everyone
201,505 starshuggingface/transformers
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
168,815 starsAUTOMATIC1111/stable-diffusion-webui
Stable Diffusion web UI
165,300 starsComfy-Org/ComfyUI
The most powerful and modular diffusion model GUI, api and backend with a graph/nodes interface. The fastest local inference engine in the world.
146,472 stars