
CliMA/EnsembleKalmanProcesses.jl
CliMA/EnsembleKalmanProcesses.jl has 131 GitHub stars and 23 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-18 07:56 UTC. Last push 2026-11-12.
What you can do
- Derivative-free: no gradients of the forward model G are required — you only need to run it at different parameter values.
- Language-agnostic: G does not need to be written in Julia.
- Efficient at scale: computational complexity does not scale strongly with the number of parameters, and the methods tolerate noisy and complex parameter-to-data landscapes.
- Parallelizable: ensemble model evaluations are embarrassingly parallel, so you can exploit HPC resources (parallelism guide).
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Derivative-free parameter calibration and uncertainty quantification for expensive models using ensemble Kalman methods
Machine LearningREADME.md
OriginalEnsembleKalmanProcesses.jl
Derivative-free optimization and approximate uncertainty quantification, built on ensemble Kalman methods.
EnsembleKalmanProcesses.jl (EKP) helps you find (locally) optimal parameters u for a computer model G so that it fits noisy observational data y. It implements a suite of methods from the ensemble Kalman filtering literature and works with any model you can run at different parameter values, in Julia or not.
| Documentation |   |
| Version |  |
| License |  |
| Tests |  |
| Code Coverage |  |
| Downloads |  |
| DOI |  |
| JOSS |  |
Features
- Derivative-free: no gradients of the forward model
Gare required — you only need to run it at different parameter values. - Language-agnostic:
Gdoes not need to be written in Julia. - Efficient at scale: computational complexity does not scale strongly with the number of parameters, and the methods tolerate noisy and complex parameter-to-data landscapes.
- Parallelizable: ensemble model evaluations are embarrassingly parallel, so you can exploit HPC resources (parallelism guide).
- Composable priors and observations: lego-like interfaces for building complex parameter distributions and observations.
- Many algorithms, one interface: toggle between ensemble Kalman inversion, sampling, unscented, transform, and Gauss–Newton variants and their configurable features (recommended configurations).
Installation
EnsembleKalmanProcesses.jl is a registered Julia package, requiring Julia LTS version or newer. Install it with the built-in package manager:
using Pkg
Pkg.add("EnsembleKalmanProcesses")
See the installation instructions for developer setup.
Quick example
We solve the classic inverse problem of finding parameters u from data y = G(u), where the forward map G carries additive noise distributed as N(0, Γ). Copy-paste the snippets to reproduce the results (up to random number generation).
using LinearAlgebra
G(u) = [
    1/abs(u[1]),
    sum(u[2:5]),
    prod(u[3:4]),
    u[1]^2-u[2]-u[3],
    u[4],
    u[5]^3,
    ] .+ 0.1*randn(6)
true_u = [3, 1, 2,-3,-4]
y = G(true_u)
Γ = (0.1)^2*I
We assume some prior knowledge of the parameters u (such as approximate scales, and the first parameter being positive), then we are ready to go:
using EnsembleKalmanProcesses
using EnsembleKalmanProcesses.ParameterDistributions

prior_u1 = constrained_gaussian("positive_with_mean_2", 2, 1, 0, Inf)
prior_u2 = constrained_gaussian("four_with_spread_5", 0, 5, -Inf, Inf, repeats=4)
prior = combine_distributions([prior_u1, prior_u2])

N_ensemble = 50
initial_ensemble = construct_initial_ensemble(prior, N_ensemble)
ensemble_kalman_process = EnsembleKalmanProcess(
    initial_ensemble, y, Γ, Inversion(), verbose=true)

N_iterations = 10
for i in 1:N_iterations
    params_i = get_ϕ_final(prior, ensemble_kalman_process)

    G_matrix = hcat(
        [G(params_i[:, j]) for j in 1:N_ensemble]... # Parallelize here!
    )

    update_ensemble!(ensemble_kalman_process, G_matrix)
end

final_solution = get_ϕ_mean_final(prior, ensemble_kalman_process)

# Let's see what's going on!
using Plots
p = plot(prior)
for (i, sp) in enumerate(p.subplots)
    vline!(sp, [true_u[i]], lc="black", lw=4)
    vline!(sp, [final_solution[i]], lc="magenta", lw=4)
end
display(p)
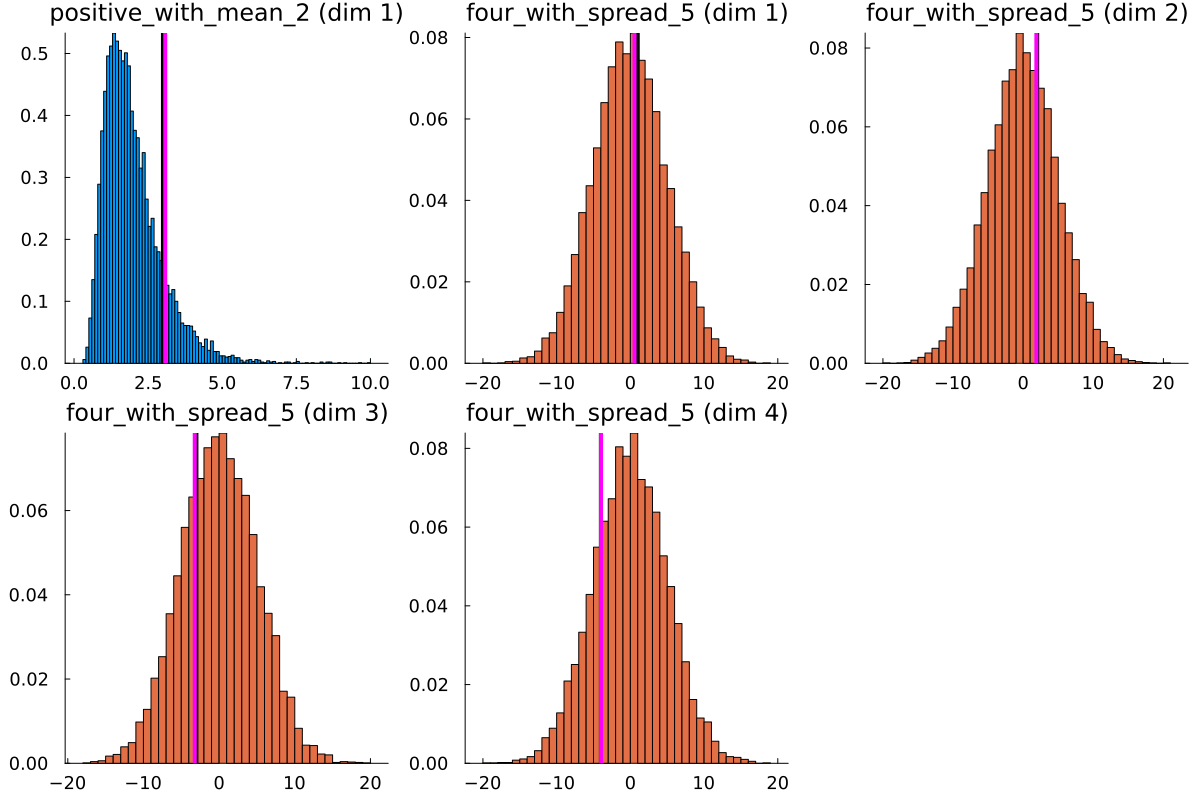
For a walkthrough of a similar problem, see the sinusoid example; many more example scripts live in examples/.
Documentation
New to the package? This roadmap shows how the pieces fit together:
Common questions
- How do I build prior distributions?
- How do I access parameters/outputs from the ekp object?
- How do I plot convergence errors or parameter distributions?
- How do I build good observational noise covariances?
- How do I build my observations and encode batching?
- What ensemble size should I take? Which process should I use? What is the recommended configuration?
- What is the difference between
get_uandget_ϕ? Why do the stored parameters appear to be outside their bounds? - What can be parallelized? How do I do it in Julia?
- What is going on in my own code?
- What is this error/warning/message?
- Where can I walk through a simple example?
- How can Claude Code help maintain or use this package?
Integration with CliMA models
EnsembleKalmanProcesses.jl is a standalone package with no dependence on the rest of the CliMA ecosystem — you can use it to calibrate any model. Within CliMA, ClimaCalibrate.jl builds on it to run HPC calibration pipelines for models such as ClimaAtmos.jl and ClimaLand.jl.
Contributing
Contributions are welcome! See the contributing guide for how to open issues and pull requests. Development follows the shared CliMA engineering standards in CliMA/DeveloperGuides.
Citing us
If you use the examples or code, please cite our article at JOSS in your published materials.
Claude integration
This repository ships Claude Code skills in .claude/skills/ that automate common maintenance tasks. If you're developing EnsembleKalmanProcesses.jl with Claude Code, these trigger automatically when your prompt matches their purpose — no need to invoke them by name.
Skills for package developers
| Skill | What it does | Example prompt |
|---|---|---|
math-auditor |
Runs an adversarial mathematical-accuracy review of src/ and test/, producing a dated report plus self-contained fix prompts for a follow-up session. |
"Review the math in src/ and test/ for correctness — construct an adversarial code review as markdown." |
docstrings |
Adds or normalises docstrings on exported symbols so the public API is self-documenting and Documenter.jl's checkdocs passes, then syncs the docs/src/API/ pages. |
"Add docstrings to the exported functions in src/Localizers.jl and make sure they show up on the API page." |
error-message-manager |
Rewrites vague or low-context Julia error messages (bare @assert, generic ArgumentError/DimensionMismatch, unhelpful throws) into structured, actionable diagnostics. |
"The DimensionMismatch error you get from a bad prior/observation size mismatch is really unhelpful — can you improve it?" |
base-show |
Adds concise Base.show/Base.summary methods to Julia types whose default REPL representation is unhelpful or overwhelming. |
"The REPL output for EnsembleKalmanProcess is way too verbose — can you make it print something more useful?" |
Skills for package users — coming soon
The following skills are aimed at people using EnsembleKalmanProcesses.jl in their own projects, not at developers of this package, so they aren't installed automatically in your own repository.
slurm-pipeline-manager— scaffolds and maintains a SLURM/HPC job-dependency tree for an EKP calibration pipeline (forward-model ensemble jobs, aggregation, and update steps wired together withsbatchdependencies).
Until these are published as a standalone install, copy the skill folder you want from this repo's .claude/skills/ directory into the .claude/skills/ directory of your own project to use it with Claude Code.