
Chandaro/BacII-Math-AI
Chandaro/BacII-Math-AI has 6 GitHub stars and 0 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-14 20:04 UTC. Last push 2026-11-11.
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Open Khmer math AI for Cambodia's BacII exam: 108K worked solutions in Khmer, verified by SymPy, and a fine-tuned Gemma 3 12B model
AIREADME.md
OriginalBacII Math AI for Cambodia
Open Khmer math AI for Cambodia's BacII exam: 108K worked solutions and a fine-tuned Gemma 3 model.
A Khmer-language math dataset in the style of Cambodia's Grade 12 BacII exam, and a model adapter trained on it.
- 108,332 exercises with full worked solutions in Khmer, math in LaTeX, across 8 BacII chapters.
- Every answer is computed by SymPy. No language model wrote a solution.
- A LoRA adapter for Gemma 3 12B (Run 8, "Daro Dai Chav 5") that answers in Khmer BacII style. It runs on an Apple silicon Mac.
- A local chat page with an automatic answer check against the dataset or SymPy.
For testing and research only. The model still makes mistakes, for example 26 of 40 right on conics and 3D geometry. Do not show its answers to students without a teacher checking them.
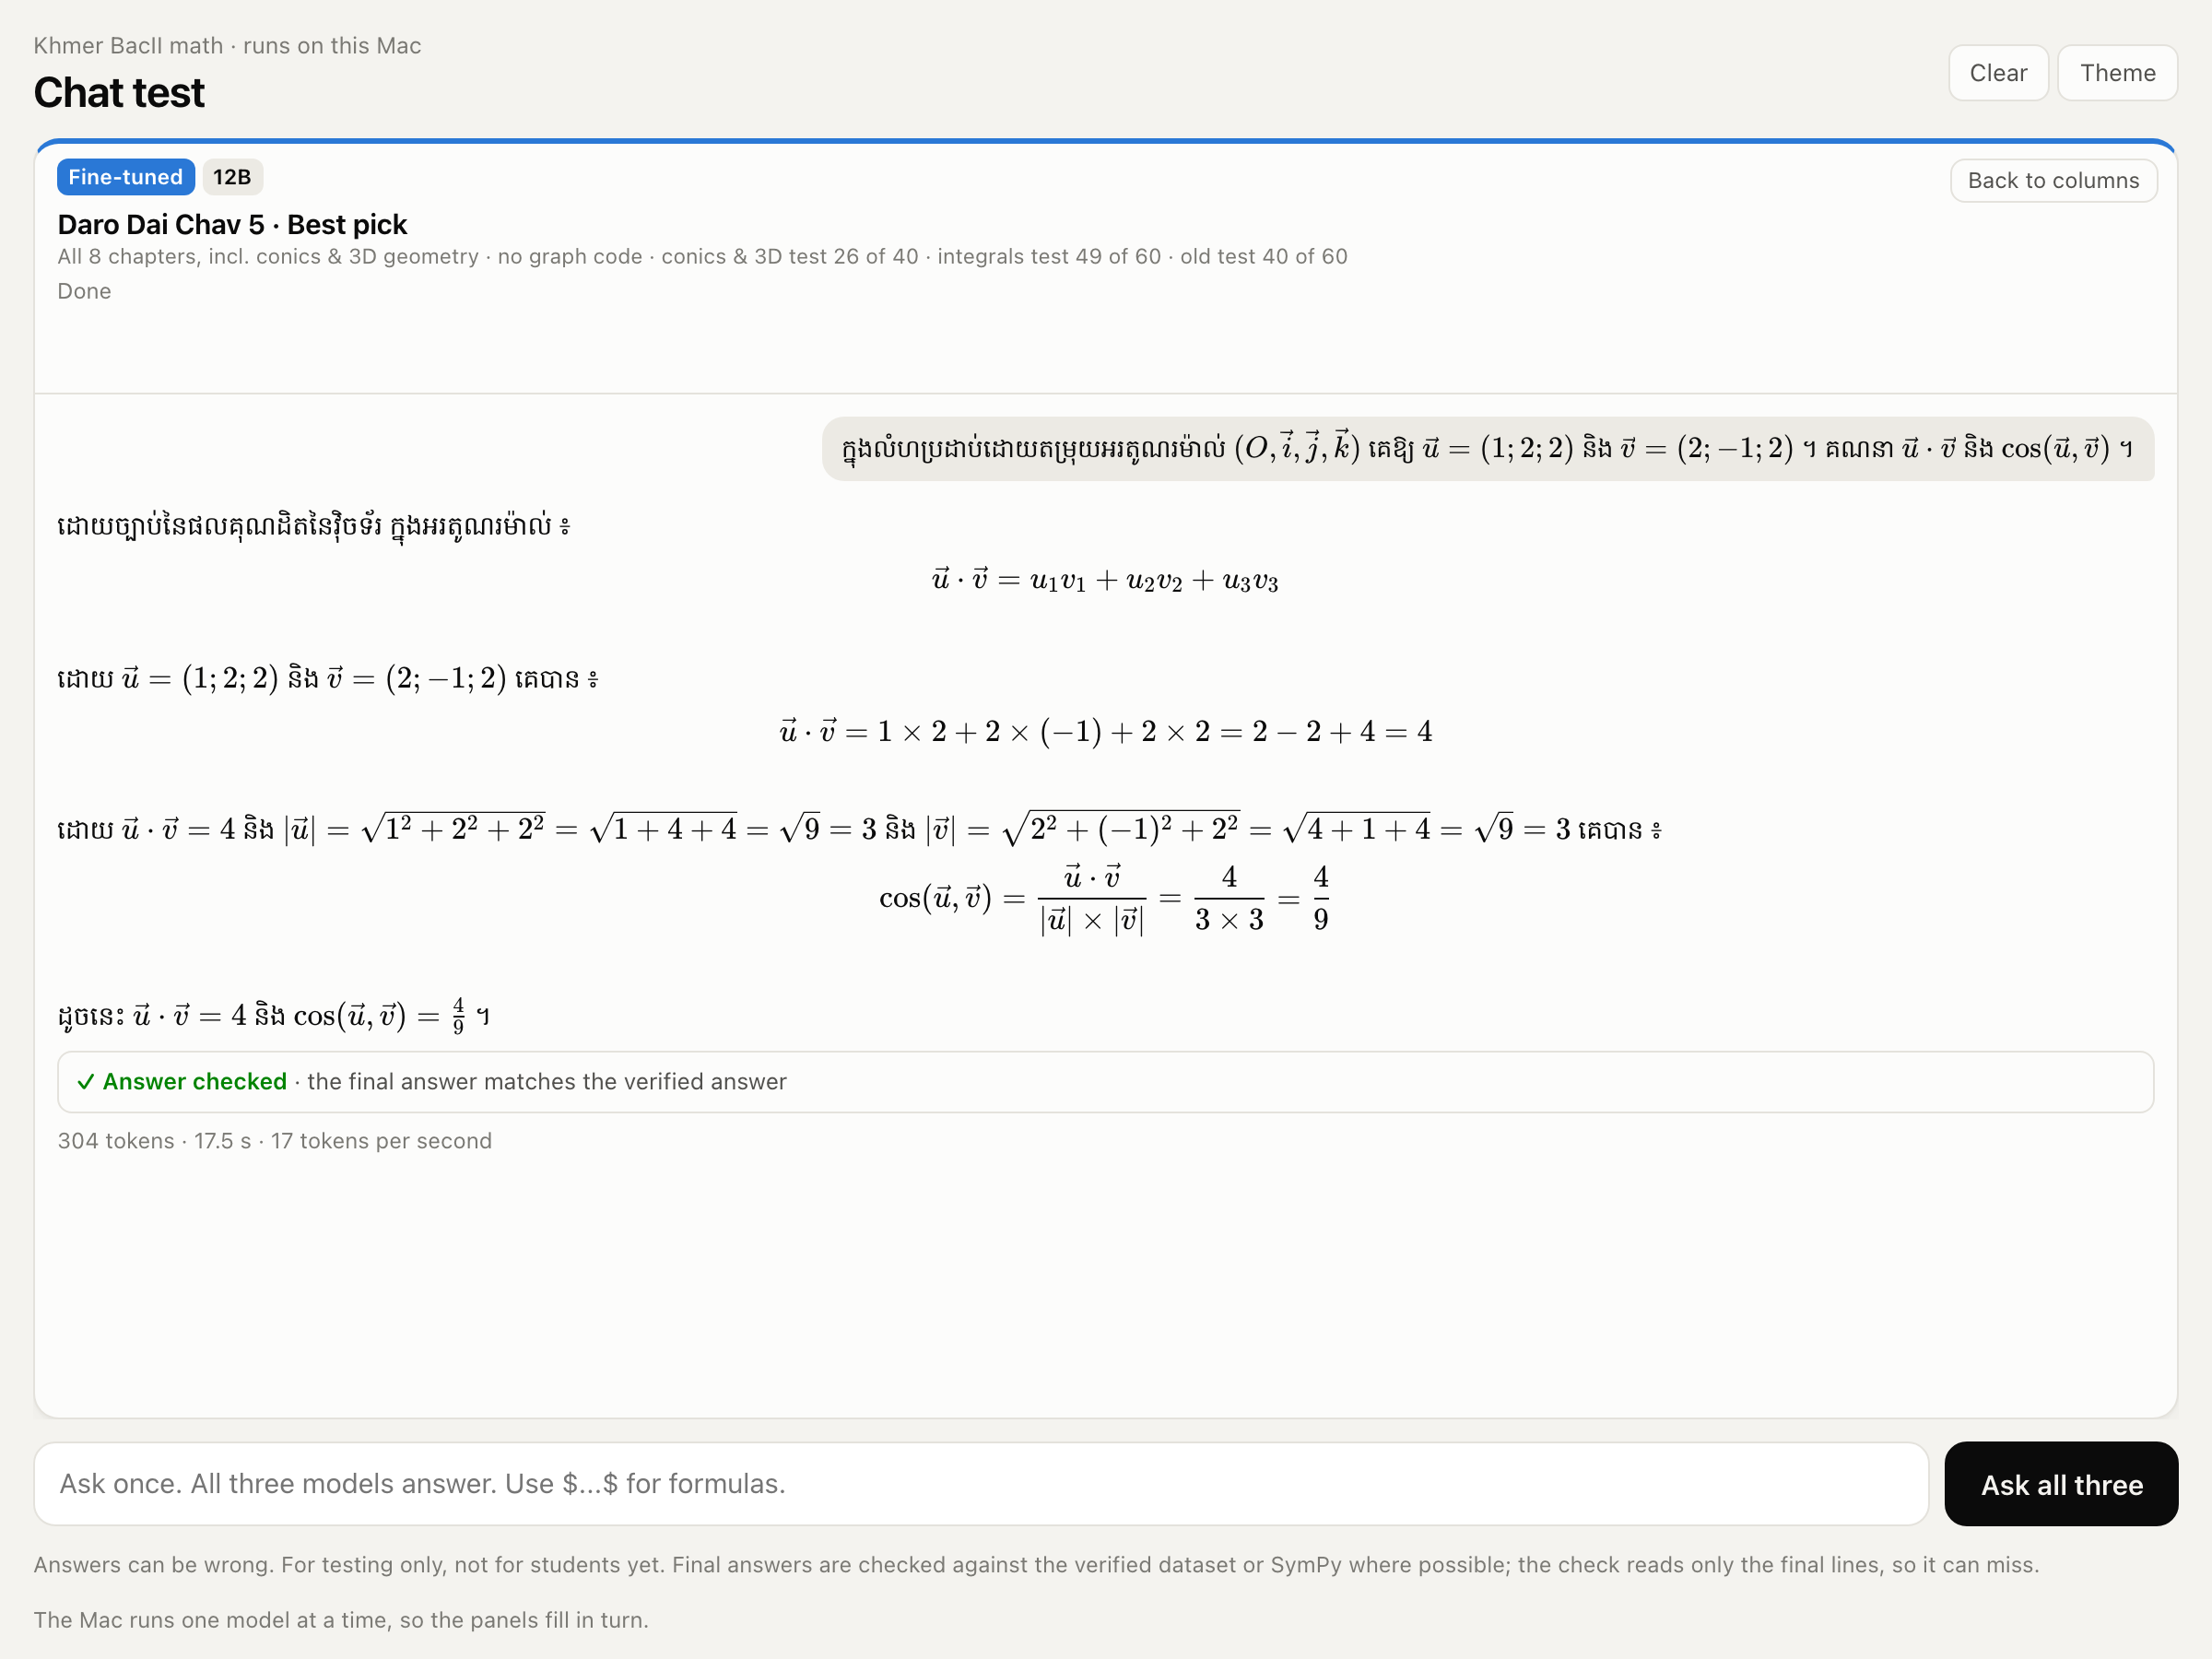
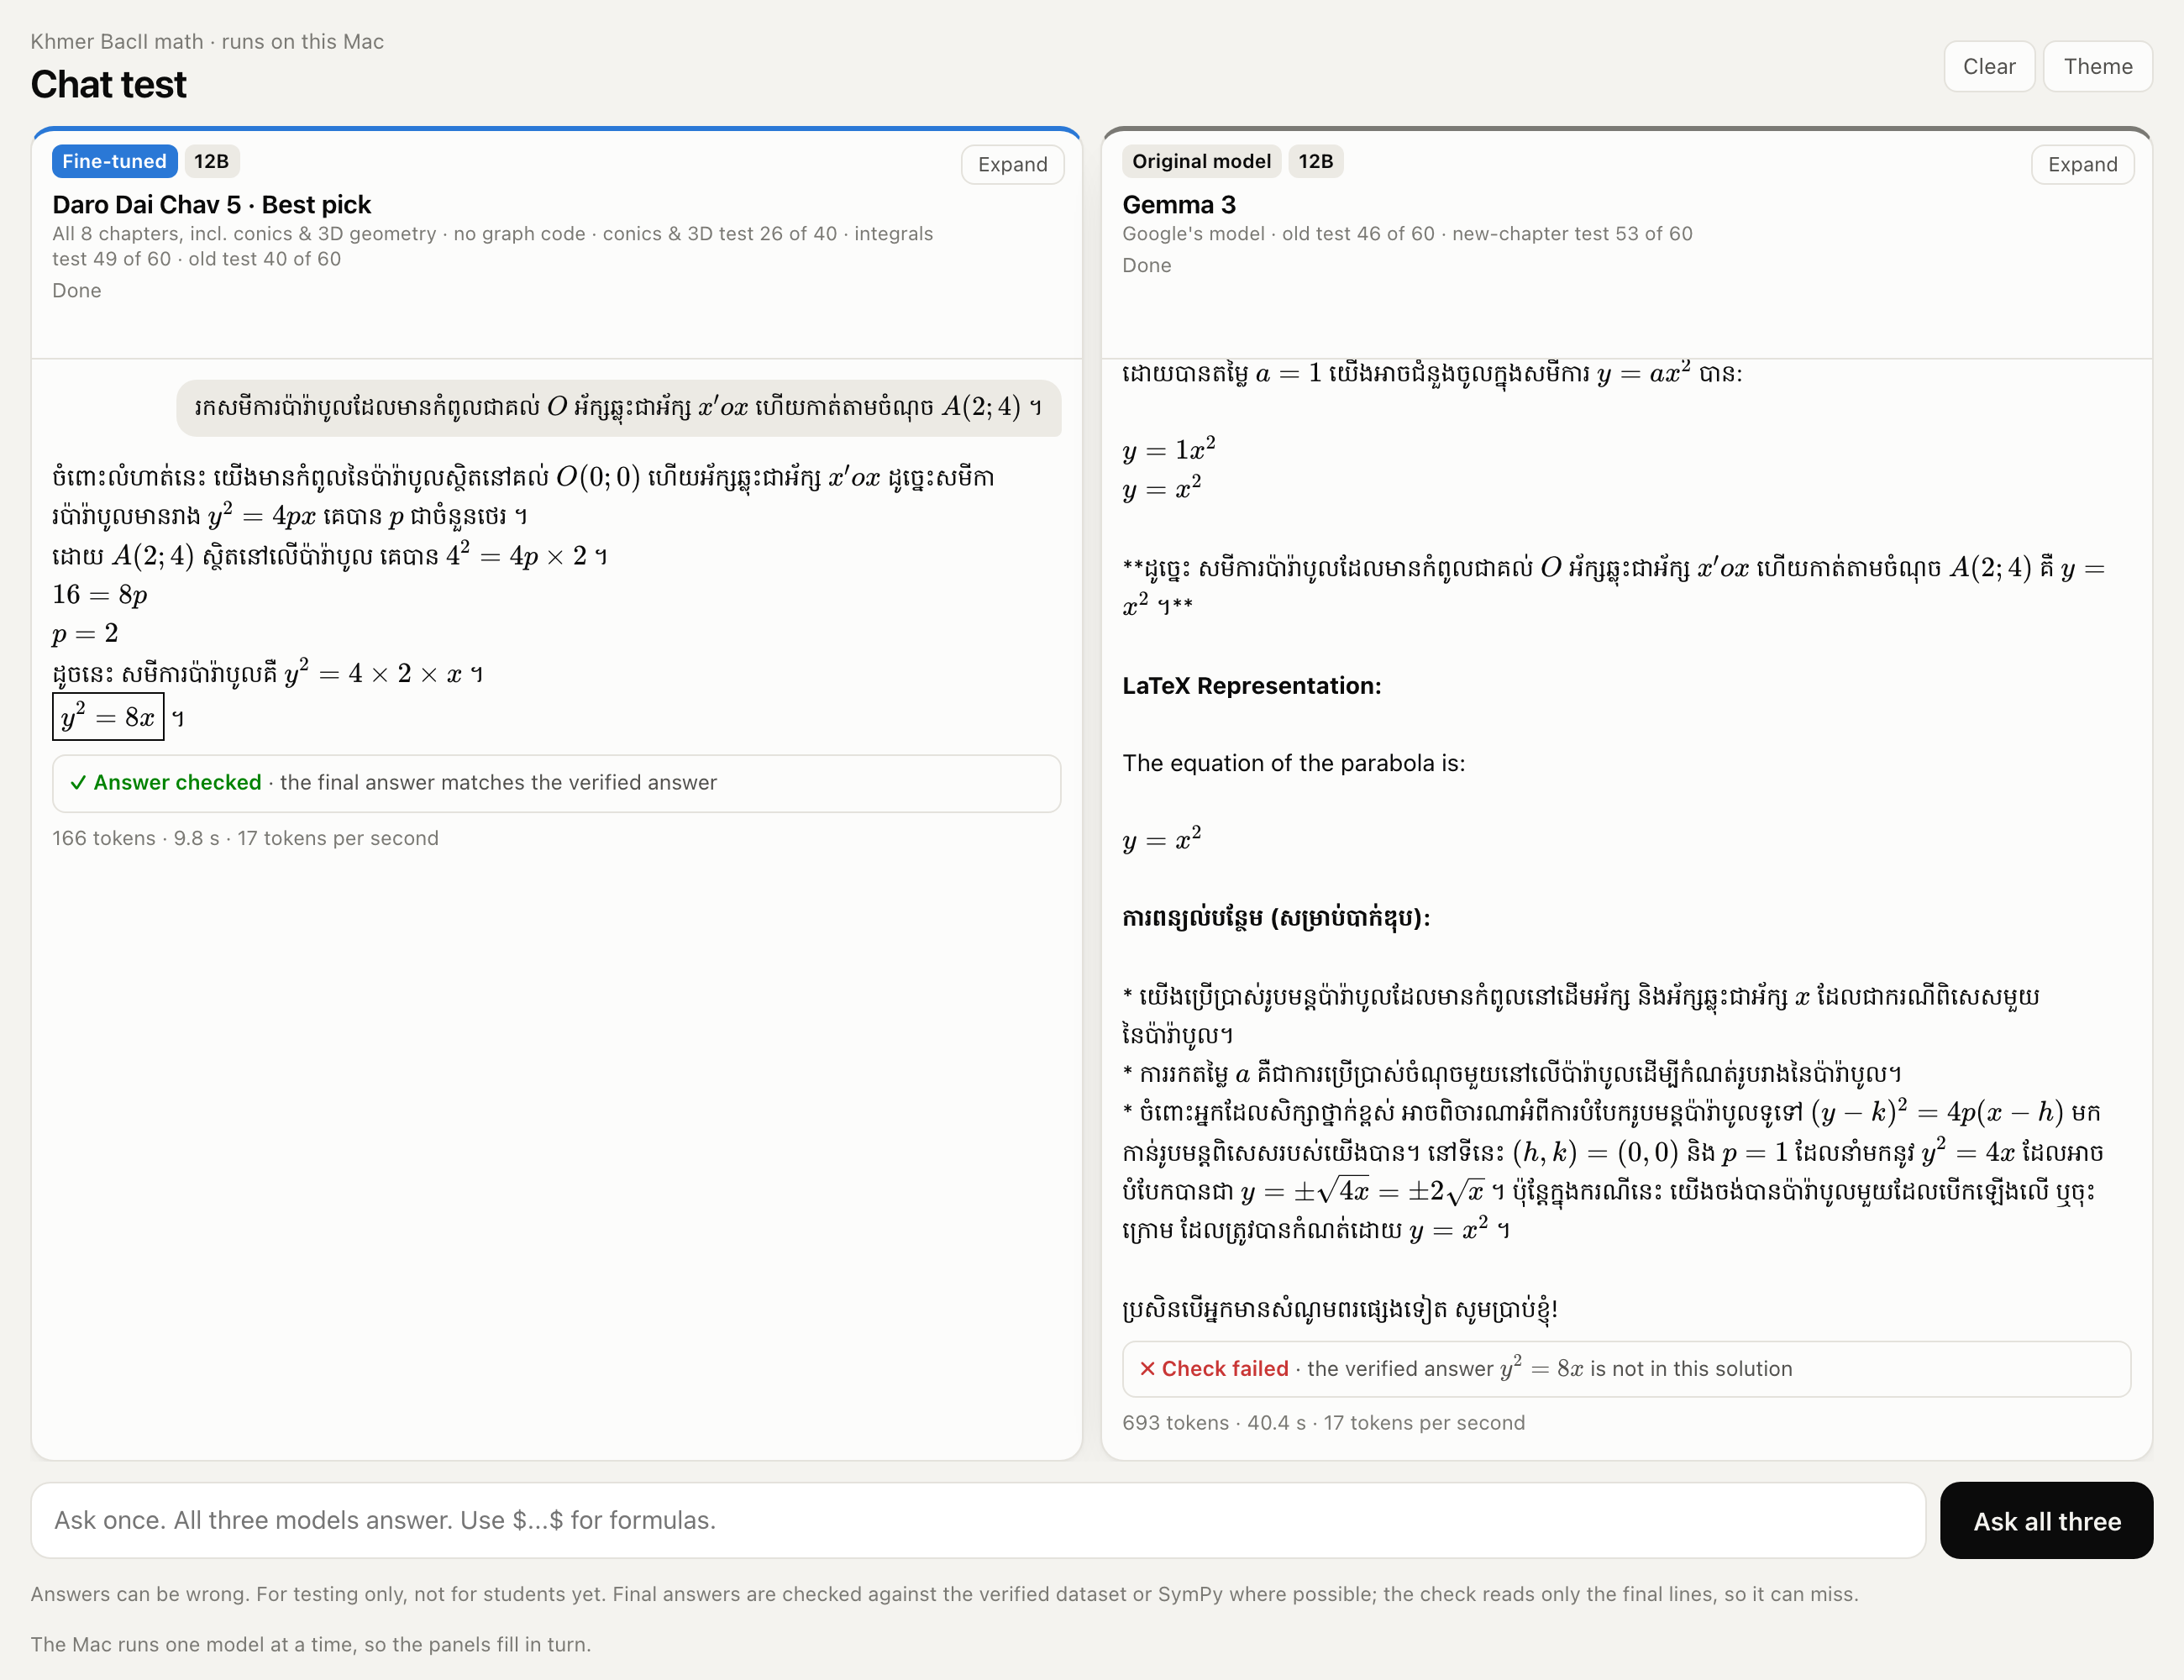
The chat page running on a Mac. The model answers in Khmer BacII style, and the answer check confirms the final answer against the verified dataset.
Dataset
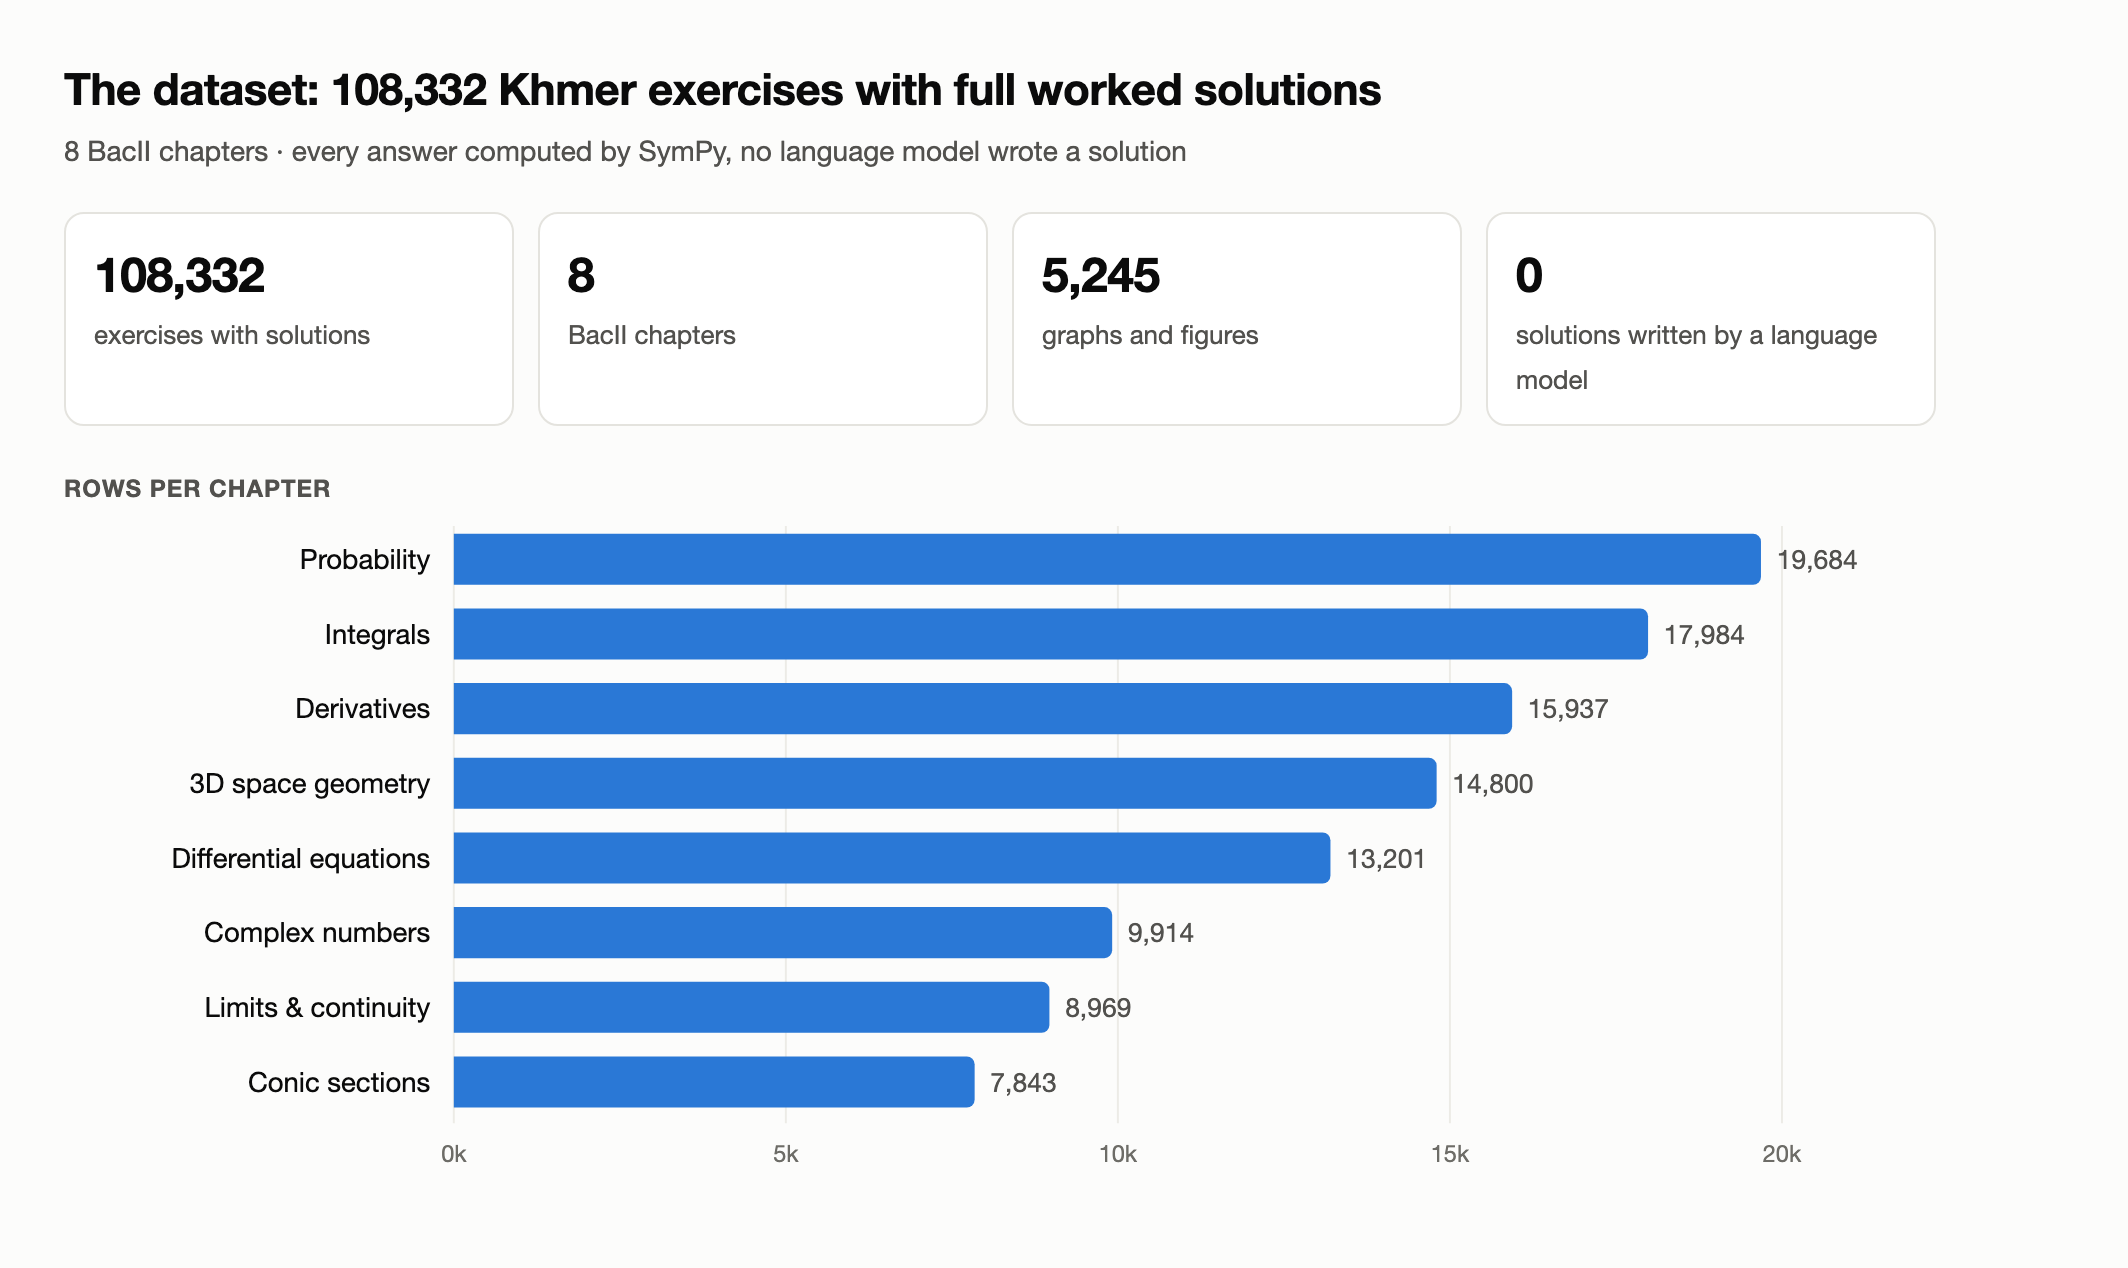
| Chapter | File | Rows |
|---|---|---|
| Derivatives | dataset/derivative_km.jsonl |
15,937 |
| Complex numbers | dataset/complex_km.jsonl |
9,914 |
| Limits and continuity | dataset/limit_km.jsonl |
8,969 |
| Integrals | dataset/integral_km.jsonl |
17,984 |
| Differential equations | dataset/diffeq_km.jsonl |
13,201 |
| Probability | dataset/probability_km.jsonl |
19,684 |
| Conic sections | dataset/conic_km.jsonl |
7,843 |
| 3D space geometry | dataset/space_km.jsonl |
14,800 |
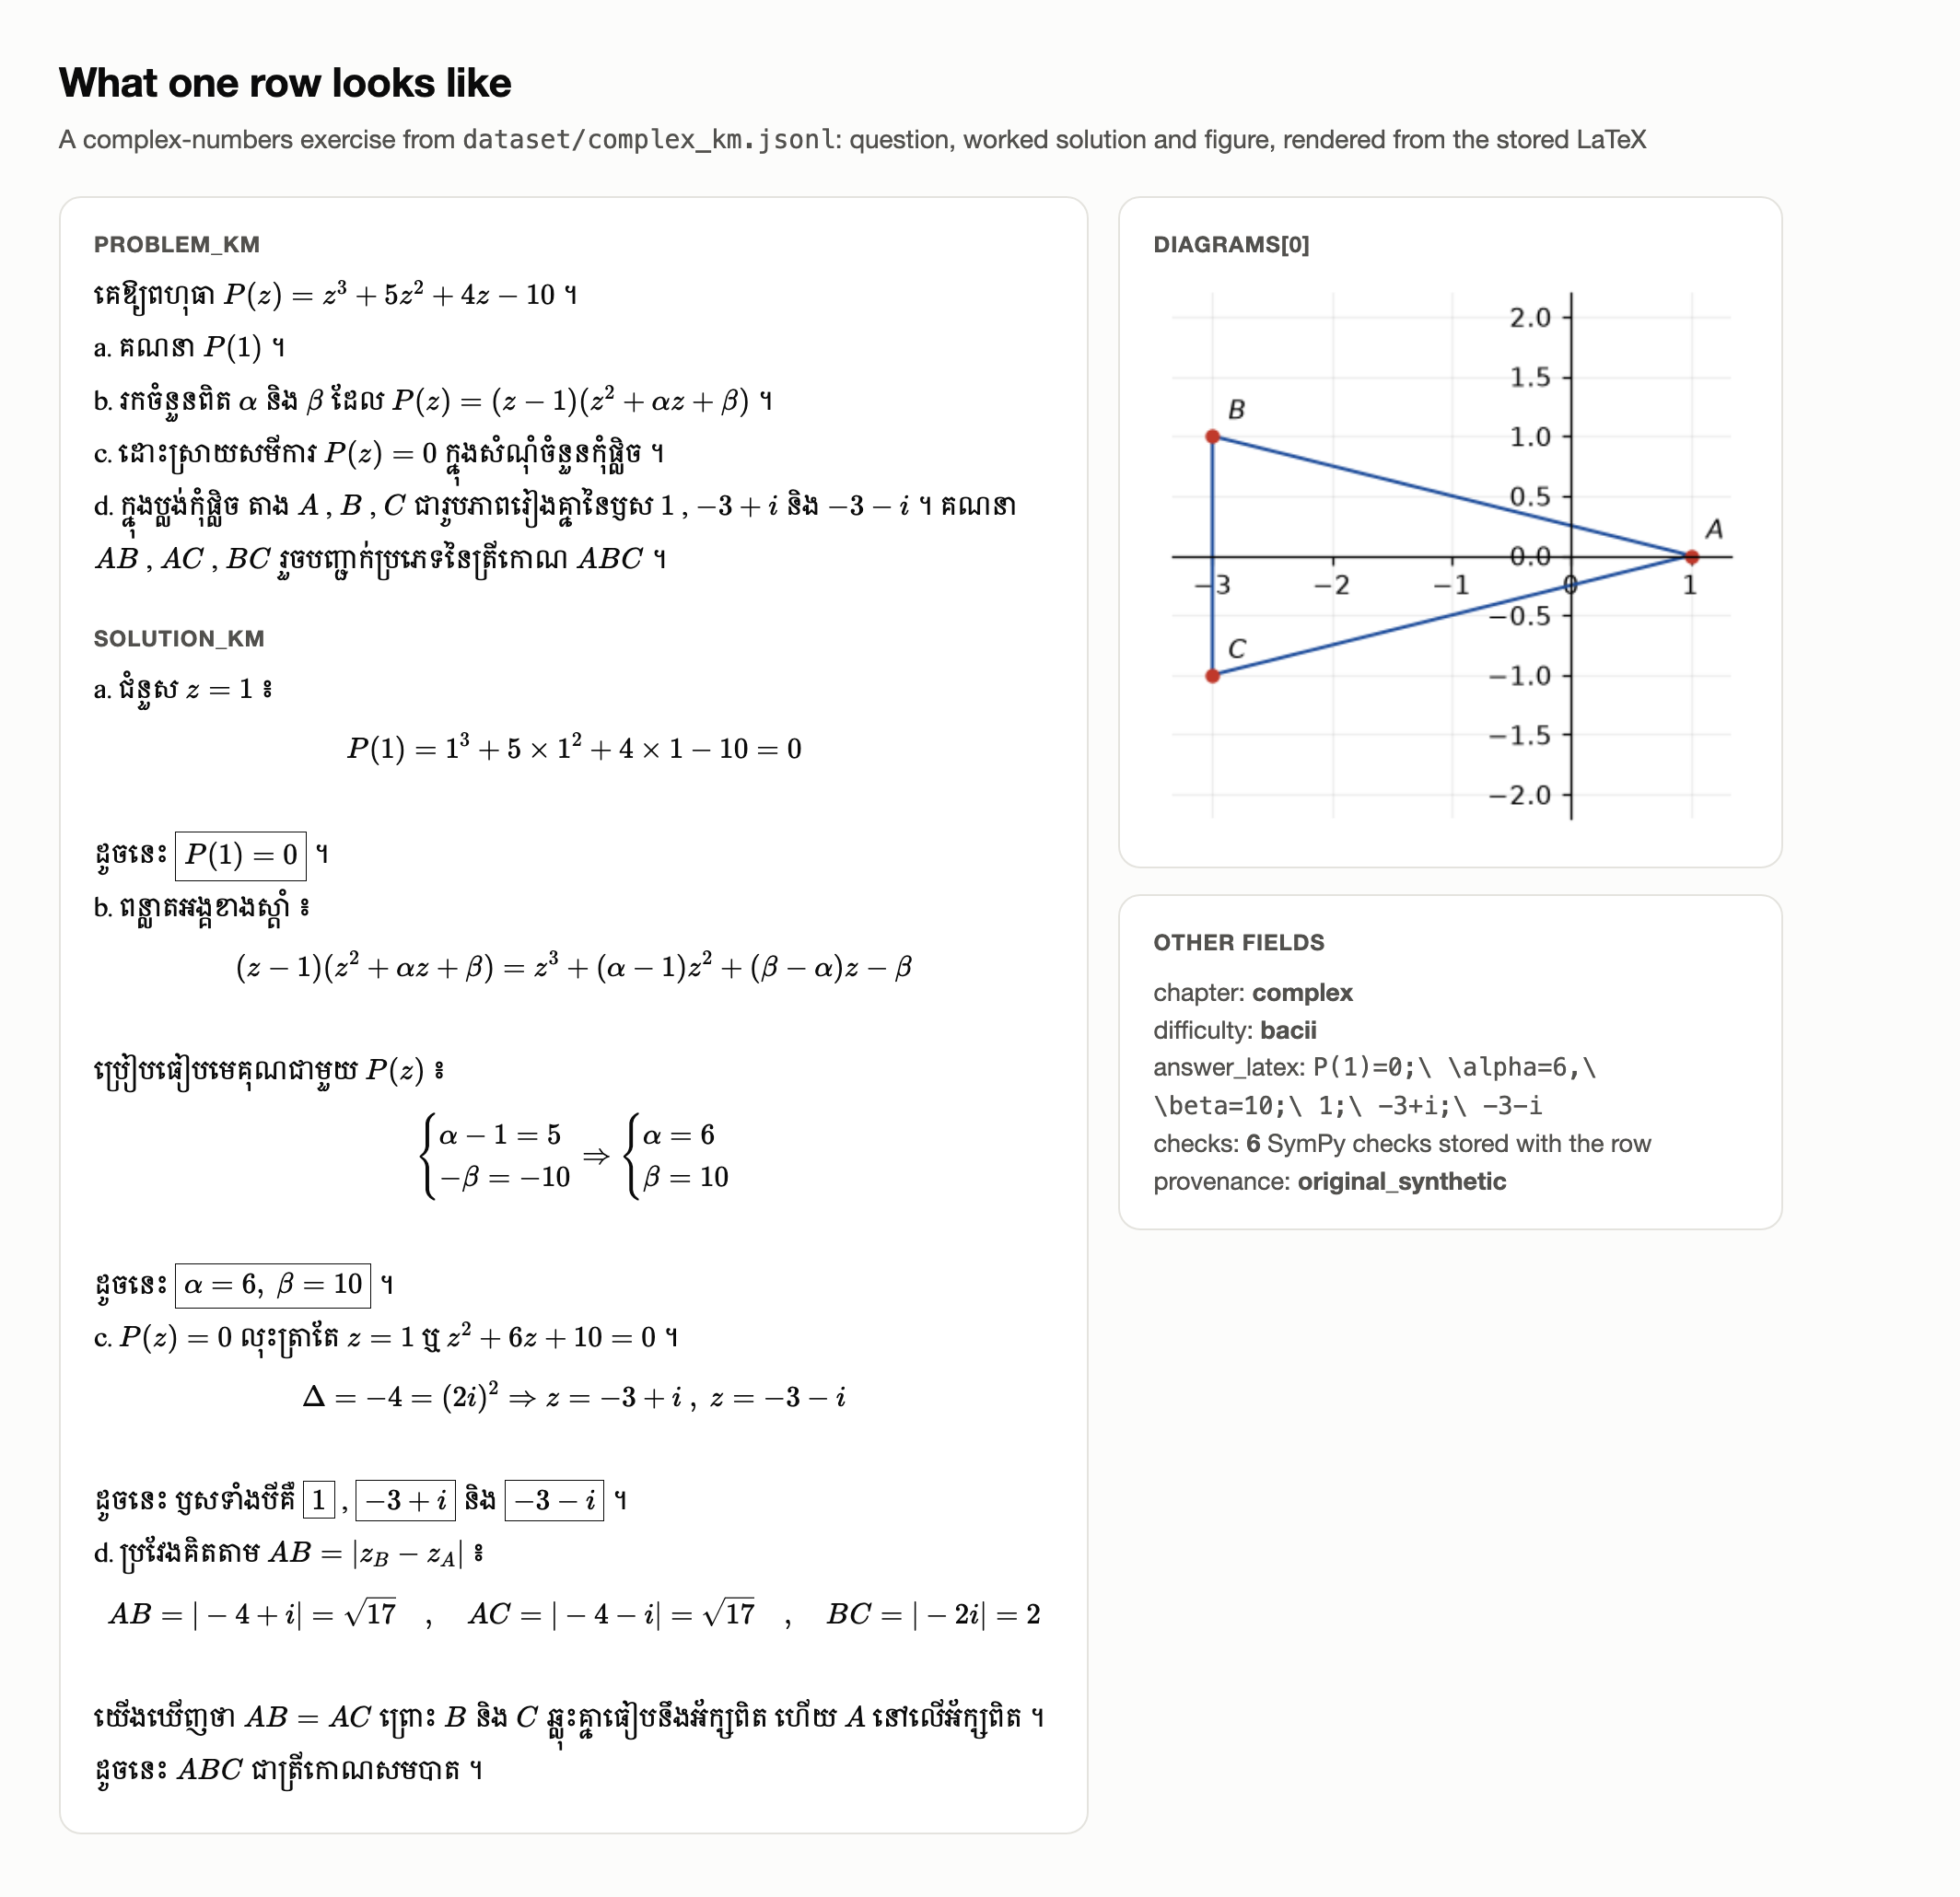
Each row has problem_km, solution_km, answer_latex, chapter, topic, subtopic, difficulty, diagrams, checks, provenance and exam_fit. See SCHEMA.md for the full schema.
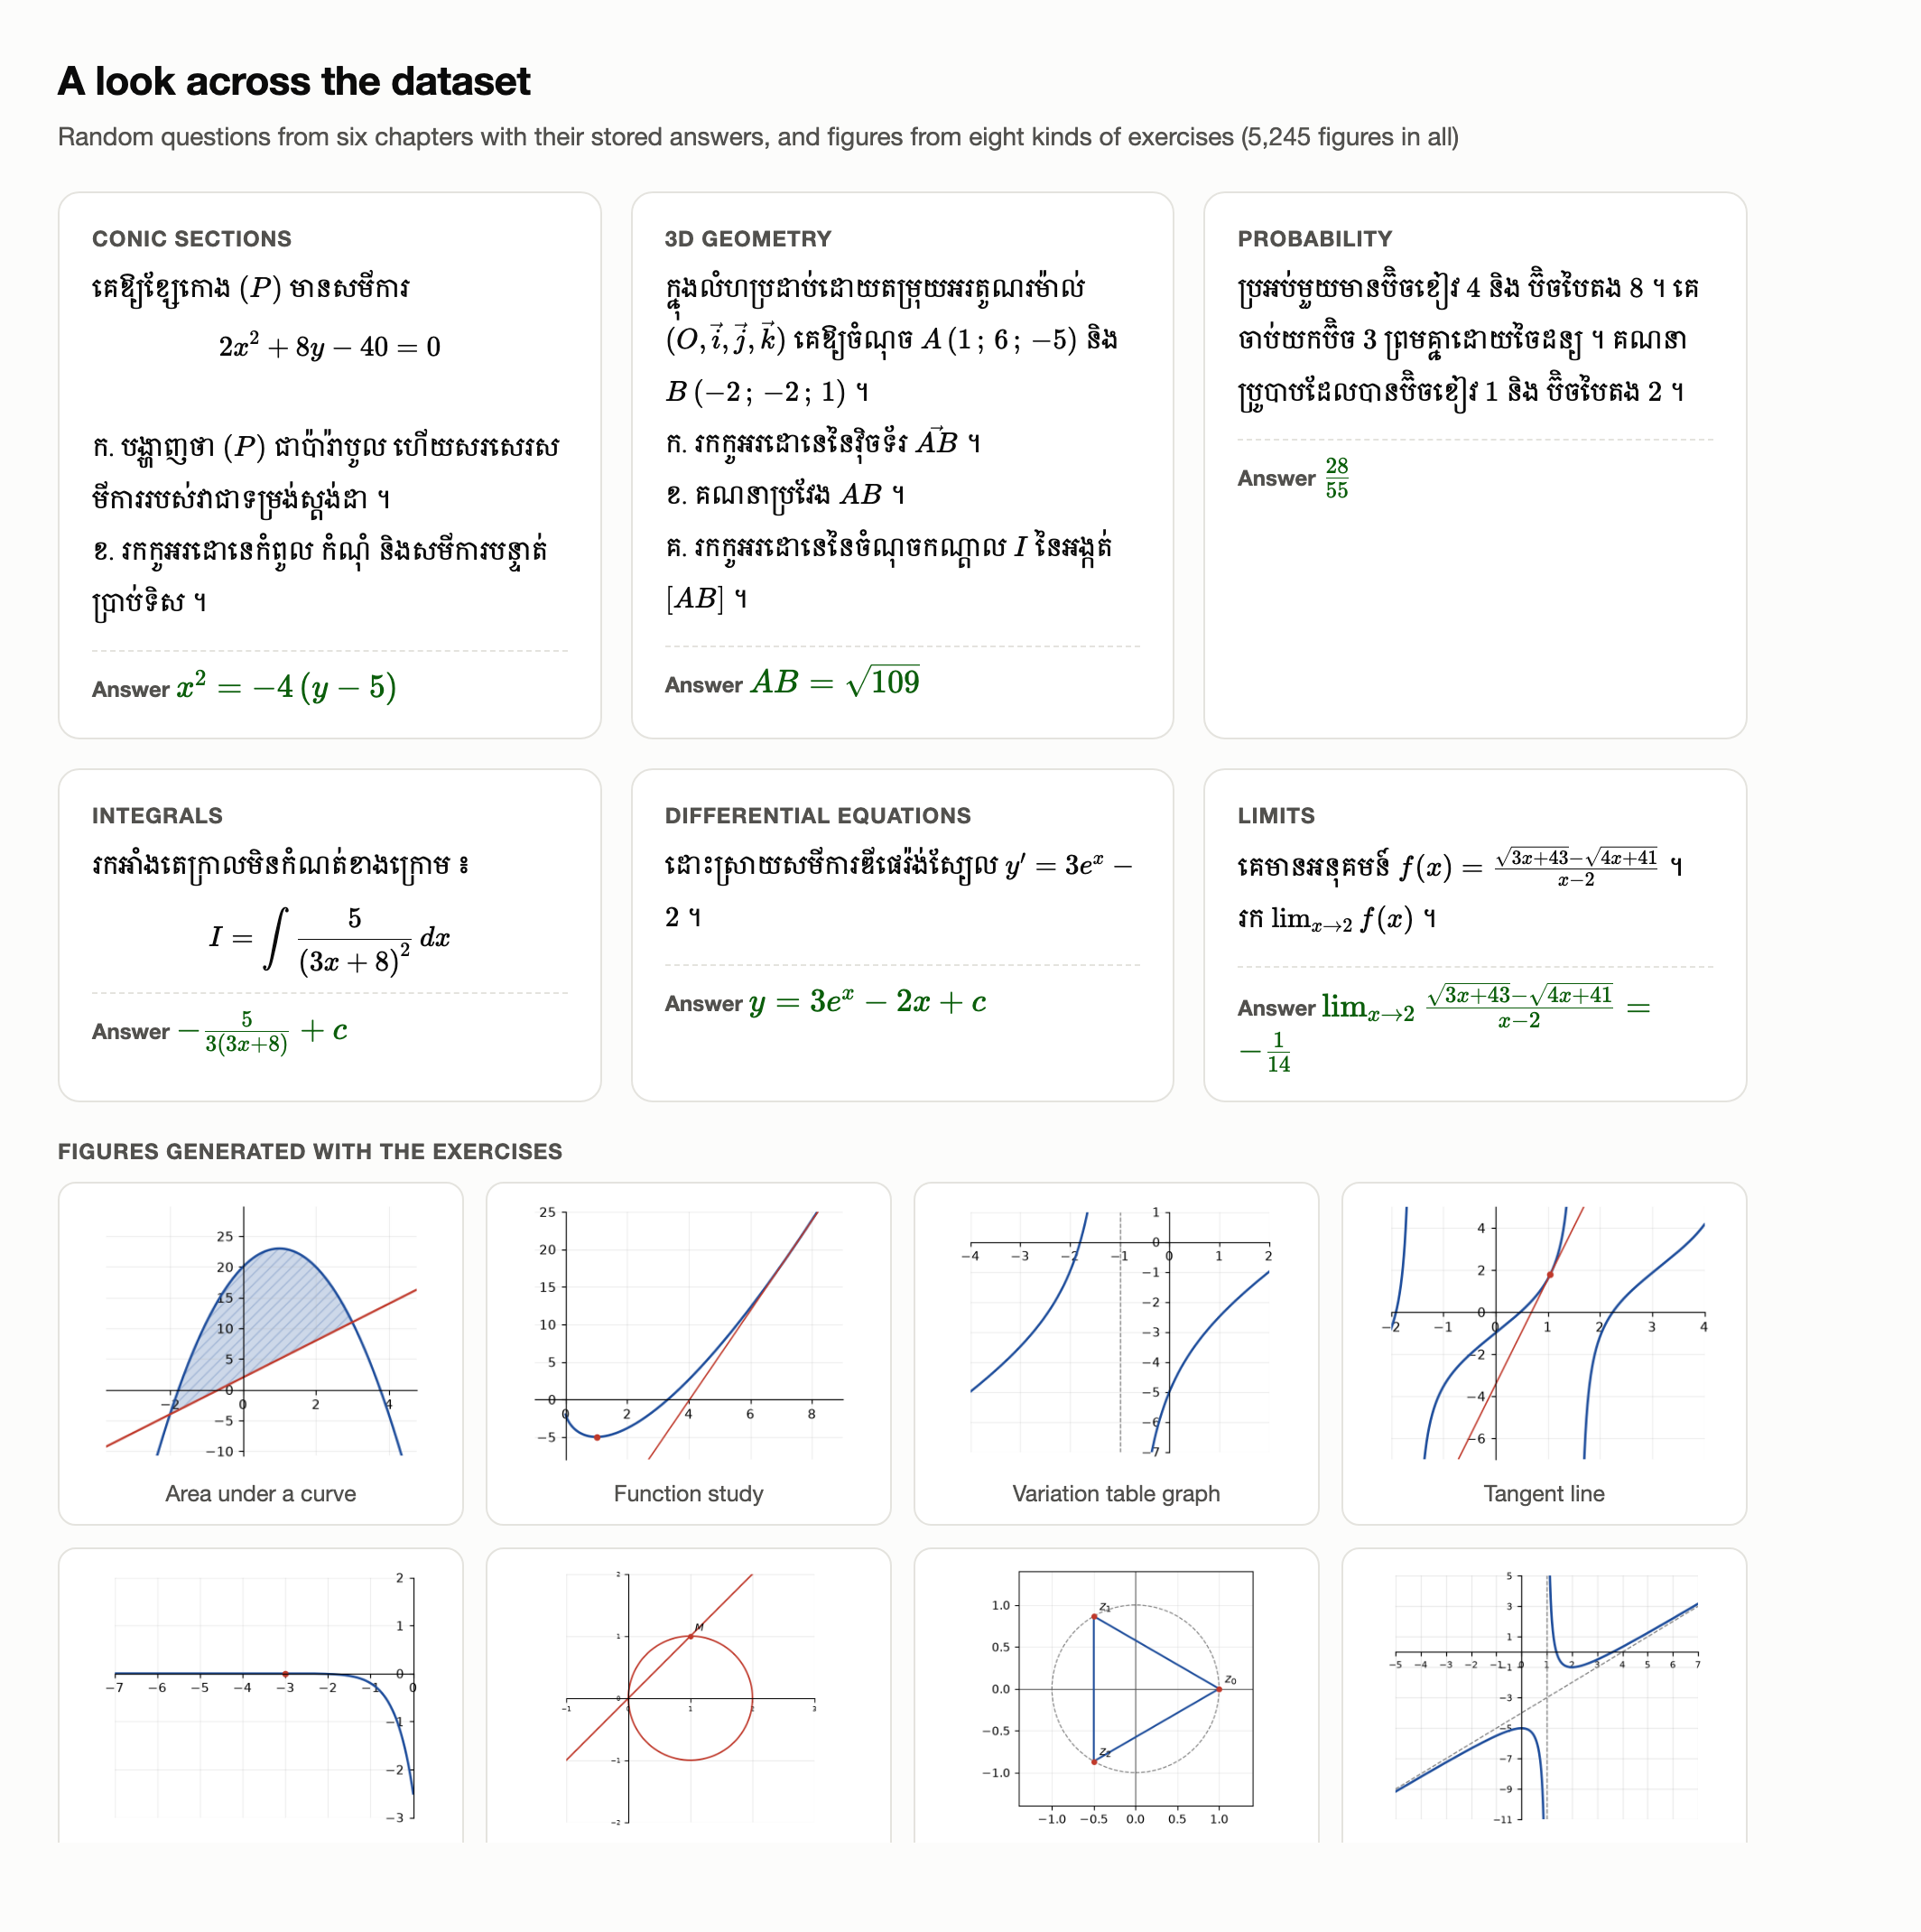
The *_km_chat.jsonl files hold the same rows as user/assistant messages, ready for chat fine-tuning. Some answers there end with TikZ graph code; Run 8 showed it is better to strip it before training (see results below).
Where the rows come from. All rows are original. They were written by the generators in gen/ in the style of BacII papers, and are not real exam items or student scripts. Wording and terms follow the style guides in sources/.
Checks. Key results are recomputed with SymPy, every formula parses in KaTeX, and every row has Khmer prose with no English outside math. Samples were blind-reviewed, and the generators were fixed after each review.
Model adapter (Run 8)
finetune/adapters/run8-step2400-half/ is a LoRA adapter (21 MB) for mlx-community/gemma-3-12b-it-qat-4bit. It was trained on finetune/run8_data/: 2,410 rows from all 8 chapters, with graph code removed.
Training settings: rank 8, last 8 layers, learning rate 3e-5, 2,400 steps, batch 1, max length 2,304, prompt masked. It is used at half strength (scale 10), which is already set in adapter_config.json.
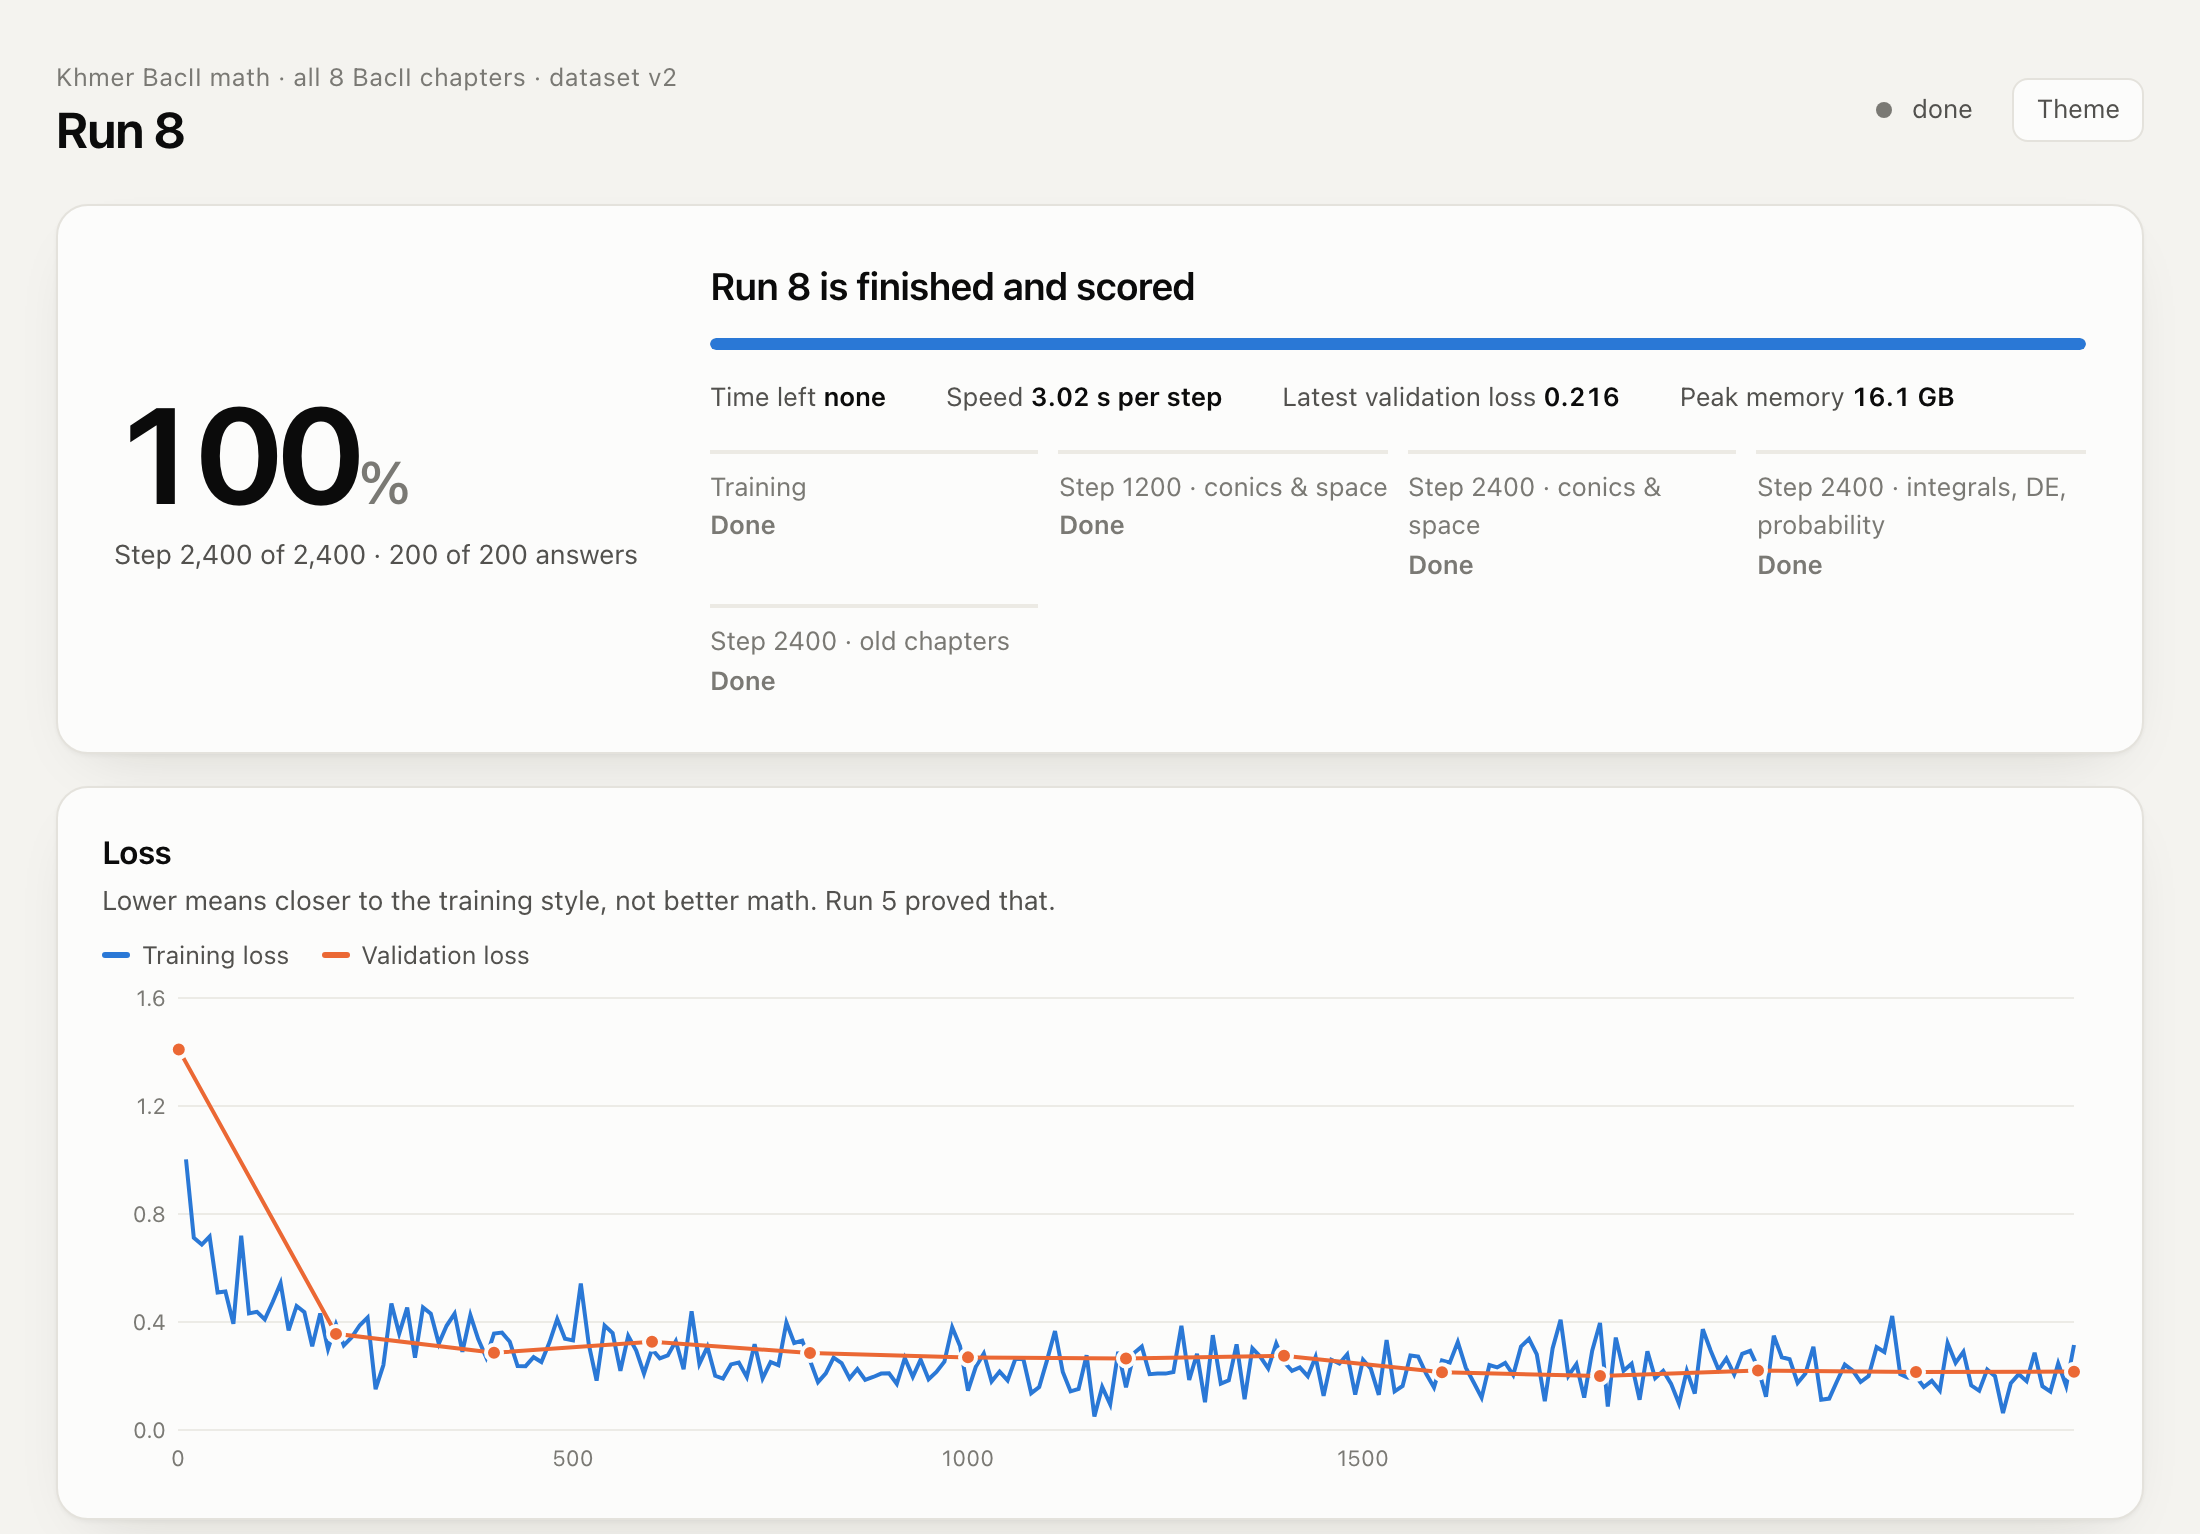
Run 8 trained in about 2 hours on an M1 Max, using 16 GB of memory at peak.
Results (blind-scored)
Graders saw anonymous answers in shuffled order and checked every final answer against the stored answer.
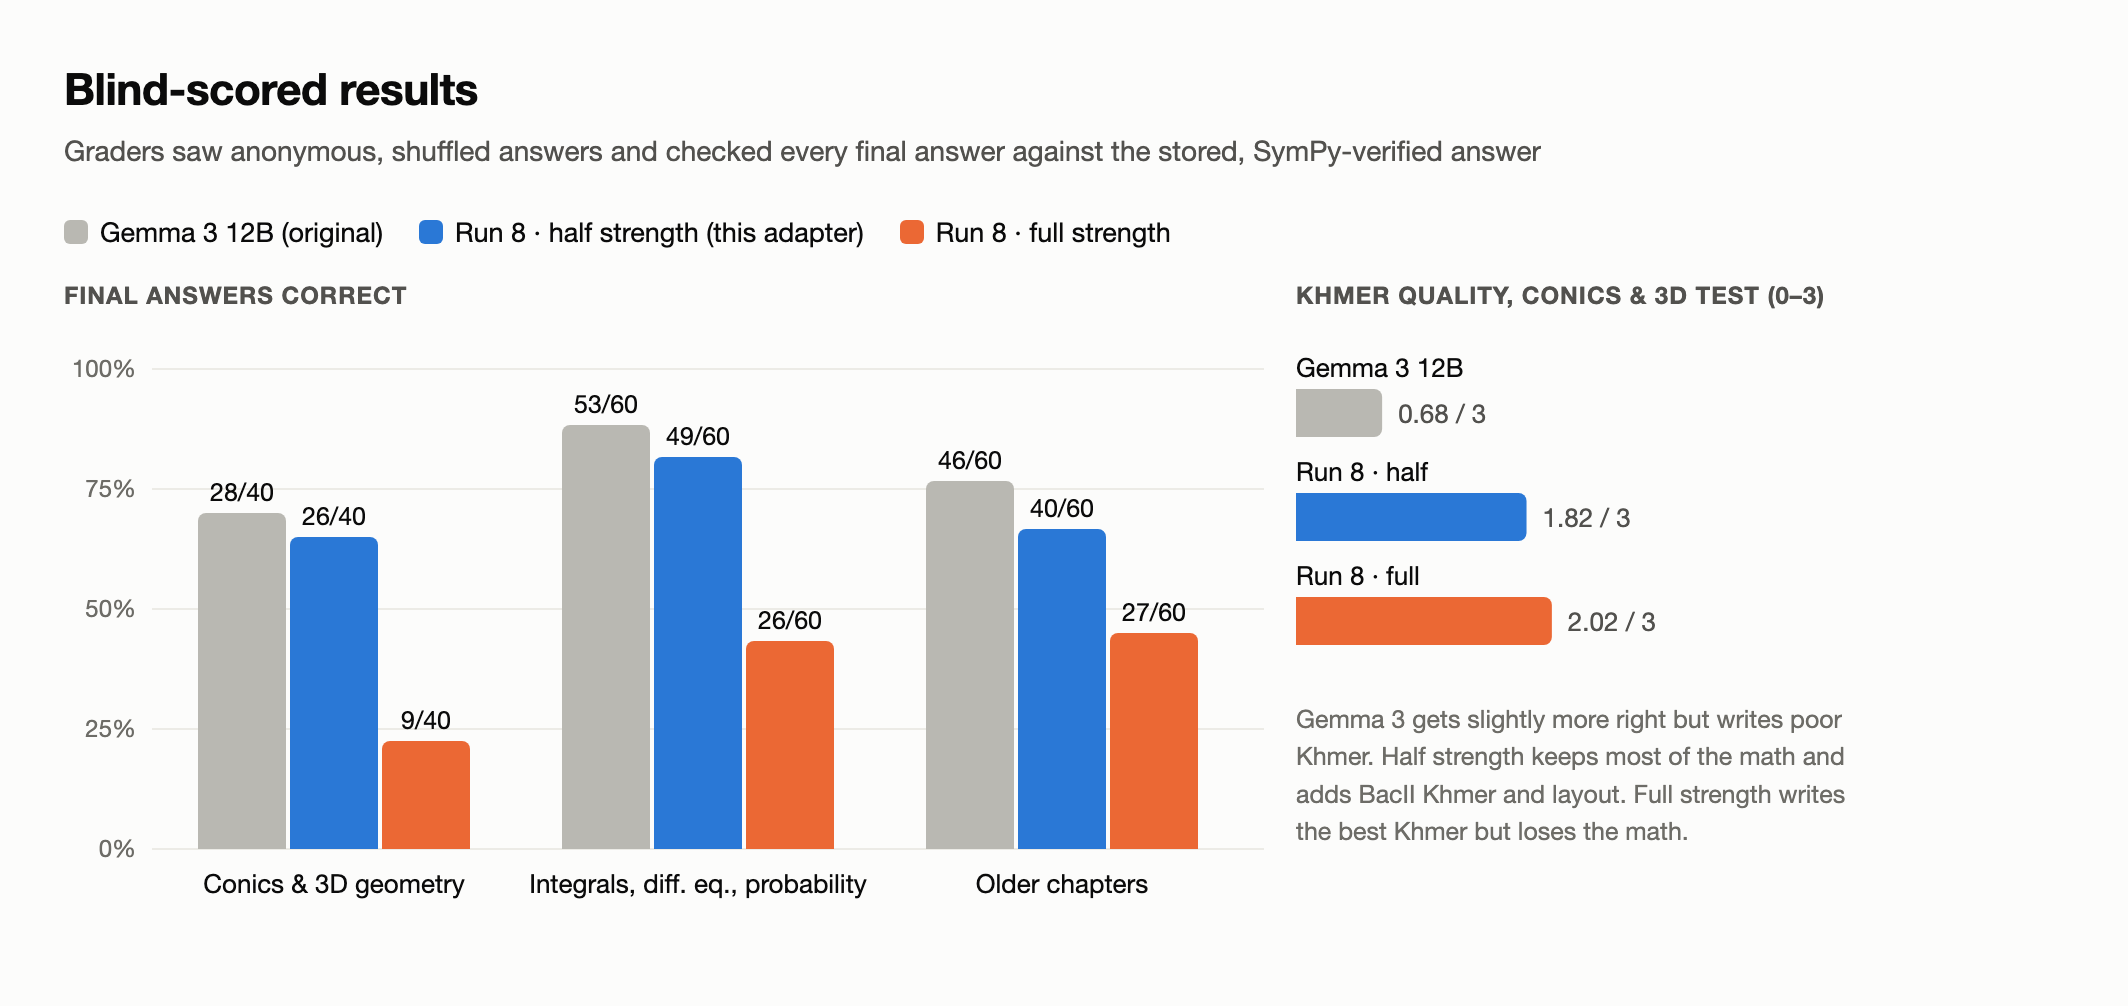
| Test | Gemma 3 12B | Run 8, half (this adapter) | Run 8, full strength |
|---|---|---|---|
| Conics & 3D geometry (40) | 28 | 26 | 9 |
| Integrals, diff. equations, probability (60) | 53 | 49 | 26 |
| Older chapters (60) | 46 | 40 | 27 |
| Khmer quality on conics & 3D (0–3) | 0.7 | 1.8 | 2.0 |
Gemma 3 gets slightly more answers right but writes poor Khmer. The adapter writes much better Khmer and BacII layout. At full strength the Khmer is best but the math falls apart.
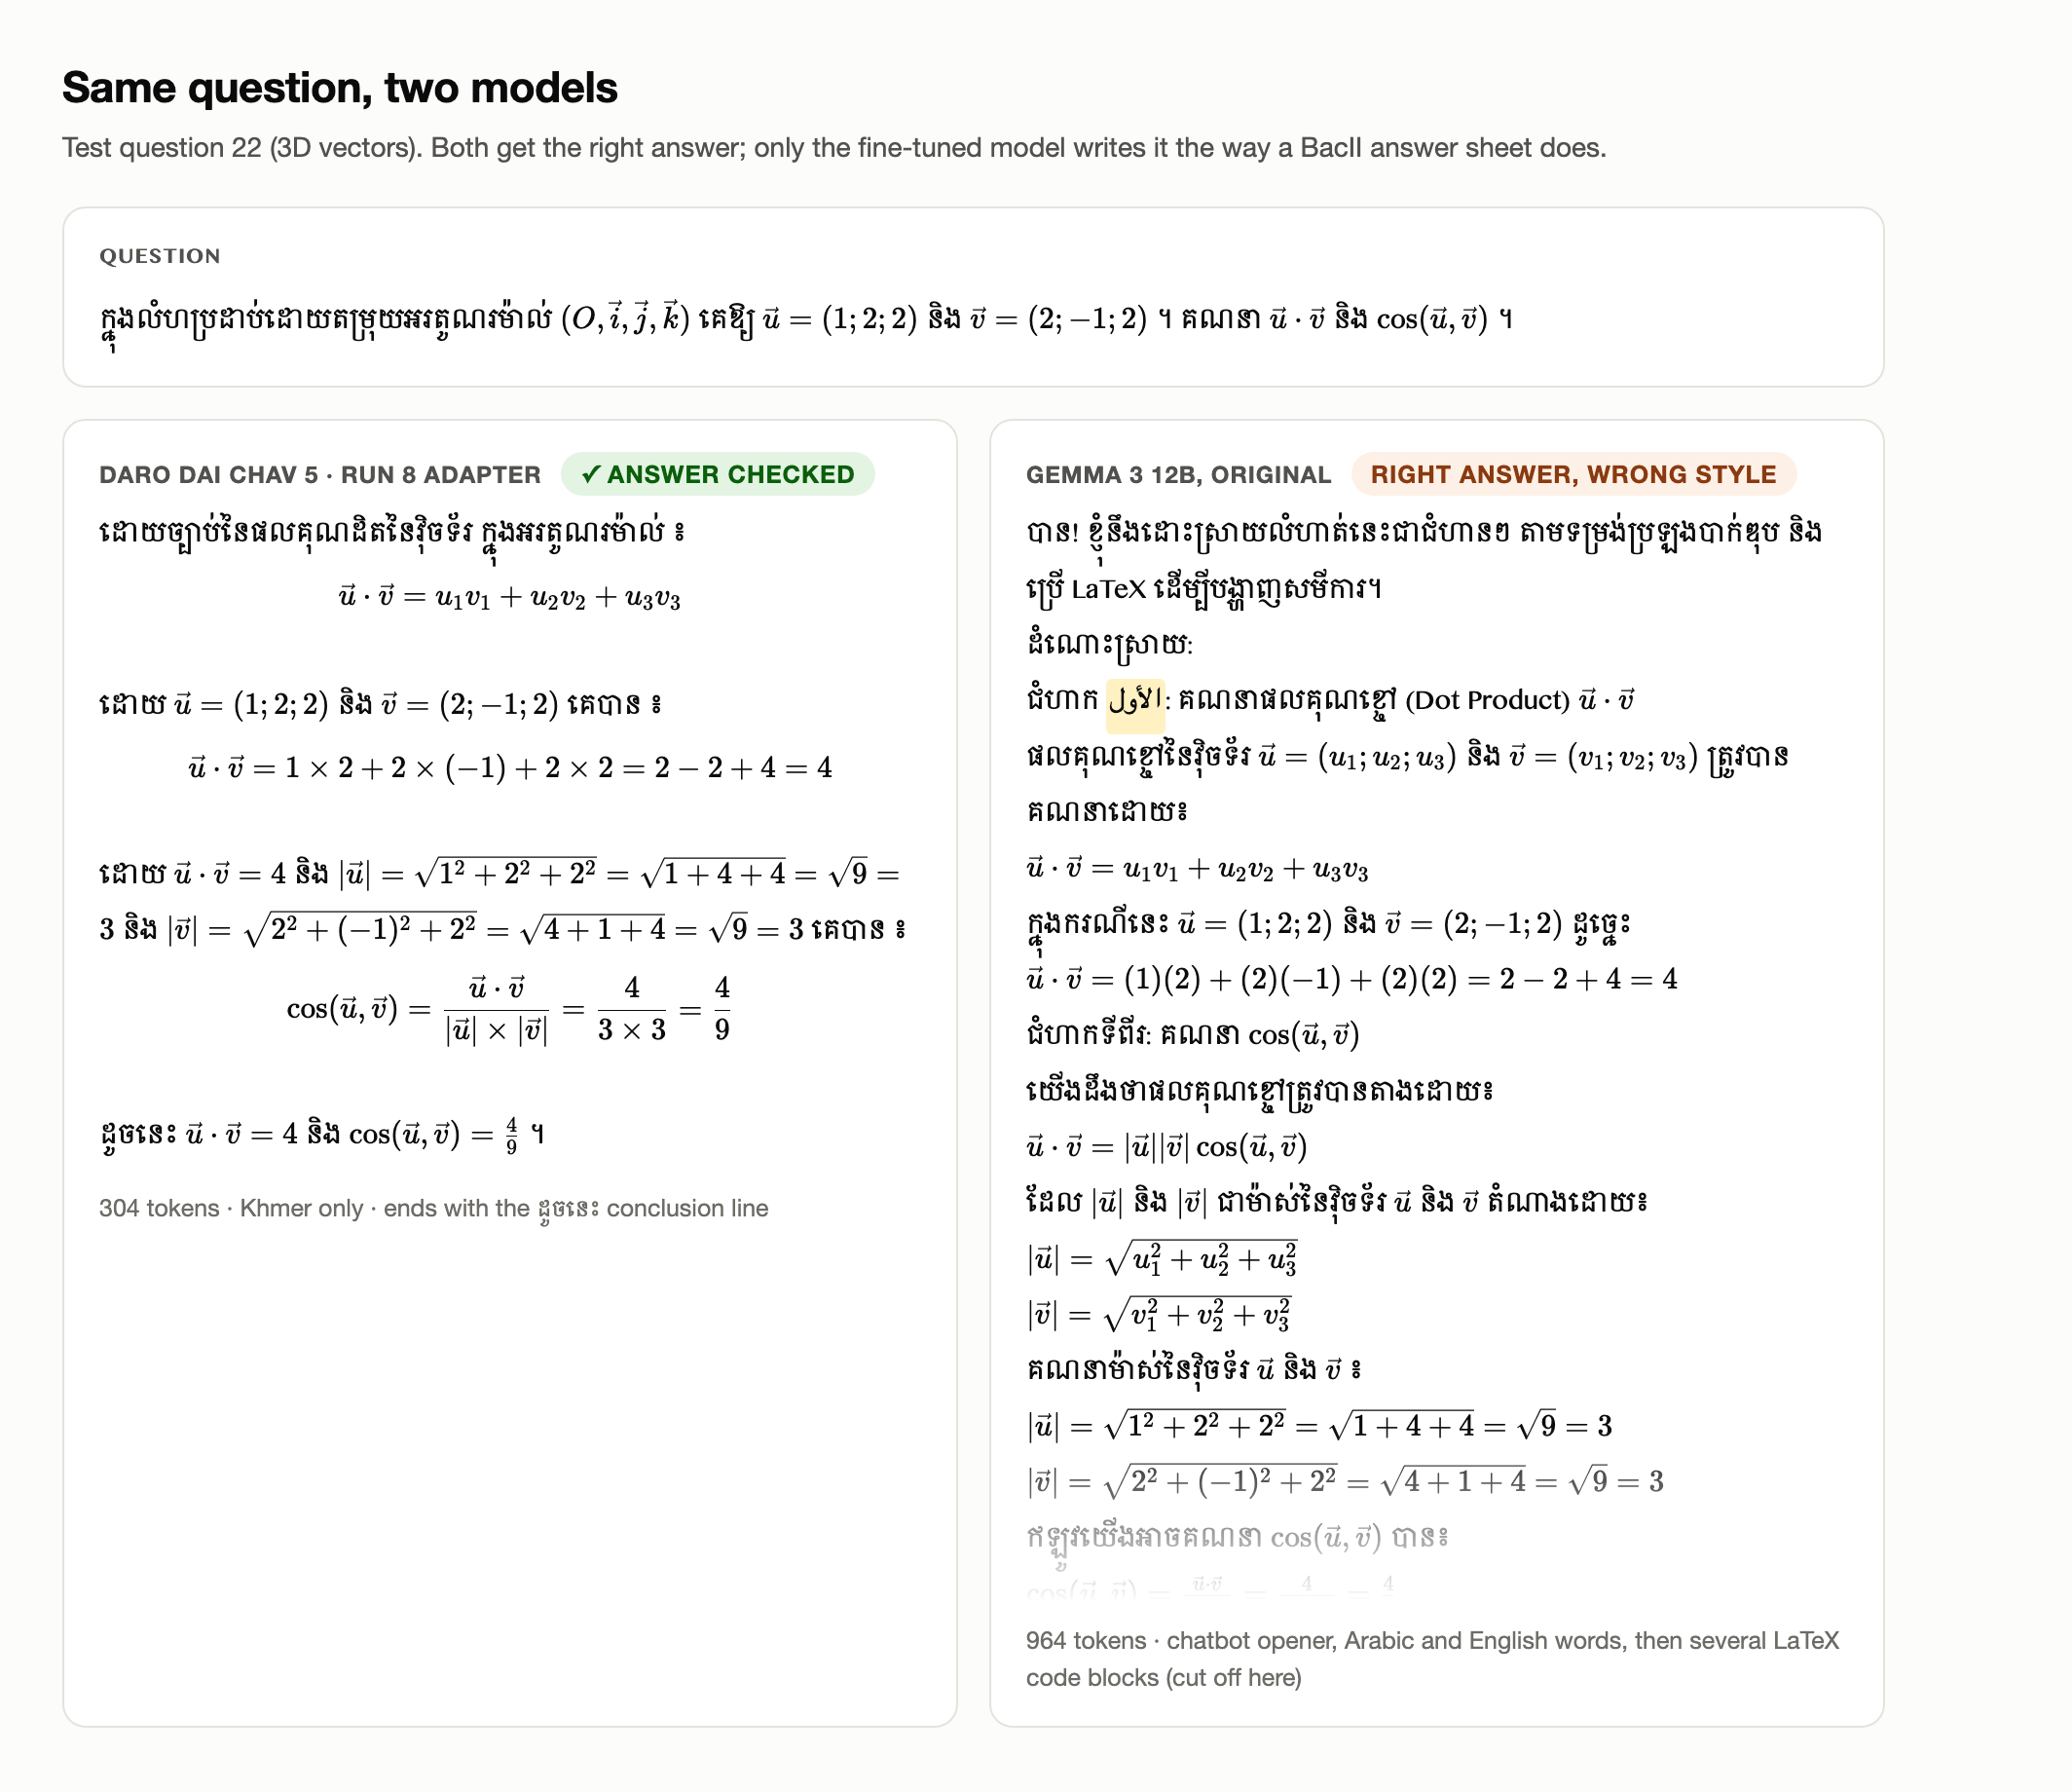
Here is the difference on one test question. Both models get the right answer:
And live in the chat page, on a conics question. The adapter answers correctly in 166 tokens; the original Gemma 3 writes a parabola that opens the wrong way ($y=x^2$), partly in English, and the answer check catches it:
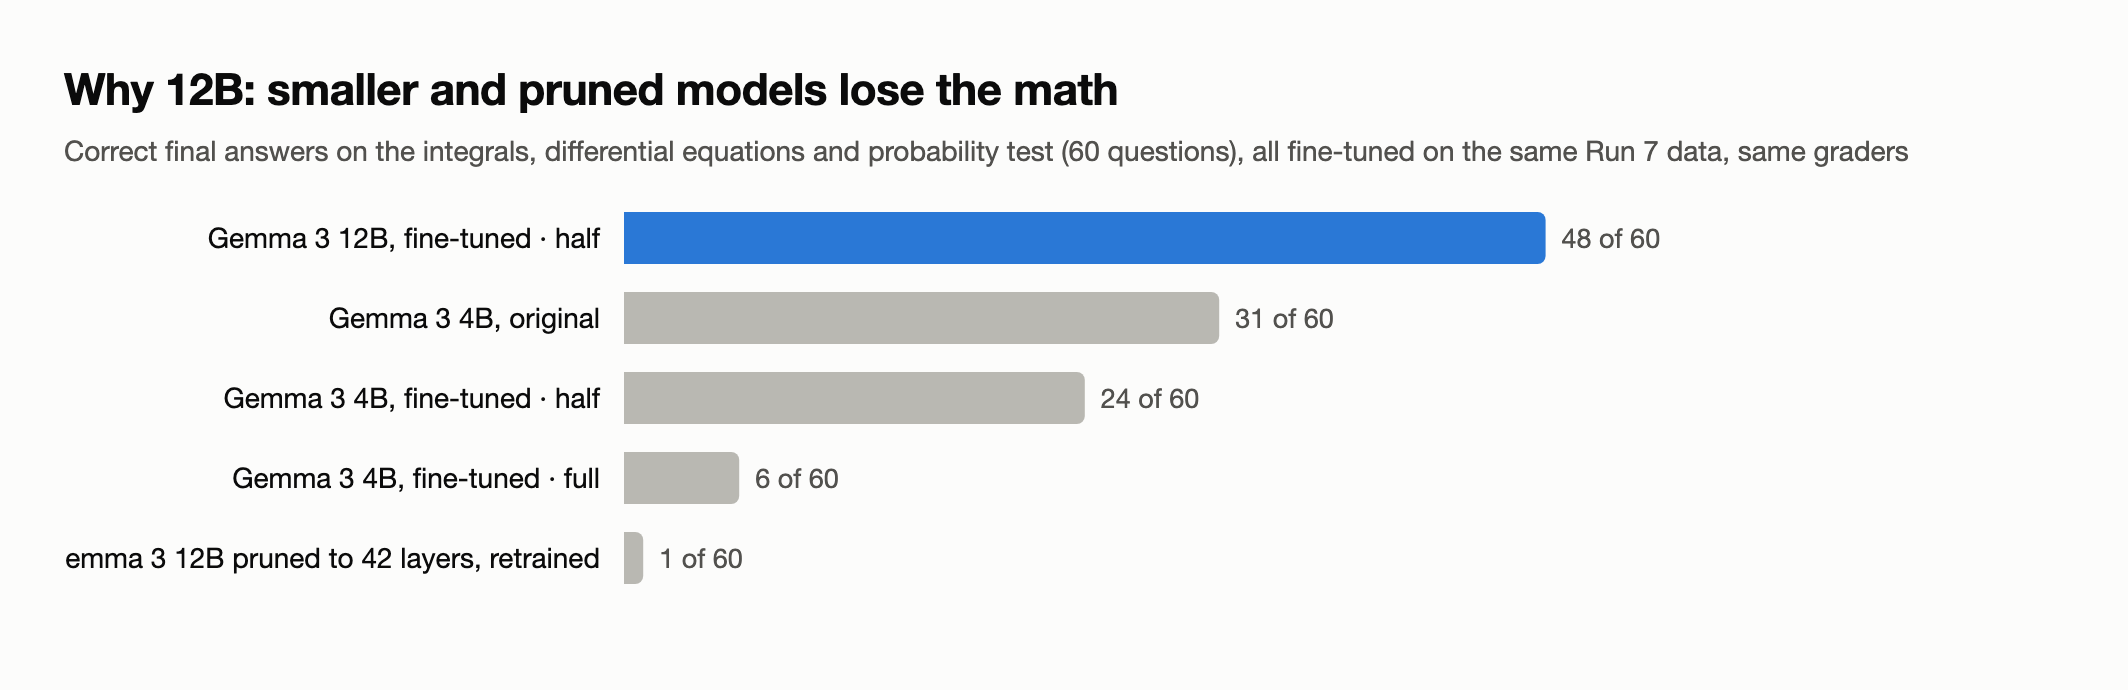
Other things tried, on the same data and graders:
| Tried | Result |
|---|---|
| Gemma 3 4B, fine-tuned | 6–24 of 60 on the integrals test: too small |
| Gemma 3 12B with 6 of 48 layers pruned, then retrained | 0–1 of 60: broken |
| Keeping TikZ graph code in the answers (Run 7) | Same accuracy, but it adds graph code and repeats itself |
Full scores are in finetune/results/.
Known weaknesses
- "Are these four points in one plane?" questions: 5 of 8 wrong.
- Building a conic from given facts, for example from its foci and eccentricity.
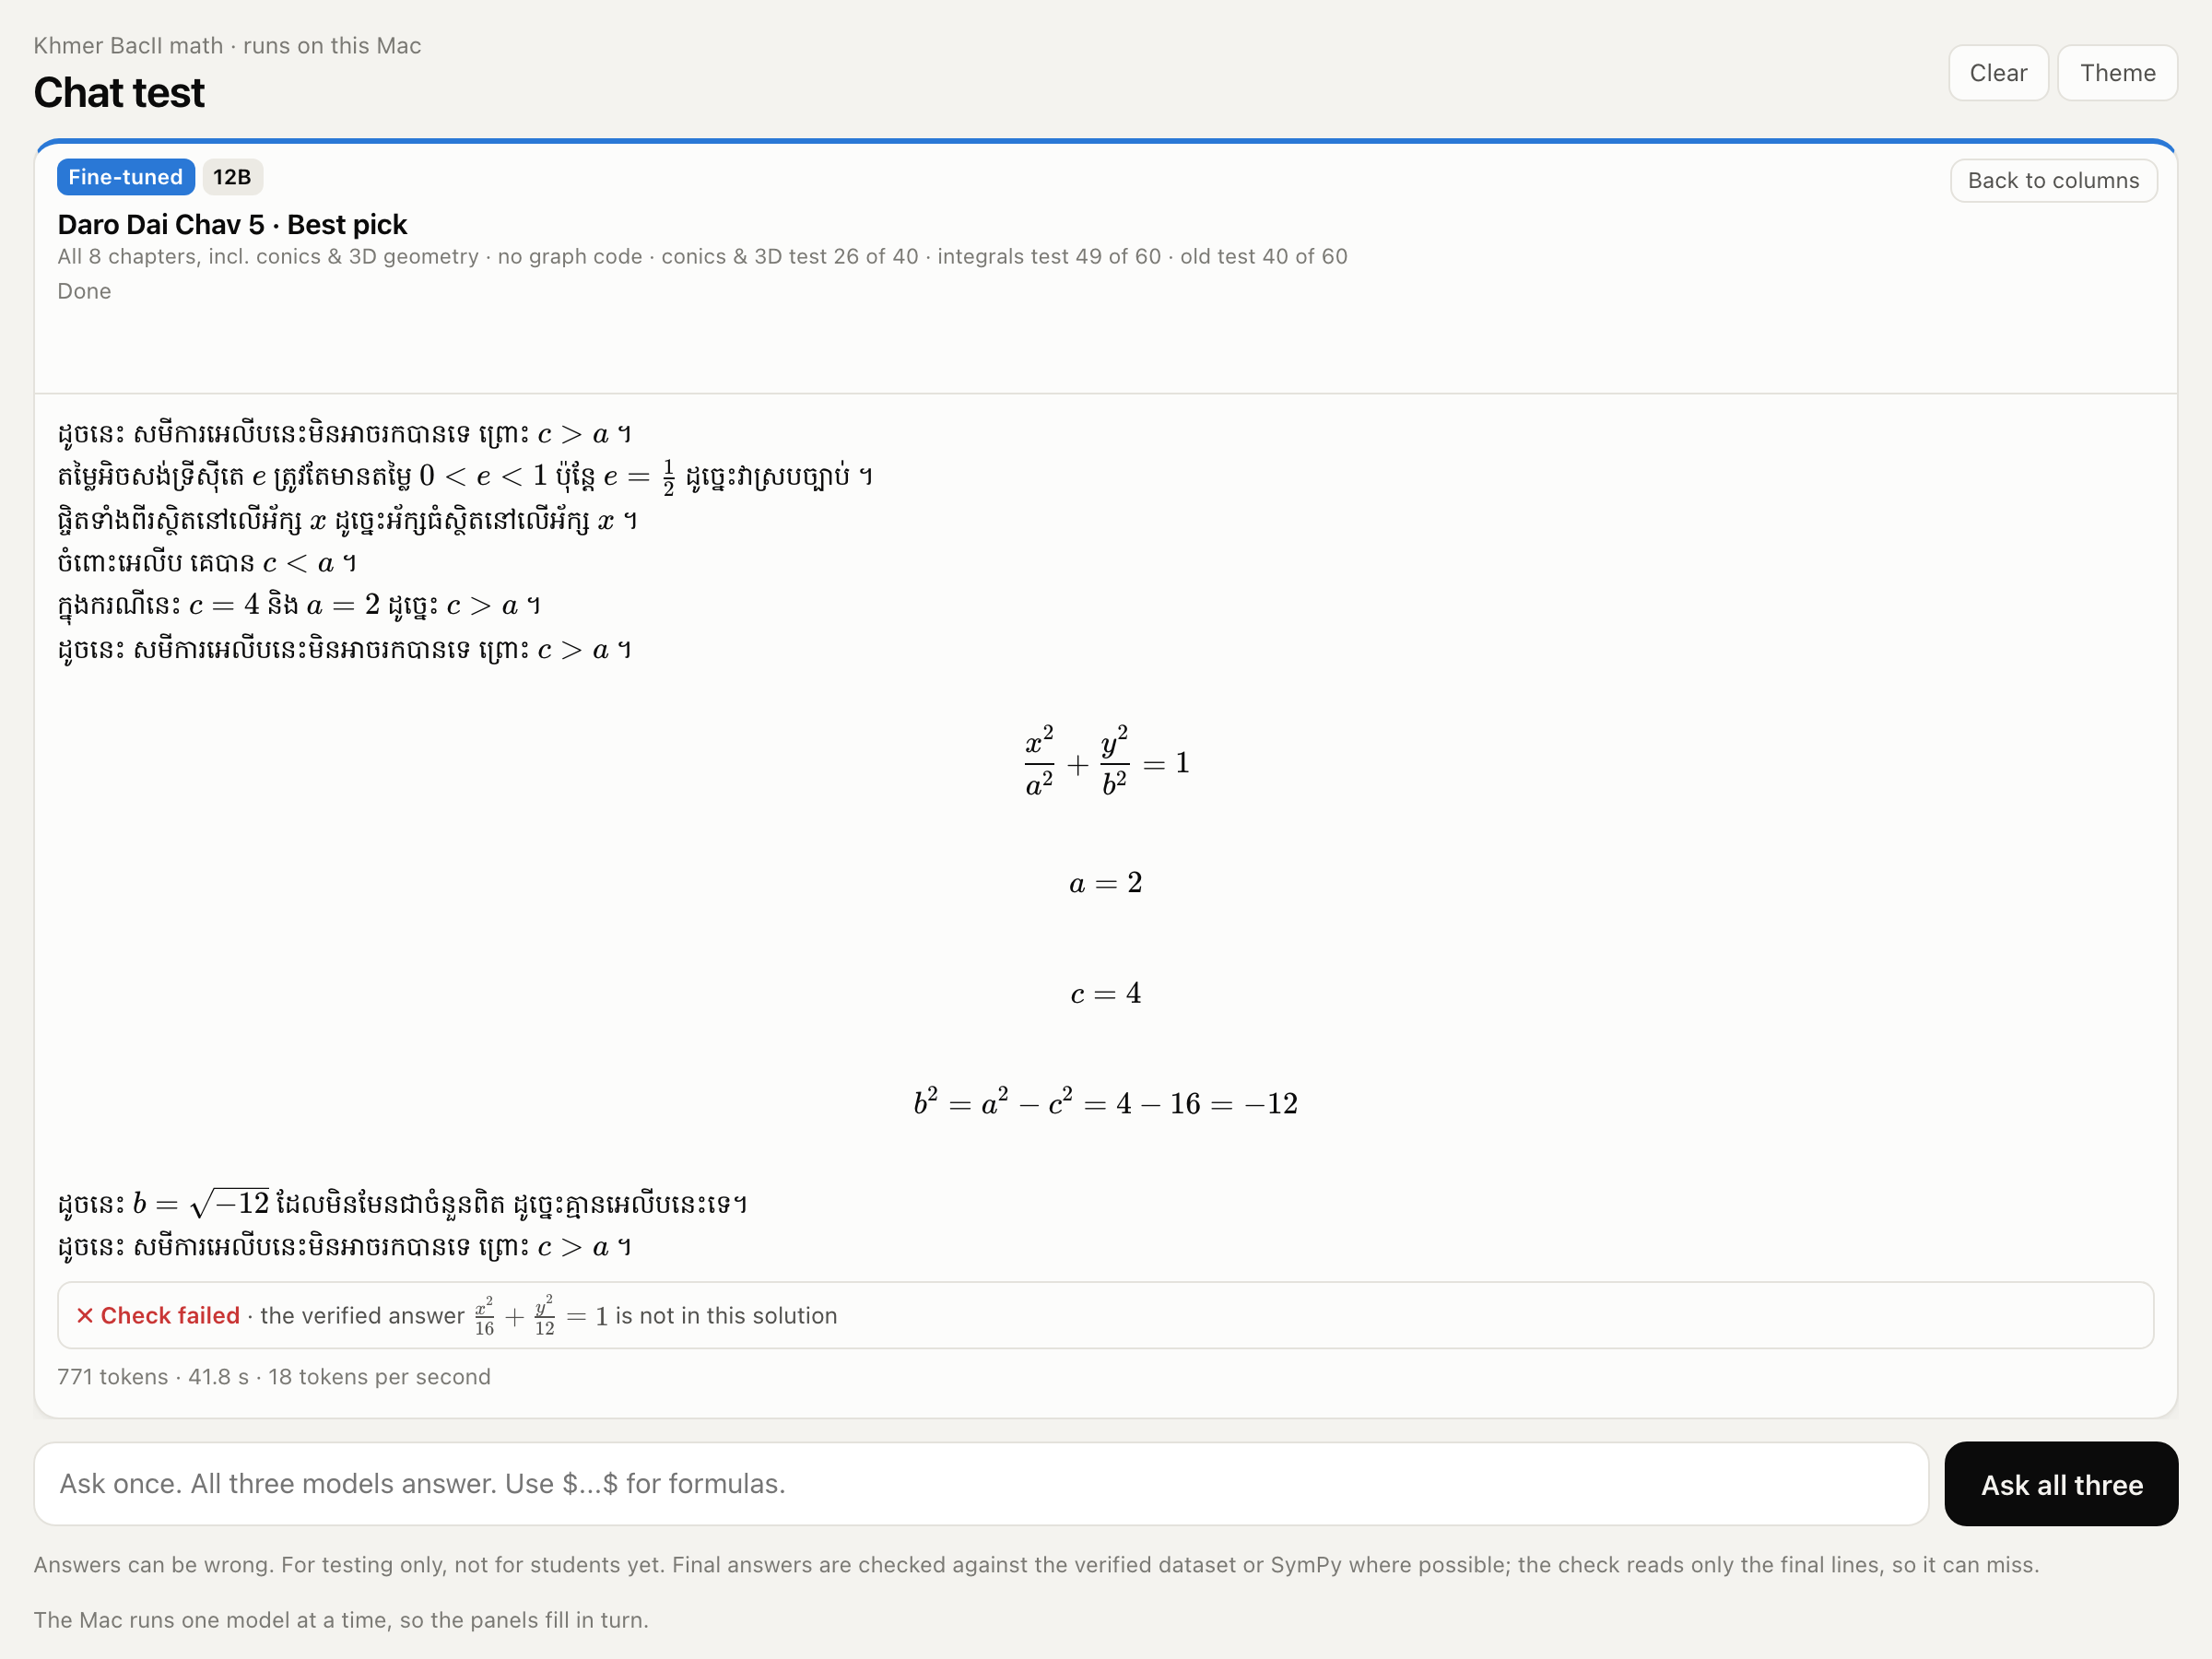
- It sometimes repeats its working in a second math block, adds English words, or invents Khmer terms.
Here is a real failure. Asked for an ellipse with foci $(\pm2;0)$ and $e=\frac12$, the model takes the distance between the foci as the major axis, mixes up $a$ and $c$, decides no ellipse exists, and repeats itself. The answer check flags it with the correct answer:
Quick start (Apple silicon Mac, 32 GB+ memory)
python3 -m venv .venv && source .venv/bin/activate
pip install -r requirements.txt
Chat with the model. This downloads Gemma 3 12B (about 8 GB) on first run, then open http://localhost:8800/chat.html.
python3 finetune/chat_server.py
Under each answer, the page shows whether the final answer matches the dataset or SymPy. The check reads only the final lines, so it can miss.
Run the tests:
python3 finetune/run_test60c.py mlx-community/gemma-3-12b-it-qat-4bit finetune/adapters/run8-step2400-half run8
run_test60b.py and run_test60.py work the same way. Results go to finetune/results_test60*/.
Train your own adapter:
python3 finetune/train_lora.py 1 --model mlx-community/gemma-3-12b-it-qat-4bit --train --data finetune/run8_data \
  --adapter-path finetune/adapters/my-run --num-layers 8 --batch-size 1 --iters 2400 --max-seq-length 2304 \
  --mask-prompt --learning-rate 3e-5 --steps-per-report 10 --steps-per-eval 200 --val-batches 30 --save-every 400
This takes about 2 hours on an M1 Max. Then copy adapter_config.json and set "scale": 10.0 to use it at half strength.
Use the answer check in your own code:
import sys; sys.path.insert(0, "lib")
from answer_check import check
check(question_text, model_answer)   # {"status": "match|partial|mismatch|unchecked", "source": ..., "expected": ...}
Layout
| Folder | What it holds |
|---|---|
dataset/ |
The data, the chat page (chat.html) and its KaTeX files |
gen/ |
Generators; gen/steps/ builds the step-by-step solutions |
lib/ |
Checks (SymPy, KaTeX, steps), merge and split tools, the answer check |
finetune/ |
Training, tests, chat server, test sets, Run 8 data and adapter, blind scores |
sources/ |
Khmer style guides and terms |
Licences
- Code: MIT (
LICENSE). - Data and style guides: CC BY 4.0 (
LICENSE-DATA.md). - Model adapter: Gemma Terms of Use (
NOTICE-GEMMA.md). Gemma itself is not included.