
Briella009/BGNexa-AI
Briella009/BGNexa-AI has 35 GitHub stars and 23 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-11 17:49 UTC. Last push 2026-10-27.
BGNexa AI — Evidence intelligence for cybersecurity, privacy and regulatory readiness.
Measured star growth
- in 24h
- 0
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalBGNexa AI
Turn evidence into readiness — and readiness into assurance work.




Try the live beta · Run locally · Releases · Architecture · Accuracy policy · Contributing
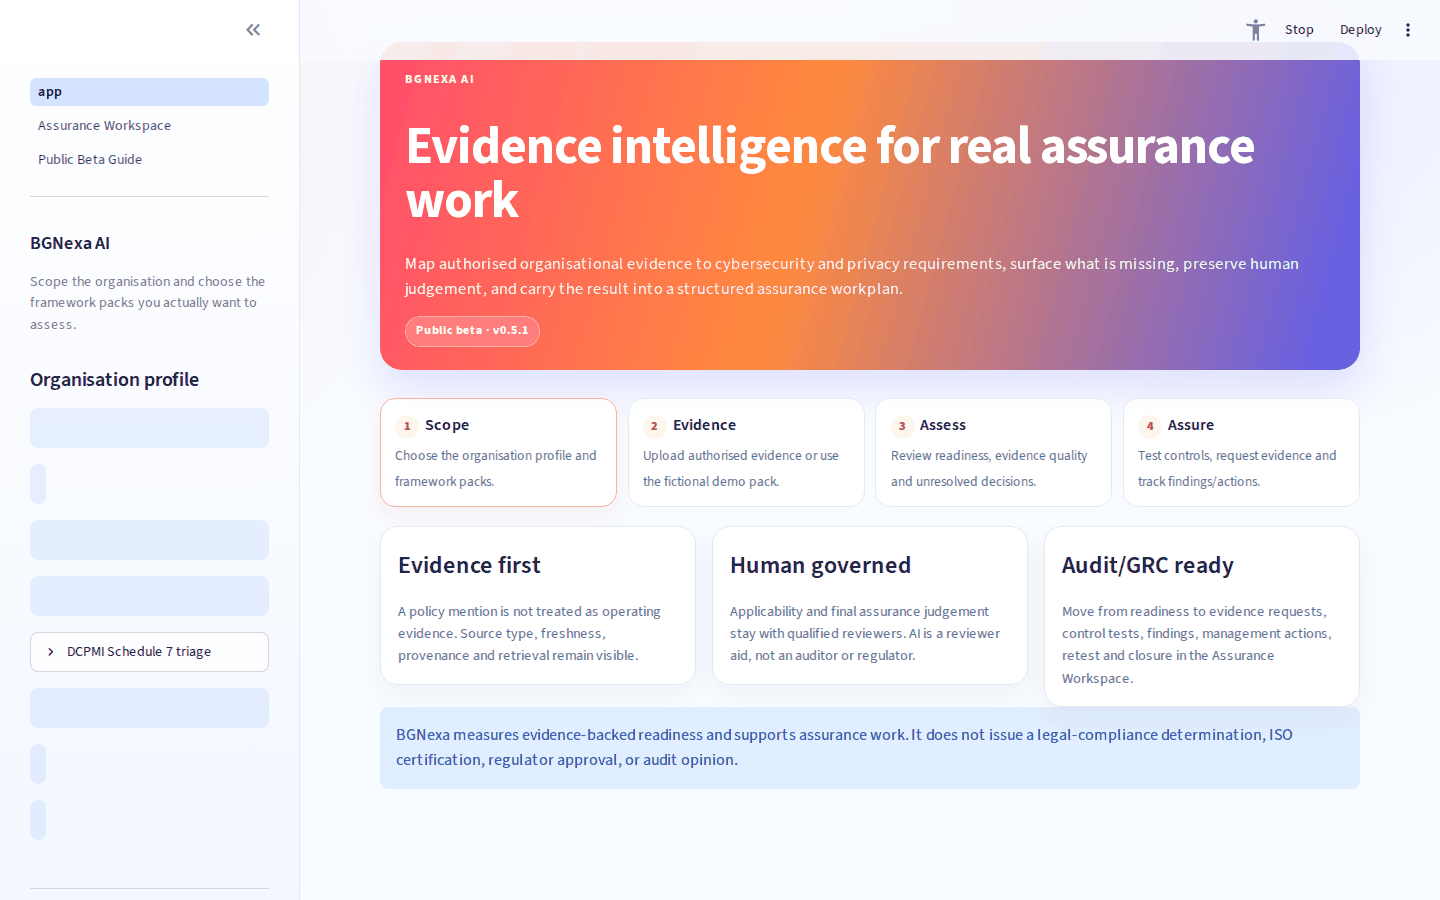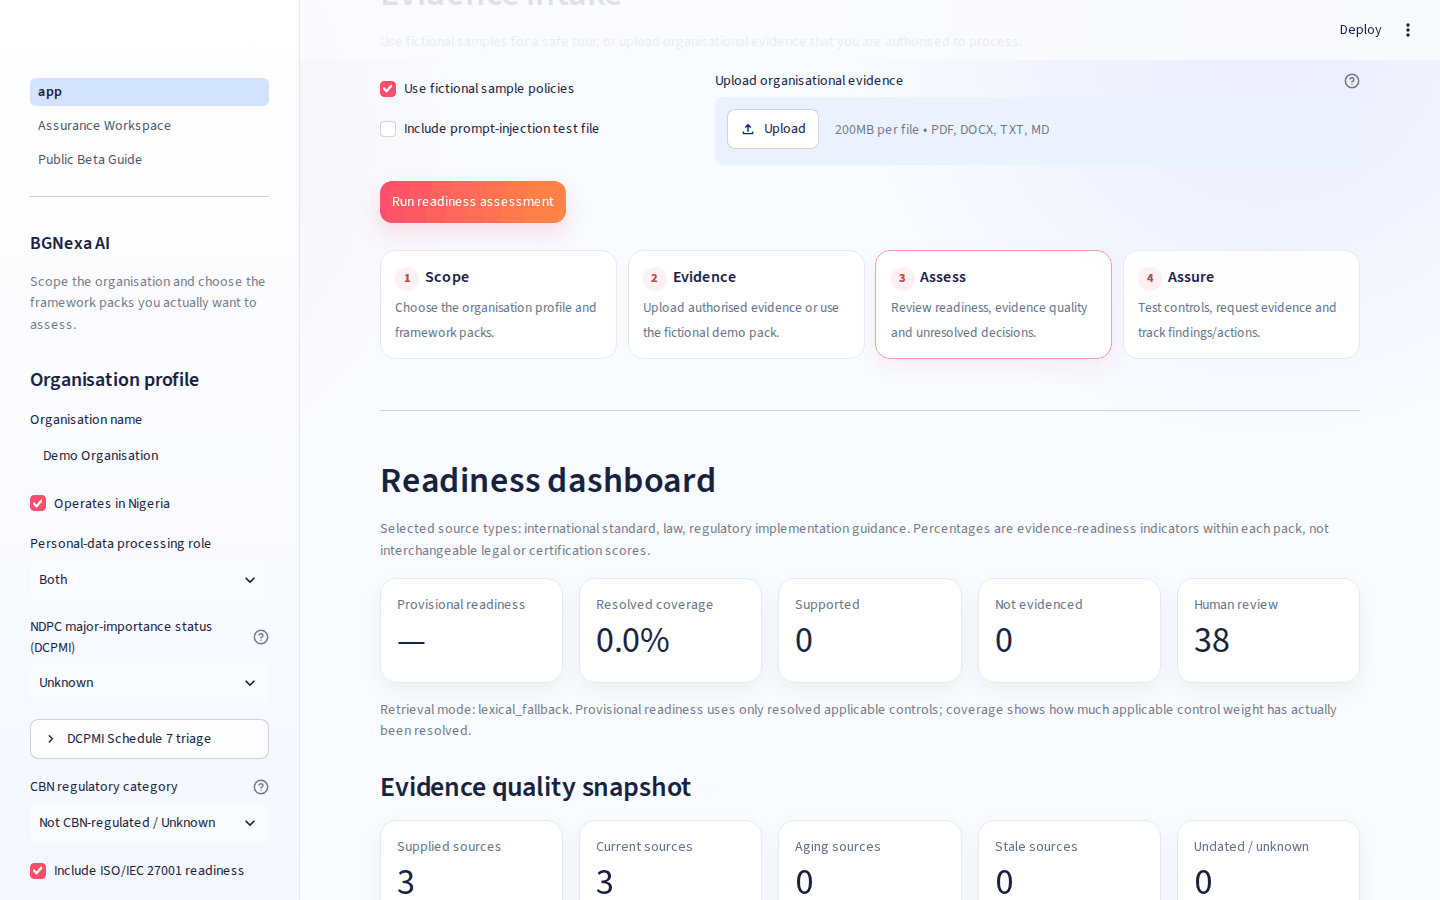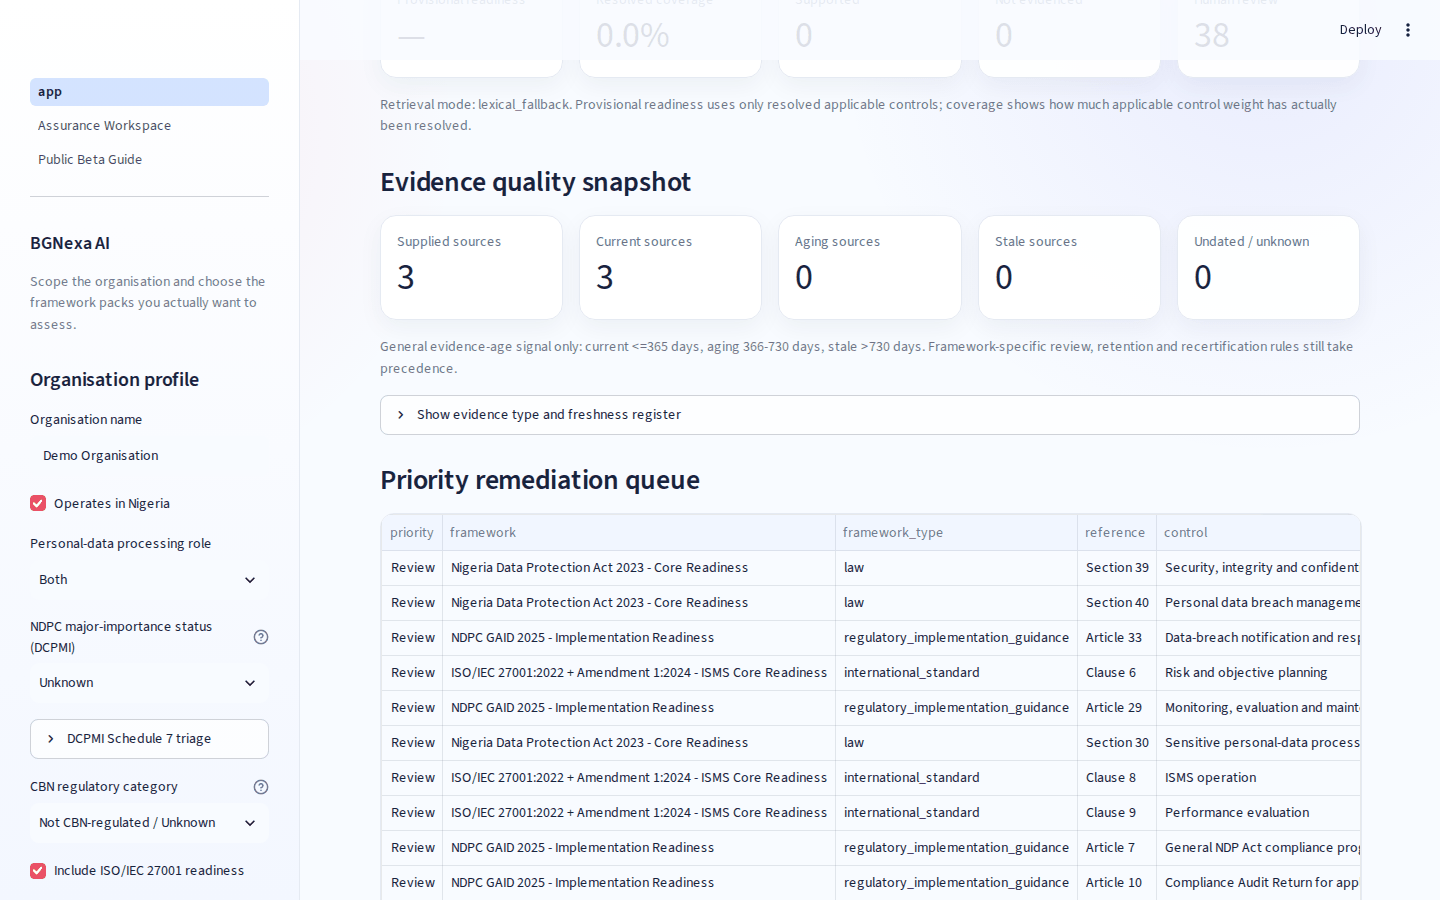
Real v0.5.1 public-beta UI captured from the repository app using fictional sample policies.
BGNexa AI is an open-source, source-traceable evidence intelligence and assurance workspace for cybersecurity, privacy and regulatory readiness. It is designed for GRC teams, internal auditors, cybersecurity assurance teams, privacy teams and control owners who need to move from uploaded evidence to a defensible review trail.
Current development release: v0.5.1
Important: BGNexa reports evidence-backed readiness and supports assurance workflows. It does not determine legal compliance, issue an audit opinion, certify ISO/IEC 27001 conformity, provide regulator approval, or replace qualified legal, privacy, cybersecurity, regulatory or audit judgement.
Try BGNexa in 2 minutes
BGNexa can run without an API key in deterministic retrieval/manual-review mode.
git clone https://github.com/Briella009/BGNexa-AI.git
cd BGNexa-AI
python -m venv .venv
source .venv/bin/activate  # Windows: .venv\Scripts\activate
pip install -r requirements.txt
streamlit run app.py
Start with non-sensitive sample/demo evidence. The public-beta code is not a production multi-tenant evidence platform.
If BGNexa solves a problem you care about, star it to follow releases, fork it to test new framework/evidence workflows, or contribute through CONTRIBUTING.md.
Independent technical reviews and contributions
Independent security, GRC, privacy, AI-assurance and software-engineering reviews are welcome, including findings that challenge assumptions or identify limitations. Please share only your first-hand observations from using the public beta with fictional/synthetic data, running a local test, or inspecting documented source code.
- Submit an independent technical review (GitHub Issue form) — describe what you tested, results, strengths, limitations and improvement suggestions. The reviewer authors their own public issue; reviews are not directly posted into this README.
- Browse independently submitted reviews — each review remains linked to its original GitHub author and discussion.
- Contribute code, tests, documentation or accessibility improvements — fork the repository and open a focused pull request with test evidence.
- Report security concerns responsibly — never place exploitable vulnerabilities, confidential evidence, personal data or credentials in public issues.
Reviewers can focus on evidence provenance and quality, readiness and applicability rules, human oversight of AI-assisted assessment, or usability and security of the public beta. Both positive and negative findings help improve the project. A GitHub star, fork or LinkedIn post alone is not a technical validation.
What BGNexa does
BGNexa separates problems that basic compliance chatbots often mix together:
- Applicability — deterministic organisation/profile rules decide what can be assessed; the LLM cannot declare a control out of scope.
- Evidence ingestion — PDF, DOCX, TXT and Markdown evidence is parsed, hashed and registered.
- Evidence retrieval — local TF-IDF retrieval works without an API key; optional semantic retrieval can be enabled separately.
- Evidence judgement — optional structured-output AI can review retrieved evidence, but quality guardrails and human review remain in control.
- Evidence quality — documented intent is separated from operational, technical, audit/test, filing, contractual and training evidence; stale-only evidence cannot establish automated support.
- Readiness scoring — provisional readiness is shown separately from resolved coverage so unresolved work cannot inflate the score.
- Human validation — reviewers can resolve findings with named rationale and evidence confirmation.
- Assurance execution — the v0.5 Assurance Workspace converts the current assessment into a traceable workplan for internal-audit/GRC follow-up.
Assurance Workspace (v0.5)
The new Assurance Workspace is designed to help a company operationalise the assessment rather than stop at a dashboard.
It creates one work item per applicable control and supports:
- control owner and assurance owner assignment;
- evidence-request registers;
- suggested test objectives and test procedures;
- workflow states from open through remediation/retest/closure;
- test-result recording;
- sample references;
- findings and severity only when a user records them — readiness gaps are not silently converted into audit findings;
- management responses, action owners and target dates;
- reviewer notes and closure evidence;
- an append-only session change log for workspace edits;
- CSV exports for workplans, evidence requests, findings/actions and the session audit trail;
- a tamper-evident assurance JSON snapshot linked to the readiness-assessment fingerprint and snapshot hash.
The public beta is intentionally session-based. It is not yet a multi-user audit-management system and does not claim cryptographic reviewer identity, immutable server audit logging or production tenant isolation.
Supported framework packs
BGNexa currently includes:
- Nigeria Data Protection Act 2023 — selected operational readiness provisions;
- NDPC GAID 2025 — selected implementation provisions with conservative DCPMI guardrails;
- CBN Risk-Based Cybersecurity Framework for OFIs, 2022 — selected directly verified controls;
- CBN Risk-Based Cybersecurity Framework for DMBs & PSBs, 2024 — selected directly verified controls;
- ISO/IEC 27001:2022 + Amendment 1:2024 — project-authored clause-level readiness summaries without redistributing ISO text;
- NIST Cybersecurity Framework 2.0 — full Core outcome surface;
- EU GDPR — selected high-value organisational readiness obligations with conservative Article 3 applicability handling.
Framework types remain visibly separate. A law, regulatory framework, implementation guide, voluntary framework and international standard are not treated as interchangeable scoring systems.
Evidence and trust guardrails
BGNexa is deliberately conservative:
- uploaded evidence is untrusted data;
- prompt-injection-like passages are flagged and blocked from automated evidence judgement;
- a document merely mentioning a topic is not proof that the requirement is satisfied;
- policy/procedure evidence does not automatically prove operating effectiveness;
- unknown dates are not invented;
- stale-only evidence cannot establish an automated
supportedresult; - applicability remains outside the LLM;
not_applicablecannot be selected by the AI reviewer or by a reviewer override;review_requiredremains unresolved review rather than a confirmed deficiency;- human-validated results remain distinct from AI proposals;
- all supplied documents remain visible in the evidence registry even when retrieval does not use them.
AI provider behaviour
BGNexa works without an API key in deterministic retrieval/manual-review mode.
Optional generation supports OpenAI or Groq. External-AI mode only sends the evidence selected for the request to the configured provider. Do not submit evidence you are not authorised to process externally.
The v0.5 AI layer also includes a provider circuit breaker. If a shared beta provider returns a rate-limit or transient connectivity/service error, BGNexa pauses immediate follow-on calls and safely falls back to human review instead of repeatedly exhausting the same quota.
Example environment configuration:
AI_PROVIDER=groq
GROQ_API_KEY=your_key_here
GROQ_MODEL=openai/gpt-oss-20b
or
AI_PROVIDER=openai
OPENAI_API_KEY=your_key_here
OPENAI_MODEL=gpt-5.6
OPENAI_EMBEDDING_MODEL=text-embedding-3-small
Never commit real API keys. Use deployment secret storage.
Readiness states
| State | Meaning |
|---|---|
supported |
Evidence supports the readiness requirement, subject to the recorded review state |
partially_supported |
Evidence covers a material subset of the requirement |
not_evidenced |
Sufficient evidence was not found or a reviewer confirmed the evidence gap |
review_required |
Scope or evidence judgement cannot safely be resolved automatically |
not_applicable |
Explicit non-AI applicability logic determines that the control is outside the applicable set |
Scoring
The dashboard intentionally shows two different values:
Provisional readiness = evidence-weight earned / resolved applicable weight.
Resolved coverage = resolved applicable weight / all applicable weight.
This prevents a small resolved subset from being presented as a reassuring overall result.
Evidence quality
Every supplied source is classified conservatively into evidence modes such as:
- documented intent;
- operational record;
- technical evidence;
- audit/test evidence;
- regulatory filing;
- contractual evidence;
- training evidence;
- unknown.
BGNexa also exposes a general freshness signal:
current: 0–365 days;aging: 366–730 days;stale: more than 730 days;unknown: no reliable date or a future-dated source.
These thresholds are product-level evidence-age signals, not replacements for framework-specific review, retention, recertification or regulatory deadlines.
Quick start
python -m venv .venv
source .venv/bin/activate  # Windows: .venv\Scripts\activate
pip install -r requirements.txt
cp .env.example .env
streamlit run app.py
The app works without an API key. Without AI review, retrieved candidates remain review_required until a person validates them.
Core quality checks:
pip install -r requirements-core.txt
pytest -q
python scripts/audit_framework_sources.py --strict
python scripts/run_evals.py --strict
python scripts/smoke_stage2.py
python scripts/smoke_stage4.py
Repository structure
.
├── app.py                         # readiness application
├── pages/
│   └── 01_Assurance_Workspace.py # internal-audit/GRC workbench
├── frameworks/                    # source-traceable framework packs
├── src/
│   ├── applicability.py
│   ├── assessor.py
│   ├── assurance.py
│   ├── copilot.py
│   ├── evidence.py
│   ├── evidence_quality.py
│   ├── llm.py
│   ├── report.py
│   ├── retriever.py
│   ├── review.py
│   └── scoring.py
├── evals/
├── scripts/
├── tests/
└── docs/
Public-beta boundary
The public Streamlit build is suitable for demonstration and controlled beta testing with non-sensitive or appropriately authorised evidence. It is not yet a production SaaS for confidential multi-tenant customer evidence.
Before a hosted production edition, BGNexa still needs authentication/SSO, tenant isolation, encrypted persistence, secure retention/deletion controls, durable server-side audit logging, malware/file validation, deployment-specific rate limits, stronger identity/sign-off, privacy controls and deployment threat modelling.
See SECURITY.md before using real organisational evidence.
Roadmap
Near-term product direction:
- persistent projects/engagements and reviewer workpapers;
- durable evidence-request and findings workflows;
- role-based access and SSO;
- framework version-diff and change alerts;
- human-approved cross-framework mappings;
- real anonymised policy/evidence corpus evaluation, including false-support and false-gap measurement;
- framework-specific evidence expiry/supersession rules;
- board/audit-committee-ready DOCX/PDF reports;
- API/integrations for GRC, ticketing and evidence stores;
- multi-tenant hosted edition with encrypted storage and durable audit logs.
Security
See SECURITY.md. Please do not place exploitable vulnerabilities, secrets, customer evidence, API keys or sensitive assessment exports in public GitHub issues.
License
MIT for the software. Third-party laws, regulations and standards retain their own rights and terms. ISO standards are not included in this repository.
Explore related projects
trimstray/the-book-of-secret-knowledge
A collection of inspiring lists, manuals, cheatsheets, blogs, hacks, one-liners, cli/web tools and more.
257,974 starsHack-with-Github/Awesome-Hacking
A collection of various awesome lists for hackers, pentesters and security researchers
125,360 starsswisskyrepo/PayloadsAllTheThings
A list of useful payloads and bypass for Web Application Security and Pentest/CTF
82,623 starscaddyserver/caddy
Fast and extensible multi-platform HTTP/1-2-3 web server with automatic HTTPS
79,020 stars