
Allessyer/awesome-kaz-datasets
Allessyer/awesome-kaz-datasets has 69 GitHub stars and 3 forks. GitHot measured +2 in 7 days. Last checked 2026-11-15 22:04 UTC. Last push 2026-11-04.
Measured star growth
- in 24h
- Update delayed
- in 7 days
- +2
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Datasets in kazakh language for different tasks
AIREADME.md
Original
 Awesome Kazakh Datasets
A curated, verified catalog of public datasets for Kazakh-language NLP, LLM, speech, and vision research.


About · Text & NLP · Speech · Vision & OCR · Watchlist · Contributing · License
✨ Explore Kazakh models across every domain — awesome-kaz-models
About
Kazakh is spoken by roughly 13 million people, yet reusable public datasets for it are scattered across Hugging Face, GitHub, institutional pages, and archives with no reliable map of what's actually downloadable today.
Every entry below is checked against its primary source, with release date, access terms, and license recorded rather than assumed. Resources that are announced but not yet independently verifiable go in the Watchlist instead of the main tables. See CONTRIBUTING.md for the full inclusion policy and CHANGELOG.md for what's new.
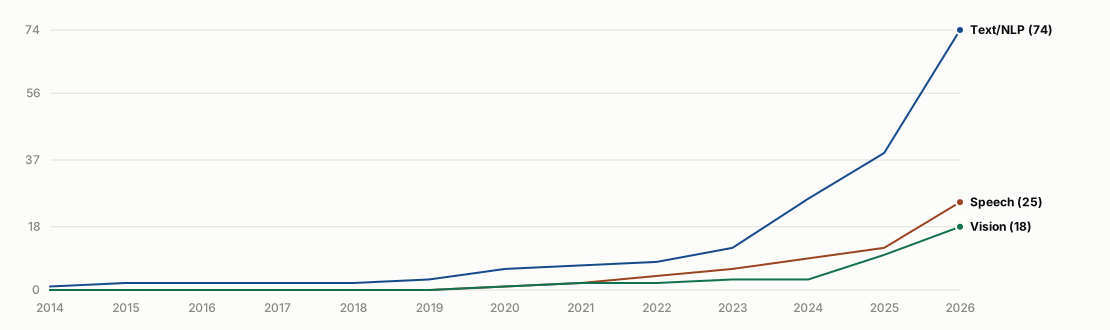
Cumulative Kazakh dataset releases over time, by section.
Text, NLP, and LLM
| ID | Released | Dataset | Task | Description | Storage | Samples |
|---|---|---|---|---|---|---|
| 1 | 2026-10 | Kazakh Text-to-SQL Rakhat Masat Open |
QA | Dataset of Kazakh natural language questions paired with executable SQLite queries across 13 relational databases, structured for SFT (3,744 pairs), independent evaluation, and DPO preference alignment. | 5.1 MB | 3,744+ question-SQL pairs |
| 2 | 2026-10 | KazAI-Detect Benchmark Yerassyl Open |
TC · Safety | Multi-domain benchmark dataset for detecting AI-generated text in Kazakh, featuring binary Human vs AI classification across consumer reviews (KazSAnDRA), essays, and news with in-domain and out-of-domain test splits. | 1.7 MB | Train, test, and OOD test splits |
| 3 | 2026-09 | Kazakh Corpus v1 Tokhtobayev Salim Open |
LM | Large-scale Kazakh pretraining corpus derived and cleaned from sozkz v3, intended for language model pretraining, SLM training, and encoder pretraining. | 17.2 GB | 8,664,472 documents |
| 4 | 2026-08 | Kazakh-Russian Child-Directed Language Corpus Mukusheva et al. Open |
LM | Bilingual corpus combining narrative texts (fairy tales, children's literature, educational texts) and child-adult dialogue transcripts in Kazakh and Russian for language acquisition and low-resource NLP research. | 31.6 MB | Not reported |
| 5 | 2026-08 | KazakhLawCorpus-clean Arailym Tleubayeva Open |
LQA · LM | Cleaned, Kazakh-only corpus of 215,889 legislative documents from the Republic of Kazakhstan (Adilet legal system) with 25 metadata fields for legal NLP, retrieval, and QA. | 1005.0 MB | 215,889 documents |
| 6 | 2026-08 | KazSpam v1 salyamq Open |
TC · Safety | Web-crawled dataset of 10,000 Kazakh texts annotated into four classes (normal, casino, porn, and other) for spam detection, content filtering, and online safety. | 105.9 MB | 10,000 examples |
| 7 | 2026-06 | FreshQA Kazakh ISSAI researchers Open |
QA | Bilingual (English/Kazakh) benchmark of factual questions with false premises, for testing how models handle incorrect assumptions. | 0.4 MB | 600 |
| 8 | 2026-06 | DeFAn Kazakh ISSAI researchers Open |
QA | Machine-translated Kazakh/English version of the DefAn hallucination benchmark for definitive question answering. | 0.2 MB | 3,178 questions |
| 9 | 2026-06 | Kazakh Open Retrieval Benchmark Timur Seidalin Open |
RAG · QA | Evidence-based Kazakh information-retrieval benchmark built from Kazakh Wikipedia, showing morphological stemming outperforms multilingual embeddings. | 14.6 MB | 300 queries; 8,370 passages |
| 10 | 2026-06 | Til-Corpus Til-Qazyna Gated |
LM | Kazakh-centered, quality-tiered text corpus for language-model pretraining, with Russian, English, and mixed-language material. | 204.2 GB | 58,850,639 documents |
| 11 | 2026-06 | Til-Instruct Til-Qazyna Gated |
IFT | Unified, model-judged and quality-tiered Kazakh-focused instruction-tuning collection assembled from TilQazyna SFT sources. | 8.35 GB | 2,563,966 raw; 2,114,016 clean; 1,581,787 premium (≈6.26M rows total) |
| 12 | 2026-06 | Til-Books Til-Qazyna Gated |
LM | Two-layer full-text book corpus with exact extraction/OCR and cleaned reading text for Kazakh language modelling. | 2.02 GB | 16,847 books; 13,194 Kazakh |
| 13 | 2026-06 | Til-Parallel Til-Qazyna Gated |
LM | Large quality-tiered multilingual corpus centered on Kazakh, with Russian and English material. | 72.16 GB | 23,294,865 rows |
| 14 | 2026-06 | Til-Morphology Til-Qazyna Gated |
MORPH | Kazakh morphological-analysis collection with word segmentation and morpheme-count fields, quality-tiered by model judging. | 207.8 MB | 3,767,518 analyses |
| 15 | 2026-06 | Til-Classification Til-Qazyna Gated |
TC | Quality-tiered Kazakh-focused text-classification collection with labels, tasks, provenance, and model-judge scores. | 15.1 MB | 91,766 rows |
| 16 | 2026-06 | Til-Terminology Til-Qazyna Gated |
LM | Quality-tiered terminology-focused text collection for Kazakh language research and text generation/pretraining. | 5.7 MB | 317,277 rows |
| 17 | 2026-06 | Til-Web-Raw-KK-v1 Til-Qazyna Gated |
LM | Raw HTML mirror of two Kazakh educational and Q&A websites (bilim-all.kz, surak.baribar.kz) — server-rendered pages, images, and attachments collected before text extraction/cleaning, as source material for the Til foundation-model program. | 19.5 GB | ≈222,890 pages |
| 18 | 2026-05 | KazLawBench Batyr Raiym Gated |
LQA | First bilingual (Russian + Kazakh) legal-LLM benchmark for Kazakhstan, spanning statutory codes and de-identified Supreme Court judgments across seven task types. | 9.9 MB | 3,098 |
| 19 | 2026-05 | 100k Movie Reviews from Kazakhstan Rustem Yeshpanov Gated |
SC | 100,502 kino.kz movie reviews (2001-2025) manually annotated for language ID and sentiment, capturing Russian, Kazakh, and code-switched Kazakh-Russian text. | 57.7 MB | 100,502 reviews |
| 20 | 2026-05 | Kazakh Wiki RAG Dataset Shyngys Kozhakhmetov Open |
RAG · STS | Kazakh query-passage retrieval dataset constructed from Kazakh Wikipedia articles, providing query-passage pairs and hard-negative triplets for semantic search, RAG evaluation, and embedding model training (e.g. kazakh-e5-rag-embedding). | 85.2 MB | Train, dev, and test retrieval splits with triplets |
| 21 | 2026-04 | Zerde-QA-50K kurumikz Open |
IFT · QA | Synthetic Kazakh QA collection spanning 20+ academic domains for instruction tuning and low-resource NLP research. | 156.2 MB | 51,422 pairs |
| 22 | 2026-03 | RAGBench Kazakh ISSAI researchers Open |
RAG | Kazakh translation of RAGBench for evaluating retrieval-augmented-generation systems across biomedical, legal, financial, and general-knowledge domains. | 31.2 MB | 11,431 |
| 23 | 2026-03 | IFBench Kazakh ISSAI researchers Open |
IF | Machine-translated Kazakh instruction-following benchmark evaluating adherence to explicit constraints. | 1.3 MB | 444 |
| 24 | 2026-03 | MMLU-Redux 2.0 Kazakh ISSAI researchers Open |
MCQA | Machine-translated Kazakh version of MMLU-Redux 2.0 for multiple-choice reasoning across 57 academic subjects. | Not reported | 5,700 questions |
| 25 | 2026-03 | PolyMath Kazakh ISSAI researchers Open |
MATH | Machine-translated Kazakh subset of PolyMath for evaluating multilingual mathematical reasoning. | Not reported | 500 problems |
| 26 | 2026-03 | Kazakh Lexical Complexity Classes Gulnur Open |
TC | CEFR-graded lexical resource for the Kazakh language containing 4,561 lemma-POS entries mapped across five CEFR proficiency levels (A1 to C1) for lexical complexity and language learning. | 0.33 MB | 4,561 lemma-POS entries |
| 27 | 2026-02 | Kazakh Analytical RAG (Single-Document) Kadyrbek et al. Gated |
RAG · QA | High-density Kazakh analytical question-answering collection with single-document context, for retrieval-augmented generation research. | 33.4 MB | 4,522 examples; ≈5.98M words |
| 28 | 2026-02 | Content Moderation and Safety — Kazakh Kadyrbek et al. Gated |
Safety · TC | Kazakh content-moderation and safety dataset with toxicity categories, severity labels, domain tags, and constructive de-escalating responses. | 9.3 MB | 17,827 examples; ≈1.67M words |
| 29 | 2026-02 | Multi-Step Reasoning for Kazakh Context Kadyrbek et al. Gated |
QA | Kazakh question-answering and instruction collection centered on complex multi-step reasoning and culturally grounded analysis. | 39.0 MB | 10,981 examples; ≈6.65M words |
| 30 | 2026-02 | SozKZ Corpus Clean v3 Dias Stukenov Open |
LM | Large-scale cleaned and deduplicated Kazakh text corpus assembled from 18 public web and text sources, filtered for language-model pretraining. | 32.3 GB | 13,463,018 documents |
| 31 | 2025-12 | MMLU-Pro Kazakh/Russian ISSAI researchers Open |
MCQA | Machine-translated Kazakh/Russian version of MMLU-Pro, with more answer options and more challenging reasoning tasks than MMLU. | 11.4 MB | 24,064 rows; 12k per language |
| 32 | 2025-12 | GSM8K Kazakh/Russian ISSAI researchers Open |
MATH | Machine-translated Kazakh and Russian test sets from GSM8K for grade-school mathematical reasoning. | Not reported | 2,638 rows |
| 33 | 2025-12 | ARC Kazakh/Russian ISSAI researchers Open |
MCQA | Machine-translated Kazakh and Russian ARC test sets for elementary and middle-school science reasoning. | Not reported | 7,096 rows |
| 34 | 2025-12 | GPQA Kazakh/Russian ISSAI researchers Open |
MCQA | Machine-translated Kazakh and Russian GPQA benchmark for expert-level biology, physics, and chemistry questions. | Not reported | 2,384 rows |
| 35 | 2025-12 | MMLU Kazakh ISSAI researchers Open |
MCQA | Machine-translated Kazakh MMLU test split for academic and professional knowledge evaluation. | Not reported | 14,042 questions |
| 36 | 2025-10 | KazCulture Maxutov et al. Gated |
CQA | Human-written passage-question-answer triplets covering Kazakh traditions, music, beliefs, cuisine, games, clothing, and handicrafts. | 4.6 MB | 16,137 PQA triplets |
| 37 | 2025-07 | HPLT 3.0 Kazakh HPLT project Open |
LM | Kazakh Cyrillic subset of HPLT 3.0, a large multilingual web-crawl corpus for language-model pretraining. | 8.76 GB | ≈5.12M documents; ≈100.6M segments; ≈7.34B tokens |
| 38 | 2025-05 | Qorgau MBZUAI NLP group Open |
Safety | Kazakh/Russian bilingual LLM-safety evaluation benchmark spanning six high-level risk areas and 17 harm types. | 103.9 MB | 2,790 prompts |
| 39 | 2025-03 | KazakhTextDuplicates v2.0 Arailym Tleubayeva Open |
STS | Controlled multi-regime benchmark for semantic deduplication, semantic similarity, and retrieval in Kazakh, with seven deterministic duplication regimes. | 217 MB | 25,922 rows |
| 40 | 2025-02 | Kazakh-IFT Laiyk et al. Gated |
IFT | Instruction-following dataset covering Kazakhstani governance, legal process, cultural practice, and public-service knowledge, LLM-generated with GPT-4o. | 7.85 MB | ~10,600 samples |
| 41 | 2025-01 | KazMMLU Togmanov et al. Open |
MCQA | Kazakh/Russian multiple-choice benchmark covering regional knowledge of Kazakhstan across school and university subjects. | 17.4 MB | 23,000 total; 10,969 Kazakh |
| 42 | 2025-01 | FineWeb2 Kazakh Hugging Face FineWeb team Open |
LM | Kazakh (kaz_Cyrl) configuration of FineWeb2, a deduplicated, quality-filtered multilingual web-crawl pretraining corpus. | 6.86 GB | 3,380,000 rows (kaz_Cyrl) |
| 43 | 2025 | KazBench-KK KazBench-KK authors Open |
CQA · MCQA | Culturally grounded Kazakh multiple-choice benchmark spanning 17 domains of traditions, society, history, and contemporary knowledge. | 2.35 MB | 7,111 questions |
| 44 | 2024-11 | Kazakh Dastur MC kz-transformers Open |
MCQA | Multiple-choice benchmark on Kazakh traditions and customs (dastur). | 0.3 MB | 1,005 |
| 45 | 2024-11 | Kazakh Constitution MC kz-transformers Open |
MCQA | Multiple-choice benchmark on the Constitution of the Republic of Kazakhstan. | 0.1 MB | 414 |
| 46 | 2024-11 | Kazakh UNT kz-transformers Open |
MCQA | Multiple-choice benchmark built from the Kazakh Unified National Testing exam. | 4.4 MB | 14,850 |
| 47 | 2024-11 | MMLU Translated KK kz-transformers Open |
MCQA | Machine-translated Kazakh version of MMLU. | 11.4 MB | 15,854 |
| 48 | 2024-11 | GSM8K Translated KK kz-transformers Open |
MR | Machine-translated Kazakh version of GSM8K grade-school math word problems. | 4.2 MB | 8,792 |
| 49 | 2024-06 | mOSCAR Kazakh OSCAR project Open |
LM | Kazakh Cyrillic configuration of mOSCAR, the multimodal multilingual OSCAR web-crawl release. | 548.6 MB | 248,403 documents |
| 50 | 2024-06 | KazLit-Parallel Sagi Abdashim Open |
MT | Multilingual literary parallel corpus of automatically aligned text segments across Kazakh, Russian, and English for machine translation and cross-lingual NLP. | 13.7 MB | 71,096 pairs |
| 51 | 2024-05 | Textual Foundations of Justice Akhmetov et al. Open |
LQA · LM | All current laws of the Republic of Kazakhstan as of 2024-04-01, in Russian and Kazakh, for legal-QA model training. | Not reported | Not reported |
| 52 | 2024-04 | KazQAD Yeshpanov et al. Gated |
QA · RAG | Kazakh open-domain QA dataset supporting reading comprehension, full ODQA, and information-retrieval settings, built from translated Natural Questions and the Kazakh UNT exam. | 281.7 MB | 6,000 questions; 12,700 passages |
| 53 | 2024-03 | KazParC ISSAI researchers Gated |
MT | Kazakh parallel corpus covering Kazakh, English, Russian, and Turkish across proverbs, literature, news, TED talks, legal documents, and UN publications, plus a large synthetic (SynC) extension. | 25.9 GB | 372,000 sentence pairs (+ 1.8M synthetic) |
| 54 | 2024-03 | Kazakh–Russian KAZNU Dauren-Nur Open |
MT | Parallel Kazakh-Russian corpus of governmental and official documents. | 23.4 MB | 86,453 pairs |
| 55 | 2024-03 | KazSAnDRA ISSAI researchers Gated |
SC | Kazakh Sentiment Analysis Dataset of Reviews and Attitudes, with numerically rated reviews supporting polarity and score classification. | 108 MB | 180,064 reviews |
| 56 | 2024-02 | Kazakh–English KAZNU Al-Farabi Kazakh National University researchers Open |
MT | Parallel Kazakh-English corpus collected from law documents and news sites. | 70.6 MB | 377,044 pairs |
| 57 | 2023-11 | Kazakh Instruction v2 Mussa & Mansurova Open |
IFT · QA | Kazakh instruction dataset built by machine-translating Stanford Alpaca with manual correction and added Kazakhstani names, places, history, and culture instructions. | 35.6 MB | 52,201 rows |
| 58 | 2023-09 | CulturaX Kazakh CulturaX authors Gated |
LM | Kazakh subset of CulturaX, a cleaned and deduplicated multilingual web corpus for language-model pretraining. | 9.07 GB | 2,733,982 documents; 2,802,485,195 tokens |
| 59 | 2023-09 | SIB-200 Kazakh David Ifeoluwa Adelani Open |
TC | Kazakh topic-classification configuration of SIB-200, derived from FLORES-200 and covering seven news topics. | 0.14 MB | 1,004 examples (701 train; 99 validation; 204 test) |
| 60 | 2023-04 | MDBKD Sagyndyk et al. Open |
LM | Multi-Domain Bilingual Kazakh Dataset combining CC100, Kazakh Wikipedia, kazakhBooks, Leipzig news, OSCAR CommonCrawl, and kazakhNews sources. | 24.7 GB | 24,883,808 texts; 2.09B tokens |
| 61 | 2022-06 | FLORES-200 Kazakh NLLB / FLORES team Open |
MT | Kazakh (kaz_Cyrl) sentences within FLORES-200, a 200-language many-to-many machine-translation evaluation benchmark of professionally translated Wikipedia sentences. | Not reported | 3,001 sentences (dev + devtest) |
| 62 | 2021-11 | KazNERD Yeshpanov et al. Gated |
NER | Kazakh named-entity corpus of 112,702 sentences from television news text, annotated with 25 entity classes using IOB2. | 136.7 MB | 112,702 sentences; 136,333 entity annotations |
| 63 | 2020-12 | KazNewsDataset Yakunin et al. Open |
TC · LM | Kazakhstani news corpus for social-significance identification with topic-modelling results, from open Kazakhstani news media and governmental development programs. | Not reported | 1,142,735 documents |
| 64 | 2020-12 | KazRusNewsDataset Yakunin et al. Open |
TC | Kazakhstani and Russian news corpus collected via web scraping from open Kazakhstani and Russian media. | Not reported | 6,261,953 documents |
| 65 | 2020 | CC-100 Kazakh CC-Net / XLM-R team Open |
LM | Explicit Kazakh (kk) monolingual subset of CC-100 reconstructed from Common Crawl for multilingual language modelling. | 889 MB | Not reported |
| 66 | 2019-06 | WikiANN Kazakh Rahimi et al. Open |
NER | Kazakh (kk) split of WikiANN / PAN-X, a Wikipedia-derived multilingual named-entity-recognition dataset with LOC/PER/ORG IOB2 tags. | 0.21 MB | Not reported (kk split) |
| 67 | 2015-06 | UD Kazakh KTB Makazhanov et al. Open |
POS | Kazakh Universal Dependencies treebank drawn from Wikipedia, folk tales, the UDHR, news, and phrasebook sentences. | 0.4 MB | 1,078 sentences; 10,536 tokens |
| 68 | 2014-05 | Apertium Kazakh Morphological Lexicon Washington et al. Open |
MORPH | Curated open-source morphological dictionary for Kazakh containing 22,000+ lemmas with paradigm codes, stem-affix mapping, and morphophonological inflection rules. | 2.5 MB | 22,000+ lemmas |
| 69 | Not reported | kaz-text-for-lm-normalized Al-Farabi Kazakh National University Gated |
LM | Normalized Kazakh language-modelling corpus combining news, literature, academic/dissertation text, and an August-2024 Kazakh Wikipedia snapshot. | 5.99 GB | Not reported |
| 70 | Not reported | Uzbek-Kazakh Parallel Corpora Sanatbek Open |
MT | Expert-translated Uzbek-Kazakh parallel sentence corpus covering literature and web news. | 34.2 MB | 133,877 pairs |
Speech and audio
| ID | Released | Dataset | Task | Description | Storage | Samples |
|---|---|---|---|---|---|---|
| 1 | 2026-08 | YO-CPT-kk NCSpeech Open |
ASR · TTS · SV | YouTube-oriented Kazakh continual-pretraining corpus spanning TTS-grade, ASR, and speaker-verification use cases. | 100.0 GB | 600 h; 156,903 utterances |
| 2 | 2026-07 | KazMix-3 ISSAI researchers Open |
TS-ASR | Kazakh three-speaker overlapping-speech dataset for target-speaker ASR, released with the Persona-ASR project; mixtures derived from KSD/SLR140 with enrollment utterances. | 256.3 MB | 89,775 rows (62.8k/13.5k/13.5k splits) |
| 3 | 2026-07 | Kazakh Code-Switching ASR Benchmark Tim2190 Open |
ASR | Benchmark of 31 spontaneous conversational speech clips (~3.7 min) featuring everyday Kazakh-Russian code-switching from YouTube interviews, vlogs, and stand-up comedy, accompanied by dual independent reference transcriptions and code-switch flags. | 40.7 MB | 31 clips (≈3.7 min) |
| 4 | 2026-06 | Til-Audio Til-Qazyna Gated |
ASR · TTS | Kazakh audio-and-transcript collection for speech recognition, speech synthesis, and audio classification. | 249.77 GB | 380,068 audio/transcript rows |
| 5 | 2026-05 | KazEGA kazega0 Gated |
EPC | Kazakh speech corpus for paralinguistic classification, annotated for emotion (7 classes), gender, and age group; source audio extracted from YouTube. | 38.1 GB | 96,582 utterances |
| 6 | 2026-04 | SAKURA Kazakh/Russian ISSAI researchers Open |
AQA | Machine-translated Kazakh and Russian SAKURA benchmark for single-hop perception and multi-hop reasoning over audio. | Not reported | 4,000 rows |
| 7 | 2026-04 | PersonaMix ISSAI researchers Open |
TS-ASR | Controlled Kazakh-English overlapping-speech benchmark for target-speaker ASR and target-presence detection. | Not reported | 9,978 mixtures |
| 8 | 2026-03 | WavCapsQA Kazakh-Russian ISSAI researchers Open |
AQA | Machine-translated Kazakh/Russian adaptation of the WavCaps-QA test set for audio question answering over environmental sounds, music, and ambient scenes. | 189 MB | 608 rows (304 Kazakh, 304 Russian) |
| 9 | 2026-03 | WavCaps Kazakh/Russian ISSAI researchers Open |
AC | Machine-translated Kazakh and Russian WavCaps test set for free-form captioning of environmental audio and sound scenes. | Not reported | 3,460 rows |
| 10 | 2026-02 | Multimedia Corpus of Modern Spoken Kazakh Language (Module 1) Troiani et al. Open |
ASR | First module of a corpus of naturally occurring spoken Kazakh conversations (2021-2023), with WAV audio, ELAN/EAF time-aligned transcriptions, verticalized TSV and linearized text, plus participant and speech-event metadata. | Not reported | ≈12 h; 33 speech events; 78 participants |
| 11 | 2026-02 | Kazakh Songs ASR Rustem Yeshpanov Gated |
ASR | Manually aligned Kazakh vocal-audio segments from commercially released songs, for studying whether sung speech improves low-resource ASR. | 2.9 GB | ≈4.5 h; 3,013 audio-text pairs (195 songs, 36 artists) |
| 12 | 2026-02 | Kazakh Speech MFA Punctuation Bekzat Uteulin Open |
ASR | Punctuation-restored, word-level-timestamped derivative of ISSAI KSC2, force-aligned with the Montreal Forced Aligner. | 56.8 GB | 408,010 utterances; ≈1,110 h |
| 13 | 2026-01 | Kazakh Speech Dataset (optimized KSC2) Flamme-VRM Open |
ASR · TTS | VAD-sliced and Whisper-Turbo re-transcribed derivative of KSC2 with quality filtering. | 54.5 GB | ≈726 h; 230,793 clips |
| 14 | 2025-12 | Mozilla Common Voice Kazakh Mozilla Foundation Open |
ASR | Crowdsourced Kazakh voice recordings from the Common Voice Scripted Speech project. | Not reported | 2,750 clips; 3.76 h recorded (2.39 h validated); 193 speakers |
| 15 | 2025-12 | KSC2 Structured Inflexion Lab Open |
ASR | Syntactically enhanced derivative of ISSAI KSC2 with full capitalization, punctuation, and grammatical formatting restored using Gemma 27B while preserving strict audio alignment. | 76.8 GB | ≈1,200 hours |
| 16 | 2025-04 | MATERIAL Kazakh–English Language Pack Appen (for IARPA MATERIAL) Paid |
ST · RAG | Kazakh conversational telephone speech with English translations, transcripts, and query-relevance annotations, from Northern and Southern Kazakh dialect regions. | Not reported | ≈57 h |
| 17 | 2024-11 | Belebele-FLEURS WüNLP Open |
SQA · ASR | Spoken reading-comprehension benchmark combining Belebele and FLEURS audio/text across 99 languages. | 3.4 GB | 870 Kazakh test examples |
| 18 | 2024-04 | KazEmoTTS Abilbekov et al. Application |
TTS · EPC | Kazakh emotional TTS corpus with six emotion classes (neutral, angry, happy, sad, scared, surprised) across male and female narrators. | 10.5 GB | 74.85 h; 54,760 clips |
| 19 | 2024-01 | ISSAI SKIMMED Dauren-Nur Open |
ASR · TTS | Multimodal Kazakh audio-transcription dataset with train/test/dev splits. | 5.4 GB | 21,617 clips |
| 20 | 2023-07 | Kazakh Speech Dataset (KSD / SLR140) Mansurova & Kadyrbek Open |
ASR | Open-source Kazakh speech corpus recorded on mobile devices across diverse regions, ages, and genders, verified by native speakers. | 56 GB | 554 h; 204,250 utterances |
| 21 | 2023-04 | Kazakh Speech Commands Kuzdeuov et al. Open |
KWS | Kazakh speech-command recognition dataset built via synthetic TTS generation and speech-corpus scraping, with data augmentation. | 267.3 MB | ≈1 h; 3,623 utterances |
| 22 | 2022-09 | Kazakh Speech Corpus 2 (KSC2) Mussakhojayeva et al. Open |
ASR | Industrial-scale open-source Kazakh speech corpus subsuming KSC and KazakhTTS2, with additional TV, radio, senate, and podcast data, including Kazakh-Russian code-switching. | 80.8 GB | ≈1,200 h; 600,000+ utterances |
| 23 | 2022-01 | KazakhTTS2 ISSAI researchers Open |
TTS | Expanded five-speaker Kazakh TTS corpus, extending the original KazakhTTS with more data, speakers, and topics. | 35.7 GB | 271 h; 5 speakers |
| 24 | 2021-04 | KazakhTTS Mussakhojayeva et al. Open |
TTS | Open-source Kazakh text-to-speech corpus, later expanded by KazakhTTS2. | 11.9 GB | ≈93 h; 42,000 utterances |
| 25 | 2020-09 | Kazakh Speech Corpus (KSC) ISSAI researchers Open |
ASR | Crowdsourced Kazakh speech corpus with an initial ASR baseline. | 19 GB | ≈332 h; 153,000 utterances |
English-Russian-Kazakh comparison by speech task
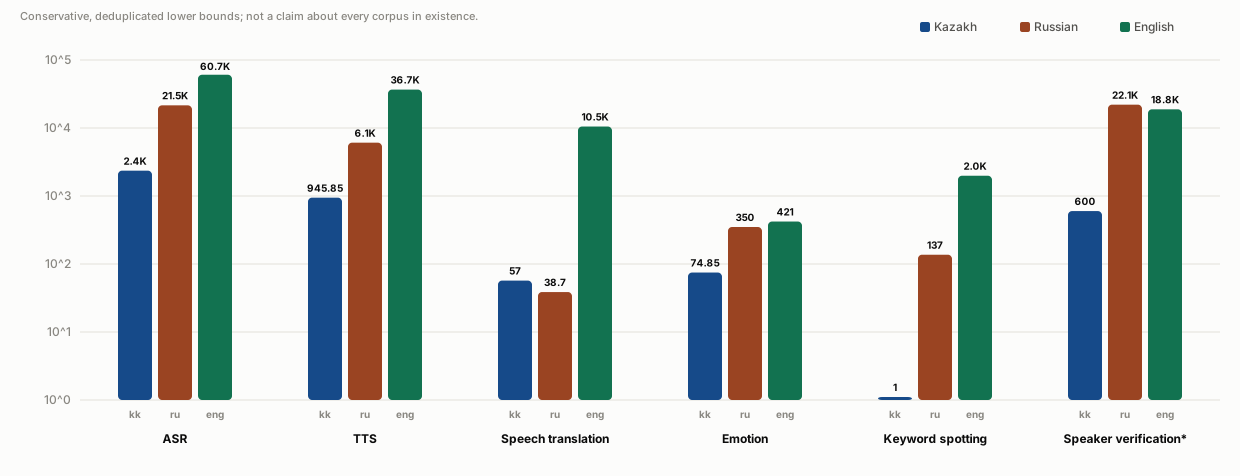
The bars are conservative lower bounds, not estimates of every dataset in existence.
Subsets, mirrors, and known derivatives are excluded. For speaker verification (*),
a broader speaker-presence rule counts complete multilingual corpora when they
explicitly contain speakers of the language; these are corpus-hours containing the
language, not language-only hours, and possible cross-corpus overlap remains.
Vision, OCR, and multimodal
| ID | Released | Dataset | Task | Description | Storage | Samples |
|---|---|---|---|---|---|---|
| 1 | 2026-08 | Darmm Kazakh OCR v2 Rakhat Zhumabek Open |
OCR | Synthetic OCR dataset for printed Kazakh Cyrillic text, adding a 70k "hard" tier (degraded print, shadows, perspective warp) and 12k multi-line document pages on top of the original clean crops. | 11.01 GB | 284,000 images |
| 2 | 2026-06 | Darmm Kazakh Cyrillic OCR Rakhat Zhumabek Open |
OCR | Synthetic printed-text OCR dataset for Kazakh Cyrillic, rendered from Kazakh Wikipedia text with Kazakh-specific characters (Ә, Ғ, Қ, Ң, Ө, Ұ, Ү, Һ, І). | 2.3 GB | 200,000 images (100k word-level + 100k line-level) |
| 3 | 2026-06 | TurkicOCR-Cyrillic Alen Issayev Open |
OCR · DU | Synthetic Turkic-Cyrillic OCR dataset spanning Kazakh, Kyrgyz, Kazakh-Russian, and Kyrgyz-Russian text and layouts. | 66.7 GB | 100,000 unique pages; 175,000 nested-config rows |
| 4 | 2026-04 | BeyneleBench ISSAI researchers Open |
T2I | Kazakh/English benchmark for cultural fidelity in text-to-image generation, pairing prompts with reference images and cultural taxonomy levels. | 2.0 GB | 750 |
| 5 | 2026-04 | SpokenMQA Kazakh ISSAI researchers Open |
AVQA | Machine-translated Kazakh adaptation of SpokenMQA for evaluating spoken mathematical reasoning in speech/audio-language models. | 1.4 GB | 2,256 |
| 6 | 2026-03 | MMBench Kazakh ISSAI researchers Open |
VQA | Kazakh translation of the MMBench validation split, evaluating perception, reasoning, and logic via multiple-choice VQA. | 772.2 MB | 4,329 |
| 7 | 2026-03 | MathVision Kazakh ISSAI researchers Open |
VMR | Machine-translated MathVision dataset for evaluating mathematical reasoning and visual understanding in multimodal LLMs. | 248.7 MB | 3,040 |
| 8 | 2026-03 | BabyVision Kazakh ISSAI researchers Open |
VQA | Machine-translated Kazakh BabyVision benchmark for child-intuitive visual perception, counting, shape recognition, and anomaly detection. | Not reported | 388 rows |
| 9 | 2025-12 | KazakhOCR Gagnier et al. Open |
OCR | Synthetic benchmark for evaluating multimodal models on Arabic-, Cyrillic-, and Latin-script Kazakh OCR. | 15.3 GB | 600 images |
| 10 | 2025-12 | AI2D Kazakh ISSAI researchers Open |
DQA | Kazakh translation of AI2D diagram-question-answering data. | 465.0 MB | 3,088 |
| 11 | 2025-12 | MathVista Kazakh ISSAI researchers Open |
VMR | Kazakh translation of MathVista for visual math reasoning. | 52.6 MB | 1,000 |
| 12 | 2025-12 | OCRBench Kazakh ISSAI researchers Open |
OCR · VQA | Kazakh OCR and visual-QA benchmark translated from OCRBench. | 28.7 MB | 441 |
| 13 | 2025-12 | QazLip Zhalgas, A. et al. Open |
VSR | Kazakh lip-movement command corpus of 102 nouns recorded from 26 participants at 1080p/60fps for visual speech recognition. | 4.41 GB | ≈34,000 videos; 1.2M frames |
| 14 | 2025-12 | MMStar Kazakh/Russian ISSAI researchers Open |
VQA | Machine-translated Kazakh and Russian MMStar benchmark for visual recognition and multimodal reasoning across 18 dimensions. | Not reported | 3,000 rows |
| 15 | 2025-12 | RealWorldQA Kazakh/Russian ISSAI researchers Open |
VQA | Machine-translated Kazakh and Russian RealWorldQA benchmark for spatial understanding and reasoning over real-world images. | Not reported | 1,530 rows |
| 16 | 2023-03 | Central Asian Food Dataset (CAFD) Karabay et al. Open |
IC | 42-class image dataset comprising 16,499 images of Kazakh national and Central Asian cuisine dishes for food recognition and dietary assessment. | 1.0 GB | 16,499 images (42 classes) |
| 17 | 2021-10 | KOHTD Toiganbayeva et al. Application |
HTR | Kazakh Offline Handwritten Text Dataset of exam papers (99% Kazakh, 1% Russian). | 2.6 MB | 3,000 exam papers; 140,335+ segmented images; ≈922,010 symbols |
| 18 | 2020-07 | HKR Nurseitov et al. Application |
HTR | Handwritten Kazakh and Russian database (HKR), predominantly Russian (≈95%) with a Kazakh minority share (≈5%). | Not reported | 1,400+ forms; ≈63,000 sentences; ≈715,699 symbols (≈5% Kazakh) |
Watchlist / announced resources
Resources below are announced, described in a paper without a public artifact, license-conflicted, or not yet independently verifiable as usable Kazakh-language datasets. They are intentionally not part of the main catalog above. Where a source is known, the entry links to it.
- Kazakh Text Corpus / Speech Corpus / AI Evaluation Benchmark Suite — Announced in 2026 as more than 10B text tokens and over 10,000 speech hours (including 1,000 manually transcribed "gold standard" hours) and a nine-dimension AI evaluation benchmark suite, from a joint initiative between the Qazaq Tili Qogamy and OpenAI, but no public dataset download was identified.
- National Corpus of the Kazakh Language (QazCorpus) — Official searchable Kazakh corpus ecosystem with multiple subcorpora. The Main Corpus reports 31,105,900 word usages with morphological, semantic, lexical, phonetic, and phonological annotation. No independently verified bulk-download artifact and reusable dataset license could be confirmed, so it remains outside the main catalog.
Abbreviations
| AC — Audio captioning | AQA — Audio question answering | ASR — Automatic speech recognition (ASR) | AVQA — Audio-visual QA | CQA — Cultural QA | DQA — Diagram QA |
| DU — Layout analysis / document understanding | EPC — Emotion / paralinguistic classification | HTR — Handwriting recognition | IC — Image classification | IF — Instruction following | IFT — Instruction tuning |
| KWS — Keyword spotting | LM — Language modelling / pretraining | LQA — Legal QA | MATH — Mathematical reasoning | MCQA — Multiple-choice QA | MORPH — Morphological analysis |
| MR — Math reasoning | MT — Machine translation | NER — Named entity recognition | OCR — OCR | POS — Dependency parsing / POS tagging | QA — Question answering |
| RAG — Retrieval / RAG | Safety — Safety evaluation | SC — Sentiment classification | SQA — Spoken QA | ST — Speech translation | STS — Text deduplication / similarity |
| SV — Speaker verification | T2I — Cultural vision benchmark (text-to-image) | TC — Text classification | TS-ASR — Target-speaker ASR / speech separation | TTS — Text-to-speech (TTS) | VMR — Visual math reasoning |
| VQA — Visual QA | VSR — Visual speech recognition (lip reading) |
Contributing
Missing a Kazakh dataset, or spotted outdated metadata? Contributions are welcome:
- Add a dataset — open a submission issue or send a PR directly.
- Fix or update an entry — edit
data/datasets.yamland open a PR. - Report a stale number — Hugging Face row counts and reported storage sizes may change over time; flag it with the current value from the Dataset Server API.
See CONTRIBUTING.md for the full inclusion criteria, required metadata, and PR format.
Contributors
|
Assel Yermekova |
 Alen Issayev |
License
This catalog's own content — the repository structure, documentation, generated tables, and scripts — is released under the MIT License. Datasets linked from this catalog remain under their own respective licenses (recorded per entry above); this MIT license does not extend to their contents.