
5663015/segment_anything_webui
5663015/segment_anything_webui has 81 GitHub stars and 9 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-15 05:38 UTC. Last push 2026-08-02.
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
A simple Segment Anything WebUI based on Gradio.
Machine LearningREADME.md
OriginalSegment Anything WebUI
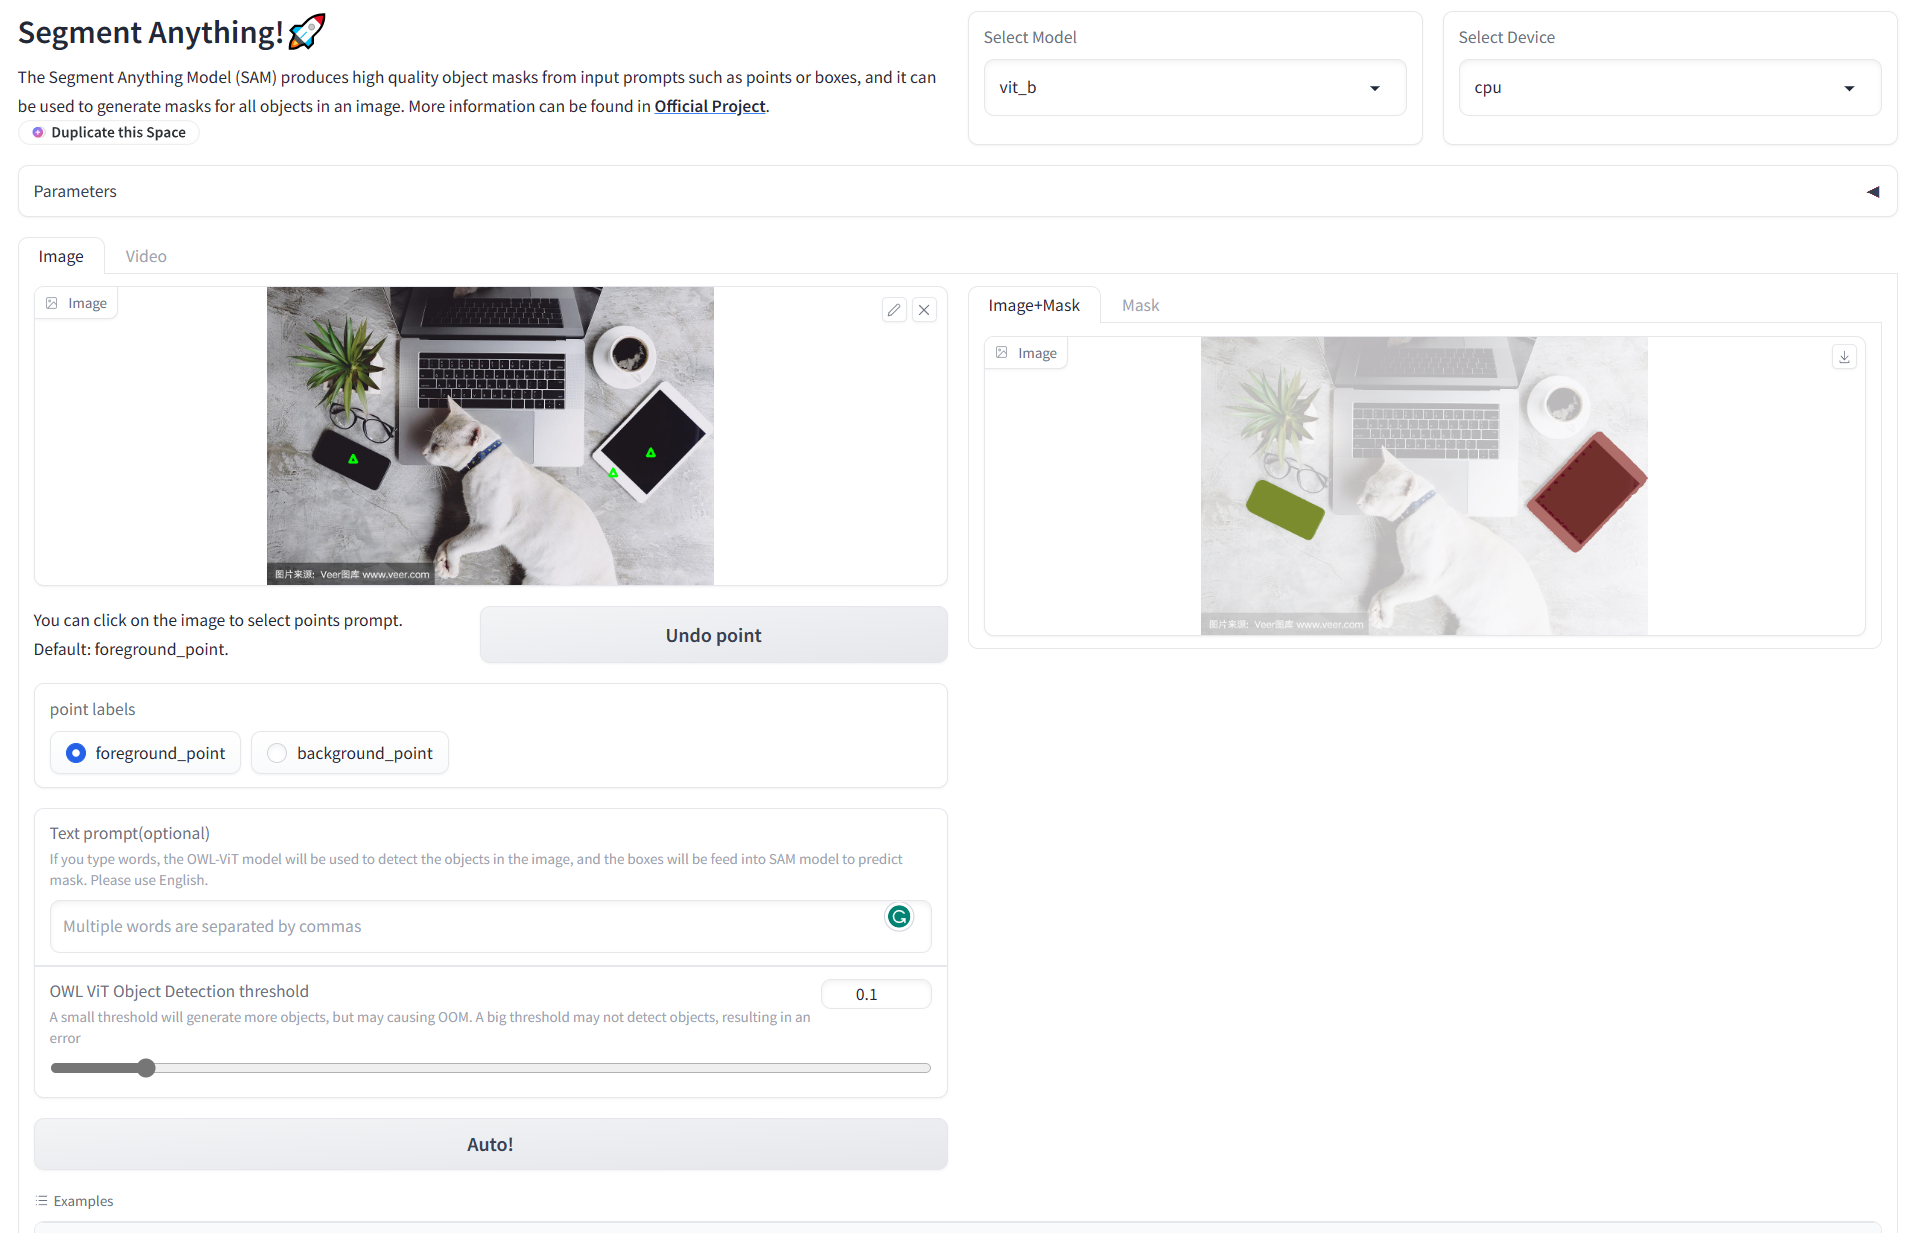
This project is based on Segment Anything Model by Meta. The UI is based on Gradio.
- Try deme on HF: AIBoy1993/segment_anything_webui
- GitHub
Change Logs
- [2023-4-11]
- Support video segmentation. A short video can be automatically segmented by SAM.
- Support text prompt segmentation using OWL-ViT (Vision Transformer for Open-World Localization) model. Text prompt is not yet released in the current SAM version, so it is implemented indirectly using OWL-ViT.
- [2023-4-15]
- Support points prompt segmentation. But due to this issue, using text and point prompts together may result in an error.
- About boxes prompt, it does not seem possible to draw the box directly in Gradio. One idea is to use two points to represent the box, but this is not accurate or elegant. Also, text prompt implements box prompt indirectly, so I won't implement box prompt directly for now. If you have any ideas about box-drawing in Gradio, please tell me.
Usage
Following usage is running on your computer.
- Install Segment Anything(more details about install Segment Anything):
pip install git+https://github.com/facebookresearch/segment-anything.git
git clonethis repository:
git clone https://github.com/5663015/segment_anything_webui.git
Make a new folder named
checkpointsunder this project,and put the downloaded weights files incheckpoints。You can download the weights using following URLs:vit_h: ViT-H SAM modelvit_l: ViT-L SAM modelvit_b: ViT-B SAM model
Under
checkpoints, make a new folder namedmodels--google--owlvit-base-patch32, and put the downloaded OWL-ViT weights files inmodels--google--owlvit-base-patch32.Run:
python app.py
Note: Default model is vit_b,the demo can run on CPU. Default device is cpu。
TODO
Video segmentation
Add text prompt
Add points prompt
Add boxes prompt
Try to combine with ControlNet and Stable Diffusion. Use SAM to generate dataset for fine-tuning ControlNet, and generate new image with SD.
Reference
- Thanks to the wonderful work Segment Anything and OWL-ViT
- Some video processing code references kadirnar/segment-anything-video, and some OWL-ViT code references ngthanhtin/owlvit_segment_anything.