Skip to content
프로젝트 카테고리

데이터 · GitHub

데이터베이스, 분석, SQL, 데이터 엔지니어링 프로젝트를 비교하세요.

유용한 GitHub 프로젝트

2,730 프로젝트

mnemosyne

mnemosyne-oss

3,595스타+5in 24h
mnemosyne preview

Zero-cloud AI memory that works everywhere. SQLite-backed. One pure-Python dependency.

hello-sql

mouredev

10,544스타+5in 24h
hello-sql preview

Curso para aprender los fundamentos del lenguaje SQL y bases de datos relacionales desde cero y para principiantes.

데이터PythonApache-2.0GitHub

PyMuPDF

pymupdf

11,078스타+5in 24h

PyMuPDF is a high performance Python library for data extraction, analysis, conversion & manipulation of PDF (and other) documents.

  • Text extraction - Plain text, rich dict (font, size, color, bbox), HTML, XML, raw blocks
  • Table detection - find_tables() — locate, extract, and export tables as Markdown or structured data
데이터PythonAGPL-3.0GitHub

rybbit

rybbit-io

13,215스타+5in 24h
rybbit preview

🐸 Rybbit - Google Analytics보다 10배 더 직관적인 오픈 소스 및 개인정보 보호 중심의 대안입니다.

  • All key web analytics metrics including sessions, unique users, pageviews, bounce rate, session duration
  • Session replays
데이터TypeScriptAGPL-3.0GitHub

surrealdb

surrealdb

33,286스타+5in 24h
surrealdb preview

실시간 웹을 위한 확장 가능한 분산형 협업 문서 그래프 데이터베이스.

  • Database server, or embedded library
  • Multi-row, multi-table ACID transactions

VictoriaLogs

VictoriaMetrics

2,469스타+5in 24h

Fast and easy to use database for logs, which can efficiently handle terabytes of logs

데이터GoApache-2.0GitHub

VictoriaMetrics

VictoriaMetrics

18,025스타+5in 24h

VictoriaMetrics: fast, cost-effective monitoring solution and time series database

  • Long-term storage for Prometheus or as a drop-in replacement for Prometheus and Graphite in Grafana.
  • Powerful stream aggregation: Can be used as a StatsD alternative.
데이터GoApache-2.0GitHub

cassandra

apache

10,141스타+4in 24h

오픈 소스 트랜잭션 분산 데이터베이스입니다. 일반 하드웨어나 클라우드 인프라에서 성능 저하 없이 선형 확장성을 제공하고, 검증된 내결함성을 갖추고 있습니다.

데이터JavaApache-2.0GitHub

doris

apache

16,189스타+4in 24h
doris preview

Apache Doris는 AI 에이전트를 위한 실시간 분석 및 하이브리드 검색 데이터베이스입니다.

  • Real-Time Analytics - Streaming ingestion, incremental transformation, and sub-second queries under high concurrency.
  • Lakehouse Analytics - Fast SQL analytics over open table formats such as Iceberg, Delta Lake, and Hudi.
데이터JavaApache-2.0GitHub

encore

encoredev

12,697스타+4in 24h

Infrastructure orchestration from local to your cloud

avbook

guyueyingmu

10,109스타+4in 24h
avbook preview

AV 영화 관리 시스템으로, avmoo, javbus, javlibrary 스크래퍼와 온라인 AV 라이브러리 및 AV 마그넷 링크 데이터베이스를 제공합니다. 일본 성인 비디오 라이브러리, 성인 비디오 마그넷 링크 - 일본 성인 비디오 데이터베이스

influxdb

influxdata

31,803스타+4in 24h

메트릭, 이벤트 및 실시간 분석을 위한 확장 가능한 데이터 저장소

데이터RustApache-2.0GitHub

memgraph

memgraph

4,653스타+4in 24h
memgraph preview

GraphRAG, AI 메모리, 에이전틱 AI, 실시간 그래프 분석을 위한 고성능 Fair-code 오픈 소스 인메모리 그래프 데이터베이스입니다. Cypher와 호환되며 C++로 구축되었습니다.

OB1

NateBJones-Projects

4,761스타+4in 24h

Open Brain — The infrastructure layer for your thinking. One database, one AI gateway, one chat channel — any AI plugs in. No middleware, no SaaS.

openmeter

openmeterio

2,439스타+4in 24h
openmeter preview

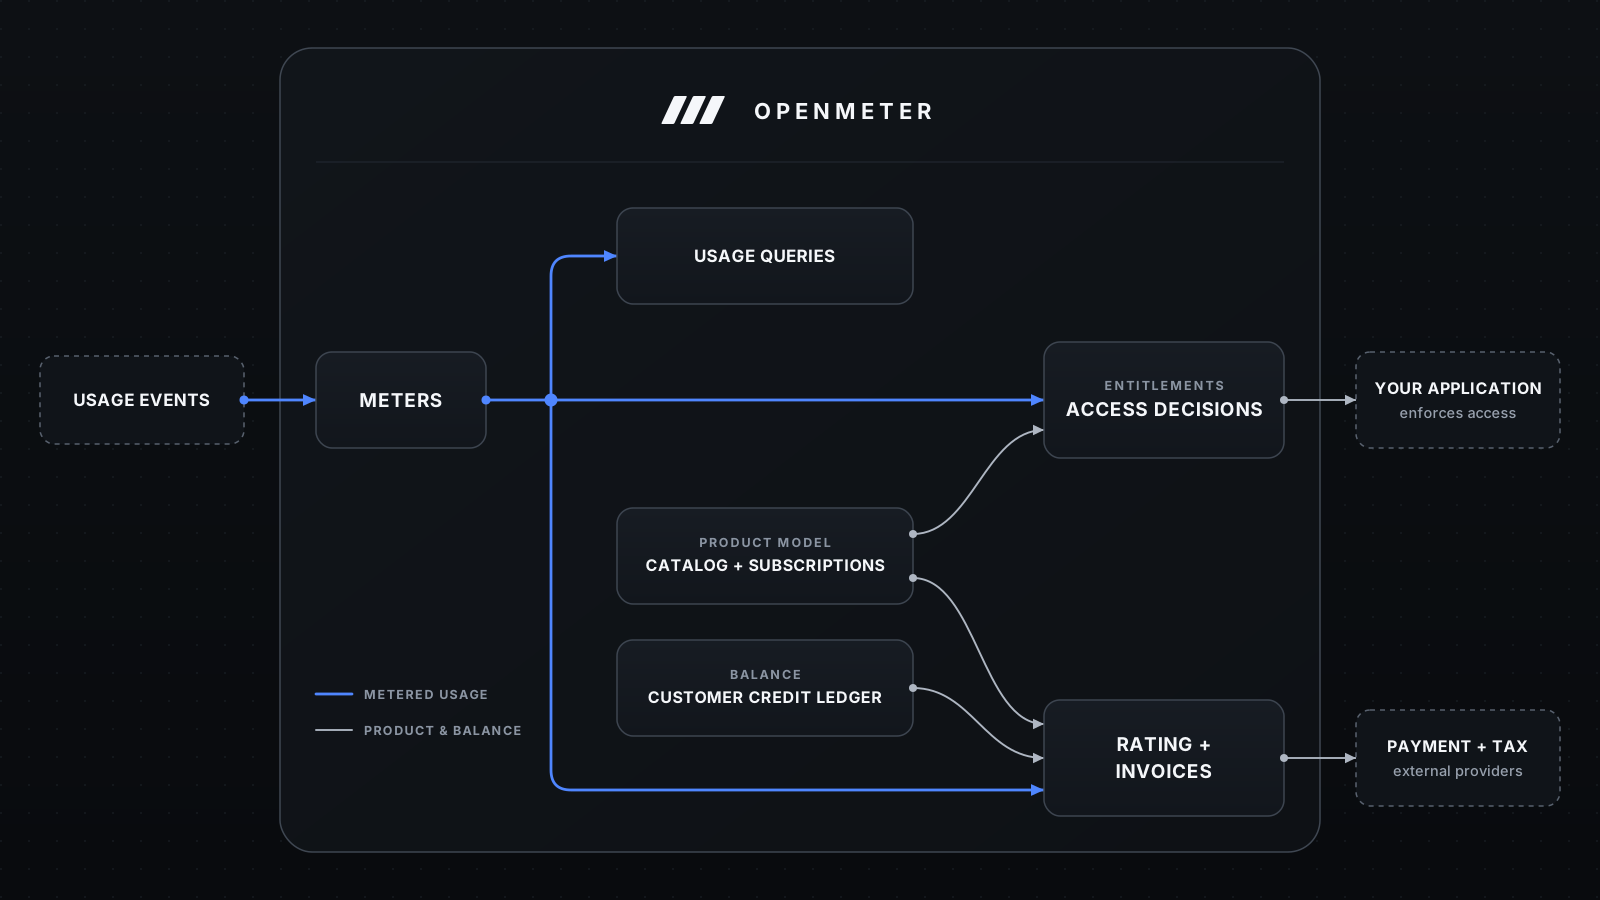
Metering and Billing for AI, API and DevOps. Collect and aggregate millions of usage events in real-time and enable usage-based billing.

데이터GoApache-2.0GitHub

openpanel

Openpanel-dev

7,261스타+4in 24h
openpanel preview

OpenPanel은 웹 및 제품 분석을 위한 오픈 소스 플랫폼으로, Mixpanel의 오픈 소스 대안이며 선택적으로 직접 호스팅할 수 있습니다.

  • 🔍 Advanced Analytics: Funnels, cohorts, user profiles, and session history
  • 🎬 Session Replay: Record and replay user sessions with privacy controls built in
데이터TypeScriptAGPL-3.0GitHub

tidb

pingcap

40,715스타+4in 24h
tidb preview

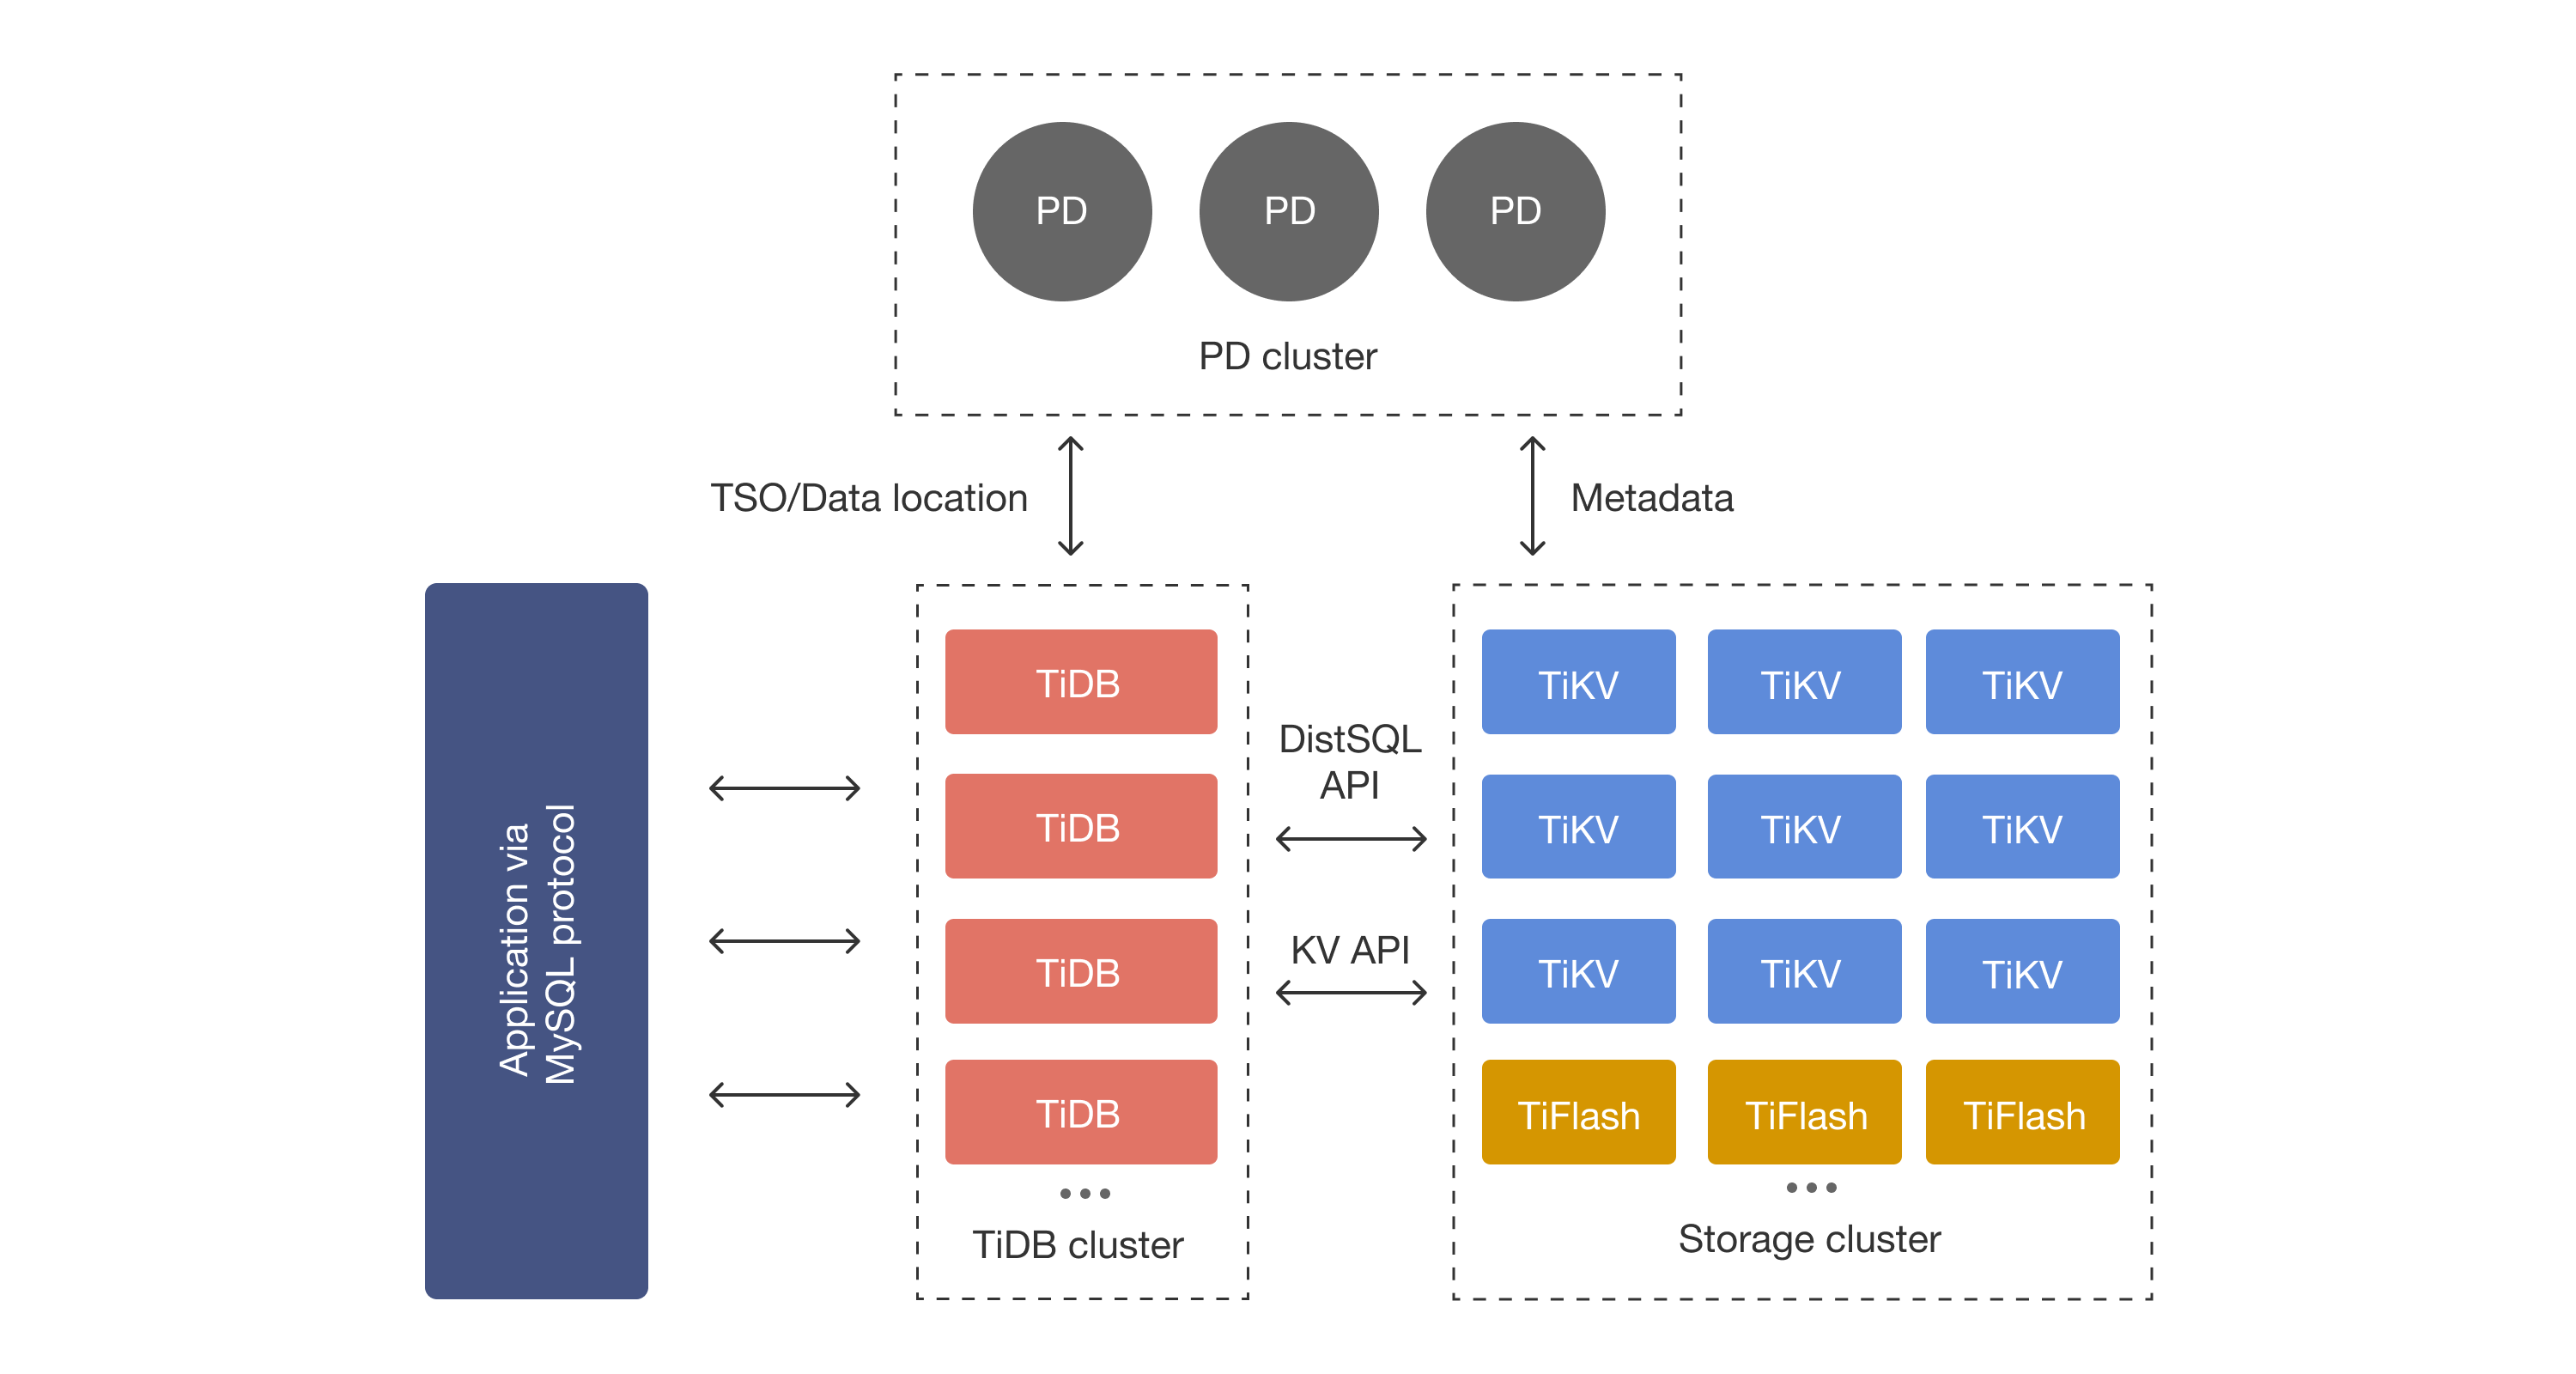
TiDB는 예측하기 어렵게 증가하는 에이전트형 워크로드를 위해 구축되었으며, ACID를 보장하고 트랜잭션, 분석, 벡터 검색을 네이티브로 지원합니다. 데이터 사일로가 없습니다. 노이지 네이버가 없습니다. 인프라 상한이 없습니다.

  • Distributed Transactions: TiDB uses a two-phase commit protocol to ensure ACID compliance, providing strong consistency. Transactions span multiple nodes, and TiDB's distributed nature ensures data correctness even in the presence of network partitions or node failures.
  • Horizontal and Vertical Scalability: TiDB can be scaled horizontally by adding more nodes or vertically by increasing resources of existing nodes, all without downtime. TiDB's architecture separates computing from storage, enabling you to adjust both independently as needed for flexibility and growth.
데이터GoApache-2.0GitHub