
ruc-datalab/CoDA-Bench
ruc-datalab/CoDA-Bench has 45 GitHub stars and 1 forks. Star changes are not measured yet. Last checked 2026-11-14 05:17 UTC. Last push 2026-09-29.
측정된 스타 증가
- in 24h
- 기록 수집 중
- in 7 days
- 기록 수집 중
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
소개
CoDA-Bench is a benchmark for code agents on data-intensive tasks. 🎈代码智能体能搞定数据密集型任务吗?
데이터README.md
Original


Code and data for [ICML 2026] CoDA-Bench: Can Code Agents Handle Data-Intensive Tasks?
Authors: Yuxin Zhang, Ju Fan, Meihao Fan, Shaolei Zhang*, Xiaoyong Du
Renmin University of China
👋 Overview
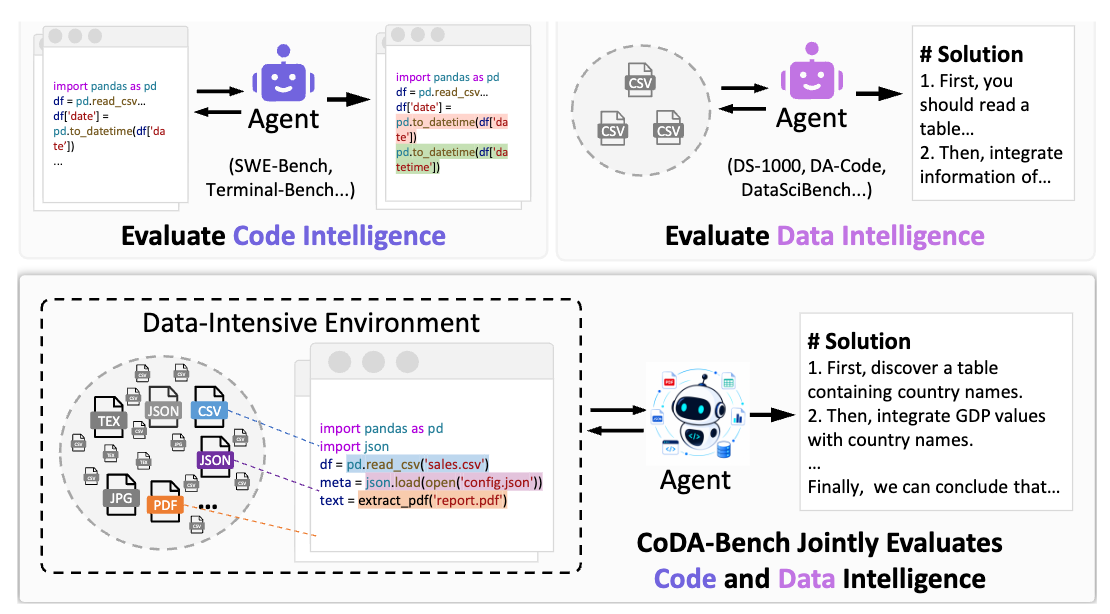
CoDA-Bench (Code and Data-intensive Benchmark) is a benchmark for evaluating AI agents on data-intensive analytical tasks. Given a natural language question and access to a Linux sandbox containing hundreds of data files, an agent must discover relevant data, write code, and produce the correct answer.
https://github.com/user-attachments/assets/34e50a62-744b-4079-8988-6a8bbfe166a0
▶️ Demo video. If it does not play inline, download/watch it here.
Unlike existing benchmarks that provide oracle data directly, CoDA-Bench requires agents to:
- 🔍 Discover relevant data among hundreds of semantically similar files
- 🗂️ Navigate complex file hierarchies in a Linux sandbox
- 🔗 Integrate information from multiple heterogeneous data sources
- 💻 Generate correct code for data-driven analytical tasks
📰 News
- [Jun. 8, 2026]: CoDA-Bench v1.0 released with Docker evaluation!
- [Jun. 1, 2026]: CoDA-Bench paper accepted at ICML 2026!
📊 Dataset Statistics
| Metric | Value |
|---|---|
| Total Tasks | 1,009 (full) / 119 (hard subset) |
| Communities | 49 (full) / 22 (hard subset) |
| Source Datasets | 199 Kaggle datasets |
| Avg Files per Task | ~3413 files |
| Total Size | ~66.45 GB (compressed) |
🚀 Quick Start
Installation
git clone https://github.com/ruc-datalab/CoDA-Bench.git
cd CoDA-Bench
pip install -e .
Download Dataset
# One-command setup: downloads and extracts everything
python scripts/setup_dataset.py --data-dir ./datasets
This downloads:
- Benchmark files (
coda_bench.json,coda_bench_hard.json) - Community data archives (49 communities, ~66.45 GB)
- Automatically extracts all archives
Run Evaluation (Docker Mode)
Step 1: Build Docker Image
cd docker
./build_all.sh
cd ..
Step 2: Set API Credentials
export LLM_API_KEY="your-api-key"
export LLM_BASE_URL="https://api.openai.com/v1"  # Optional
Step 3: Run Evaluation
# Quick test (4 instances)
python scripts/run_evaluation.py \
    --model gpt-5.5 \
    --instances 0 1 2 3 \
    --output results/test

# Full evaluation
python scripts/run_evaluation.py \
    --model gpt-5.5 \
    --output results/full \
    --workers 8
Step 4: Evaluate Results
python -m coda_bench.cli evaluate \
    --pred results/test/predictions.jsonl \
    --gold datasets/coda_bench.json \
    --out results/test/scores.json
Why Docker?
Docker mode provides secure isolation:
- ✅ Agents cannot access benchmark answers
- ✅ Network-restricted environment (only LLM API accessible)
- ✅ Resource limits (memory, CPU, timeout)
- ✅ Reproducible across different machines
See docker/README.md for detailed Docker documentation.
💽 Manual Evaluation
If you prefer manual control:
1. Load Dataset
import json

with open('datasets/coda_bench.json') as f:
    tasks = json.load(f)

# Each task contains:
# - instance_id: unique identifier
# - question: natural language question
# - answer: expected answer
# - release_community: community data directory
2. Run Your Agent
# Your agent should:
# 1. Access community data at: datasets/communities/{release_community}/full_community
# 2. Explore files and write code to answer the question
# 3. Output final answer
3. Evaluate Predictions
python -m coda_bench.cli evaluate \
    --pred predictions.jsonl \
    --gold datasets/coda_bench.json \
    --out results.json
Prediction format (JSONL):
{"instance_id": 0, "prediction": "38%"}
{"instance_id": 1, "prediction": "150"}
🏆 Leaderboard
Current state-of-the-art results (as of paper publication):
| System | Model | EA (Full) | EA (Hard) | DA (Full) |
|---|---|---|---|---|
| Mini-SWE-Agent | GPT-5.5 | 61.1% | 49.6% | 52.3% |
| Codex CLI | GPT-5.5 | 60.3% | 47.9% | 51.7% |
| OpenHands | GPT-5.5 | 59.7% | 44.5% | 48.9% |
| Claude Code | Sonnet-4.6 | 53.8% | 42.9% | 47.2% |
EA = Execution Accuracy, DA = Discovery Accuracy
💡 Example Task
{
  "instance_id": 0,
  "question": "What is the percentage of missing values in the RBC feature?",
  "answer": "38%",
  "release_community": "community_26"
}
The agent needs to:
- Navigate to
datasets/communities/community_26/full_community/ - Find
ckdisease/source/kidney_disease.csvamong ~3413 files - Load and analyze the data
- Calculate missing value percentage for RBC column
- Format answer as "38%"
📚 Documentation
- Docker Evaluation Guide - Secure Docker-based evaluation
- Evaluation Protocol - Scoring and metrics
- Data Format - Dataset schema
- Baseline Agents - Reference implementations
🗺️ Roadmap
v1.0 (Current - June 2026)
- ✅ OpenHands agent with Docker isolation
- ✅ Full dataset (1,009 tasks) + hard subset (119 tasks)
- ✅ Secure evaluation environment
- ✅ Complete documentation
Coming Soon
- 🚧 Direct mode - Quick testing without Docker (simple, no isolation)
- 🚧 Additional agents - Claude Code, Codex, Mini-SWE-Agent Docker support
- 🚧 Better logging - Real-time progress tracking
- 🚧 Performance optimizations - Faster evaluation
💫 Contributing
We welcome contributions! See CONTRIBUTING.md for guidelines.
Ways to contribute:
- 🐛 Report bugs or issues
- 💡 Suggest new features
- 📝 Improve documentation
- 🧪 Add agent implementations
- 📊 Share evaluation results
✍️ Citation
@inproceedings{zhang2026codabench,
  title={CoDA-BENCH: Can Code Agents Handle Data-Intensive Tasks?},
  author={Zhang, Yuxin and Fan, Ju and Fan, Meihao and Zhang, Shaolei and Du, Xiaoyong},
  booktitle={Proceedings of the 43rd International Conference on Machine Learning},
  year={2026},
  organization={PMLR}
}
📄 License
MIT License. See LICENSE for details.
Individual Kaggle datasets may have their own licenses.
📧 Contact
- GitHub Issues: github.com/ruc-datalab/CoDA-Bench/issues
- Email: [email protected]
💬 Community Groups
Welcome to join the CoDA-Bench WeChat group or the Data+AI Enterprise WeChat group, chat and share ideas with others!
If you like CoDA-Bench, give it a GitHub Star ⭐.
Dataset correction: v1.0.1
The community mapping and archive omissions reported in issue #1 are corrected. Download the updated task JSON files and the required archives together. Full/hard splits use 49/22 communities. Previous evaluation scores refer to the original dataset revision; their applicability to this corrected release has not been established. See release notes for validation scope and upgrade instructions.
관련 프로젝트 살펴보기
Asabeneh/30-Days-Of-Python
30 Days of Python 프로그래밍 챌린지는 Python 프로그래밍 언어를 30일 동안 배우기 위한 단계별 가이드입니다. 이 챌린지는 100일 이상 걸릴 수 있습니다. 자신의 속도에 맞춰 진행하세요. 다음 동영상도 도움이 될 수 있습니다: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,715 스타grafana/grafana
개방적이고 조합 가능한 옵저버빌리티 및 데이터 시각화 플랫폼입니다. Prometheus, Loki, Elasticsearch, InfluxDB, Postgres 등 여러 소스의 메트릭, 로그, 트레이스를 시각화합니다.
77,894 스타redis/redis
실시간 데이터 기반 애플리케이션을 구축하는 개발자에게 Redis는 가장 선호되고, 가장 빠르며, 기능이 가장 풍부한 캐시, 데이터 구조 서버이자 문서 및 벡터 쿼리 엔진입니다.
77,491 스타apache/superset
Apache Superset는 데이터 시각화 및 데이터 탐색 플랫폼입니다.
75,522 스타